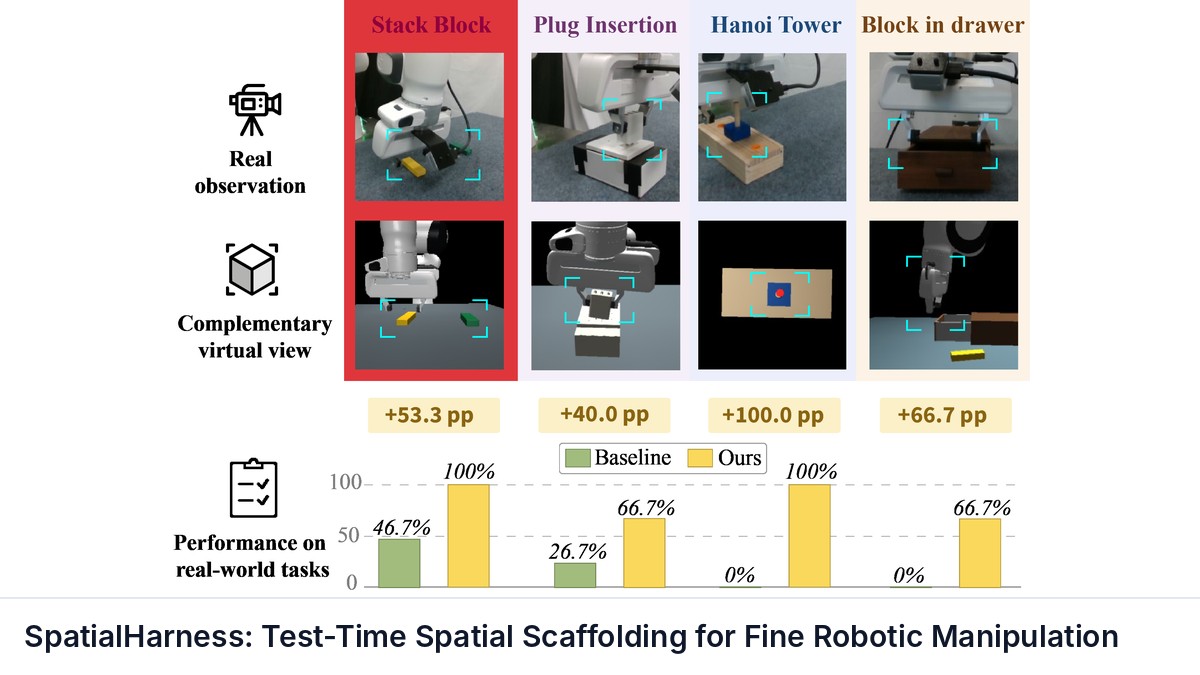
Manipulation

242 papers

Dexterous and contact-rich robotic manipulation strategies.

sim-to-real reinforcement-learning vision vla manipulation locomotion control learning-from-demonstration planning human-robot-interaction benchmark humanoid model-predictive-control uav dexterous tactile offline-rl ar-vr rl foundation-models perception representation-learning simulation evaluation diffusion-policy diffusion-models hand-tracking world-models gpu-acceleration bimanual imitation-learning dataset benchmarking navigation vision-language generation safety open-source llm mobile-manipulation il llm-robotics behavior-cloning zero-shot

Papers

Sorted by year (newest first)
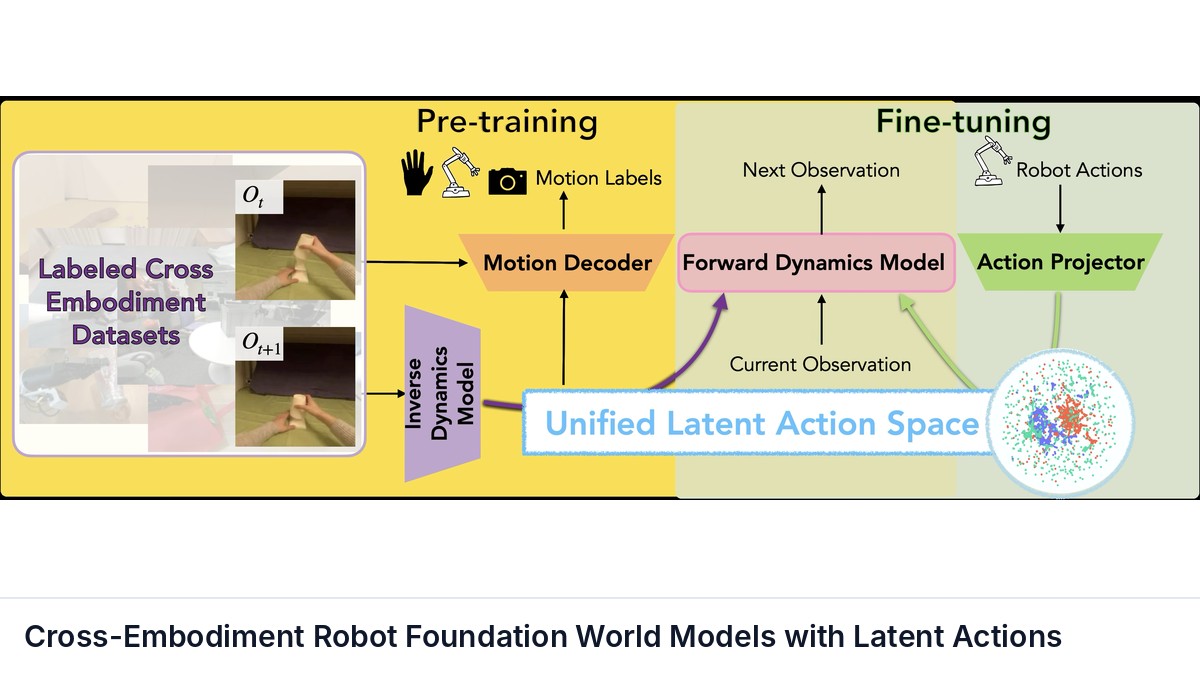
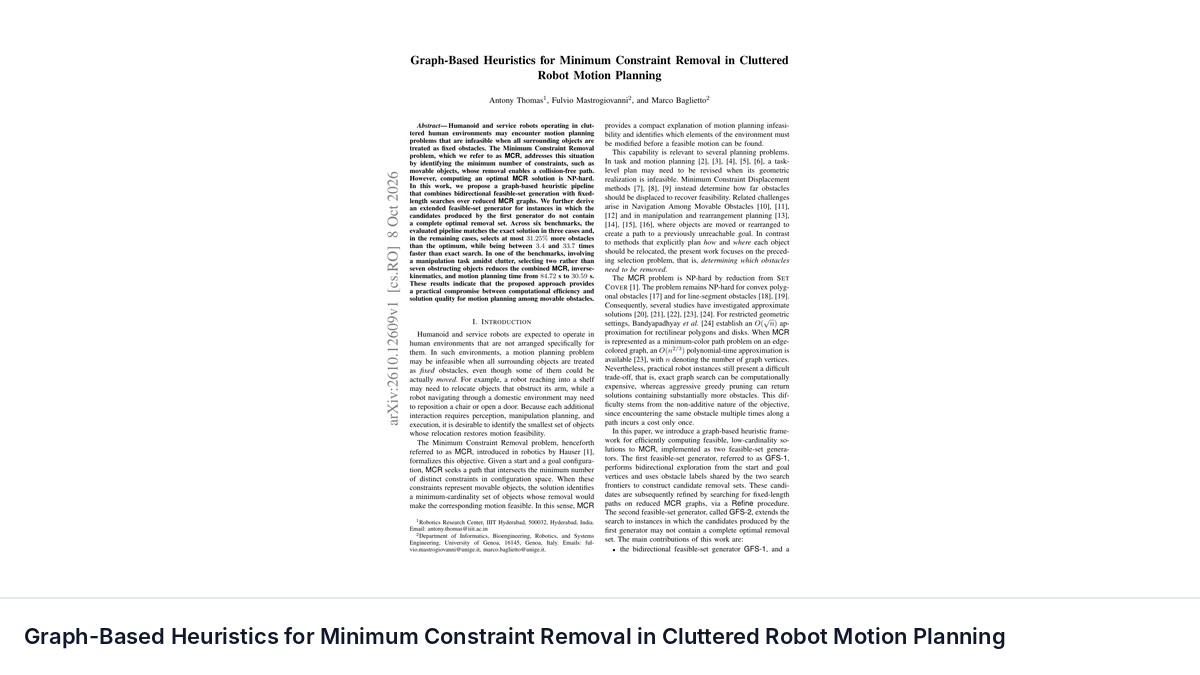
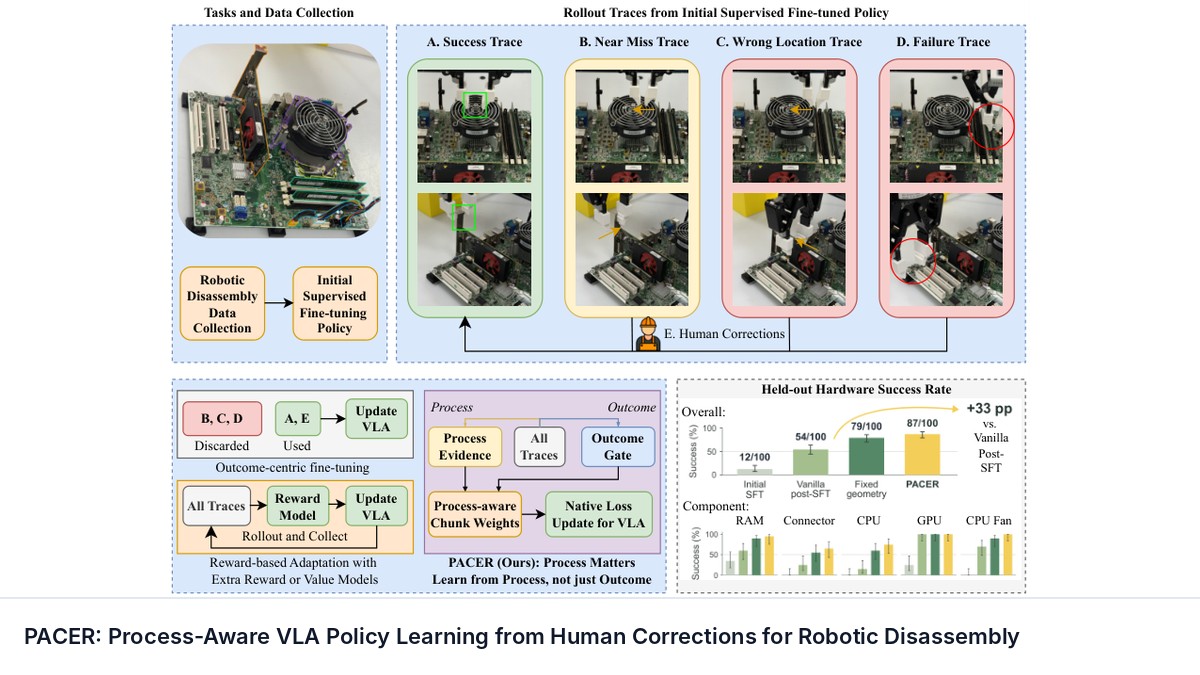
A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
arXiv preprint

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies

Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.

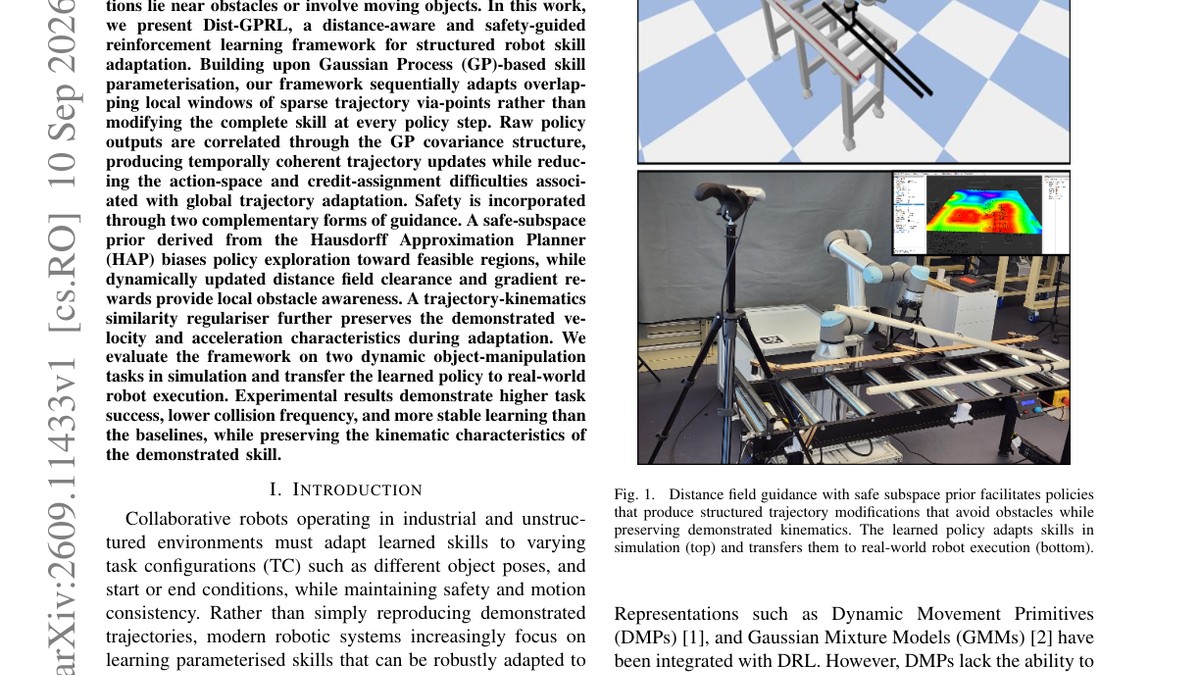
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.

manipulation vision vla reinforcement-learning sim-to-real control learning-from-demonstration benchmark
PDF Advanced
A Two-Echelon Covering Tour Vehicle Routing Problem with Drones for Post-Disaster Relief
arXiv preprint

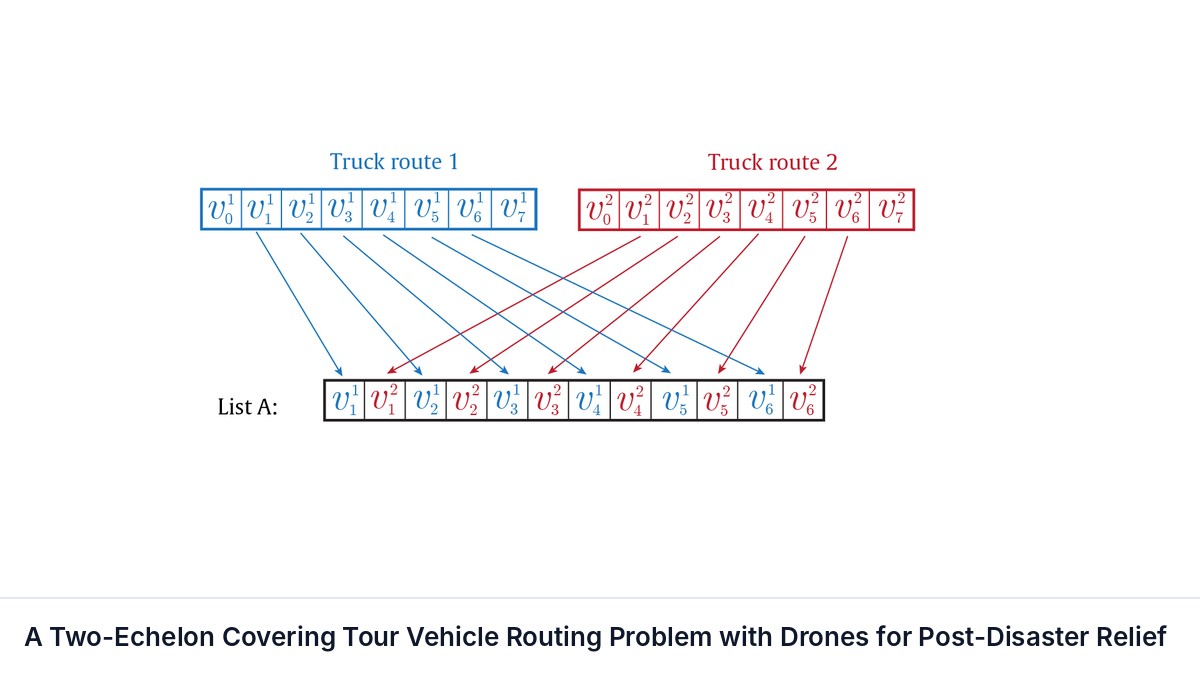
A Two-Echelon Covering Tour Vehicle Routing Problem with Drones for Post-Disaster Relief

Dang Viet Anh Nguyen, Rajesh Piplani, Aldy Gunawan

We introduce the two-echelon covering tour vehicle routing problem (2E-CTVRP) for the distribution of relief supplies after a disaster. In the first echelon, a fleet of trucks transports supplies and drones from a central depot to satellites at the periphery of the affected area.

manipulation reinforcement-learning benchmark
Code PDF Intermediate
GitHub ★ —
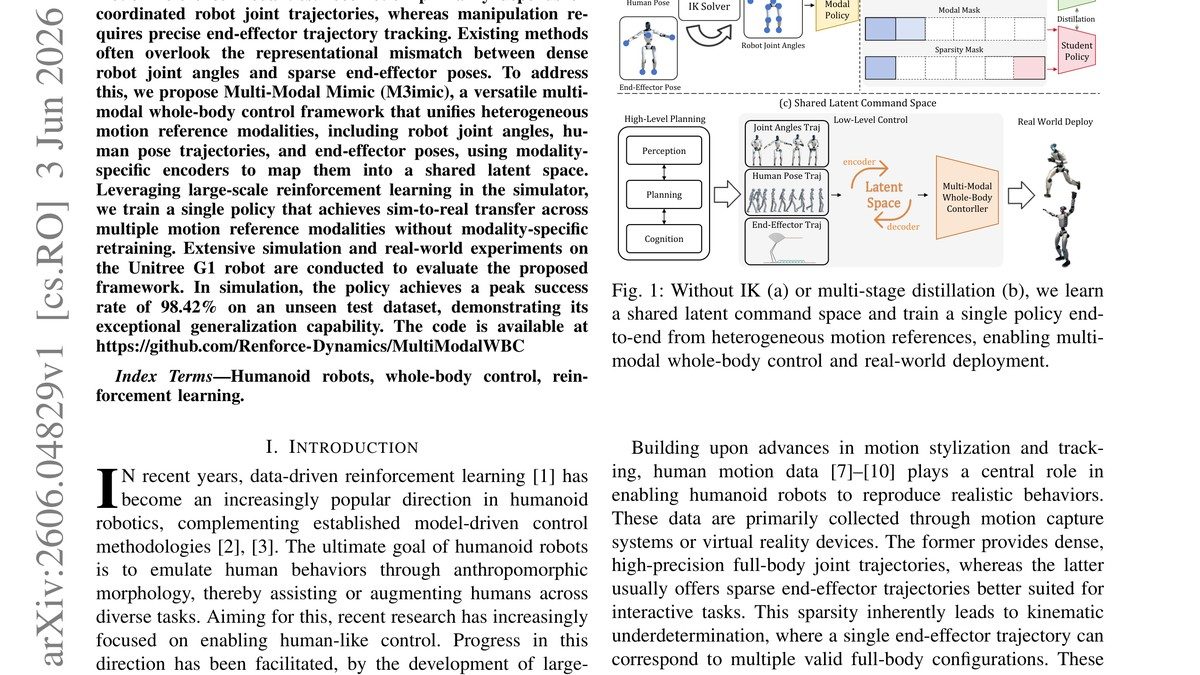
Accelerating and Scaling MPC-Guided Reinforcement Learning for Humanoid Locomotion and Manipulation
arXiv preprint

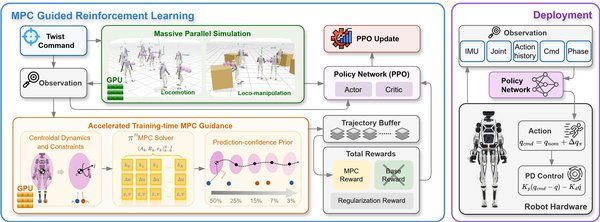
Accelerating and Scaling MPC-Guided Reinforcement Learning for Humanoid Locomotion and Manipulation

Junheng Li, Liang Wu, Sergio A. Esteban et al.

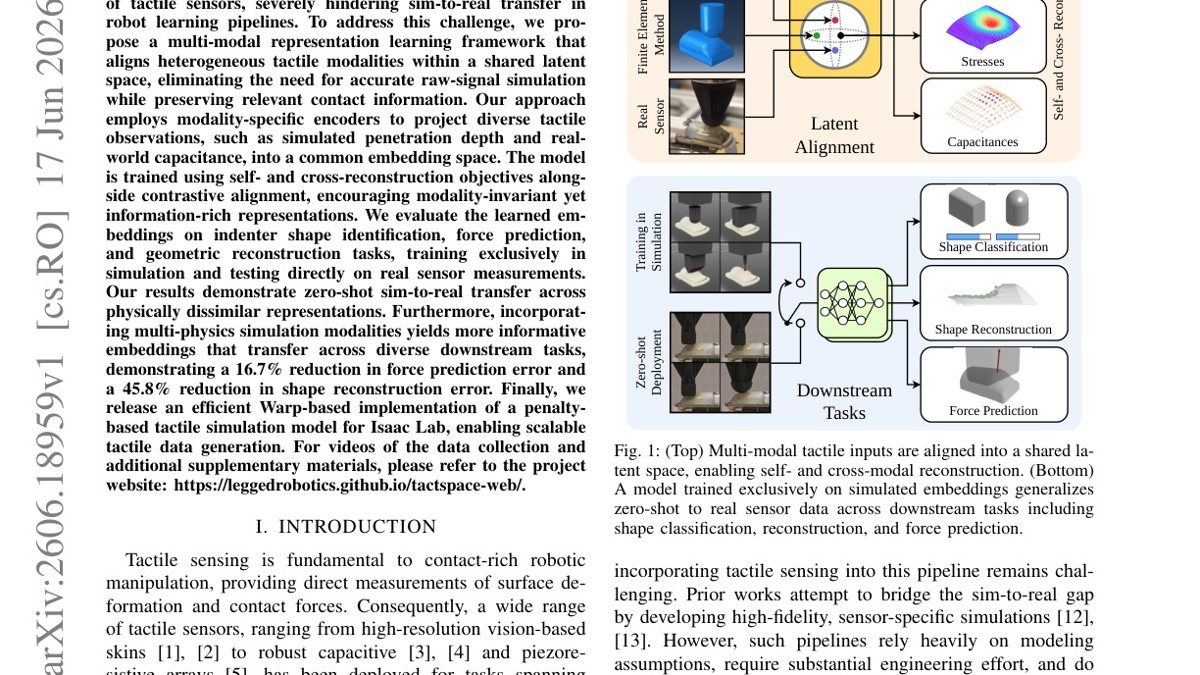
In humanoid motion control, model predictive control (MPC) offers physically grounded prediction and constraint handling, while reinforcement learning (RL) enables robust whole-body skills through large-scale simulation. However, using MPC inside RL often requires time-consuming problem construction or excessive training overhead, making such frameworks difficult to justify in practice. This work studies efficient training-time MPC guidance for humanoid locomotion and manipulation, termed MPC-RL. We introduce a centroidal-dynamics MPC reward formulation that leverages guidance from MPC trajectories in training time. To make this practical in massively parallel RL, we develop π^nMPC, a parallel-in-horizon and construction-free batched GPU MPC solver that operates directly on time-varying dynamics to avoid high memory usage and pre-compilation. Through a variety of comparative studies and hardware validations, we have found that MPC-RL achieves superior performance in locomotion and manipulation skills.

humanoid reinforcement-learning model-predictive-control locomotion manipulation
Code PDF Advanced
GitHub ★ —
AD-WM: Action-Discriminative World Models for Counterfactual Model Predictive Control
arXiv preprint

AD-WM: Action-Discriminative World Models for Counterfactual Model Predictive Control

Jiabin Qiu, Zixuan Chen, Hongye Cao et al.

Latent world models are typically trained to predict factual transitions, whereas model predictive control (MPC) must compare alternative actions from the same state. A model can therefore achieve low factual prediction error yet poorly distinguish candidate actions.

manipulation reinforcement-learning planning control
Code PDF Intermediate
GitHub ★ —
AHEAD: Anticipatory Hand-Driven Teleoperation via Human Intent Prediction
arXiv preprint

AHEAD: Anticipatory Hand-Driven Teleoperation via Human Intent Prediction

Seok Joon Kim, Junho Lee, Federica Spinola et al.

Direct hand-driven teleoperation maps an operator's hand motion to robot end-effector commands at every frame, enabling precise control, but it requires constant monitoring and correction during approach, grasp, and placement, which can be slow and fatiguing.

manipulation reinforcement-learning planning control learning-from-demonstration
PDF Intermediate
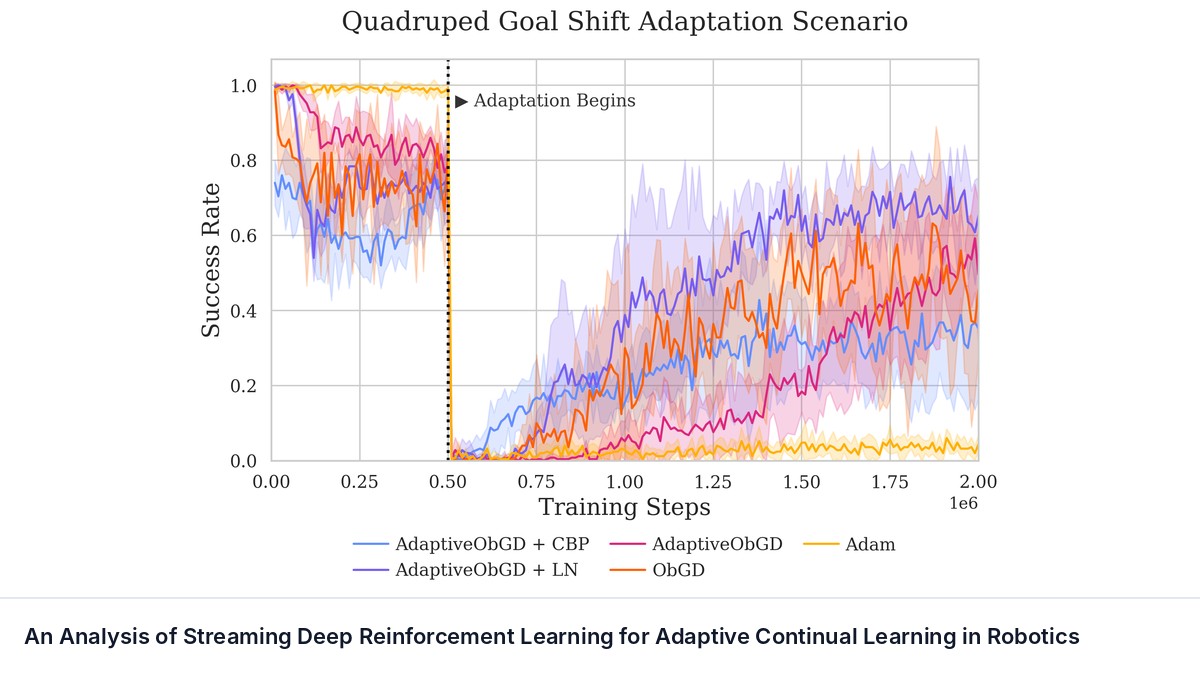
An Analysis of Streaming Deep Reinforcement Learning for Adaptive Continual Learning in Robotics
arXiv preprint

An Analysis of Streaming Deep Reinforcement Learning for Adaptive Continual Learning in Robotics

Teeratham Vitchutripop, Alyssa Quarles, Wenhe Zhang et al.

Over the course of a lifetime, robots may encounter novel scenarios unaccounted for in its original training that result in performance degradation. One common approach to mitigating this issue is to further grow the offline training dataset in hopes of producing a policy robust to these changes.

manipulation locomotion reinforcement-learning benchmark
PDF Intermediate
Autonomous Droplet Navigation via Model-Based Reinforcement Learning: Zero-Shot Transfer and Emergent Dynamics
arXiv preprint

Autonomous Droplet Navigation via Model-Based Reinforcement Learning: Zero-Shot Transfer and Emergent Dynamics

Rajneesh Anand, Mayuresh V. Kothare

Self-driving laboratories (SDLs) are transforming chemical and materials discovery through closed-loop automation, yet automated infrastructure for physical manipulation of soft, deformable matter remains beyond current robotic platforms.

manipulation vision reinforcement-learning planning control
Code PDF Intermediate
GitHub ★ —
AXIS: A Growable Community-Driven Data Engine for Scalable Robot Manipulation
arXiv preprint

AXIS: A Growable Community-Driven Data Engine for Scalable Robot Manipulation

Mengfei Zhao, Dihong Huang, Yikai Tang et al.

Learning effective robot manipulation policies requires diverse, high-quality demonstrations, yet existing data pipelines are often difficult to scale because they rely on specialized hardware, centralized operators, or fixed task suites.

manipulation vision vla learning-from-demonstration benchmark
PDF Advanced
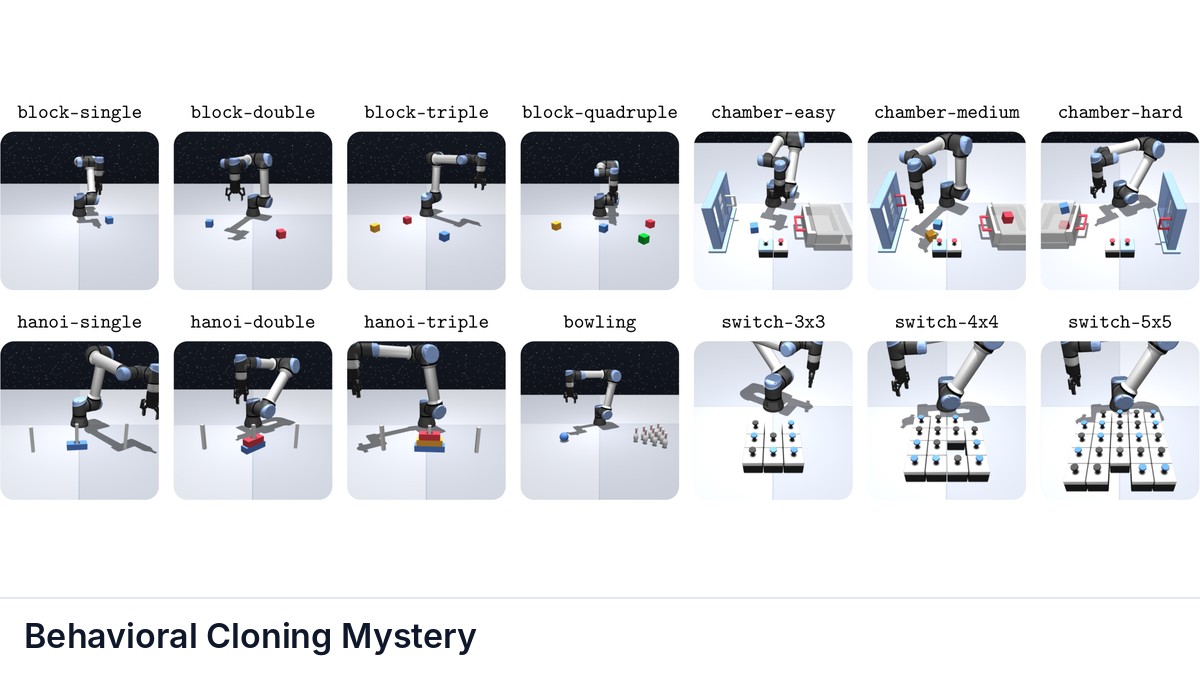
Behavioral Cloning Mystery
arXiv preprint

Behavioral Cloning Mystery

Seohong Park, Sergey Levine

Behavioral cloning (BC), despite its simplicity, exhibits many counterintuitive phenomena in the real world. For example, the performance of BC often keeps increasing as the model overfits more to the dataset, and fully closed-loop policies often completely fail without action chunking.

manipulation reinforcement-learning control learning-from-demonstration benchmark
Code PDF Intermediate
GitHub ★ —
Beyond Reconstruction: What Matters in Action Tokenization for Robot Policies?
arXiv preprint

Beyond Reconstruction: What Matters in Action Tokenization for Robot Policies?

Haoran Chen, Jingtian Ji, Samuel Wheeler et al.

Autoregressive action-token policies such as vision-language-action models require action tokenizers to translate discrete token sequences into precise control actions in continuous space. Many action tokenizers learn the mapping between tokens and actions via a reconstruction objective.

manipulation vision vla reinforcement-learning control benchmark
PDF Intermediate
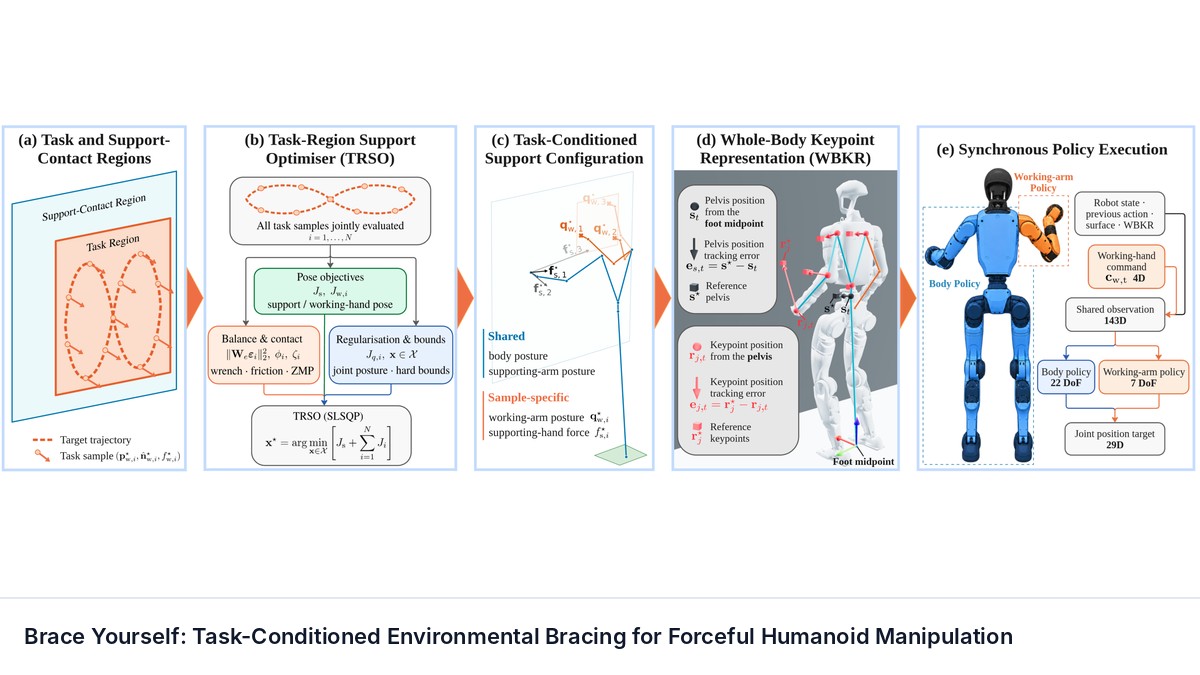
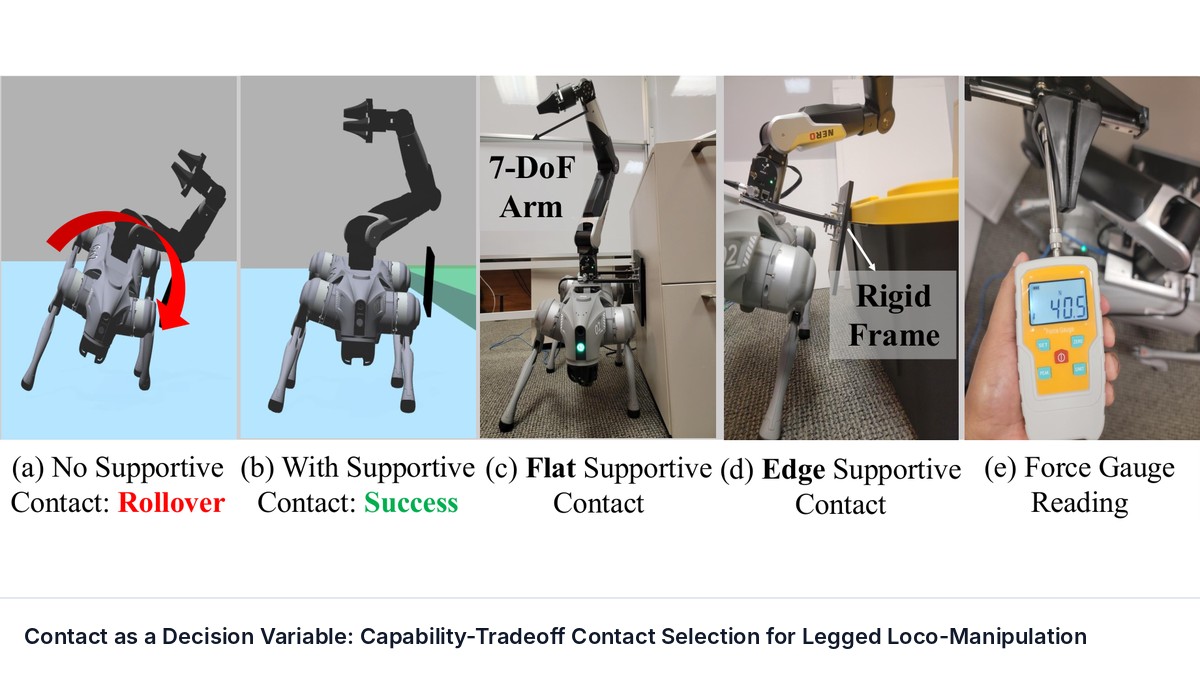
Brace Yourself: Task-Conditioned Environmental Bracing for Forceful Humanoid Manipulation
arXiv preprint

Brace Yourself: Task-Conditioned Environmental Bracing for Forceful Humanoid Manipulation

Zongyuan Zhang, Christopher Lehnert, Will N. Browne et al.

Forceful manipulation is challenging for humanoid robots because interaction forces can disturb whole-body balance. We introduce the Supporting Hand Strategy (SHS), which enables a humanoid to brace against the environment with one hand while performing forceful manipulation with the other.

manipulation reinforcement-learning planning
PDF Intermediate
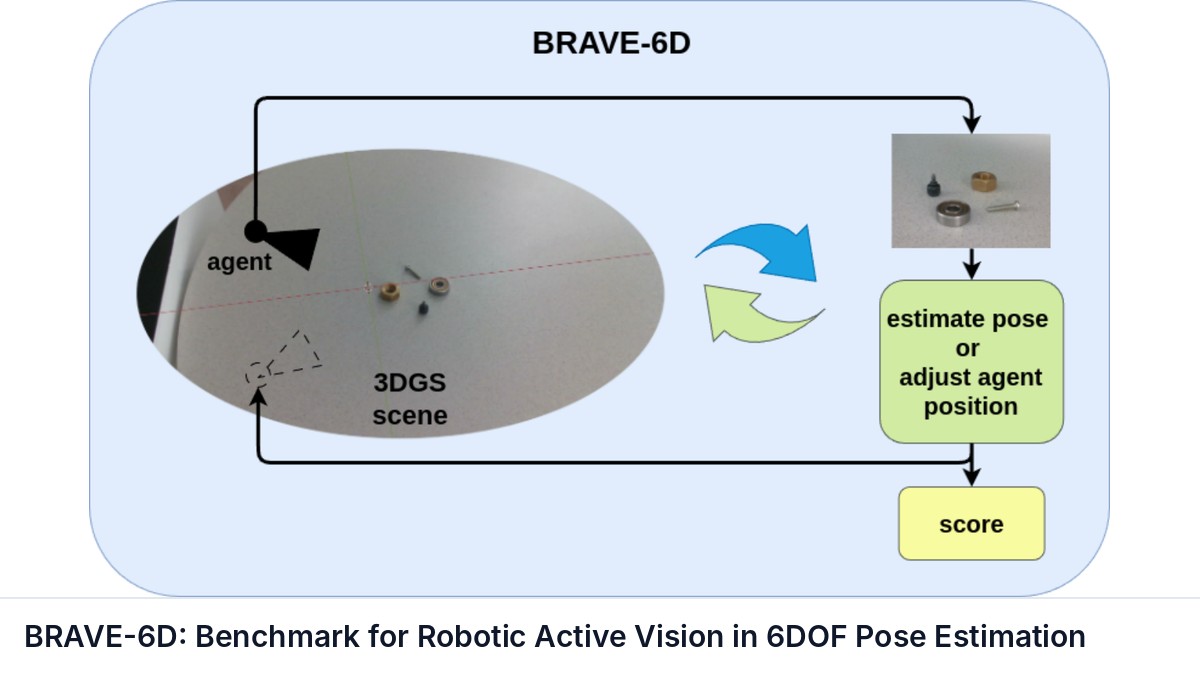
BRAVE-6D: Benchmark for Robotic Active Vision in 6DOF Pose Estimation
arXiv preprint

BRAVE-6D: Benchmark for Robotic Active Vision in 6DOF Pose Estimation

Philipp Ausserlechner, Bernhard Neuberger, Alessandro Scherl et al.

Detecting and grasping small objects remains a significant challenge in robotics. Active vision, where the robot moves closer to the object, is an intuitive solution, yet comparing approaches on common ground is difficult since identical physical scene setups are required.

manipulation vision benchmark
PDF Intermediate
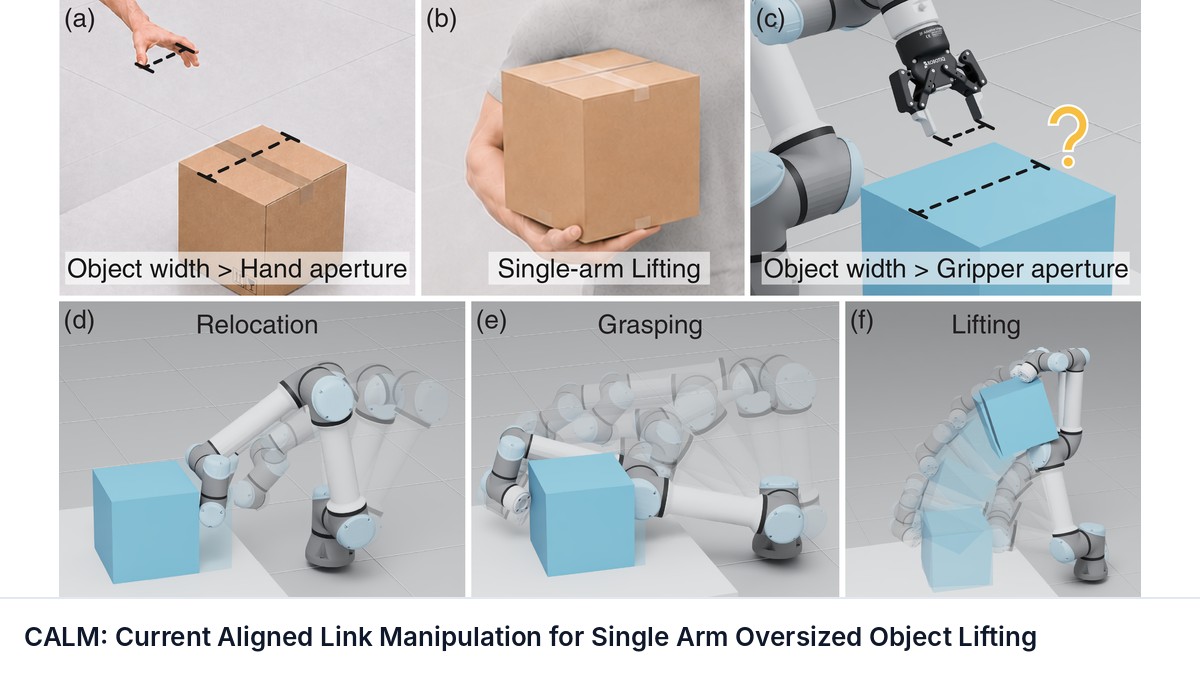
CALM: Current Aligned Link Manipulation for Single Arm Oversized Object Lifting
arXiv preprint

CALM: Current Aligned Link Manipulation for Single Arm Oversized Object Lifting

Hu, Jun, Chen, Sihan, Jovanovic, Kosta et al.

Most robots manipulate objects solely with their end effectors, whereas humans flexibly leverage different body parts, such as the forearm and elbow, especially when handling oversized objects.

manipulation reinforcement-learning sim-to-real learning-from-demonstration
PDF Intermediate
Capability-Aware Arbitration for Semantic Intent-Based Shared Control
arXiv preprint

Capability-Aware Arbitration for Semantic Intent-Based Shared Control

Zhaoda Du, Michael Bowman, Xiaoli Zhang

Shared control often allocates robot authority based on confidence in inferred human intent, assuming reliable autonomous execution. When this assumption fails, high intent confidence can cause over-helping.

manipulation vision vla reinforcement-learning control learning-from-demonstration benchmark
Code PDF Intermediate
GitHub ★ —
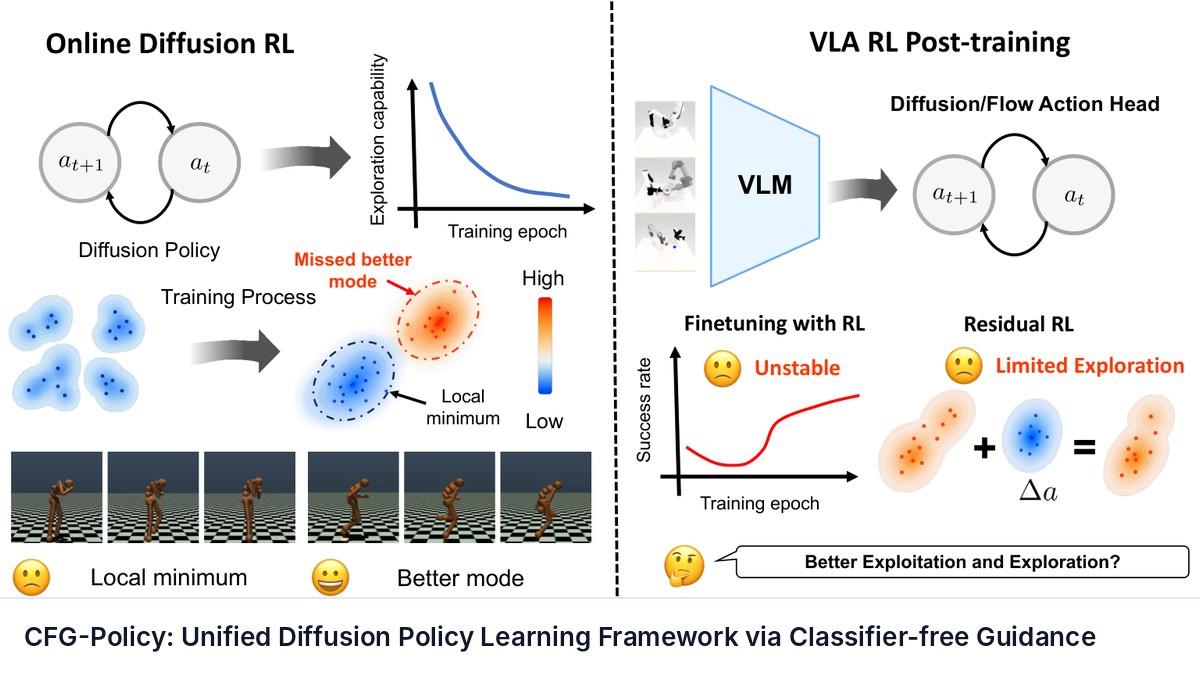
CFG-Policy: Unified Diffusion Policy Learning Framework via Classifier-free Guidance
arXiv preprint

CFG-Policy: Unified Diffusion Policy Learning Framework via Classifier-free Guidance

Shutong Ding, Zhaoyang Liu, Yimiao Zhou et al.

Diffusion policies are increasingly used in robotic control and manipulation, vision-language-action models, and world-model-based agents. Their ability to represent multimodal action distributions offers rich opportunities for exploration in reinforcement learning (RL).

manipulation vision vla reinforcement-learning control
Code PDF Advanced
GitHub ★ —
CoDA: Co-Evolution of Data Engines and Action Policies
arXiv preprint

CoDA: Co-Evolution of Data Engines and Action Policies

Tianjiao Yu, Zhilin Ou, Yifan Shen et al.

Generative simulation can automate robot environment construction, but physically valid environments are not necessarily useful for training. The challenge is to identify environments that address a policy's failures and supervision that helps it overcome them.

manipulation vision reinforcement-learning
PDF Intermediate
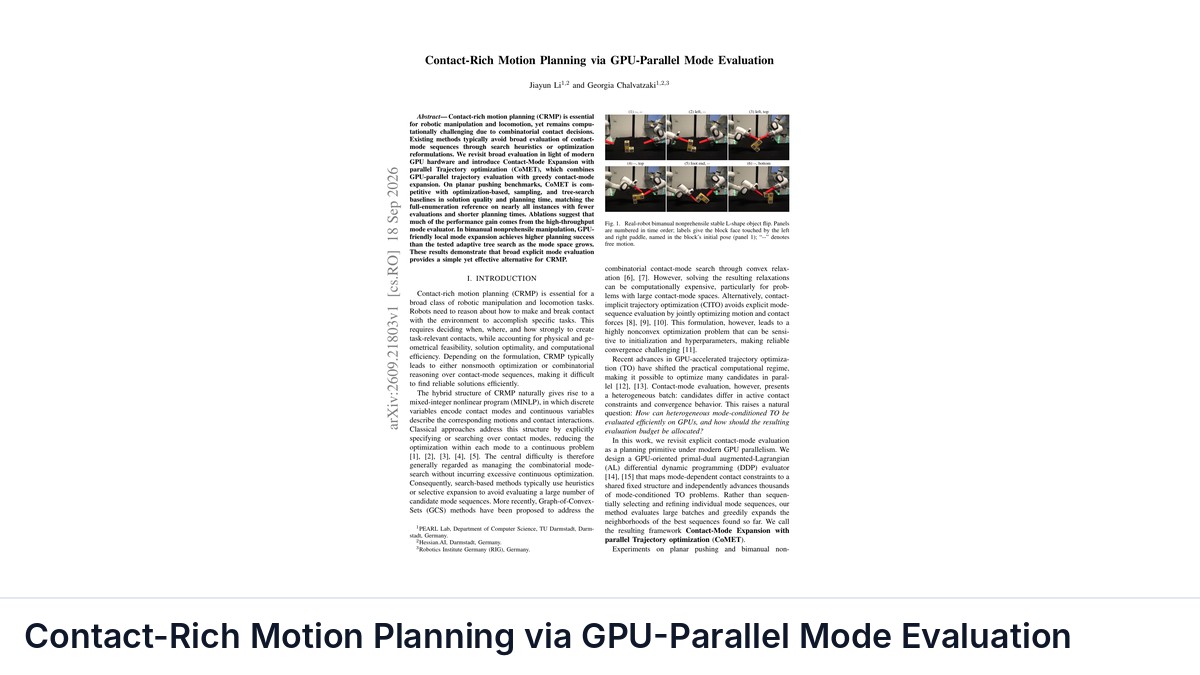
Contact-Rich Motion Planning via GPU-Parallel Mode Evaluation
arXiv preprint

Contact-Rich Motion Planning via GPU-Parallel Mode Evaluation

Jiayun Li, Georgia Chalvatzaki

Contact-rich motion planning (CRMP) is essential for robotic manipulation and locomotion, yet remains computationally challenging due to combinatorial contact decisions.

manipulation locomotion reinforcement-learning planning benchmark
PDF Intermediate
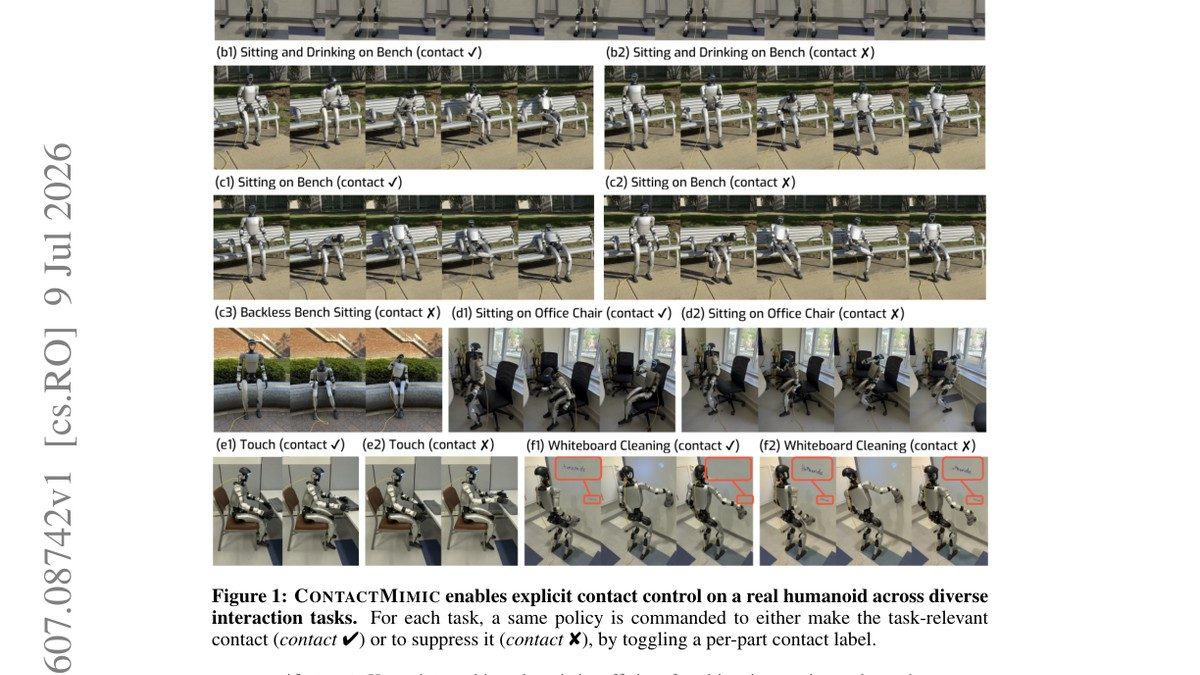
ContactMimic: Humanoid Object Interaction via Contact Control
arXiv preprint

ContactMimic: Humanoid Object Interaction via Contact Control

Xinyao Li, Xialin He, Runpei Dong et al.

Keypoint tracking alone is insufficient for object interaction tasks such as sitting on a chair, wiping a board, or pushing furniture, where the robot can reach the correct pose without making meaningful physical contact with the object.

manipulation reinforcement-learning control
PDF Intermediate
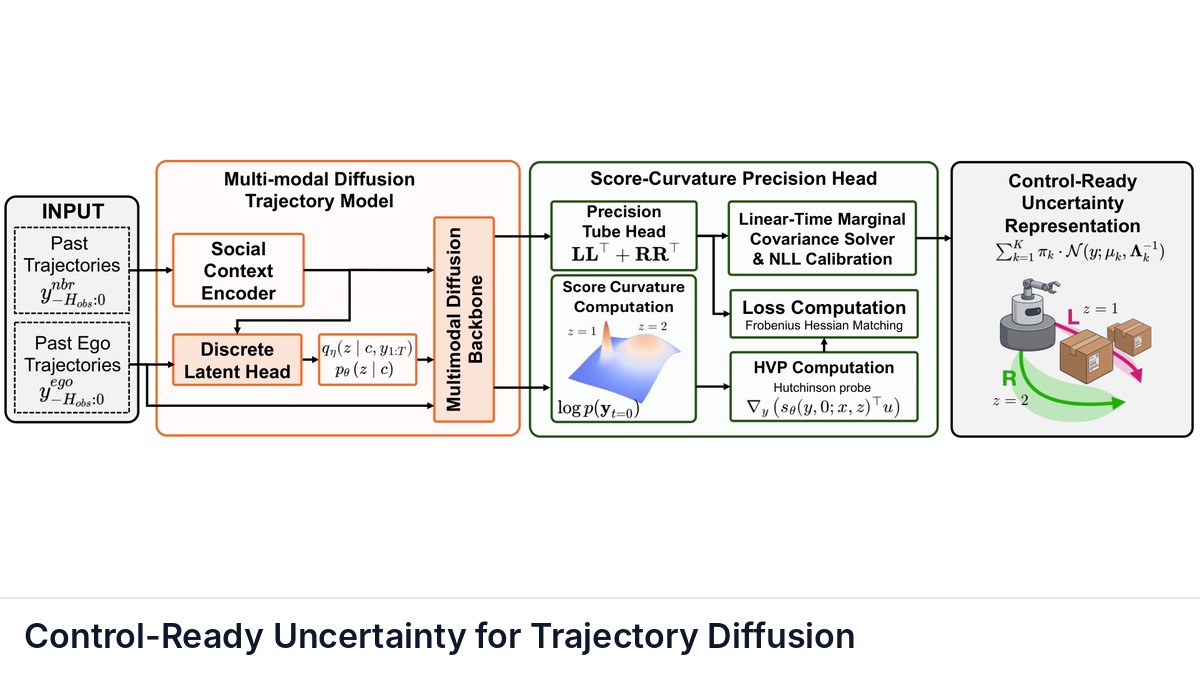
Control-Ready Uncertainty for Trajectory Diffusion
arXiv preprint

Control-Ready Uncertainty for Trajectory Diffusion

Zhiwei Xue, Jia Yue Kam, Jinhang Qiu et al.

Diffusion models can represent complex, multimodal trajectory distributions, but extracting uncertainty from them typically requires costly Monte Carlo sampling. This limits their use in real-time control, where robots must rapidly assess risk and maintain safety margins.

manipulation reinforcement-learning planning control
PDF Advanced
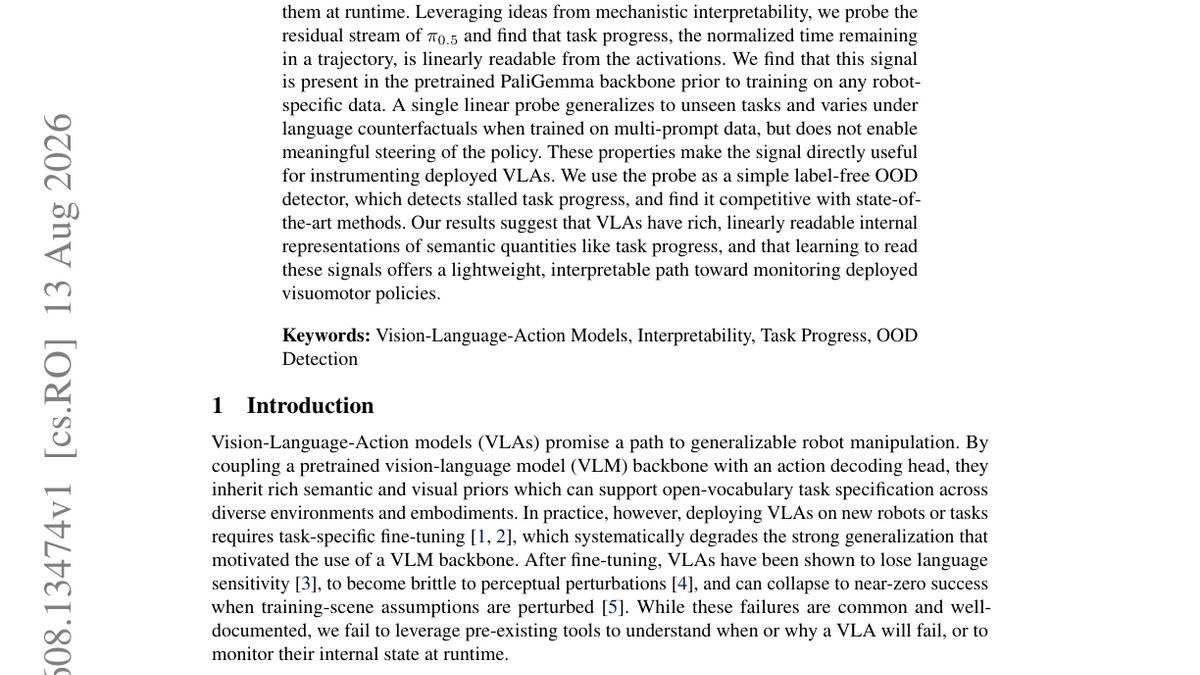
Decoding Task Progress from VLA Representations
arXiv preprint

Decoding Task Progress from VLA Representations

Atiksh Bhardwaj, Edward Weiyi Duan, Prithwish Dan et al.

Vision-language-action models (VLAs) are moving rapidly towards deployment as general-purpose manipulation policies, but we currently lack basic tools for understanding what these models represent internally or for monitoring them at runtime.

manipulation vision vla reinforcement-learning control
PDF Intermediate
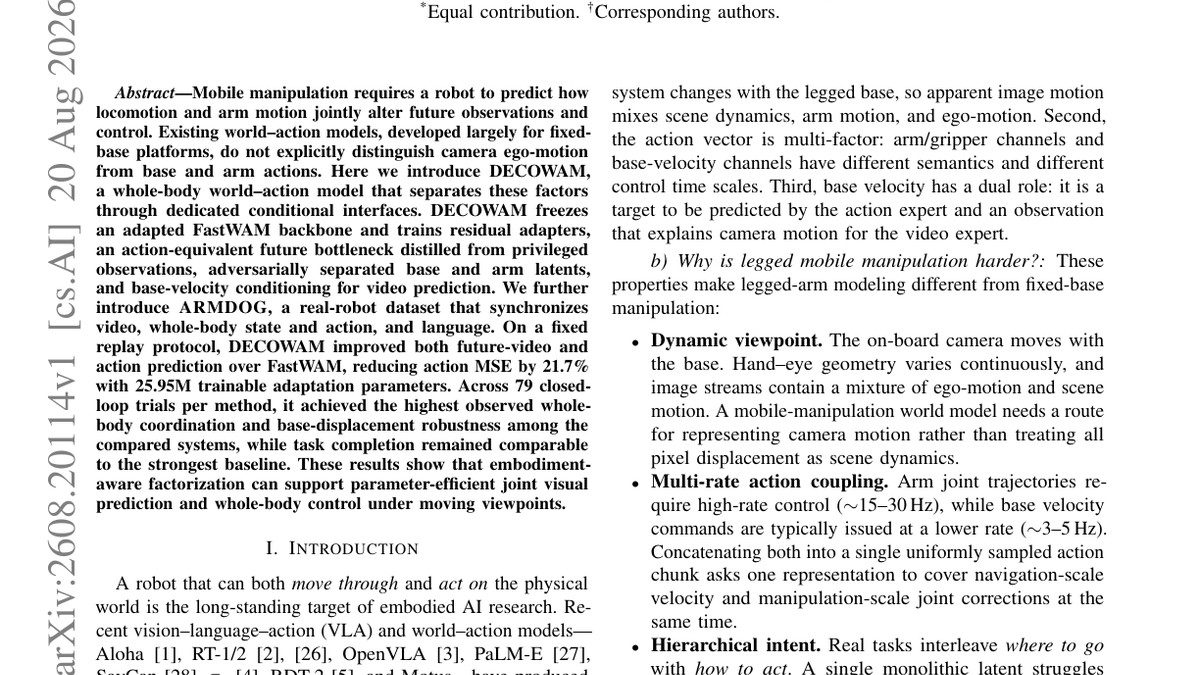
DECOWAM: Decoupled Whole-Body World-Action Model for Legged Mobile Manipulation
arXiv preprint

DECOWAM: Decoupled Whole-Body World-Action Model for Legged Mobile Manipulation

Siyuan Ma, Boshi Zhang, Yutian Zhang et al.

Mobile manipulation requires a robot to predict how locomotion and arm motion jointly alter future observations and control. Existing world-action models, developed largely for fixed-base platforms, do not explicitly distinguish camera ego-motion from base and arm actions.

manipulation locomotion vision reinforcement-learning control benchmark
PDF Intermediate
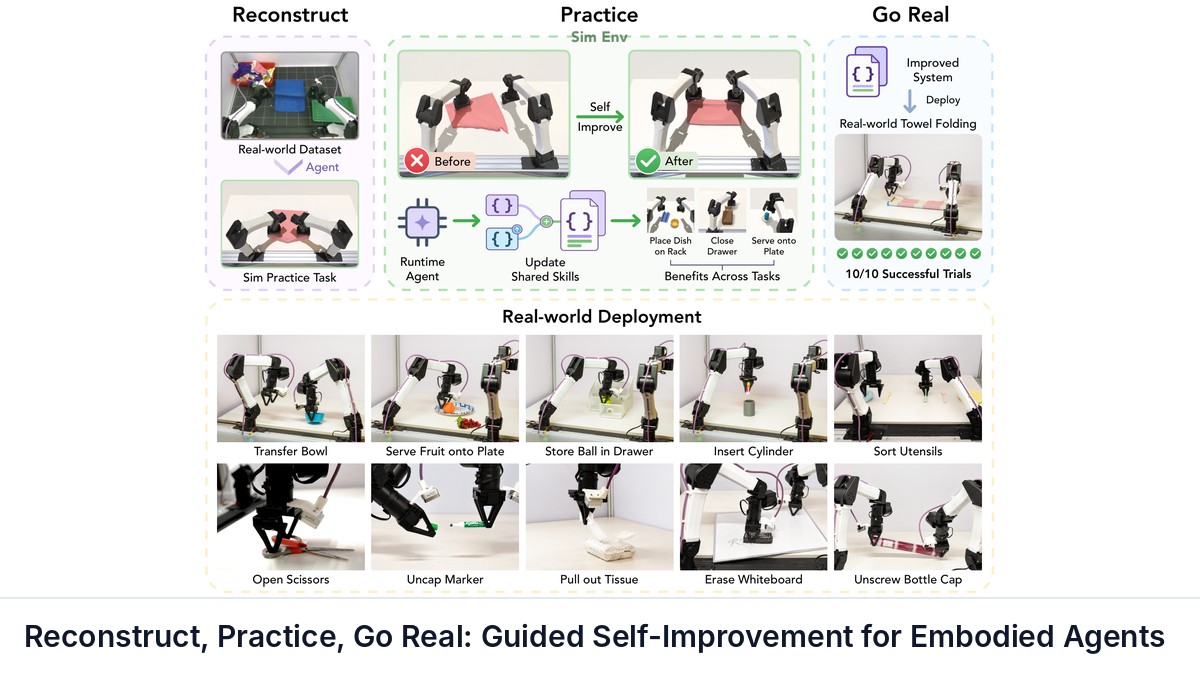
Deliberate Practice: Learning Robot Skills under a Budget
arXiv preprint

Deliberate Practice: Learning Robot Skills under a Budget

Shivam Vats, Sudarshan Harithas, Mete Tuluhan Akbulut et al.

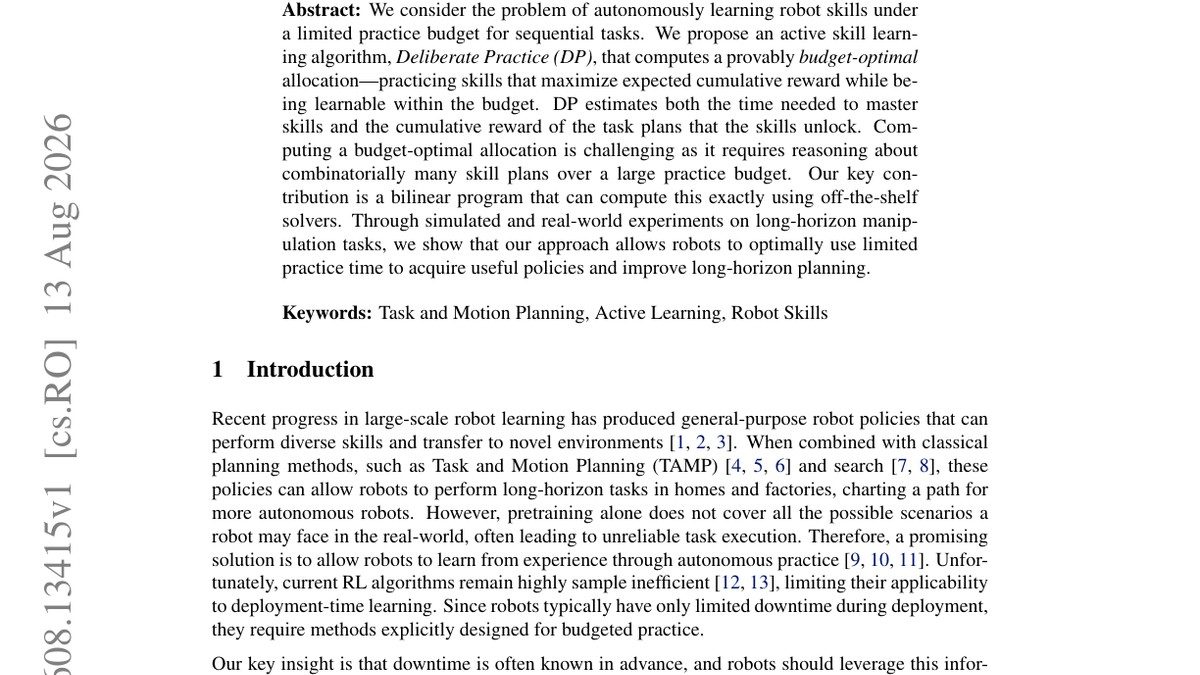
We consider the problem of autonomously learning robot skills under a limited practice budget for sequential tasks.

manipulation reinforcement-learning planning
PDF Intermediate
Development of a Humanoid Robot Prototype for Multimodal Human-Robot Interaction
arXiv preprint

Development of a Humanoid Robot Prototype for Multimodal Human-Robot Interaction

Thang Tran Viet, Thanh Nguyen Canh, Huy Uong Gia et al.

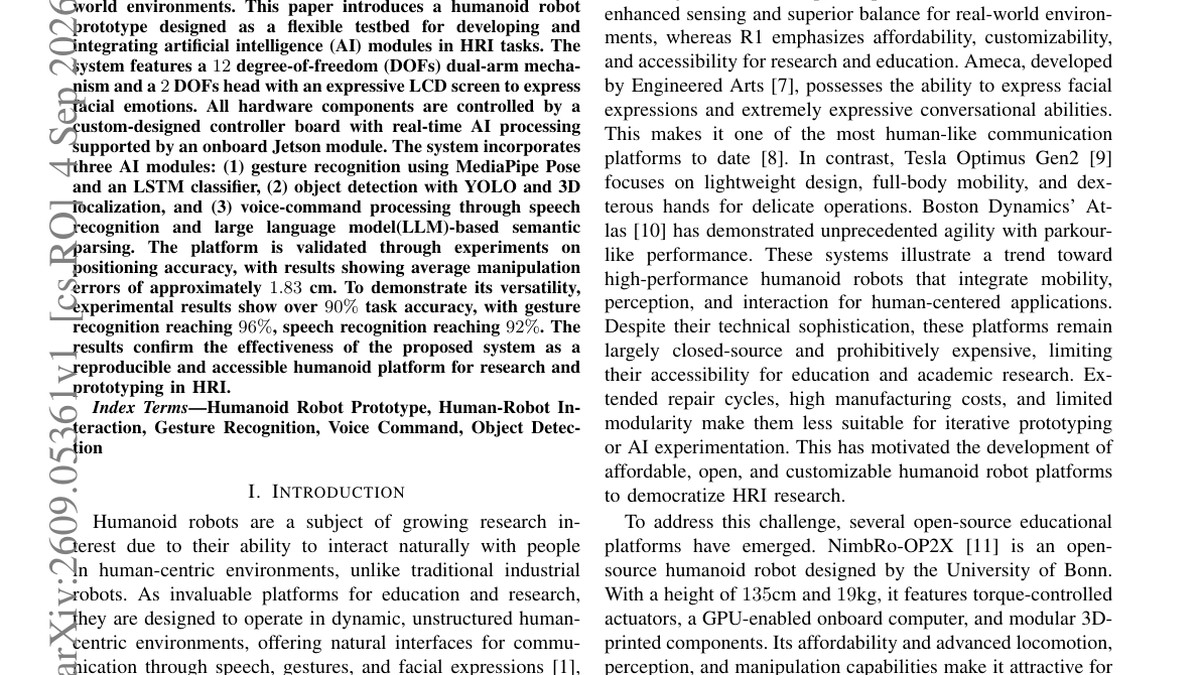
Human-robot interaction (HRI) enables intuitive and intelligent collaboration between humans and robots in real-world environments. This paper introduces a humanoid robot prototype designed as a flexible testbed for developing and integrating artificial intelligence (AI) modules in HRI tasks.

manipulation vision vla reinforcement-learning control human-robot-interaction
Code PDF Intermediate
GitHub ★ —
DexPort: A Hand-Held Skill Interface for Dexterous Hand Data Collection
arXiv preprint

DexPort: A Hand-Held Skill Interface for Dexterous Hand Data Collection

Amber Xie, Jiawei Fu, Xiaofeng Guo et al.

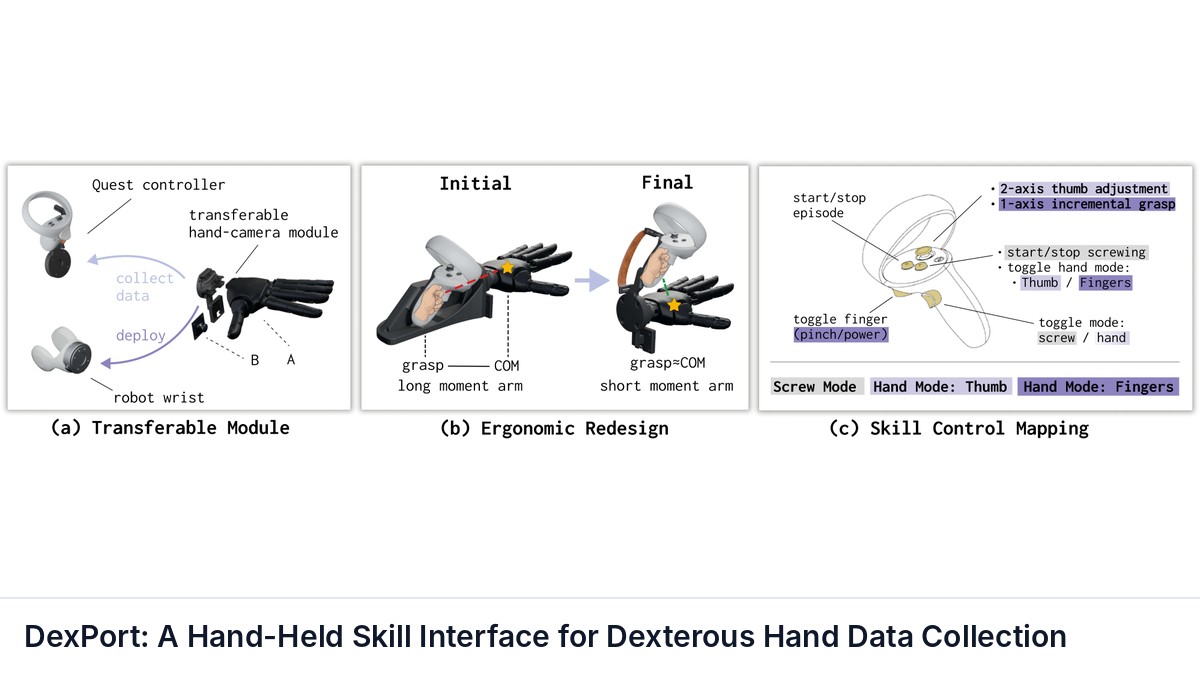
Collecting high-quality demonstrations remains a central bottleneck for learning dexterous manipulation. Teleoperation records executable robot actions, but it requires a complete robot setup and places the burden of coordinating many finger joints on the operator.

manipulation reinforcement-learning control learning-from-demonstration
PDF Intermediate
Dexterity from Supervised Play
arXiv preprint

Dexterity from Supervised Play

Botao He, Yiming Dou, Yiannis Aloimonos et al.

How can robots autonomously collect the contact-rich experience needed to learn dexterous manipulation?

manipulation reinforcement-learning sim-to-real planning control learning-from-demonstration benchmark
Code PDF Intermediate
GitHub ★ —
DexVerse: A Modular Benchmark for Multi-Task, Multi-Embodiment Dexterous Manipulation
arXiv preprint

DexVerse: A Modular Benchmark for Multi-Task, Multi-Embodiment Dexterous Manipulation

Yunchao Yao, Zhuxiu Xu, Tianqi Zhang et al.

Building general-purpose dexterous manipulation policies requires benchmarks that go beyond isolated tasks to systematically evaluate policies across diverse interaction modes, sensory conditions, and robot embodiments.

manipulation vision vla reinforcement-learning control learning-from-demonstration benchmark
PDF Advanced
DITTO: Dexterous Interface for Transparent TeleOperation
arXiv preprint

DITTO: Dexterous Interface for Transparent TeleOperation

Joaquin Palacios, Katelyn Lee, Cheng Zhang et al.

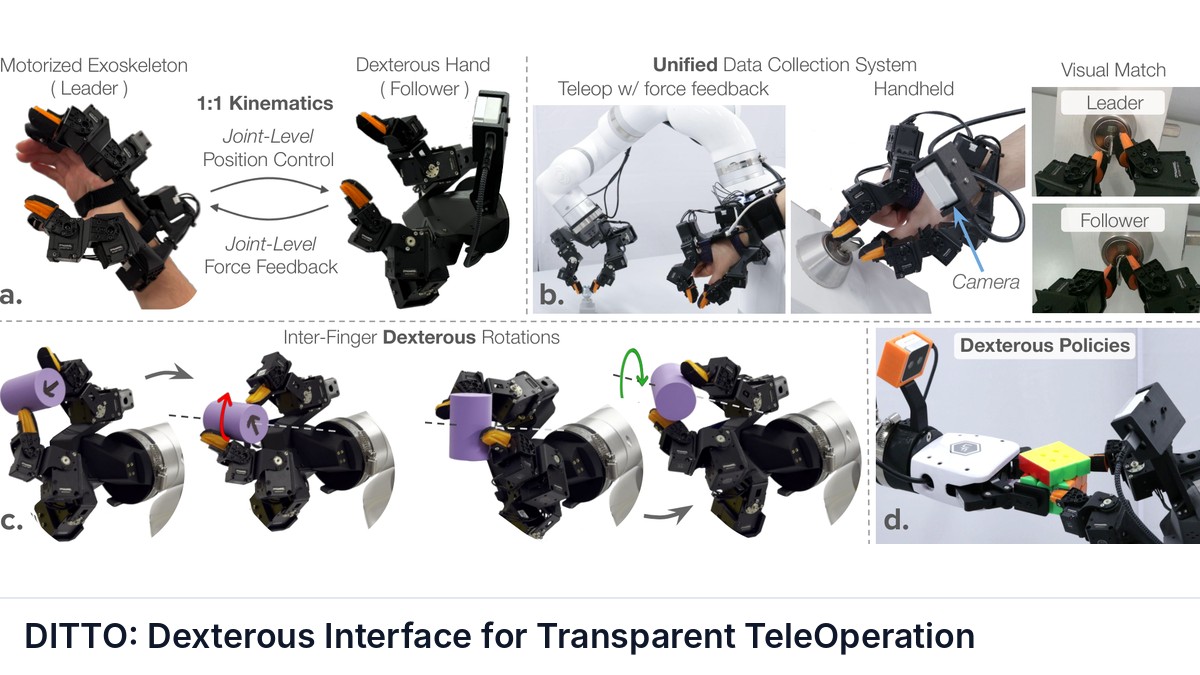
Collecting data for manipulation with high-DOF hands is challenging, as interfaces must capture rich hand motion while rendering the contact interactions essential for precise manipulation.

manipulation vision learning-from-demonstration
Code PDF Intermediate
GitHub ★ —
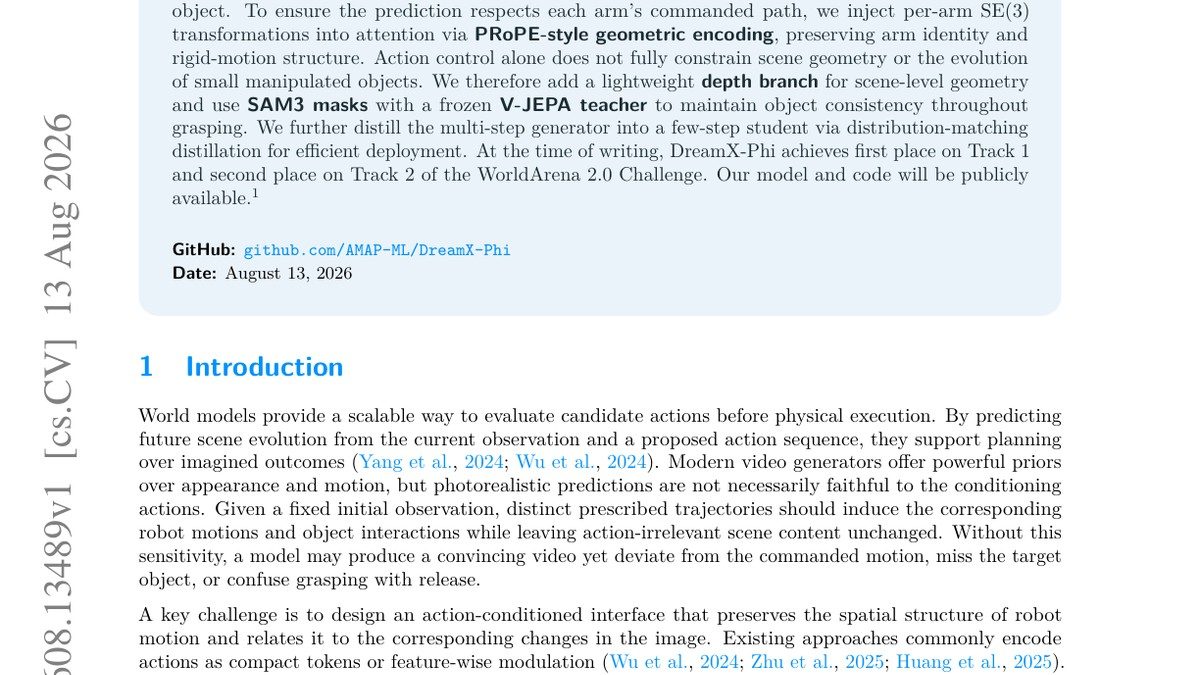
DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation
arXiv preprint

DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation

DreamX Team, Rui Chen, Xiangxiang Chu et al.

We present \textbf{DreamX-Phi 1.0}, an action-conditioned video world model for robotic manipulation that, given an observed frame, a language instruction, and a prescribed action sequence comprising end-effector poses and gripper states, predicts the resulting future observations.

manipulation reinforcement-learning control
PDF Intermediate
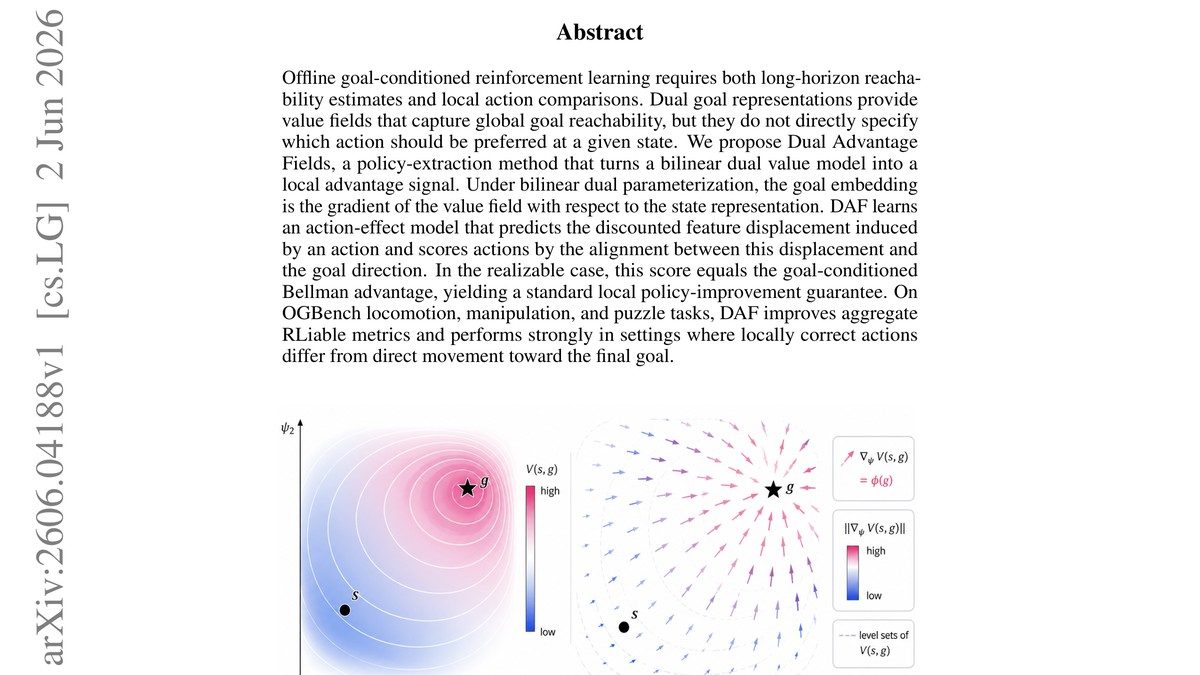
Dual Advantage Fields
ICML 2026

Dual Advantage Fields

Alexey Zemtsov, Maxim Bobrin, Alexander Nikulin et al.

Offline goal-conditioned reinforcement learning requires both long-horizon reachability estimates and local action comparisons. Dual goal representations provide value fields that capture global goal reachability, but they do not directly specify which action should be preferred at a given state.

reinforcement-learning manipulation locomotion
PDF Advanced
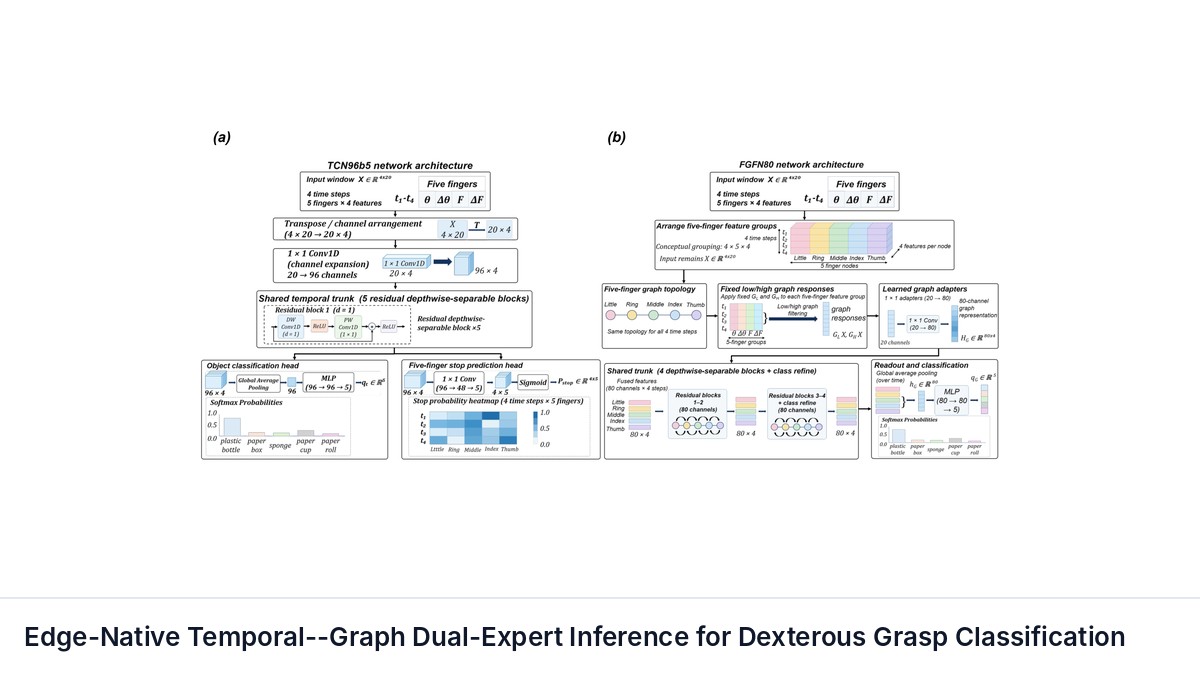
Edge-Native Temporal--Graph Dual-Expert Inference for Dexterous Grasp Classification
arXiv preprint

Edge-Native Temporal--Graph Dual-Expert Inference for Dexterous Grasp Classification

Jiajian Zheng, Bin Zhang, Wen Fan et al.

Multi-finger hands contact objects at different times, so a global close command can overload early-contact fingers while others are still moving. Dense tactile arrays address this problem but add hardware, calibration, bandwidth, and computation.

manipulation reinforcement-learning tactile benchmark
PDF Intermediate
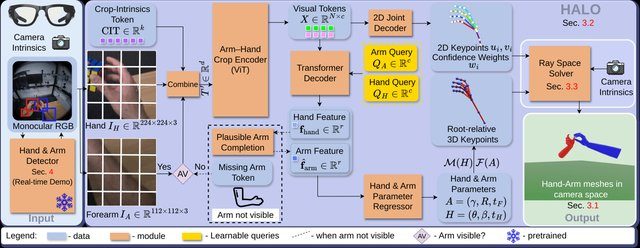
EgoForce: Forearm-Guided Camera-Space 3D Hand Pose from a Monocular Egocentric Camera
SIGGRAPH 2026

EgoForce: Forearm-Guided Camera-Space 3D Hand Pose from a Monocular Egocentric Camera

Christen Millerdurai, Shaoxiang Wang, Yaxu Xie et al.

Reconstructing the absolute 3D pose and shape of the hands from the user's viewpoint using a single head-mounted camera is crucial for practical egocentric interaction in AR/VR, telepresence, and hand-centric manipulation tasks, where sensing must remain compact and unobtrusive.

manipulation manipulation simulation
Code PDF Intermediate
Code ★ 0
Evidence-Gated Task and Motion Planning with Vision-Language Models
arXiv preprint

Evidence-Gated Task and Motion Planning with Vision-Language Models

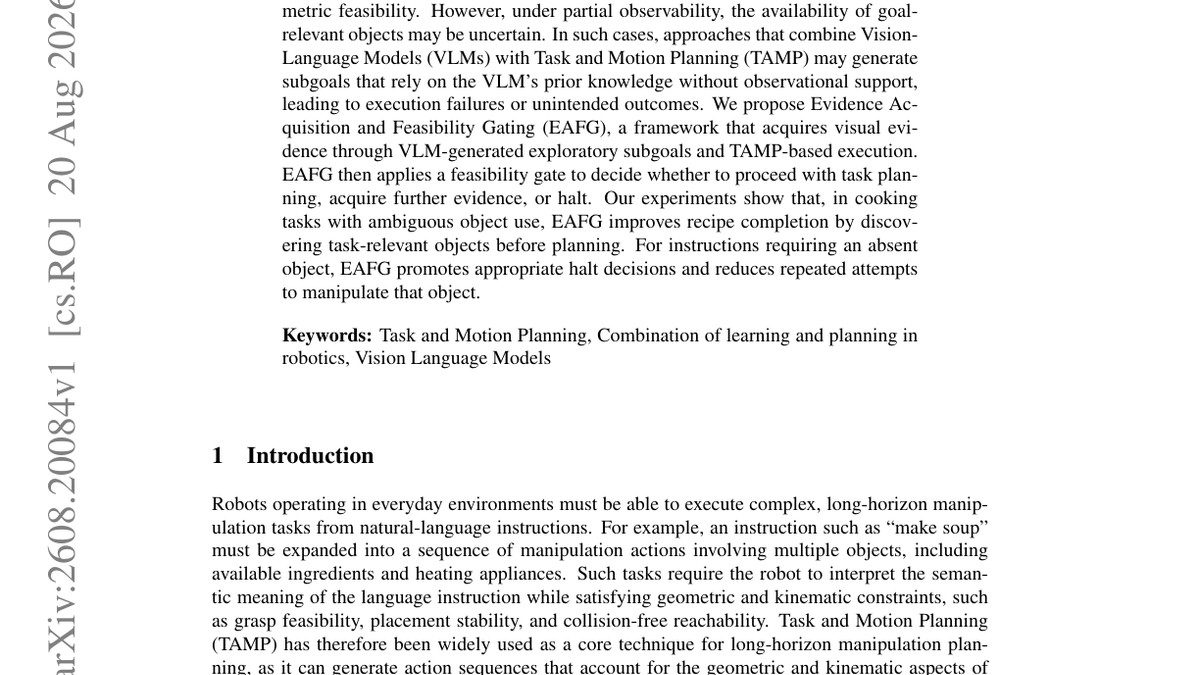
Tsunehiko Tanaka, Matthew Stephenson, Alistair Macvicar et al.

Robots executing long-horizon manipulation tasks from natural-language instructions must reason about both semantic task structure and geometric feasibility. However, under partial observability, the availability of goal-relevant objects may be uncertain.

manipulation vision vla reinforcement-learning planning
PDF Intermediate
Fast Planning for Multi-object Multi-target Throwing
arXiv preprint

Fast Planning for Multi-object Multi-target Throwing

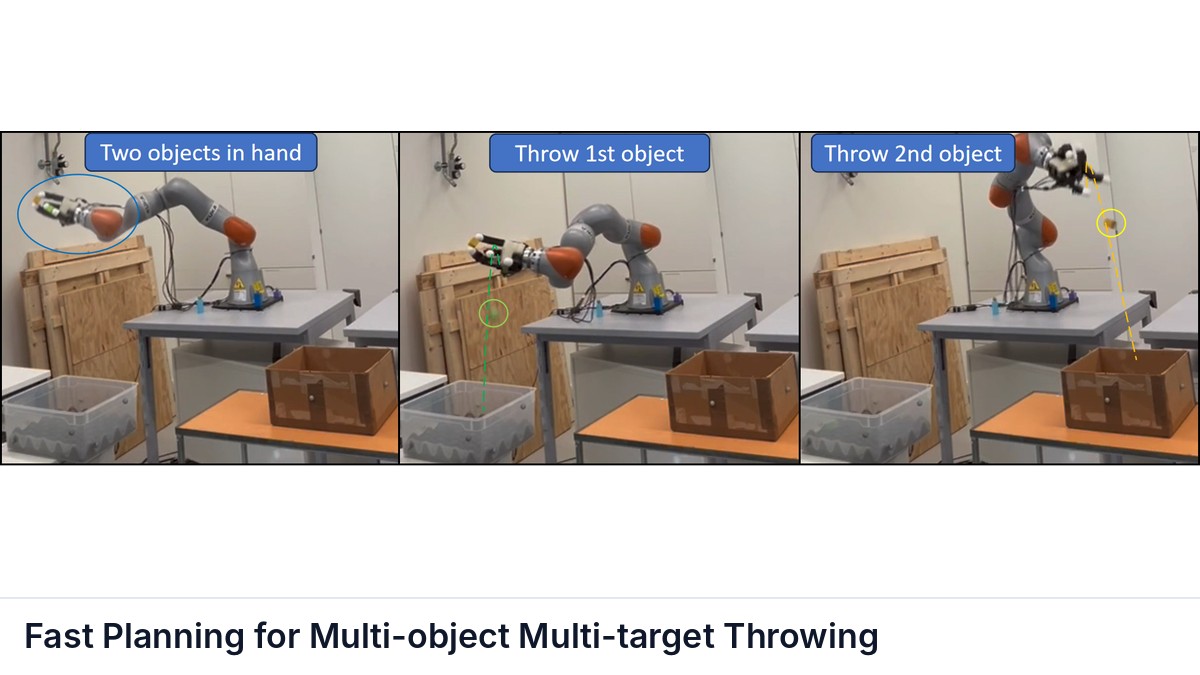
Zhengming Zhu, Yang Liu, Xiao Gao et al.

Robot throwing has emerged as a promising technique for improving efficiency in logistics and warehouse automation, by enlarging the workspace and speeding up the process. To significantly increase the throwing system's throughput, we develop strategies for throwing multiple objects in one swipe.

manipulation reinforcement-learning planning
Code PDF Intermediate
GitHub ★ —
Faster Visuomotor Policy Learning on Action Manifolds via Riemannian MeanFlow
arXiv preprint

Faster Visuomotor Policy Learning on Action Manifolds via Riemannian MeanFlow

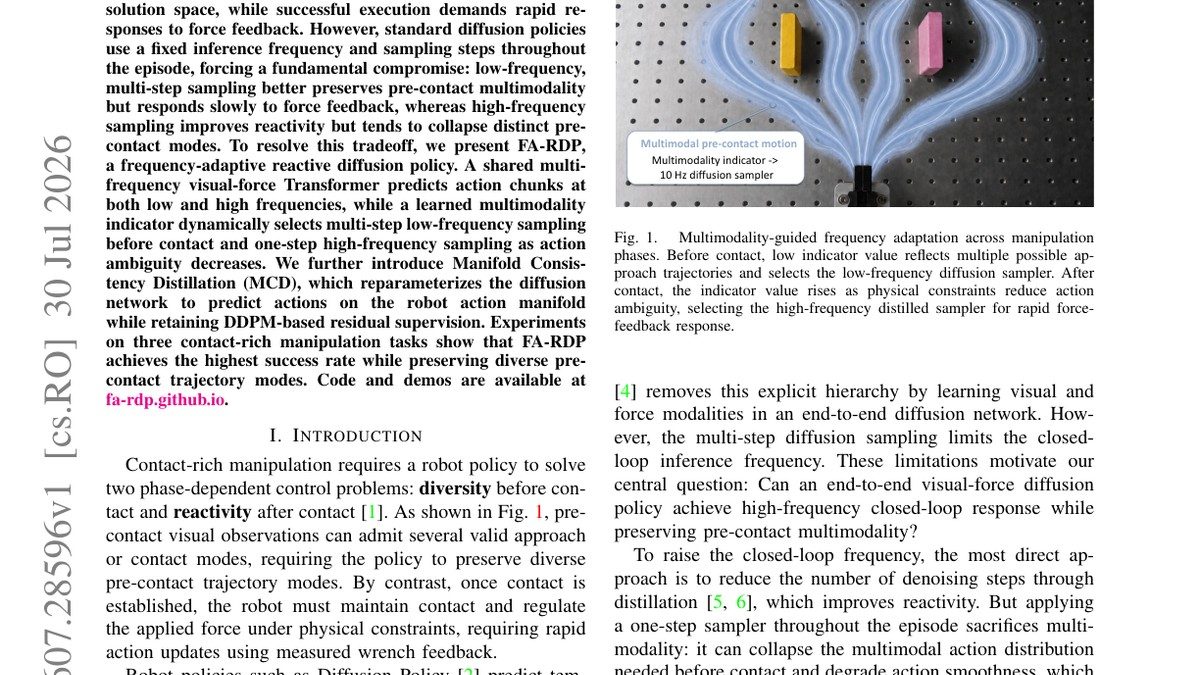
S. Talha Bukhari, Austin Garrett, Yi Wei et al.

Visuomotor policies learn a direct map from raw sensory observations to robot action sequences. Policies based on Diffusion and Flow Matching capture the multimodal distribution over action sequences in an end-to-end manner.

manipulation reinforcement-learning control benchmark
PDF Advanced
Fiatlux: A Long-Horizon Benchmark for Humanoid Ladder Climbing and Light-Bulb Replacement
arXiv preprint

Fiatlux: A Long-Horizon Benchmark for Humanoid Ladder Climbing and Light-Bulb Replacement

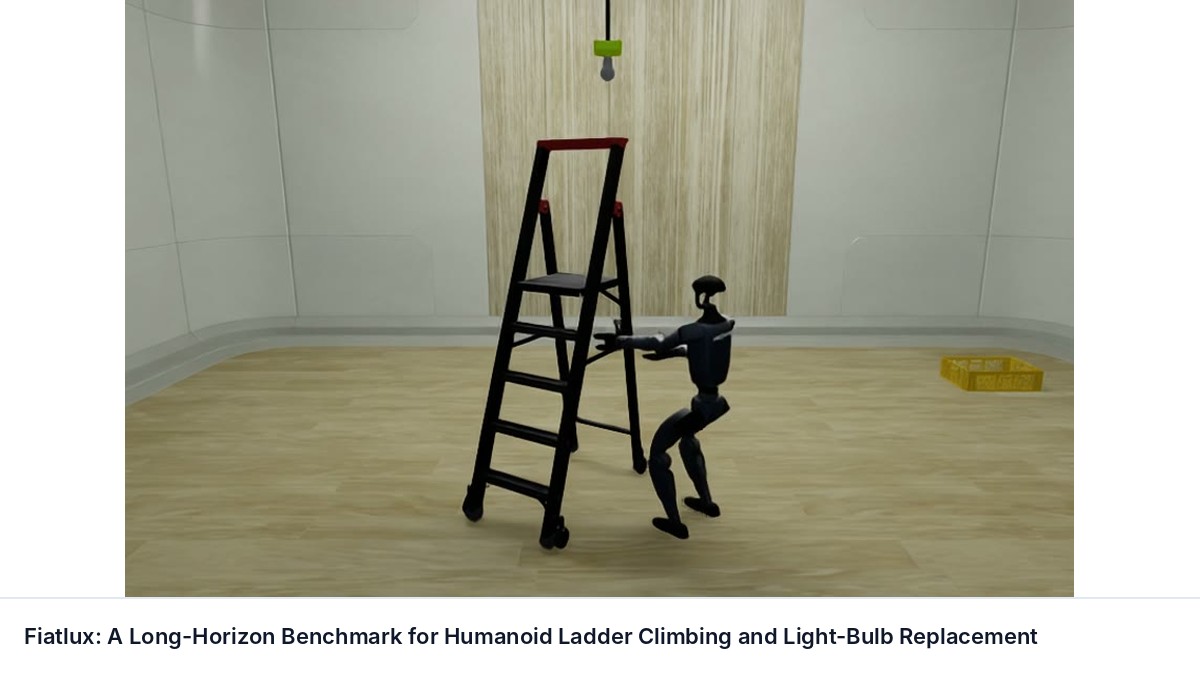
Pavel Bushuyeu, Yujin Chen, Anton Nikolaev et al.

Existing benchmarks evaluate tabletop manipulation, flat-floor household activity, or humanoid locomotion and manipulation as separate task groups; none scores vertical mobility and dexterous work on a fragile payload in one long-horizon episode.

manipulation locomotion vision vla reinforcement-learning control benchmark
PDF Intermediate
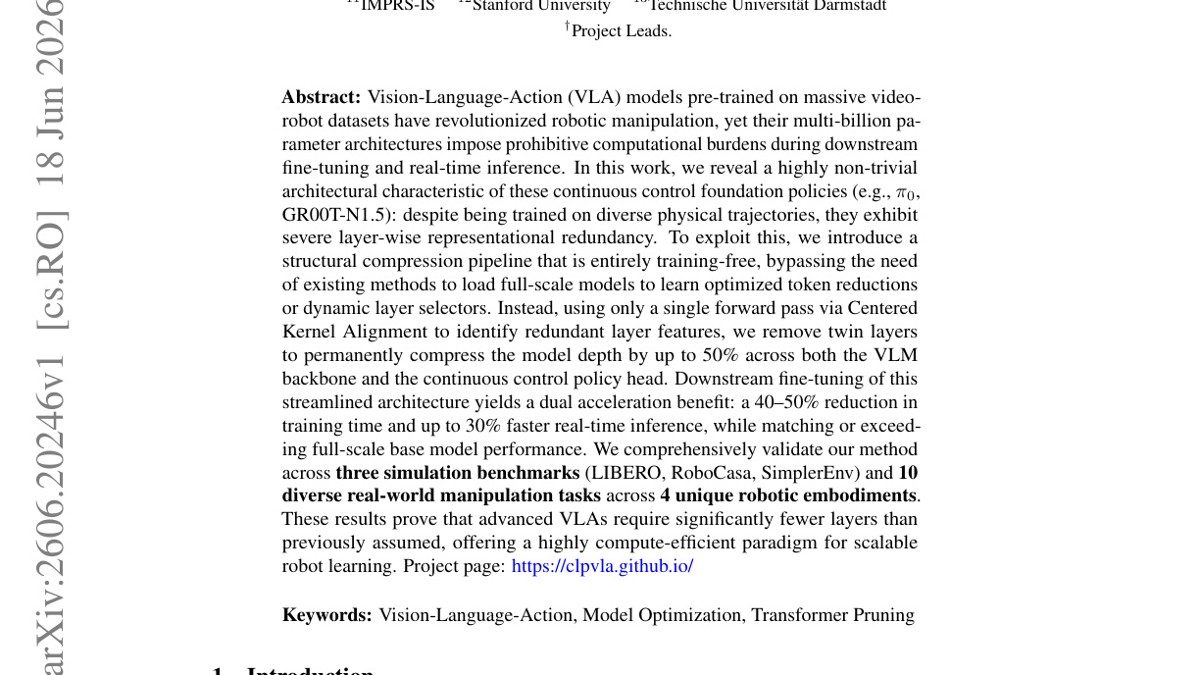
Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think
arXiv preprint

Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think

Gia-Binh Nguyen, Trong-Bao Ho, Thien-Loc Ha et al.

Vision-Language-Action (VLA) models pre-trained on massive video-robot datasets have revolutionized robotic manipulation, yet their multi-billion parameter architectures impose prohibitive computational burdens during downstream fine-tuning and real-time inference.

ar-vr evaluation manipulation
PDF Intermediate
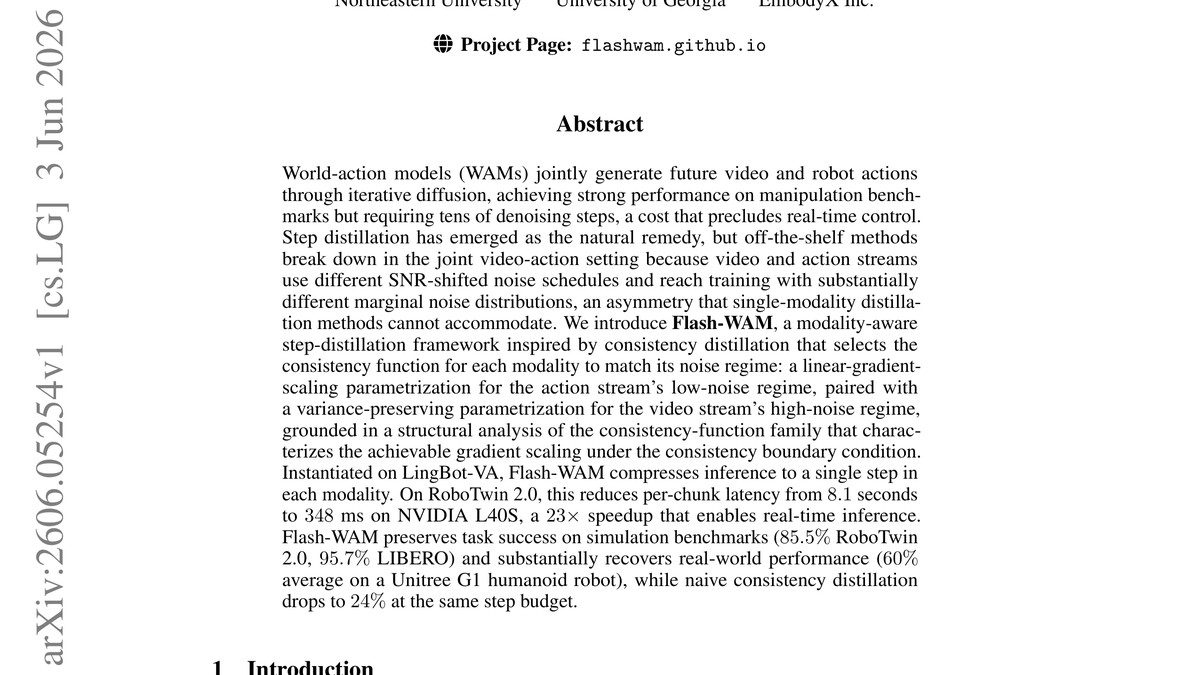
Flash-WAM: Modality-Aware Distillation for World Action Models
arXiv preprint

Flash-WAM: Modality-Aware Distillation for World Action Models

Arman Akbari, Ci Zhang, Arash Akbari et al.

World-action models (WAMs) jointly generate future video and robot actions through iterative diffusion, achieving strong performance on manipulation benchmarks but requiring tens of denoising steps, a cost that precludes real-time control.

sim-to-real reinforcement-learning diffusion-policy manipulation humanoid
PDF Intermediate
Aligning Flow Map Policies with Optimal Q-Guidance
arXiv

Aligning Flow Map Policies with Optimal Q-Guidance

Christos Ziakas, Alessandra Russo, Avishek Joey Bose

Generative policies based on expressive model classes, such as diffusion-models and flow matching, are well-suited to complex control problems with highly multimodal action distributions.

rl diffusion-models manipulation
PDF Advanced
FORCA: A Force-Aware Coding Agent for Contact-Rich Robot Manipulation
arXiv preprint

FORCA: A Force-Aware Coding Agent for Contact-Rich Robot Manipulation

Xiao Tan, Yixuan Wang, Zhexi Wang et al.

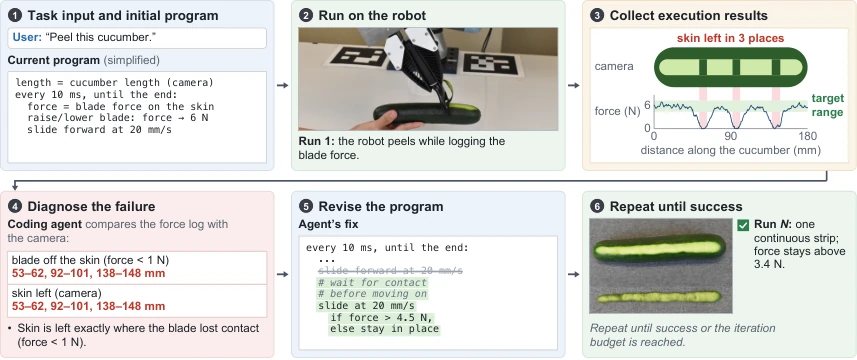
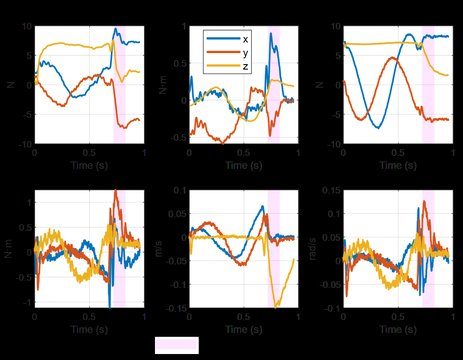
FORCA lets a coding agent use wrist force/torque readings both while its robot program runs and when it revises that program between real-robot attempts, without demonstrations or task-specific training.

manipulation vision control learning-from-demonstration
PDF Intermediate
ForeTac-VLA: A Forecasting-Based Tactile-Vision-Language-Action Model for Contact-Rich Robotic Manipulation
arXiv preprint

ForeTac-VLA: A Forecasting-Based Tactile-Vision-Language-Action Model for Contact-Rich Robotic Manipulation

Zhengyu Tao, Xin Li, Xin Wang

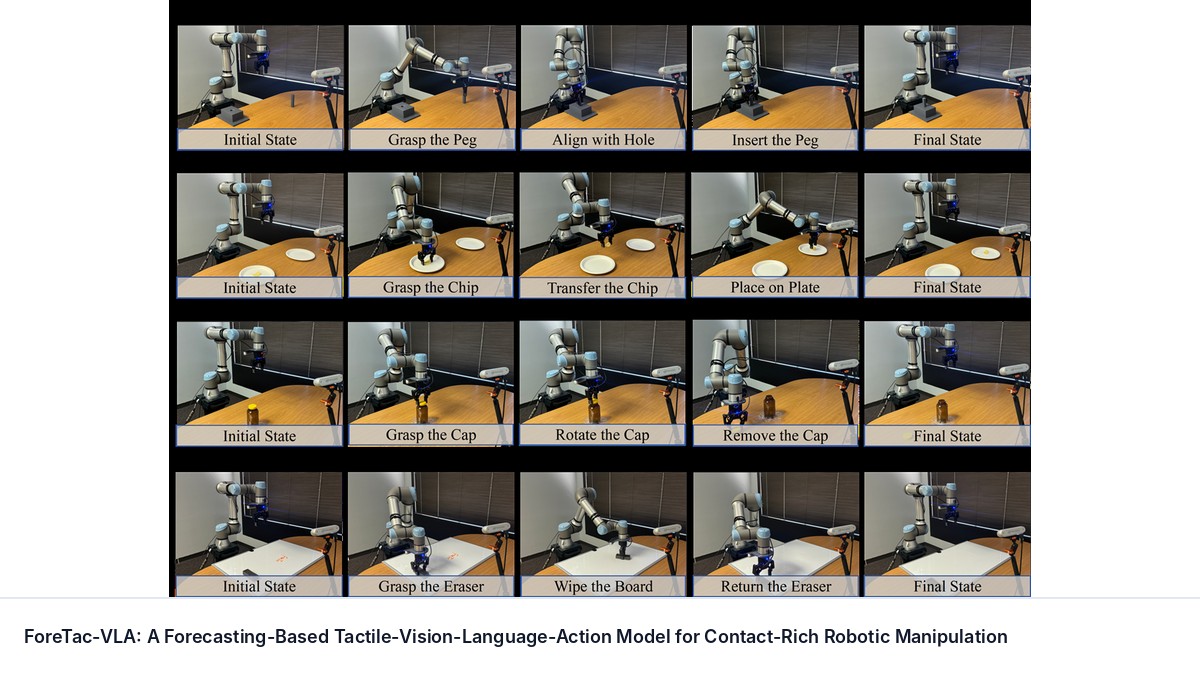
Vision-language-action (VLA) models have demonstrated strong capabilities in robotic manipulation, yet their reliance on visual perception limits robustness in contact-rich environments, where critical physical interaction states may not be visually observable.

manipulation vision vla reinforcement-learning learning-from-demonstration tactile
PDF Intermediate
From Pretraining to Proficiency: Real-World Subtask RL for Long-Horizon Manipulation with Minimal Human Intervention
arXiv preprint

From Pretraining to Proficiency: Real-World Subtask RL for Long-Horizon Manipulation with Minimal Human Intervention

Sichang Su, Benjamin Yang, Zhiyun Deng et al.

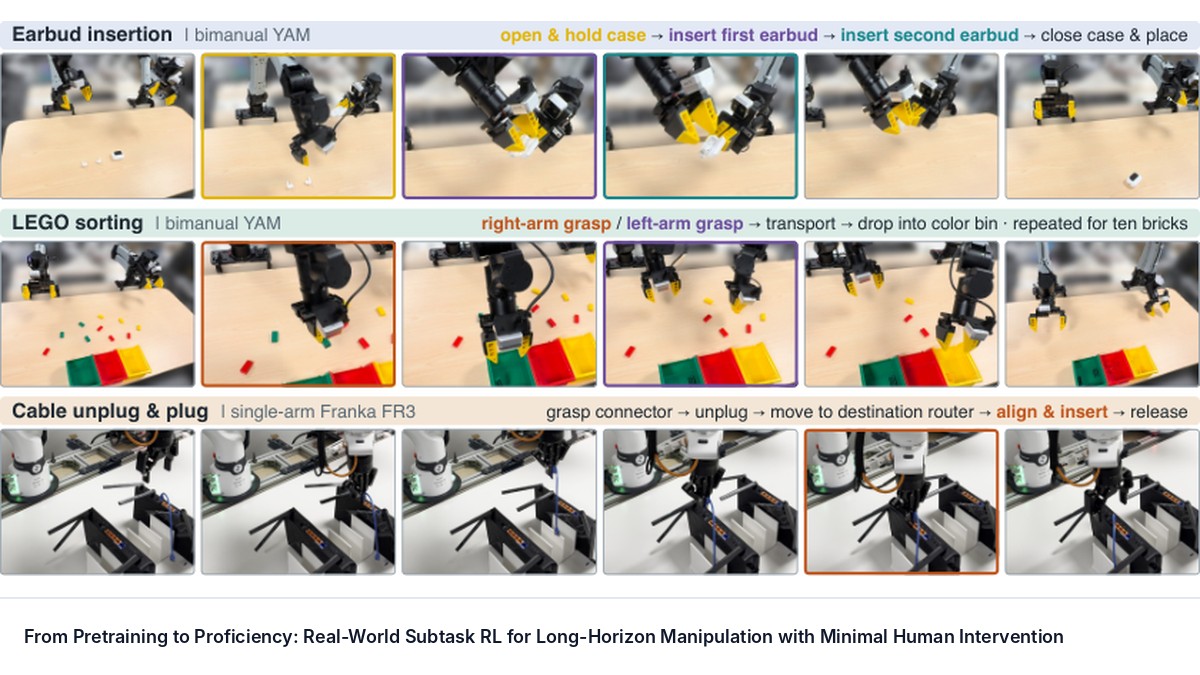
A pretrained robot foundation policy may execute most of a long-horizon task yet repeatedly fail at a few critical subtasks. Collecting additional full-task demonstrations for supervised fine-tuning (SFT) requires operators to repeat behaviors the policy already performs well.

manipulation reinforcement-learning learning-from-demonstration
Code PDF Intermediate
GitHub ★ —
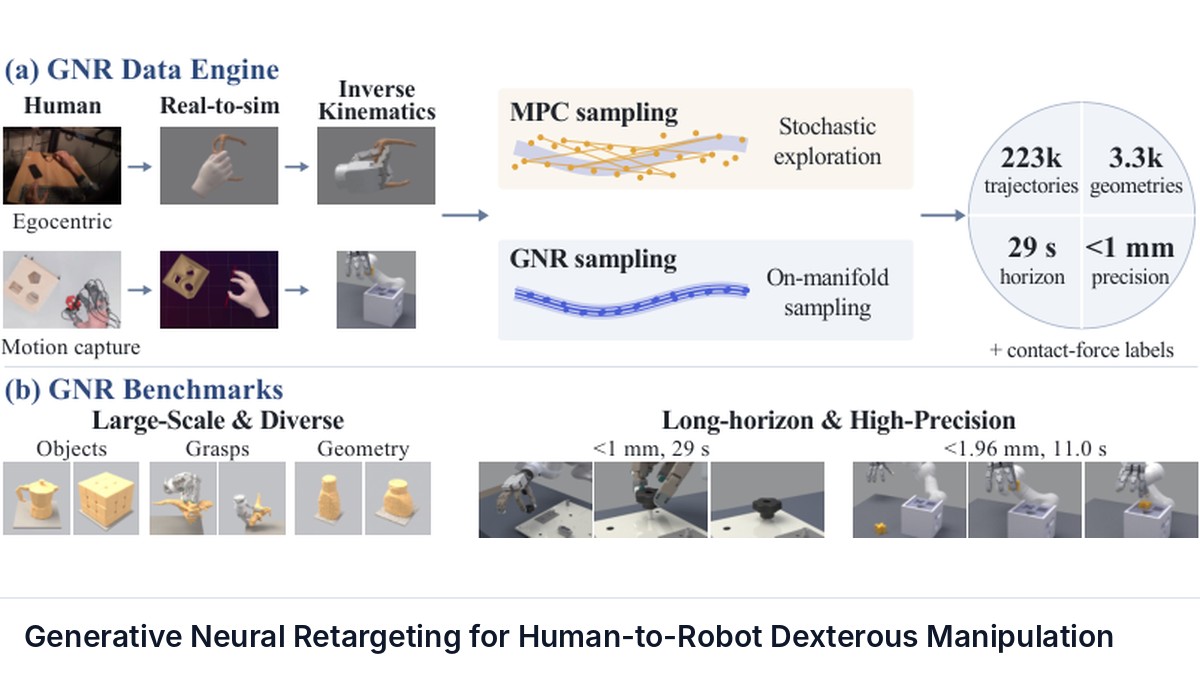
Generative Neural Retargeting for Human-to-Robot Dexterous Manipulation
arXiv preprint

Generative Neural Retargeting for Human-to-Robot Dexterous Manipulation

Dechen Gao, Yue Yang, Ben Abbatematteo et al.

Human demonstrations are a scalable data source for learning dexterous manipulation, but the embodiment gap prevents human motion from being executed directly on robots. Inverse kinematics (IK) retargets human motion to robots efficiently but ignores dynamics, often producing infeasible motions.

manipulation reinforcement-learning control learning-from-demonstration benchmark
PDF Advanced
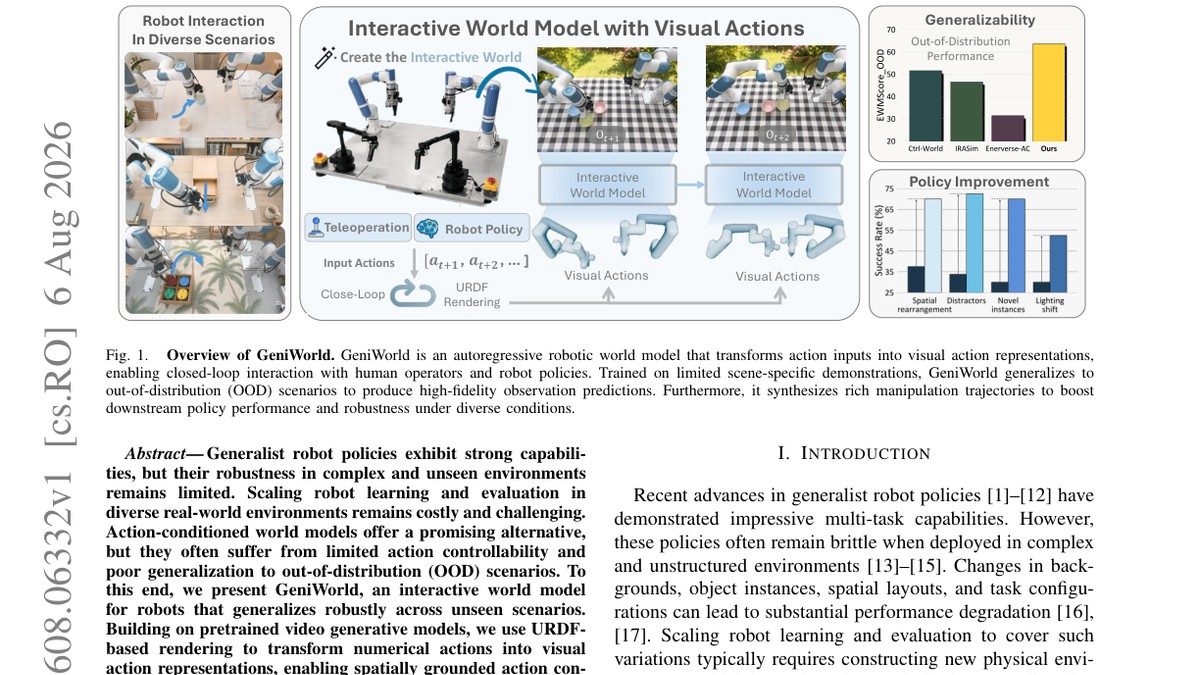
GeniWorld: A Generalizable Interactive World Model for Robotic Manipulation via Visual Actions
arXiv preprint

GeniWorld: A Generalizable Interactive World Model for Robotic Manipulation via Visual Actions

Chenghao Gu, Hanyang Yu, Jingbo Zhang et al.

Generalist robot policies exhibit strong capabilities, but their robustness in complex and unseen environments remains limited. Scaling robot learning and evaluation in diverse real-world environments remains costly and challenging.

manipulation vision reinforcement-learning control learning-from-demonstration benchmark
PDF Intermediate
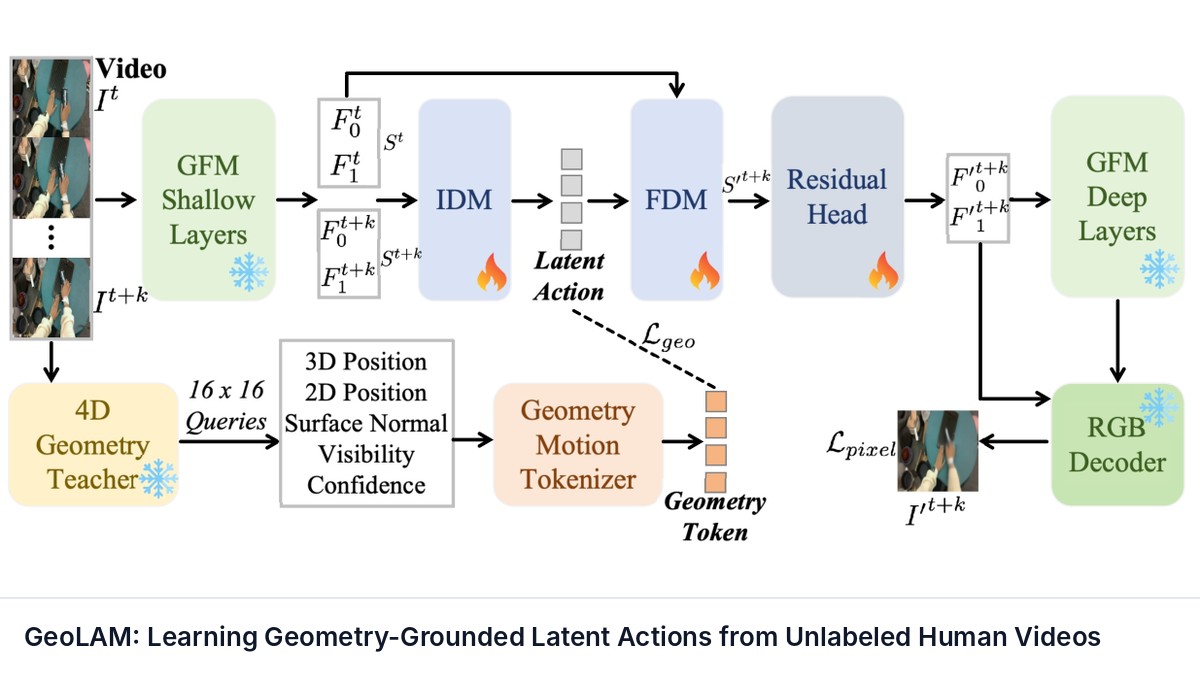
GeoLAM: Learning Geometry-Grounded Latent Actions from Unlabeled Human Videos
arXiv preprint

GeoLAM: Learning Geometry-Grounded Latent Actions from Unlabeled Human Videos

Yifan Xie, Hekun Tian, Jinkun Liu et al.

Human videos provide rich manipulation experience, but extracting action representations that preserve useful motion remains challenging. Visual reconstruction alone can entangle manipulation-related motion with appearance changes and camera movement.

manipulation vision reinforcement-learning learning-from-demonstration benchmark
PDF Intermediate
GesVLA: Gesture-Aware Vision-Language-Action Model
arXiv preprint

GesVLA: Gesture-Aware Vision-Language-Action Model

Wenxuan Guo, Ziyuan Li, Meng Zhang et al.

GesVLA augments standard VLA models with gesture awareness, enabling robots to interpret verbal instructions alongside human hand gestures for disambiguated manipulation.

vla manipulation hand-tracking
Code PDF Intermediate
GitHub ★ 18 Updated May 2026
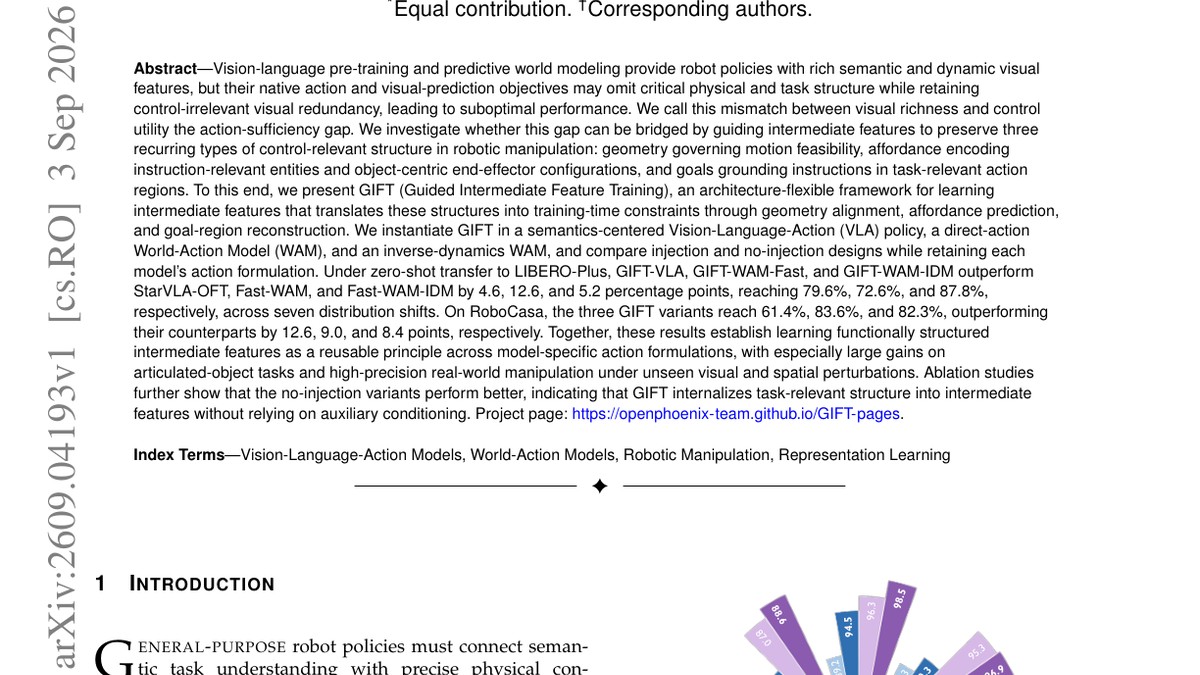
GIFT: Guided Intermediate Feature Training via Action-Oriented Structural Supervision for Robotic Manipulation
arXiv preprint

GIFT: Guided Intermediate Feature Training via Action-Oriented Structural Supervision for Robotic Manipulation

Yupeng Zheng, Xiang Li, Songen Gu et al.

Vision-language pre-training and predictive world modeling provide robot policies with rich semantic and dynamic visual features, but their native action and visual-prediction objectives may omit critical physical and task structure while retaining control-irrelevant visual redundancy.

manipulation vision vla reinforcement-learning control
PDF Intermediate
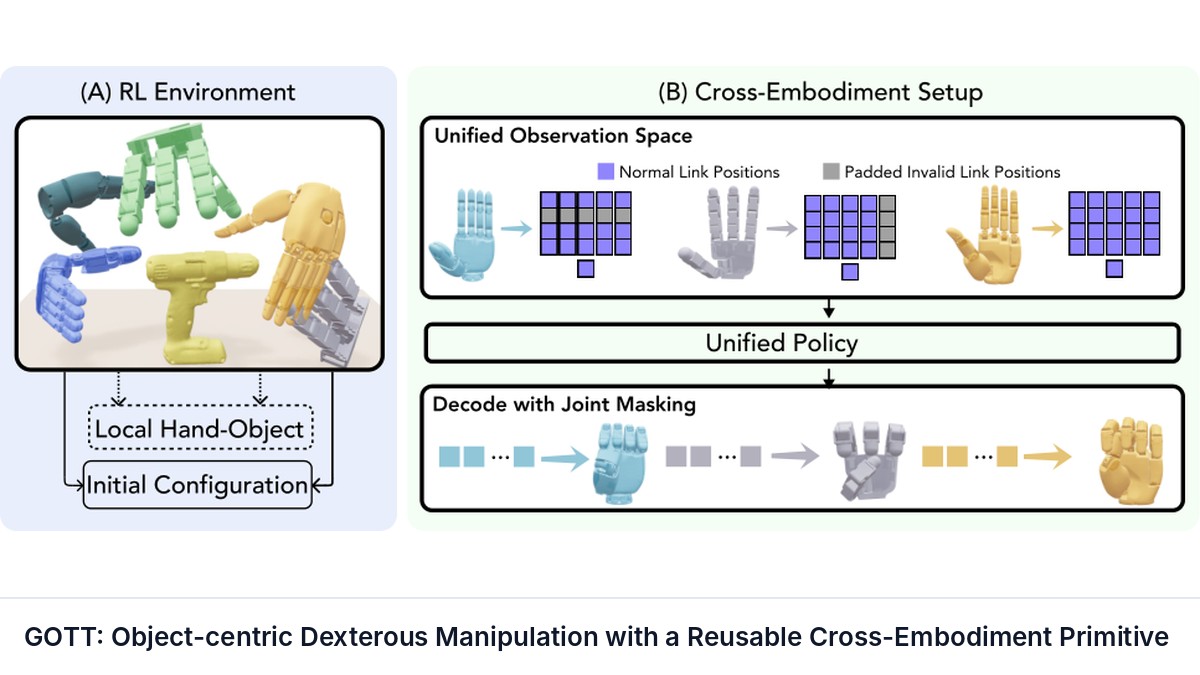
GOTT: Object-centric Dexterous Manipulation with a Reusable Cross-Embodiment Primitive
arXiv preprint

GOTT: Object-centric Dexterous Manipulation with a Reusable Cross-Embodiment Primitive

Yulin Liu, Lai Wei, Yen-Jen Wang et al.

Foundation models and large-scale human data provide rich sources of manipulation intent, but translating this intent into multi-fingered robot behavior remains difficult. Dexterous hands still lack a reusable low-level primitive that reliably establishes contact across tasks and embodiments.

manipulation reinforcement-learning planning control learning-from-demonstration
PDF Advanced
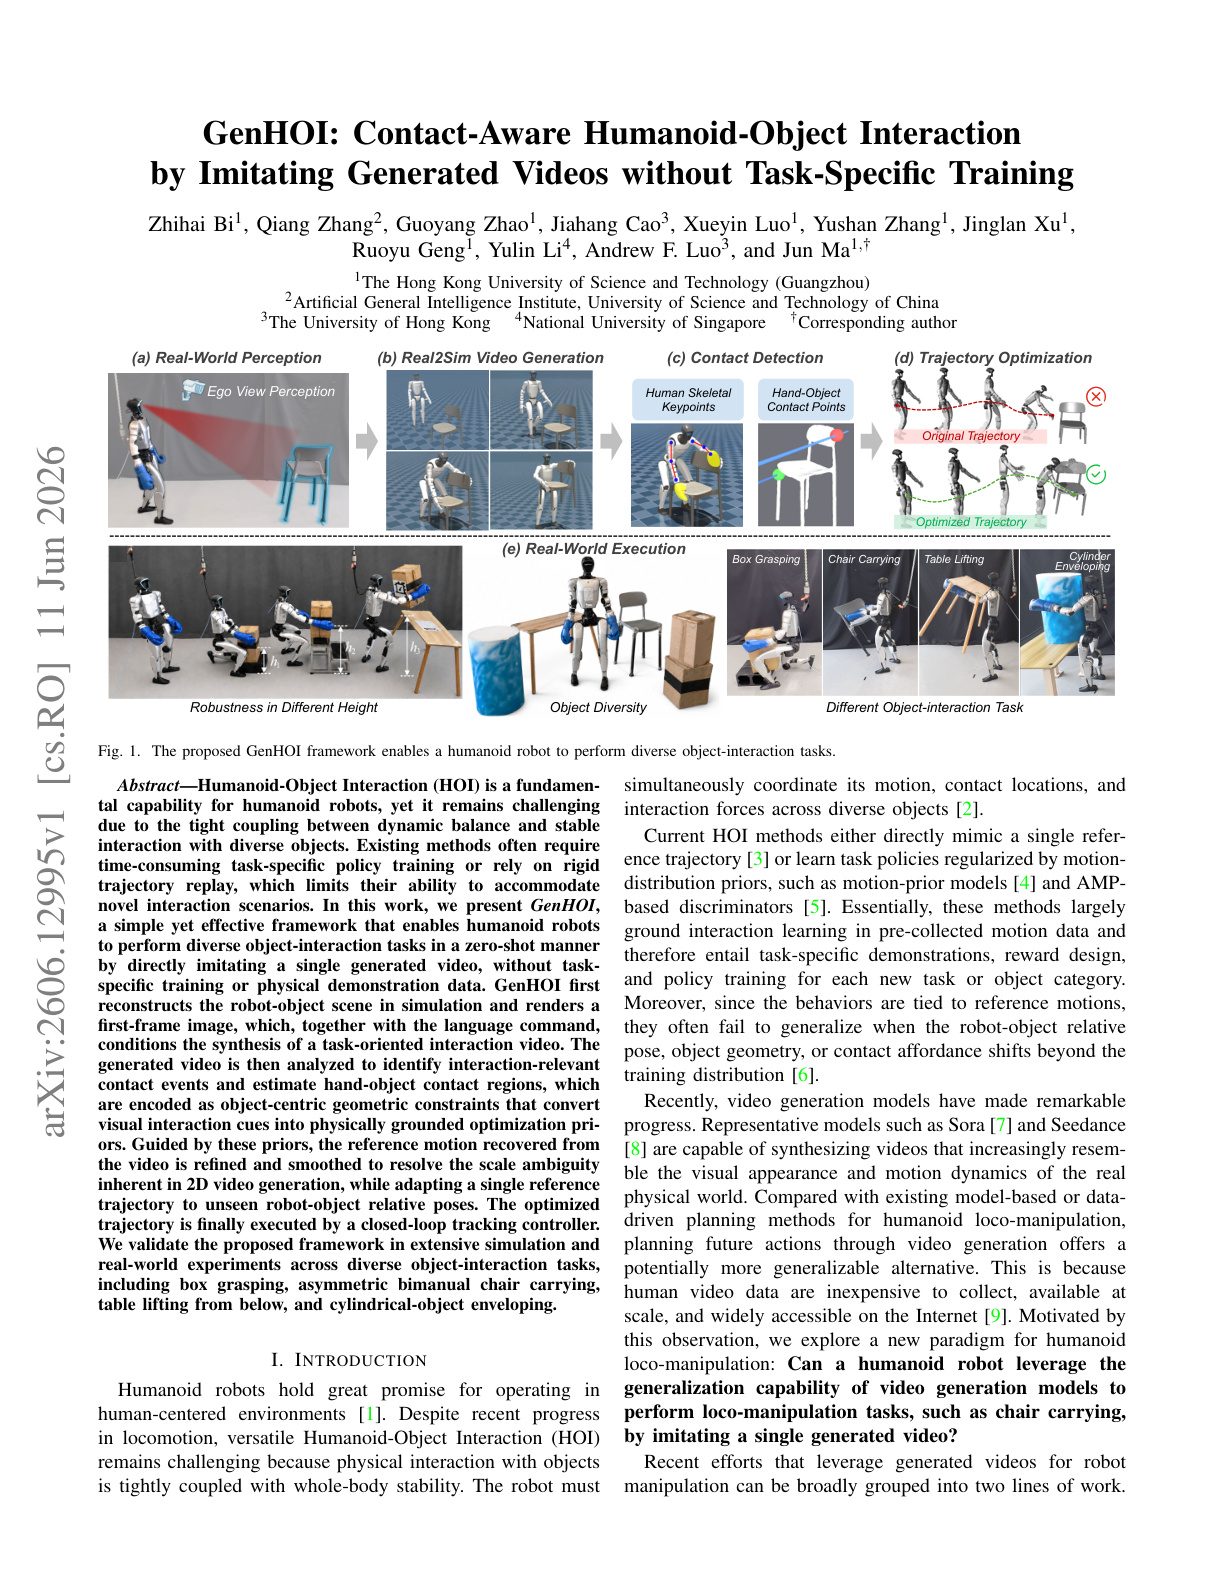
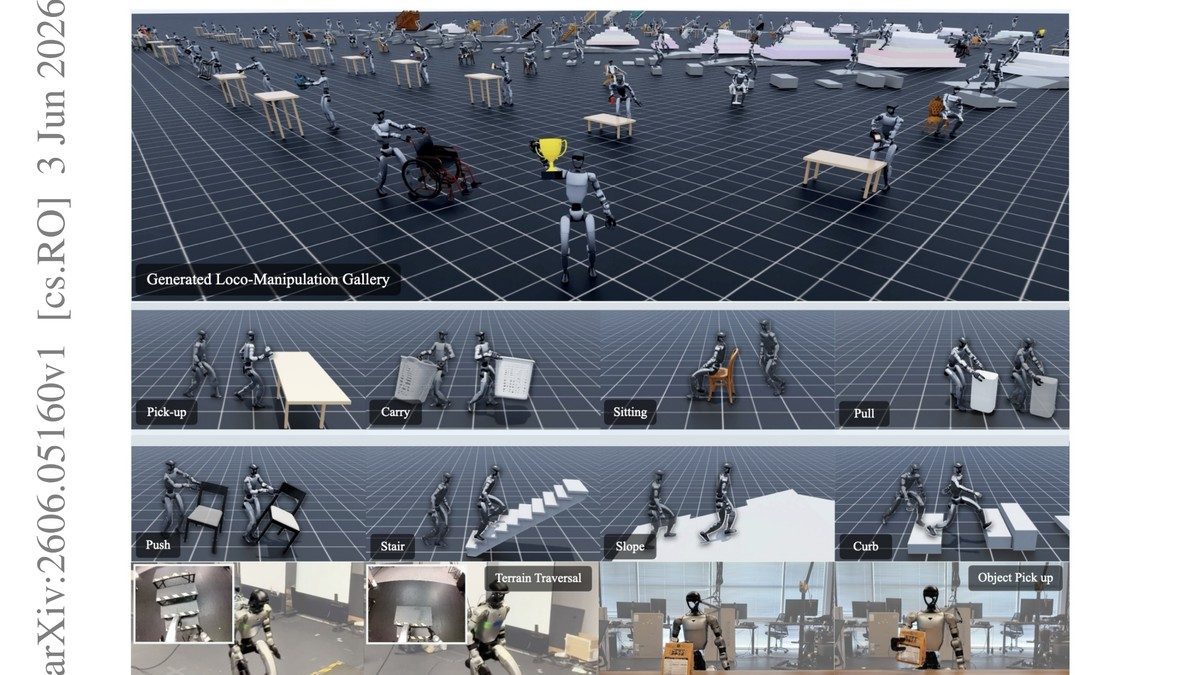
GRAIL: Generating Humanoid Loco-Manipulation from 3D Assets and Video Priors
arXiv preprint

GRAIL: Generating Humanoid Loco-Manipulation from 3D Assets and Video Priors

Tianyi Xie, Haotian Zhang, Jinhyung Park et al.

Scaling humanoid loco-manipulation requires robot-compatible demonstrations across diverse objects, whole-body motions, and scene geometries, but teleoperation and motion capture are difficult to scale because each collection depends on physical setups, instrumented actors, and robot operation.

sim-to-real reinforcement-learning vision manipulation humanoid
Code PDF Advanced
GitHub ★ 275 Updated Jun 2026
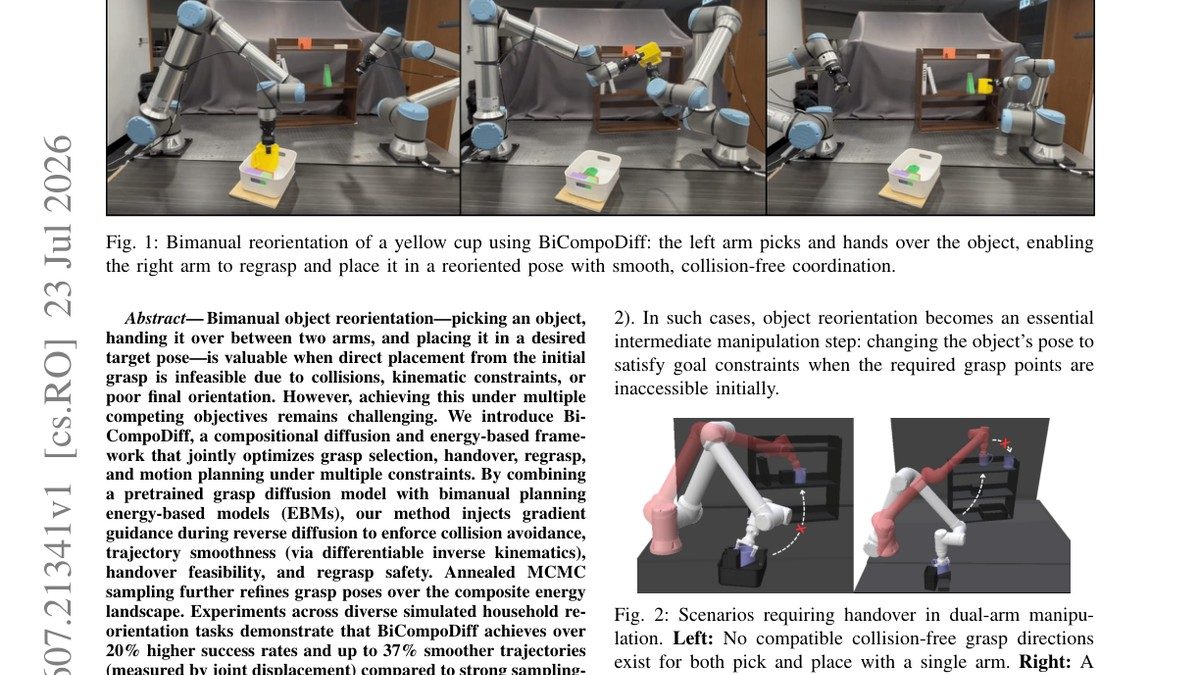
Grasp, Handover, Rotate: Bimanual Object Reorientation via Compositional Diffusion and Energy-Based Optimization
arXiv preprint

Grasp, Handover, Rotate: Bimanual Object Reorientation via Compositional Diffusion and Energy-Based Optimization

Wun Lam Yeung, Wenjun Liu, Yui Cheung Yu et al.

Bimanual object reorientation - picking an object, handing it over between two arms, and placing it in a desired target pose - is valuable when direct placement from the initial grasp is infeasible due to collisions, kinematic constraints, or poor final orientation.

manipulation reinforcement-learning sim-to-real planning
PDF Advanced
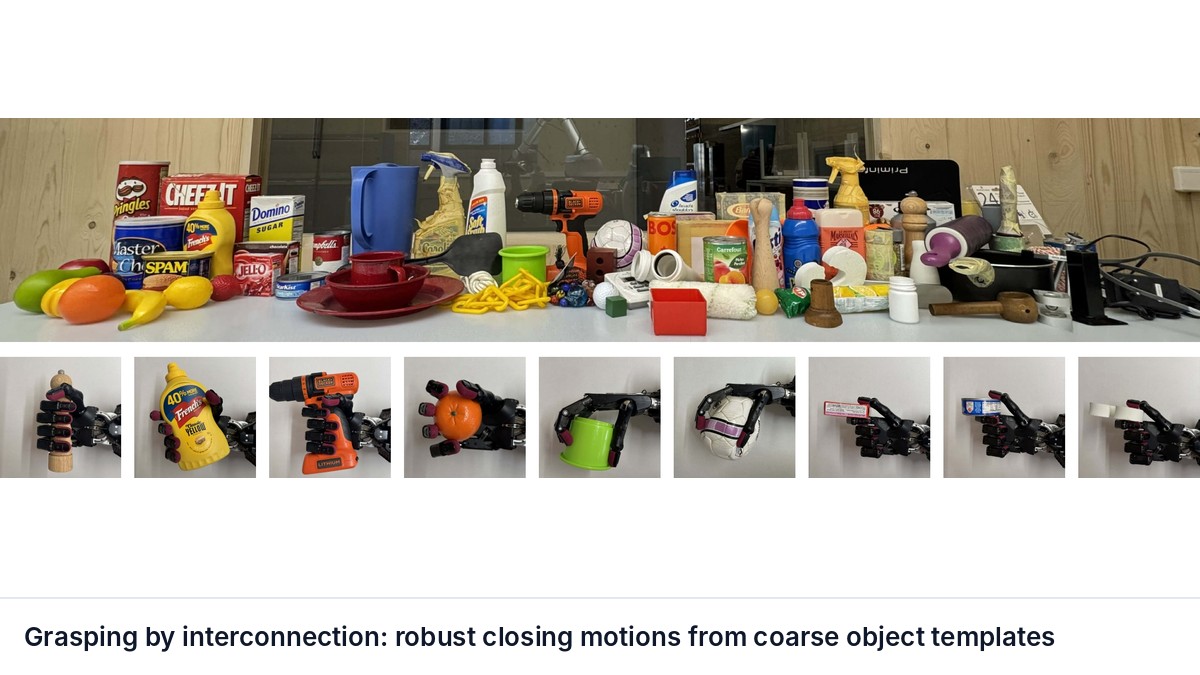
Grasping by interconnection: robust closing motions from coarse object templates
arXiv preprint

Grasping by interconnection: robust closing motions from coarse object templates

Julien Vanderheyden, Guillaume Drion, Fulvio Forni et al.

Dexterous robot hands must often grasp objects whose shape, size, and pose are known only approximately. Grasp planners typically require accurate object models or correct errors with feedback, but how much inaccuracy a closing motion can tolerate on its own remains unclear.

manipulation control benchmark
PDF Intermediate
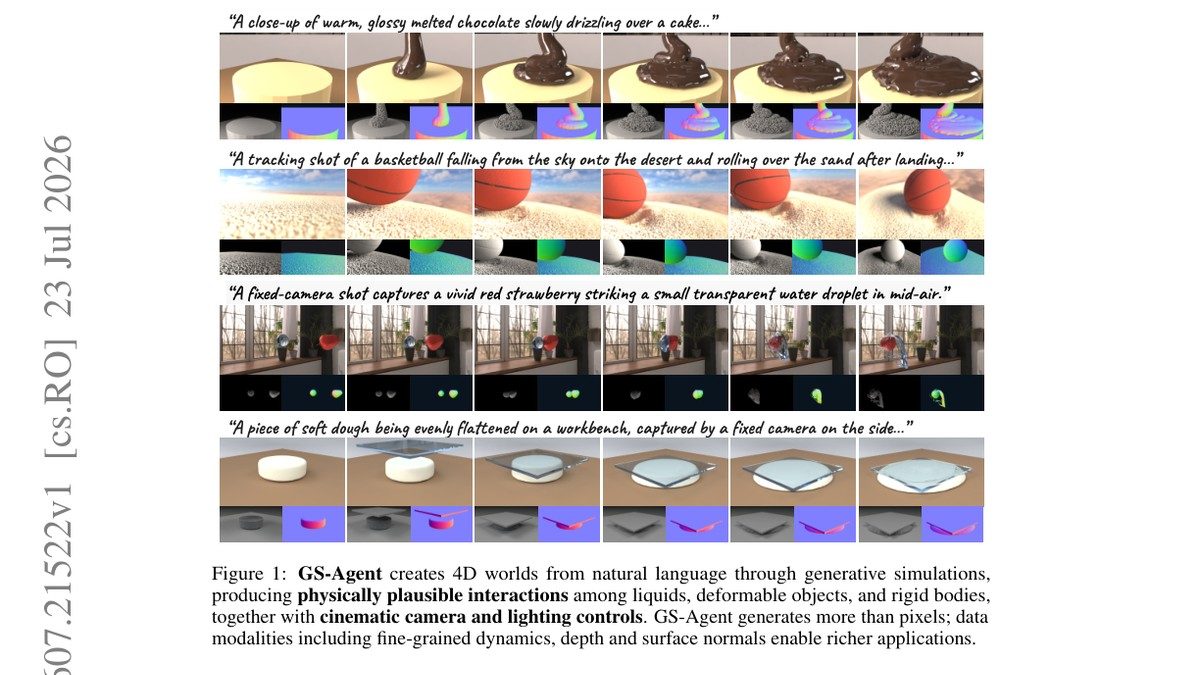
GS-Agent: Creating 4D Physical Worlds With Generative Simulation
arXiv preprint

GS-Agent: Creating 4D Physical Worlds With Generative Simulation

Hongxin Zhang, Chunru Lin, Junyan Li et al.

Creating dynamic and physically realistic 4D worlds from natural language descriptions is both fascinating and challenging. Traditional computer graphics methods rely on manual creation, requiring extensive human effort to fine-tune materials, motions, and visual fidelity.

manipulation vision reinforcement-learning control
Code PDF Advanced
GitHub ★ —
HarmoWAM: Harmonizing Generalizable and Precise Manipulation via Adaptive World Action Models
arXiv

HarmoWAM: Harmonizing Generalizable and Precise Manipulation via Adaptive World Action Models

Qiuxuan Feng, Jiale Yu, Jiaming Liu et al.

World Action Models (WAMs) have emerged as a promising paradigm for robot control by modeling physical dynamics. Current WAMs generally follow two paradigms: generalizable but imprecise models learned from diverse data, or precise but specialized models fitted to specific tasks.

foundation-models manipulation
Code PDF Intermediate
GitHub ★ 7 Updated May 2026
Has GPT-6-Astra Achieved Embodied Intelligence?
arXiv preprint

Has GPT-6-Astra Achieved Embodied Intelligence?

SenseNova, Joint Research Team, : et al.

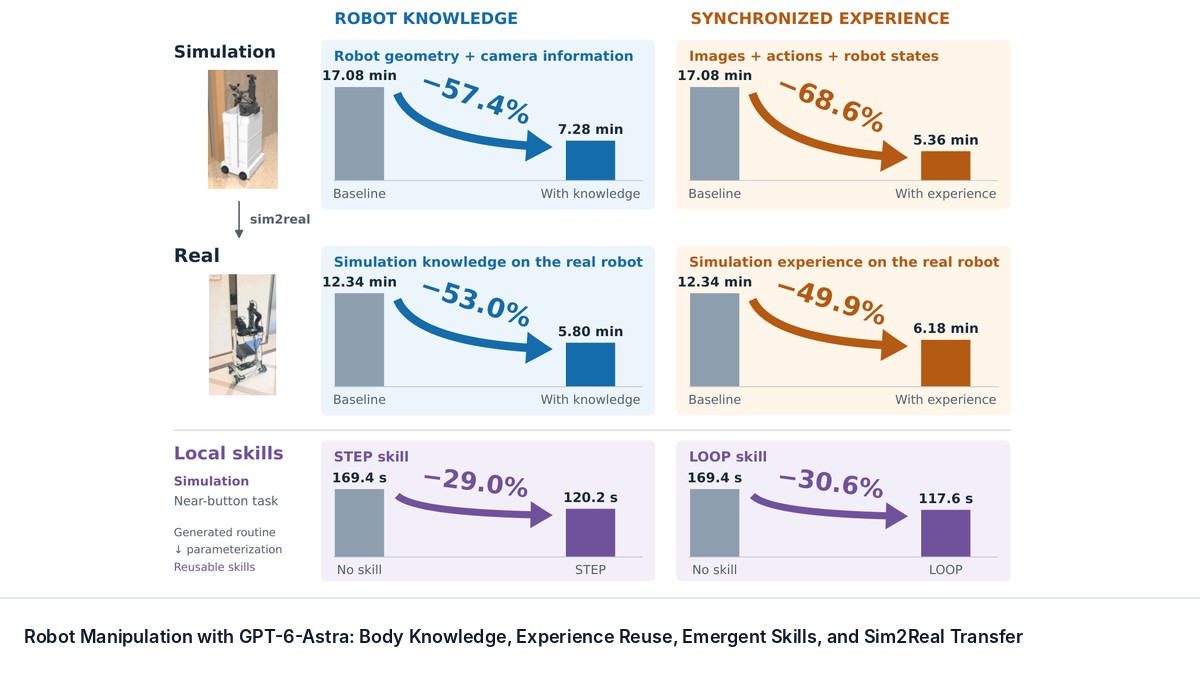
GPT-6-Astra demonstrates a level of competence in robotic manipulation and navigation that challenges the conventional paradigm of building specialized models for individual tasks and embodiments.

manipulation locomotion vision reinforcement-learning planning control learning-from-demonstration benchmark
Code PDF Advanced
GitHub ★ —
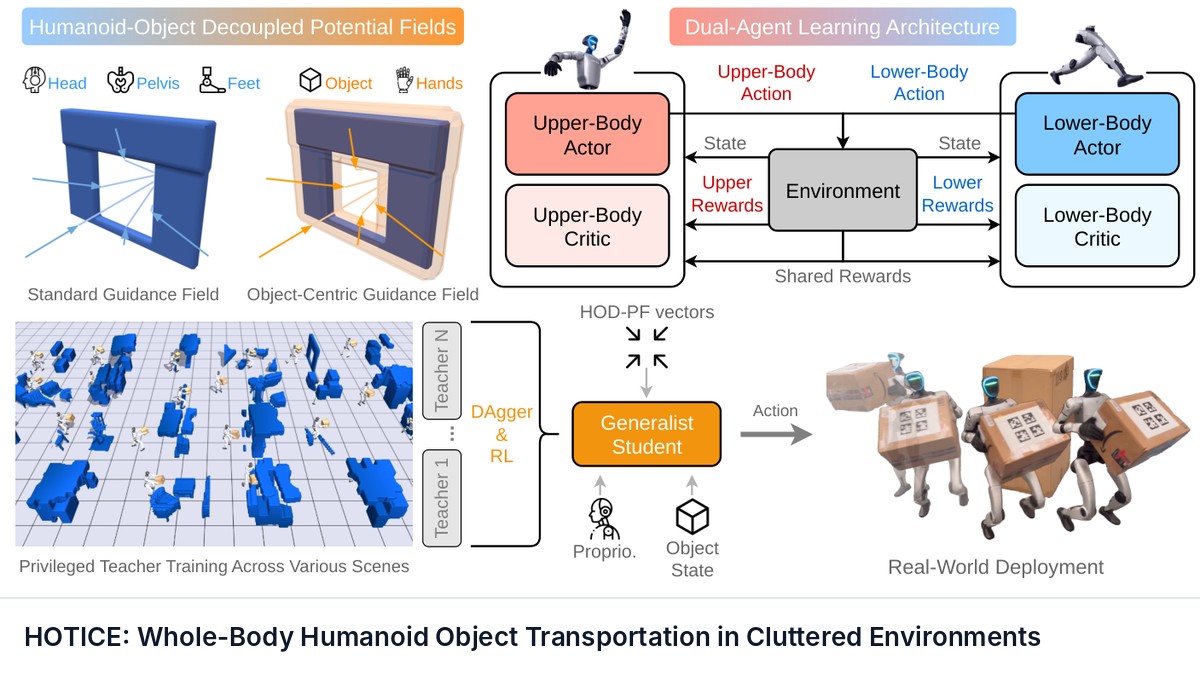
HOTICE: Whole-Body Humanoid Object Transportation in Cluttered Environments
arXiv preprint

HOTICE: Whole-Body Humanoid Object Transportation in Cluttered Environments

Toan Nguyen, Weiduo Yuan, Siheng Zhao et al.

Object transportation is a fundamental capability for humanoid robots operating in real-world, human-centric environments, yet existing methods struggle when clutter constrains free space around both the robot and its carried payload.

manipulation reinforcement-learning control
PDF Intermediate
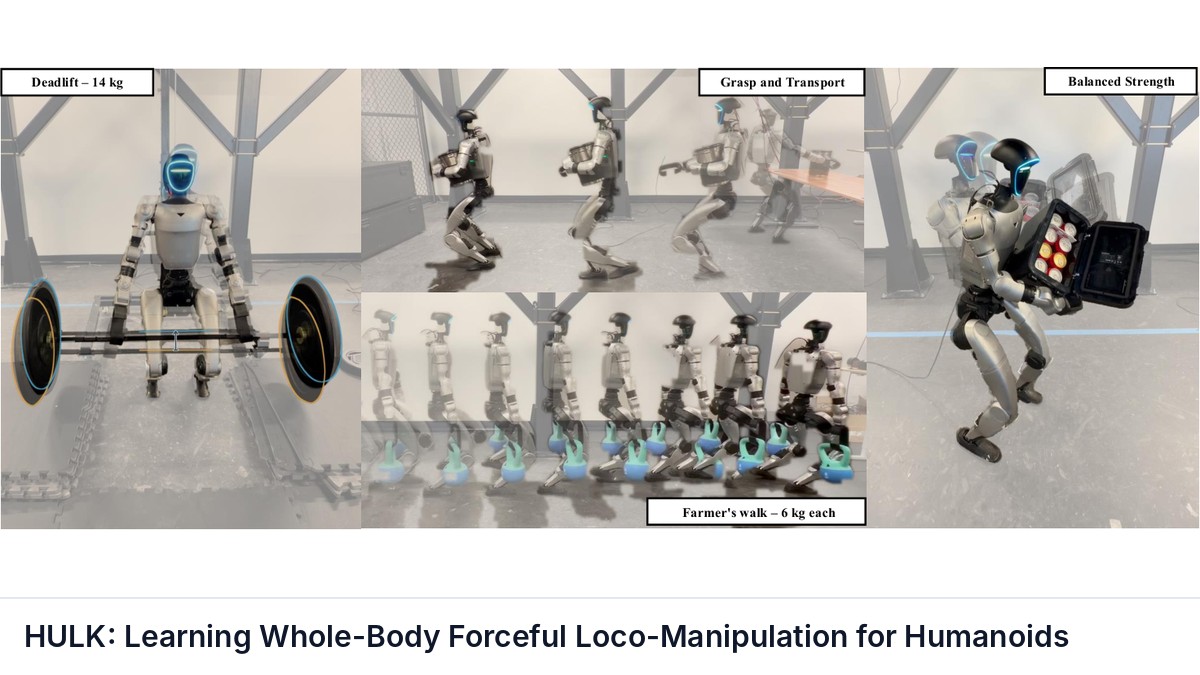
HULK: Learning Whole-Body Forceful Loco-Manipulation for Humanoids
arXiv preprint

HULK: Learning Whole-Body Forceful Loco-Manipulation for Humanoids

An Dang, Arturo Flores Alvarez, Yu-Ming Chen et al.

Humanoid loco-manipulation of large, heavy objects demands forceful interaction across the entire body. However, such payloads shift a humanoid's center of mass and impose sustained loads across the upper body, challenging balance and command tracking.

manipulation reinforcement-learning control benchmark
PDF Intermediate
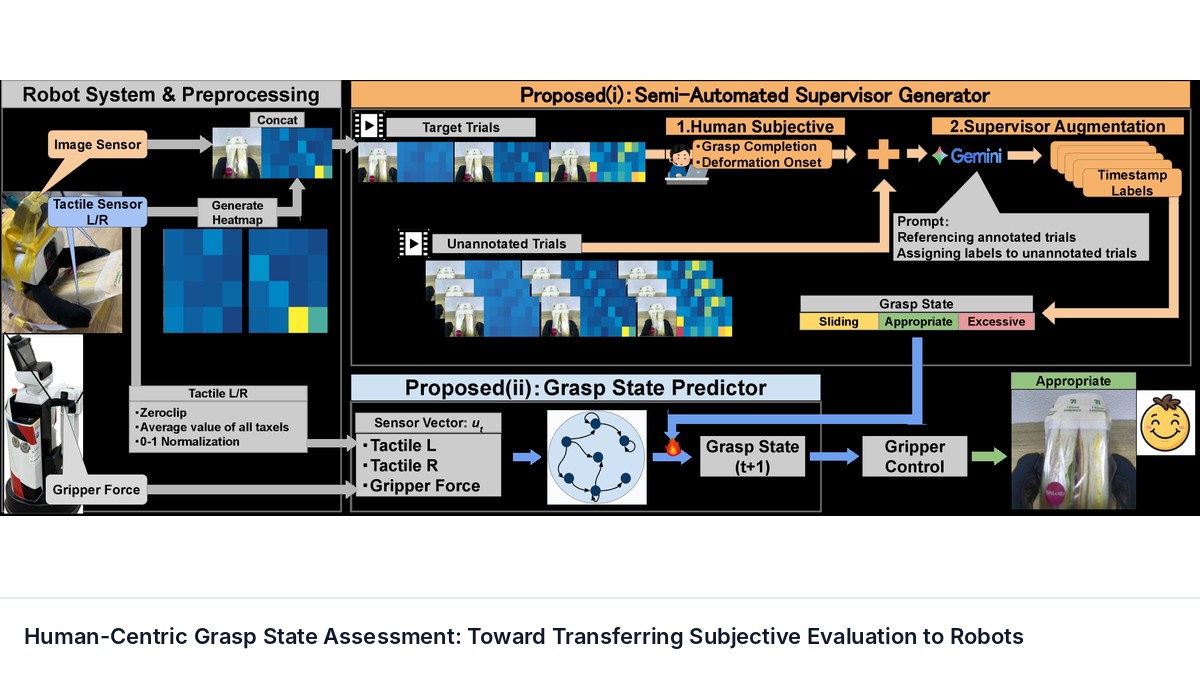
Human-Centric Grasp State Assessment: Toward Transferring Subjective Evaluation to Robots
arXiv preprint

Human-Centric Grasp State Assessment: Toward Transferring Subjective Evaluation to Robots

Ryohei Kobayashi, Kosei Isomoto, Yuga Yano et al.

We propose a framework that transfers tacit human subjective criteria to robotic systems for the appropriate grasping of deformable objects. Achieving such behavior is challenging because a semantic gap exists between qualitative human expectations and quantitative robotic measurements.

manipulation vision vla control tactile benchmark
PDF Intermediate
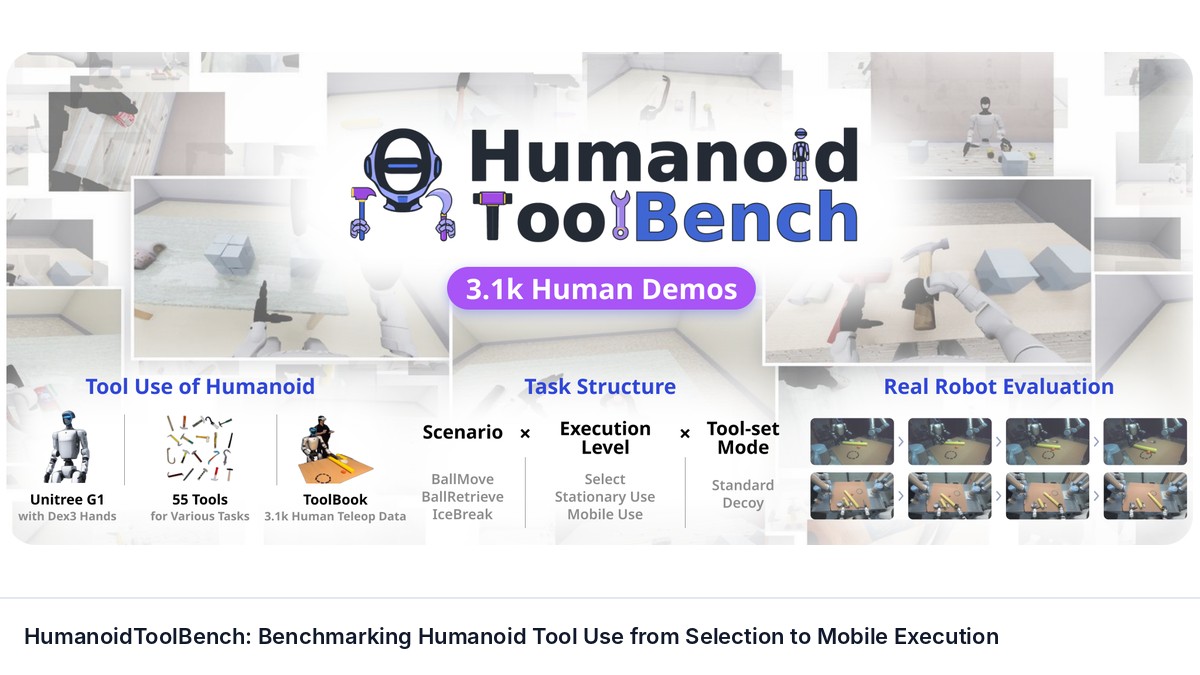
HumanoidToolBench: Benchmarking Humanoid Tool Use from Selection to Mobile Execution
arXiv preprint

HumanoidToolBench: Benchmarking Humanoid Tool Use from Selection to Mobile Execution

Kyochul Jang, Seohyeon Park, Ohchul Kwon et al.

As robotic hardware and learning methods advance, humanoids need tools to perform tasks beyond their inherent physical limits. Successful tool use requires selecting a suitable tool and coordinating manipulation and, when needed, locomotion to complete the task.

manipulation locomotion learning-from-demonstration benchmark
Code PDF Intermediate
GitHub ★ —
iAm.md: Robot Skill Self-Assessment through Agentic Introspection for Unknown Open-Vocabulary Domains
arXiv preprint

iAm.md: Robot Skill Self-Assessment through Agentic Introspection for Unknown Open-Vocabulary Domains

Vincenzo Guarino, Emanuele Musumeci, Vincenzo Suriani et al.

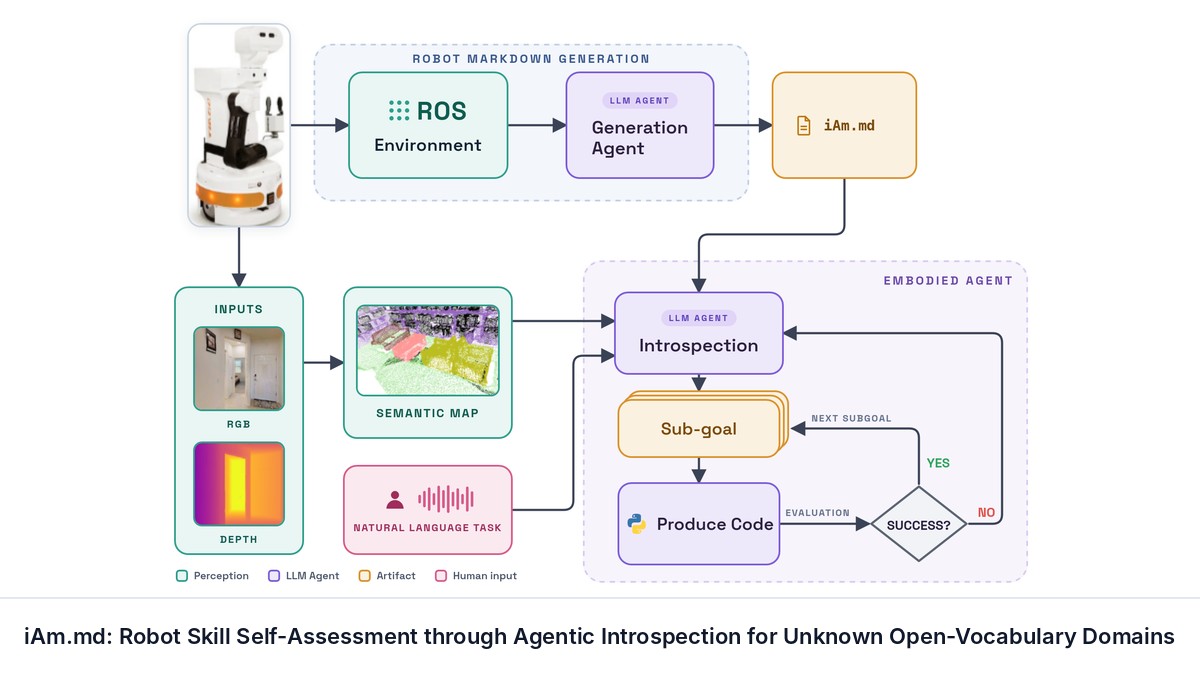
Agentic AI based on Large Language Model generalization capabilities offers a wide range of potential applications, including planning for embodied tasks. For example, embodied agents based on Foundation models can generate plausible plans in autonomous robotics scenarios.

manipulation vision reinforcement-learning planning
PDF Advanced
Improving Robotic Generalist Policies via Flow Reversal Steering
arXiv preprint

Improving Robotic Generalist Policies via Flow Reversal Steering

Andy Tang, William Chen, Andrew Wagenmaker et al.

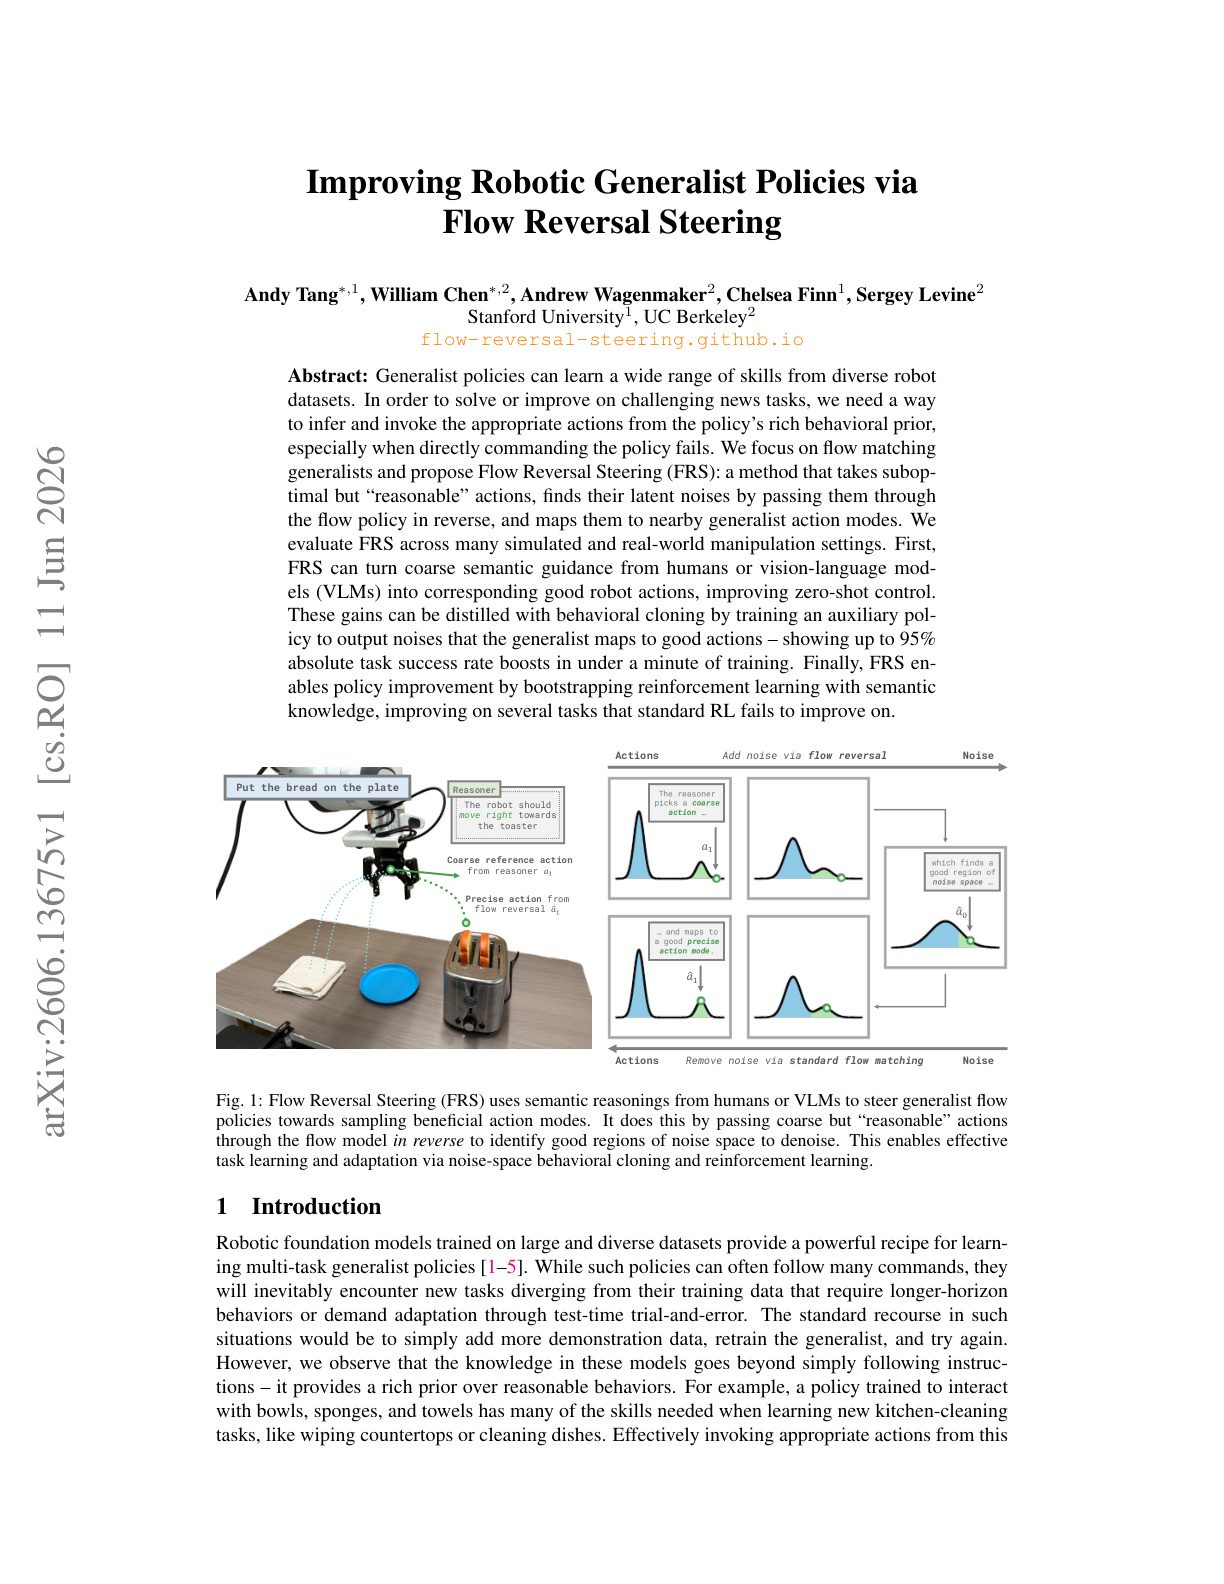
Generalist policies can learn a wide range of skills from diverse robot datasets. In order to solve or improve on challenging news tasks, we need a way to infer and invoke the appropriate actions from the policy's rich behavioral prior, especially when directly commanding the policy fails.

manipulation vla world-models
PDF Advanced
In-Context Learning for Robots: Methods and Applications
arXiv preprint

In-Context Learning for Robots: Methods and Applications

Haojian Huang, Zexi Li, Junhao Guo et al.

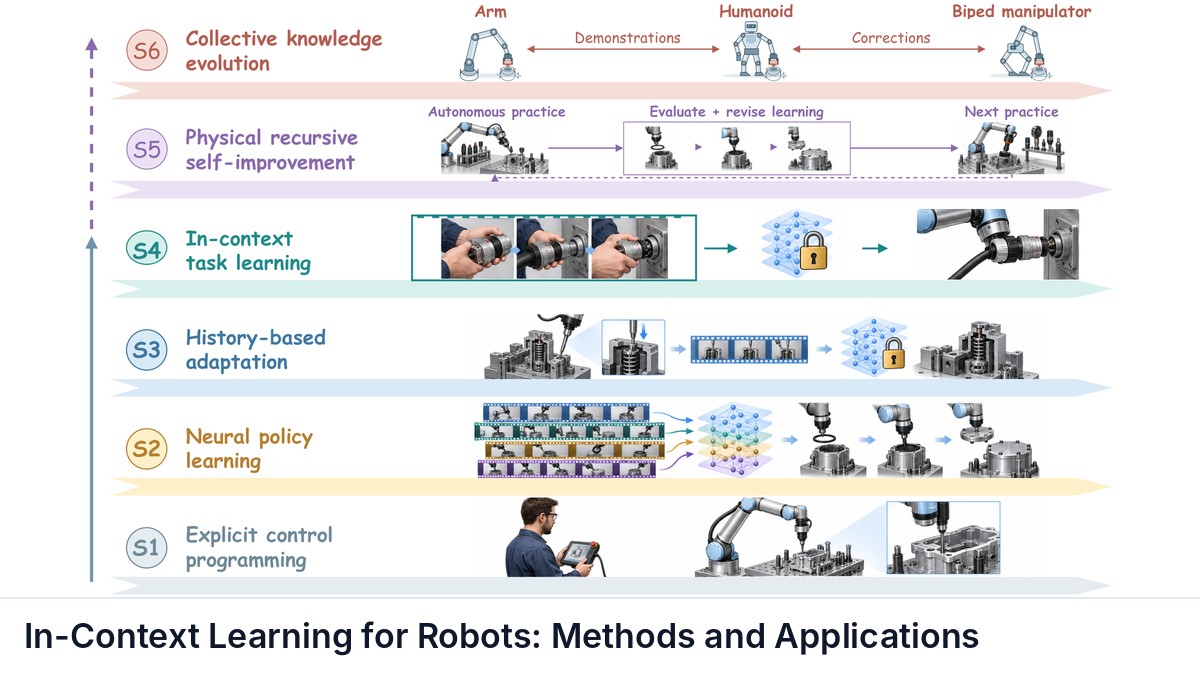
General-purpose robots must infer what a new task requires and translate that understanding into appropriate physical action.

manipulation reinforcement-learning planning control learning-from-demonstration benchmark
Code PDF Beginner
GitHub ★ —
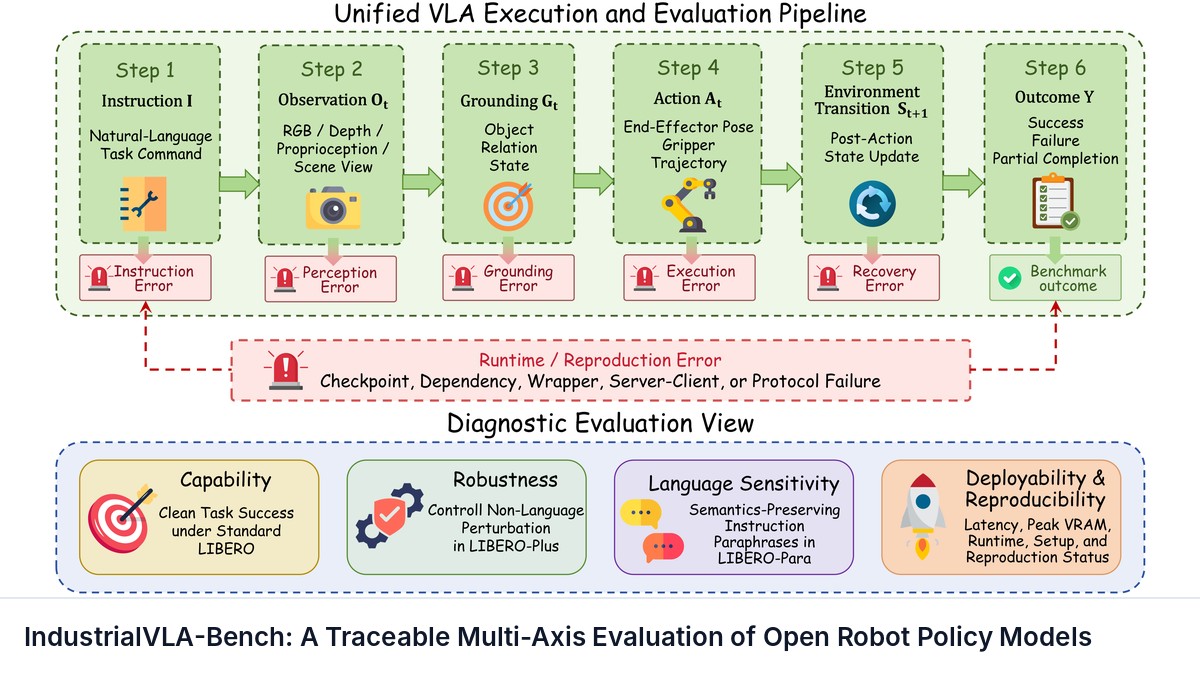
IndustrialVLA-Bench: A Traceable Multi-Axis Evaluation of Open Robot Policy Models
arXiv preprint

IndustrialVLA-Bench: A Traceable Multi-Axis Evaluation of Open Robot Policy Models

Yiqi Wang, Zhifeng Rao, Jiaqi Zhang et al.

Open robot policies increasingly follow two paradigms: vision-language-action models (VLAs) directly map observations and instructions to actions, whereas world-action models (WAMs) incorporate learned video or world dynamics into policy learning or action generation.

manipulation vision vla reinforcement-learning benchmark
Code PDF Intermediate
GitHub ★ —
LadderMan: Learning Humanoid Perceptive Ladder Climbing
arXiv preprint

LadderMan: Learning Humanoid Perceptive Ladder Climbing

Siheng Zhao, Yuanhang Zhang, Ziqi Lu et al.

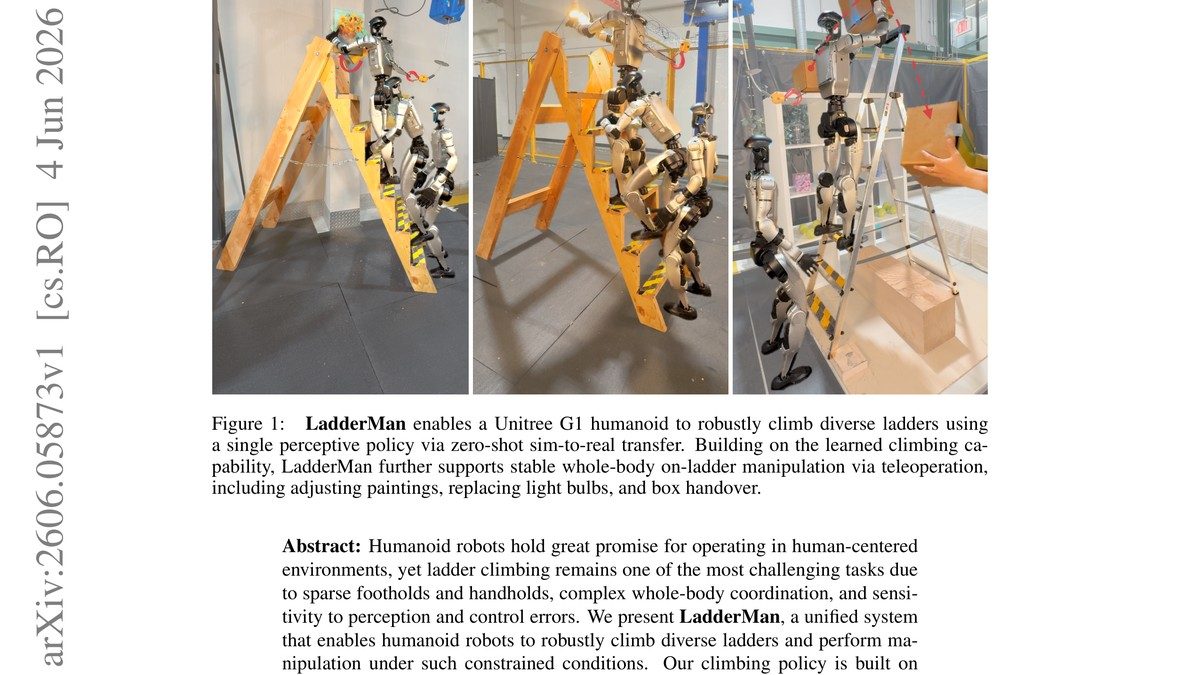
Humanoid robots hold great promise for operating in human-centered environments, yet ladder climbing remains one of the most challenging tasks due to sparse footholds and handholds, complex whole-body coordination, and sensitivity to perception and control errors.

sim-to-real reinforcement-learning vision manipulation humanoid
PDF Advanced
LEAP: Making Privileged Geometry Supervision Effective for Visuomotor Learning
arXiv preprint

LEAP: Making Privileged Geometry Supervision Effective for Visuomotor Learning

Han Fang, Yunpeng Jiang, Jianshu Hu et al.

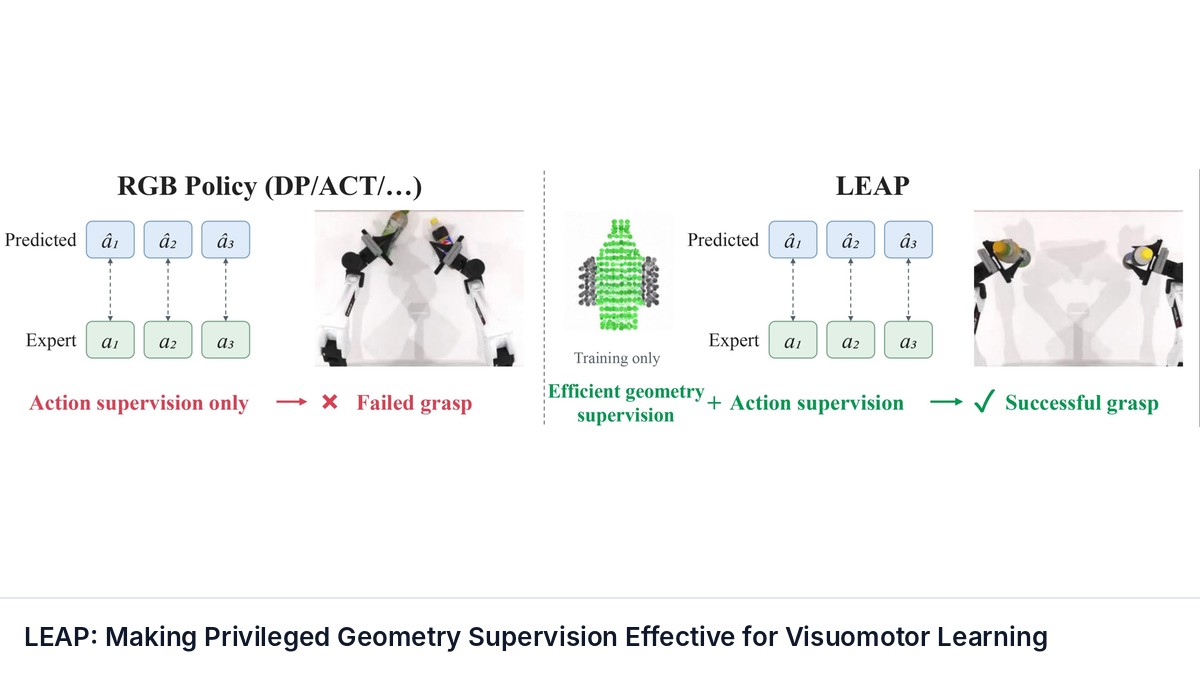
Privileged 3D supervision uses additional geometric information during training to guide RGB-based visuomotor policy learning, without requiring geometric inputs at deployment. However, low reconstruction error does not ensure that visual representations capture geometry useful for control.

manipulation vision reinforcement-learning control
PDF Advanced
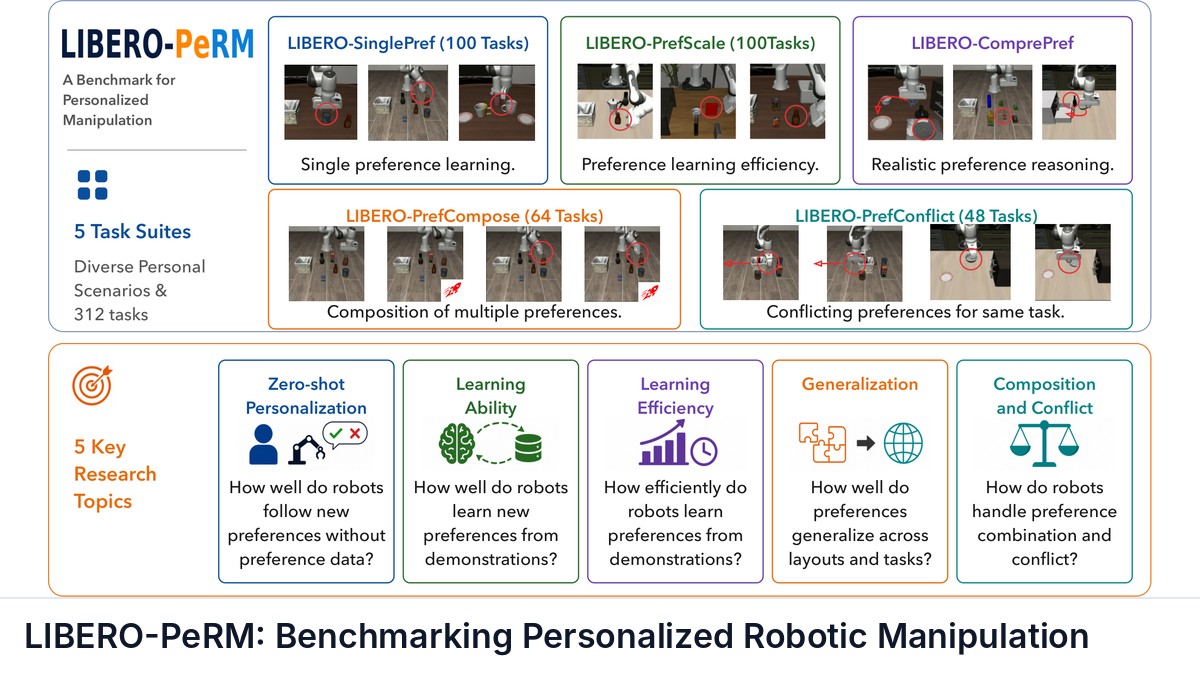
LIBERO-PeRM: Benchmarking Personalized Robotic Manipulation
arXiv preprint

LIBERO-PeRM: Benchmarking Personalized Robotic Manipulation

Zhixu Li, Keqian Tang, Litian Gong et al.

Personalization is essential for general-purpose robots to transition into household environments and achieve true practicality.

manipulation vla control learning-from-demonstration benchmark
PDF Intermediate
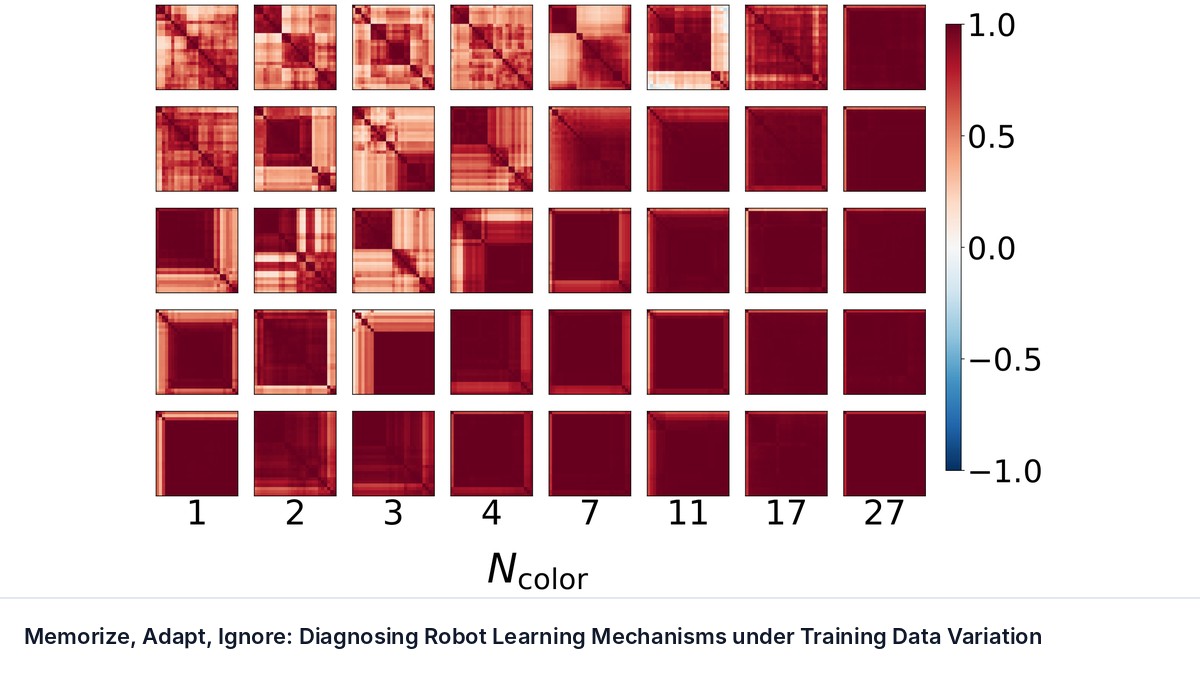
Memorize, Adapt, Ignore: Diagnosing Robot Learning Mechanisms under Training Data Variation
arXiv preprint

Memorize, Adapt, Ignore: Diagnosing Robot Learning Mechanisms under Training Data Variation

Ke Zhang, Danica J. Sutherland, Chao Liu

Training data variation, whether through designing a domain randomization (DR) scheme in simulation or curating demonstrations for imitation learning, is a primary lever for improving the robustness of robotic manipulation policies.

manipulation vision vla reinforcement-learning sim-to-real learning-from-demonstration
PDF Intermediate
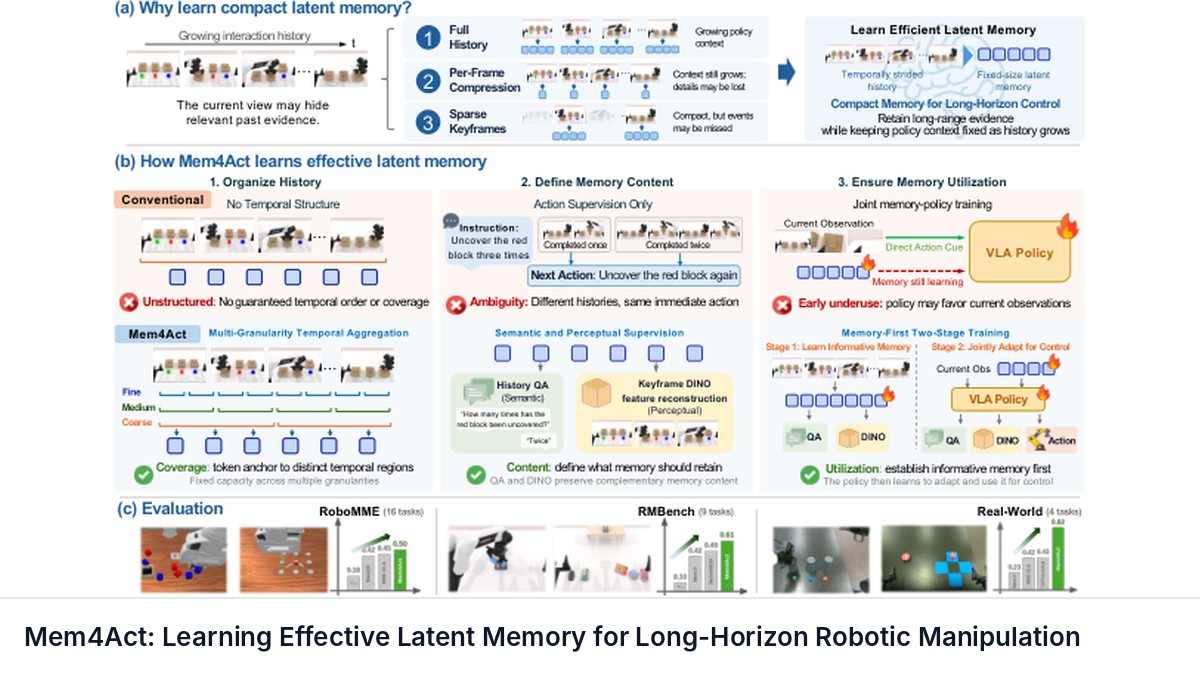
Memory as Plans: World-Action Modeling with Memory-Grounded Planning
arXiv preprint

Memory as Plans: World-Action Modeling with Memory-Grounded Planning

Sizhe Zhao, Haozhe Xie, Weiyu Zhao et al.

Mainstream robotic policies often adopt a Markovian formulation, but many complex real-world manipulation tasks are inherently non-Markovian, requiring long-horizon memory beyond the current observation.

manipulation vision reinforcement-learning planning
PDF Intermediate
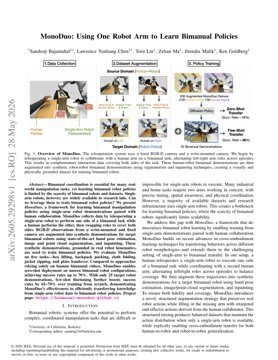
MonoDuo: Using One Robot Arm to Learn Bimanual Policies
ICRA 2026

MonoDuo: Using One Robot Arm to Learn Bimanual Policies

Sandeep Bajamahal, Lawrence Yunliang Chen, Toru Lin et al.

Bimanual coordination is essential for many real-world manipulation tasks, yet learning bimanual robot policies is limited by the scarcity of bimanual robots and datasets. Single-arm robots, however,

manipulation bimanual imitation-learning dataset
PDF Intermediate
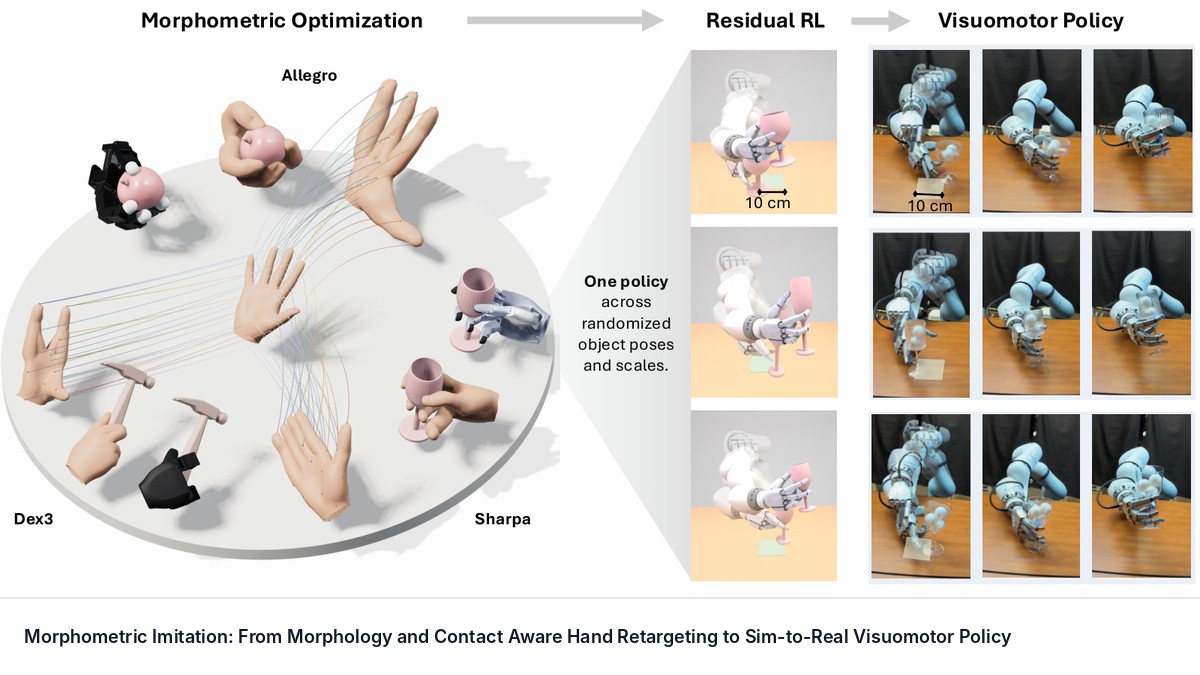
Morphometric Imitation: From Morphology and Contact Aware Hand Retargeting to Sim-to-Real Visuomotor Policy
arXiv preprint

Morphometric Imitation: From Morphology and Contact Aware Hand Retargeting to Sim-to-Real Visuomotor Policy

Tara Sadjadpour, Siming He, C. K. Wolfe et al.

Human hand-object interactions (HOIs) provide a rich source of demonstrations for dexterous manipulation, but learning directly from them presents challenges in bridging morphology gaps, ensuring dynamical feasibility, and sim-to-real deployment.

manipulation reinforcement-learning sim-to-real learning-from-demonstration
PDF Intermediate
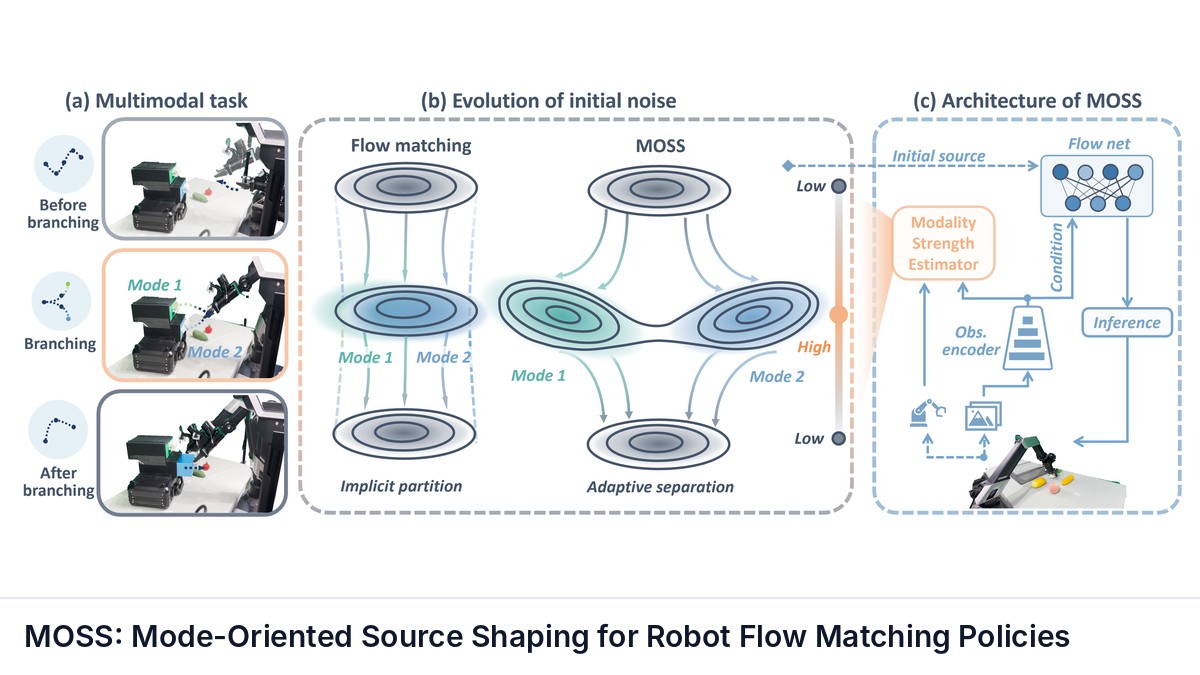
MOSS: Mode-Oriented Source Shaping for Robot Flow Matching Policies
arXiv preprint

MOSS: Mode-Oriented Source Shaping for Robot Flow Matching Policies

Zirun Ma, Jindou Jia, Tuo An et al.

In robotic manipulation, the same observation often admits multiple feasible actions. Generative policies such as diffusion and flow matching naturally capture such multimodal behaviors, yet which mode is executed is left to random sampling and cannot be actively controlled.

manipulation vision reinforcement-learning control benchmark
Code PDF Advanced
GitHub ★ —
Native Video-Action Pretraining for Generalizable Robot Control
arXiv preprint

Native Video-Action Pretraining for Generalizable Robot Control

Qihang Zhang, Lin Li, Luyao Zhang et al.

The advent of video-action models offers a promising path for robot control. Nevertheless, we argue that repurposing video generative models designed for digital content creation is inherently inadequate for physical environments.

manipulation vision reinforcement-learning control
PDF Advanced
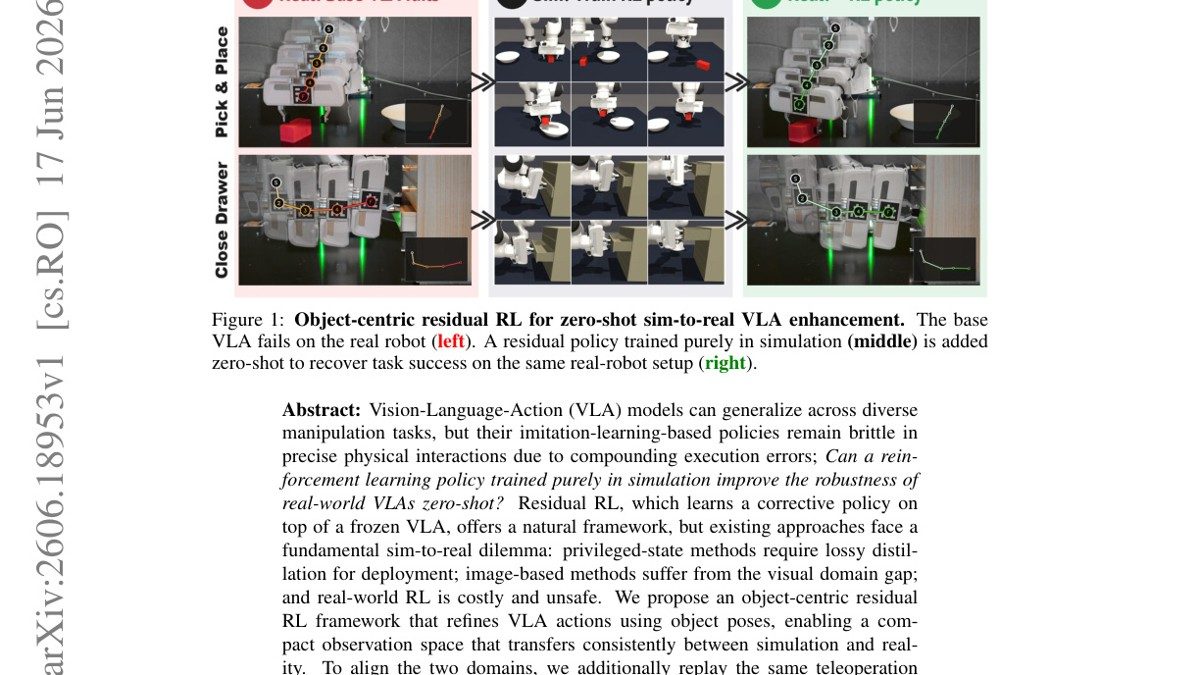
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
arXiv preprint

Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement

Kinam Kim, Namiko Saito, Heecheol Kim et al.

Vision-Language-Action (VLA) models can generalize across diverse manipulation tasks, but their imitation-learning-based policies remain brittle in precise physical interactions due to compounding execution errors; Can a reinforcement learning policy trained purely in simulation improve the robustness of real-world VLAs zero-shot?

ar-vr manipulation rl
PDF Intermediate
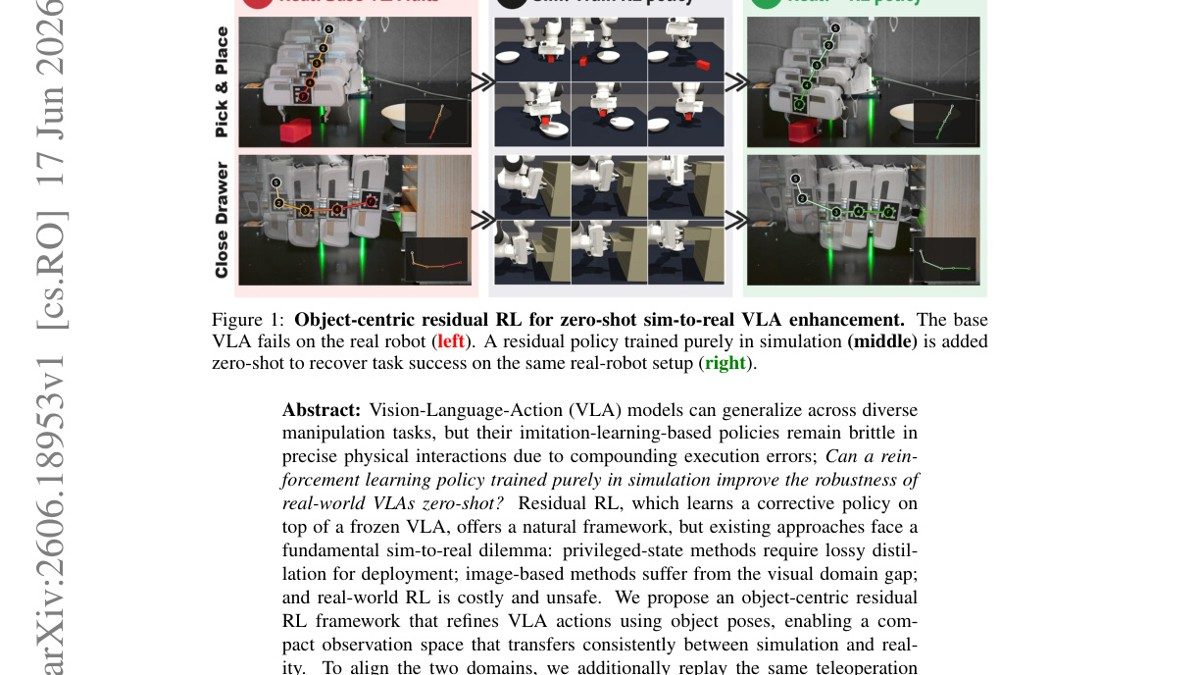
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
arXiv preprint

Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement

Kinam Kim, Namiko Saito, Heecheol Kim et al.

Vision-Language-Action (VLA) models can generalize across diverse manipulation tasks, but their imitation-learning-based policies remain brittle in precise physical interactions due to compounding execution errors; Can a reinforcement learning policy trained purely in simulation improve the robustness of real-world VLAs zero-shot?

ar-vr manipulation rl
PDF Intermediate
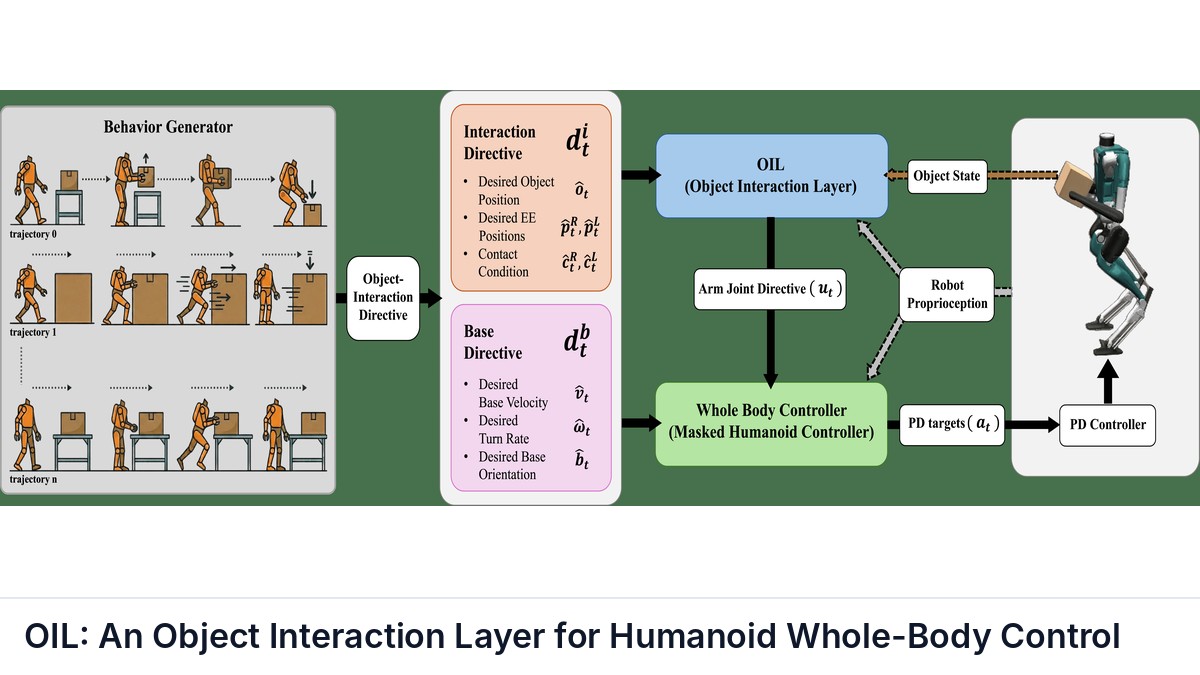
OIL: An Object Interaction Layer for Humanoid Whole-Body Control
arXiv preprint

OIL: An Object Interaction Layer for Humanoid Whole-Body Control

Pranay Dugar, Mohitvishnu S. Gadde, Rajesh Mangannavar et al.

Recent progress in learned whole-body controllers for humanoid robots has enabled robust free-space motion by tracking kinematic targets such as joint or end-effector trajectories.

manipulation locomotion reinforcement-learning sim-to-real control learning-from-demonstration
PDF Intermediate
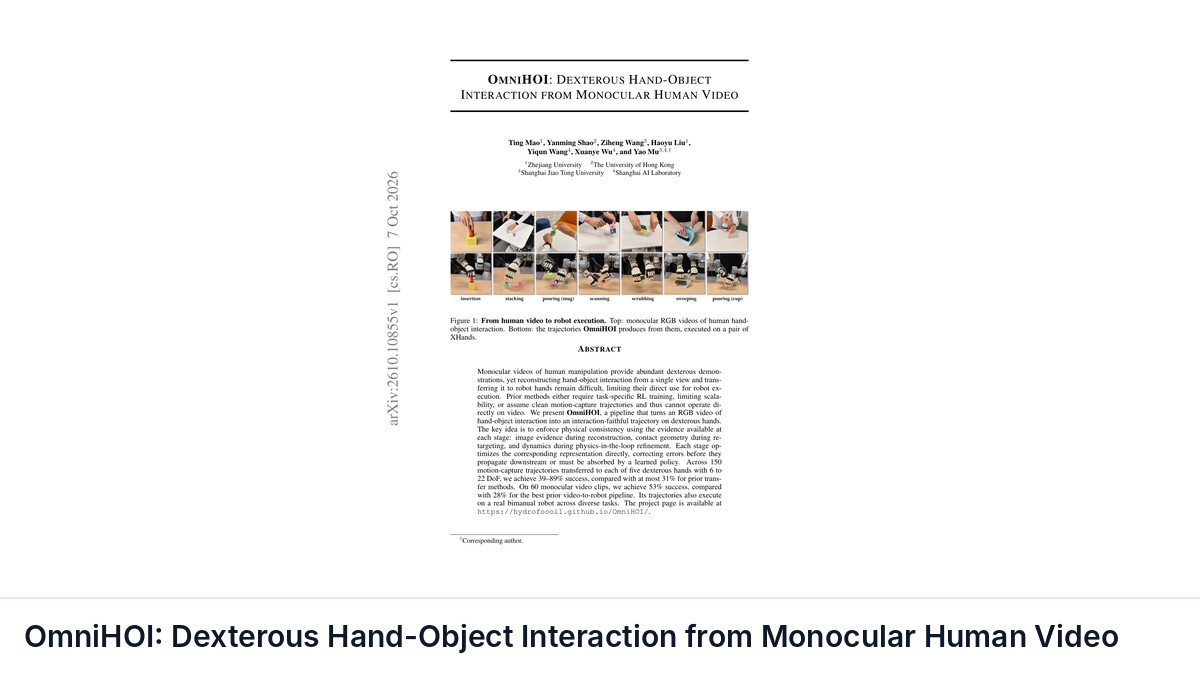
OmniHOI: Dexterous Hand-Object Interaction from Monocular Human Video
arXiv preprint

OmniHOI: Dexterous Hand-Object Interaction from Monocular Human Video

Ting Mao, Yanming Shao, Ziheng Wang et al.

Monocular videos of human manipulation provide abundant dexterous demonstrations, yet reconstructing hand-object interaction from a single view and transferring it to robot hands remain difficult, limiting their direct use for robot execution.

manipulation vision reinforcement-learning learning-from-demonstration
PDF Intermediate
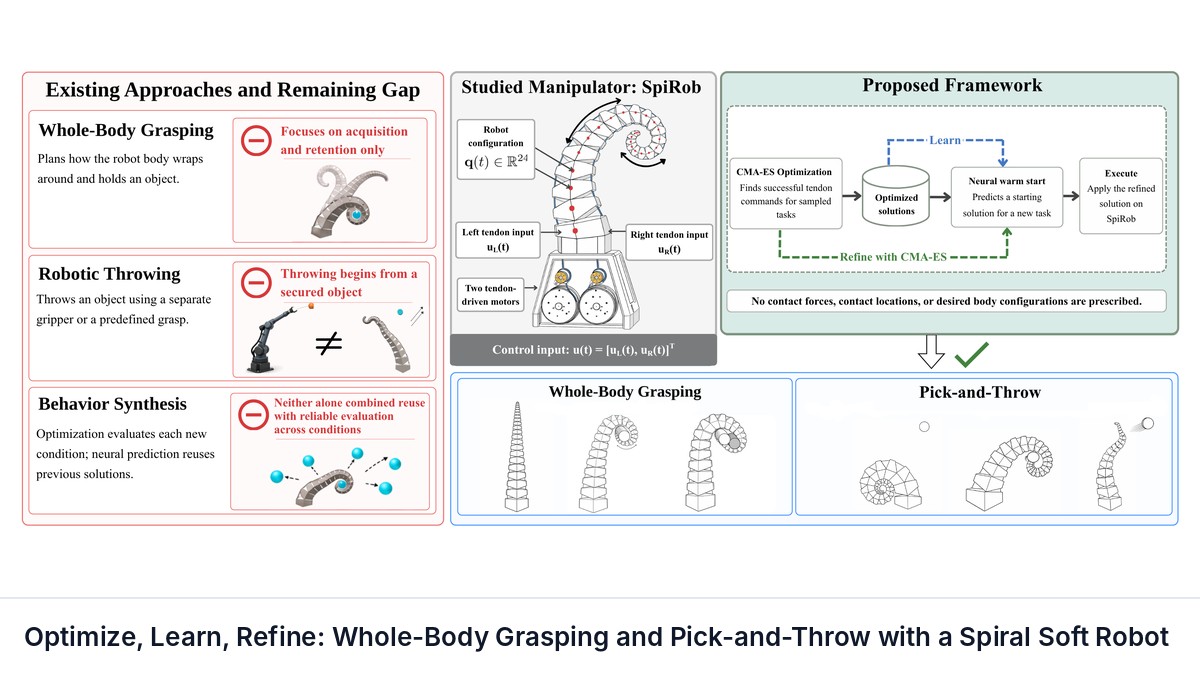
Optimize, Learn, Refine: Whole-Body Grasping and Pick-and-Throw with a Spiral Soft Robot
arXiv preprint

Optimize, Learn, Refine: Whole-Body Grasping and Pick-and-Throw with a Spiral Soft Robot

Marwah Basuhai, Tingcong Liu, Ibrahim Alsarraj et al.

Soft continuum robots can exploit distributed compliance for whole-body manipulation, but synthesizing behavior through changing contacts remains difficult. We address whole-body grasping and pick-and-throw from an initially ungrasped state through outcome-based actuation-space optimization.

manipulation
PDF Advanced
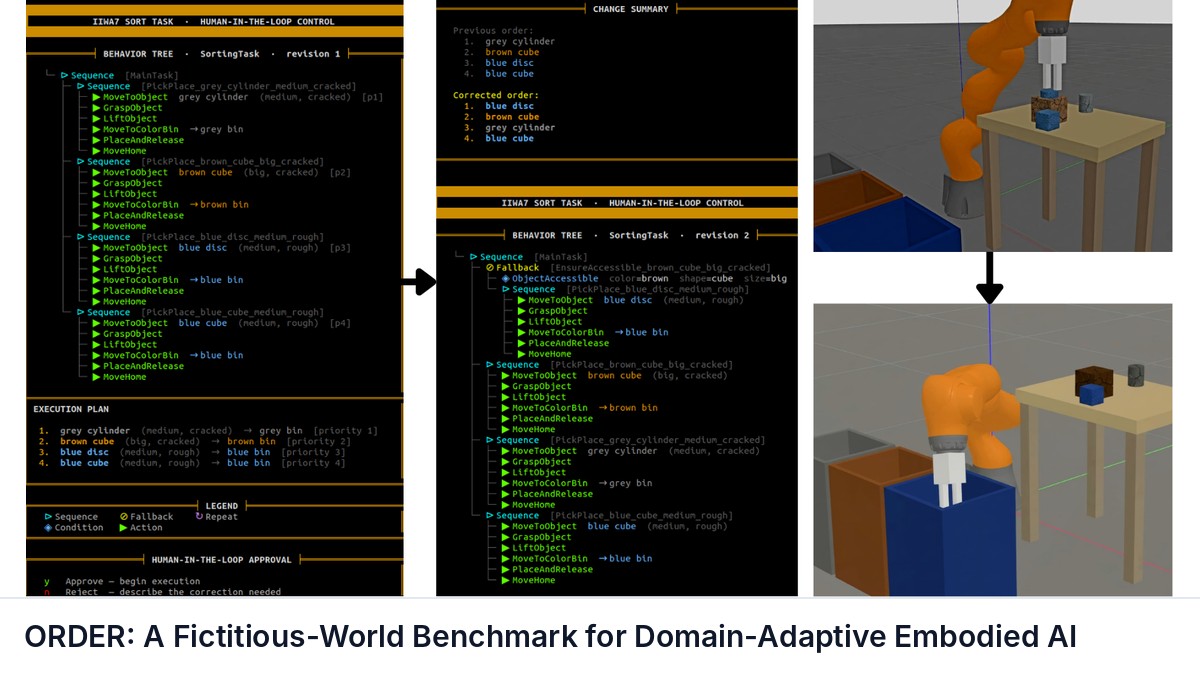
ORDER: A Fictitious-World Benchmark for Domain-Adaptive Embodied AI
arXiv preprint

ORDER: A Fictitious-World Benchmark for Domain-Adaptive Embodied AI

Sai Krishna Reddy Sathi, Anuj Tiwari

Adapting language models to new domains via continual pre-training raises a basic evaluation problem: if the training corpus overlaps with what the model already knows, performance gains cannot be cleanly attributed to new learning rather than pre-existing knowledge.

manipulation vision reinforcement-learning benchmark
PDF Intermediate
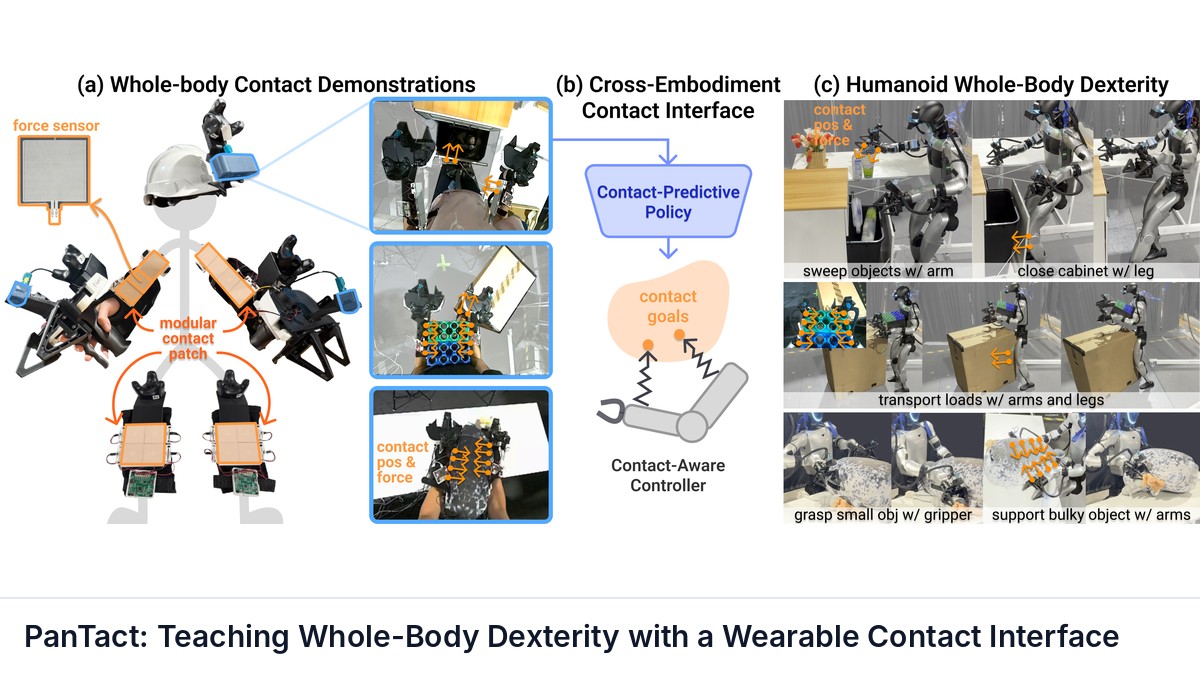
PanTact: Teaching Whole-Body Dexterity with a Wearable Contact Interface
arXiv preprint

PanTact: Teaching Whole-Body Dexterity with a Wearable Contact Interface

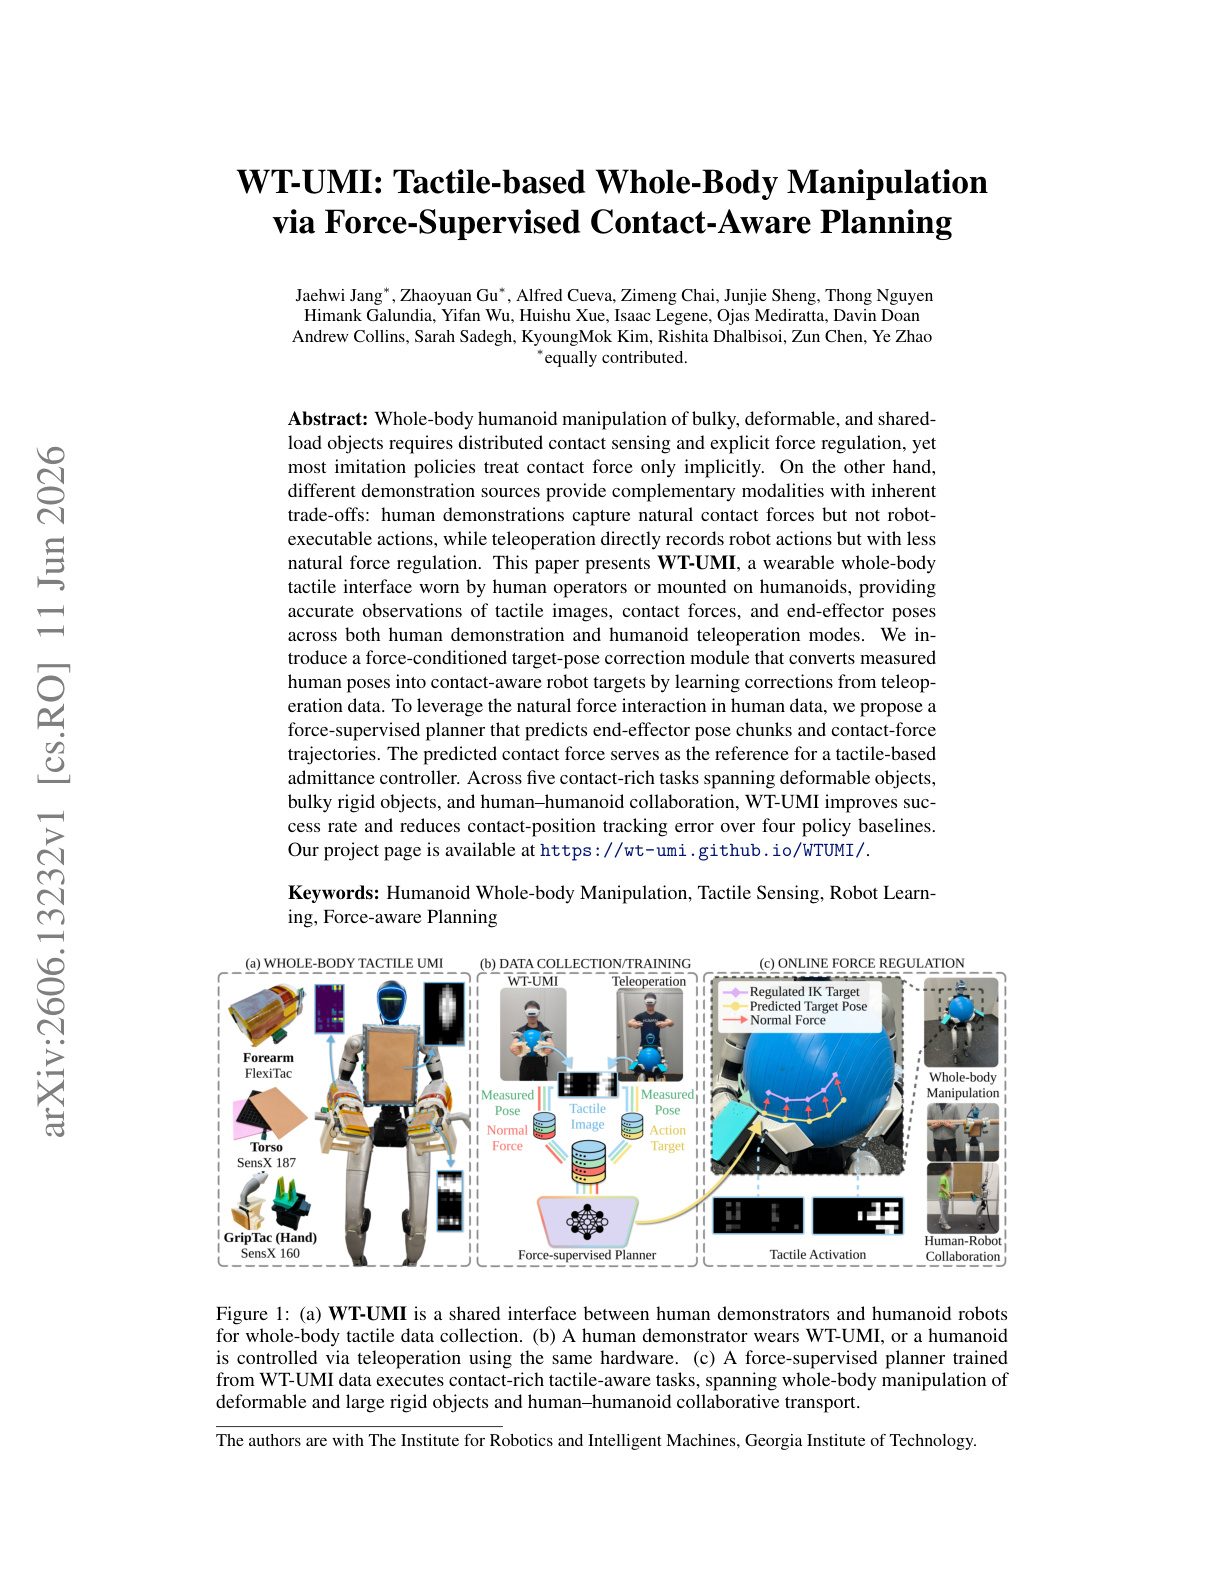
Xiaomeng Xu, Han Zhang, Zhian Ruan et al.

Humanoid robots have many degrees of freedom and contact surfaces, yet most loco-manipulation research restricts manipulation to the hands and avoids other body contacts with the environment.

manipulation vision reinforcement-learning control learning-from-demonstration
PDF Intermediate
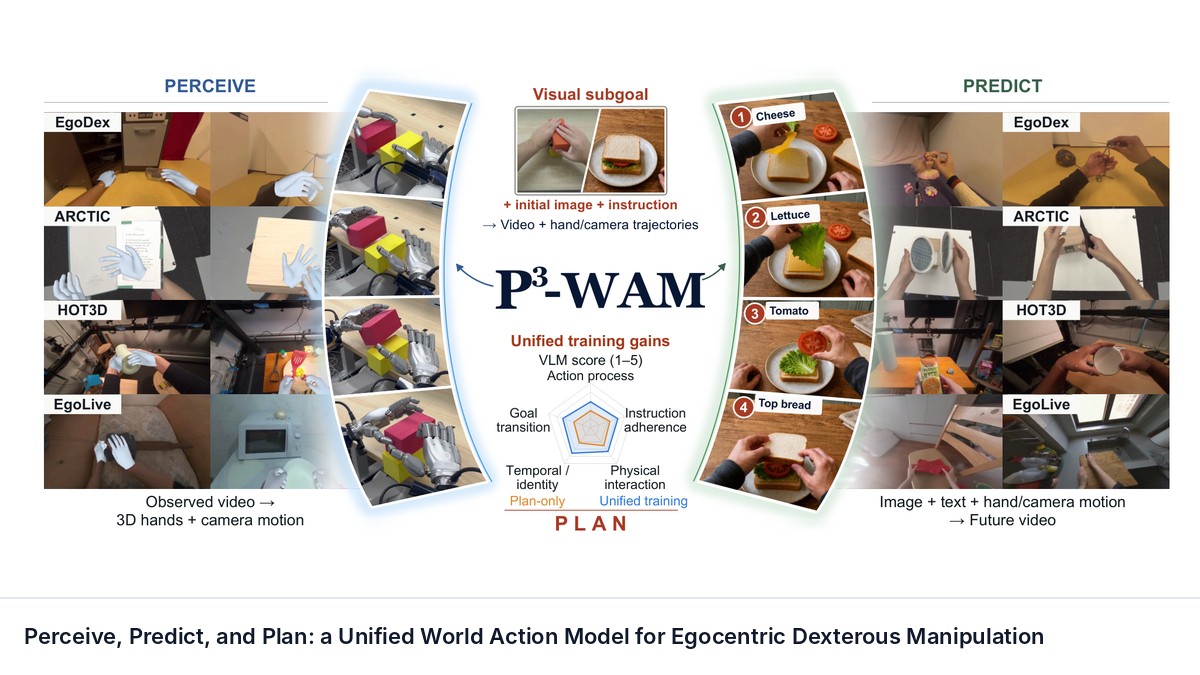
Perceive, Predict, and Plan: a Unified World Action Model for Egocentric Dexterous Manipulation
arXiv preprint

Perceive, Predict, and Plan: a Unified World Action Model for Egocentric Dexterous Manipulation

Zirui Wu, Chen Guo, Tianjian Jiang et al.

We introduce P$^{3}$-WAM, a unified world action model for egocentric dexterous manipulation that learns 3D perception, action-conditioned prediction, and goal-directed planning through three complementary modes: Perceive, which reconstructs articulated hand motion and camera trajectories from video; Predict, which generates visual futures under prescribed actions; and Plan, which jointly generates action trajectories and their anticipated visual consequences conditioned on an initial image, a language instruction, and an optional visual goal.

manipulation vision reinforcement-learning planning benchmark
Code PDF Advanced
GitHub ★ —
PhAIL: A Real-Robot VLA Benchmark and Distributional Methodology
arXiv preprint

PhAIL: A Real-Robot VLA Benchmark and Distributional Methodology

Sergey Arkhangelskiy

Real-world evaluation of vision-language-action (VLA) policies still rests on binary success rate at a fixed timeout with N <= 25 rollouts per condition, almost always without confidence intervals or

benchmarking vla manipulation evaluation
PDF Intermediate
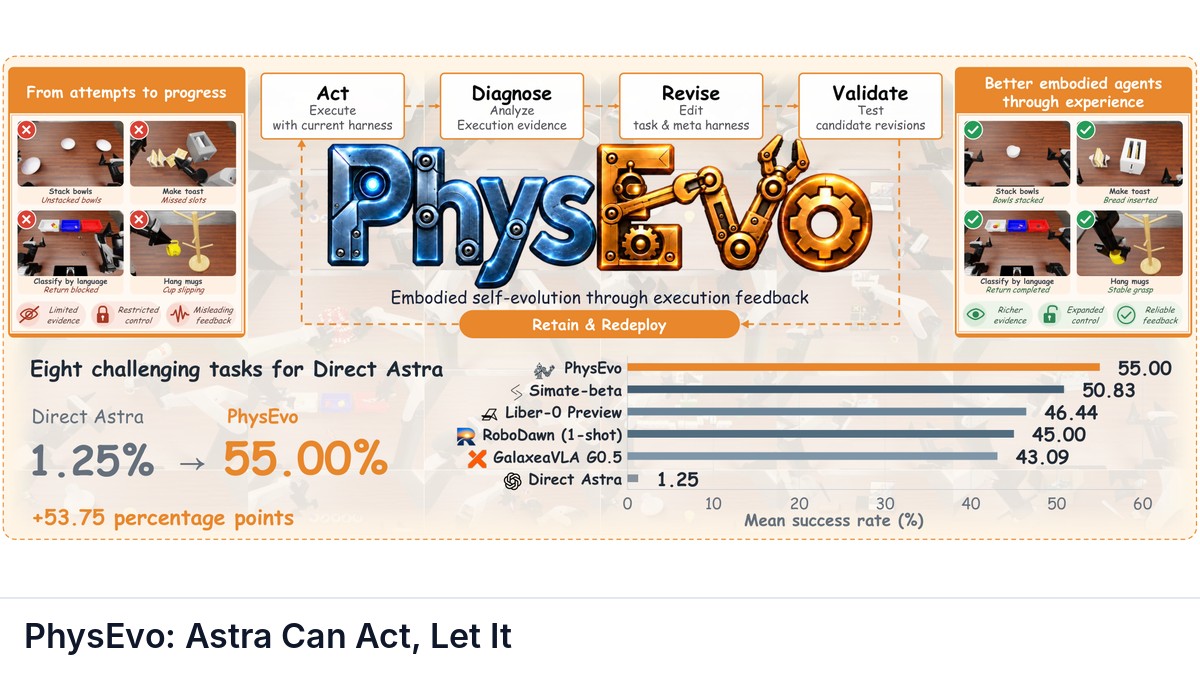
PhysEvo: Astra Can Act, Let It
arXiv preprint

PhysEvo: Astra Can Act, Let It

Wenqing Tian, Zeyu Zhang, Zhaocheng Liu et al.

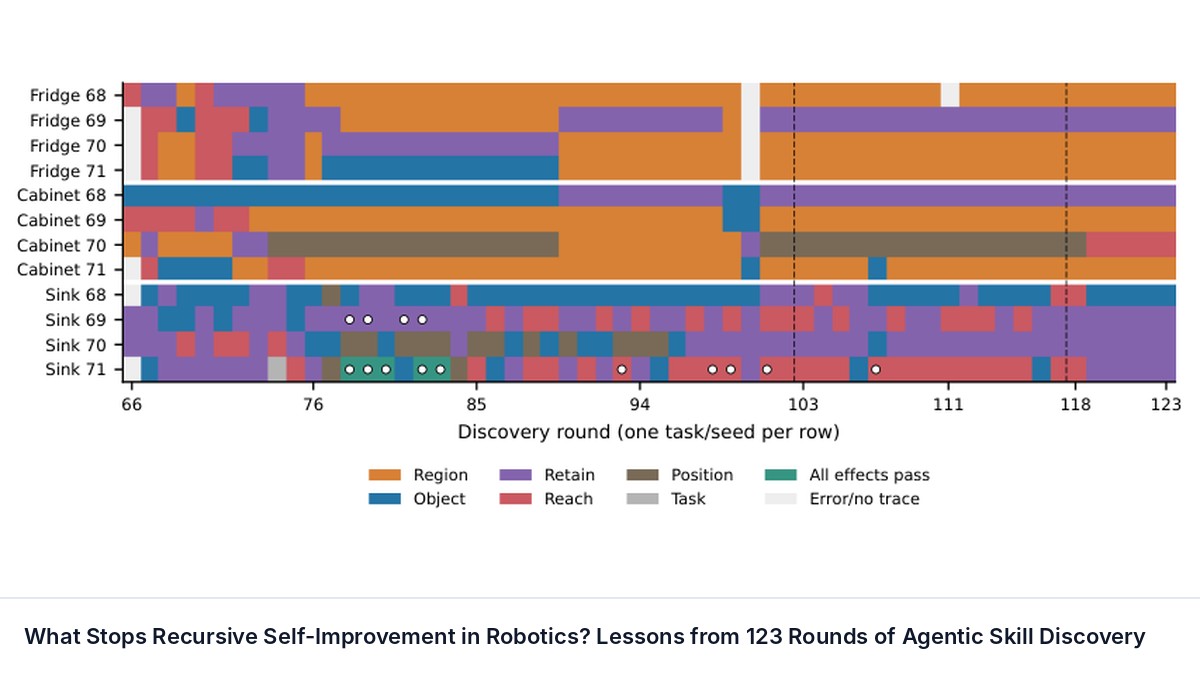
Astra can act, yet reliable manipulation depends on the system through which it observes and controls the world. We introduce PhysEvo, a framework for physical recursive self-improvement (RSI) around a single frozen model.

manipulation vision reinforcement-learning control benchmark
Code PDF Intermediate
GitHub ★ —
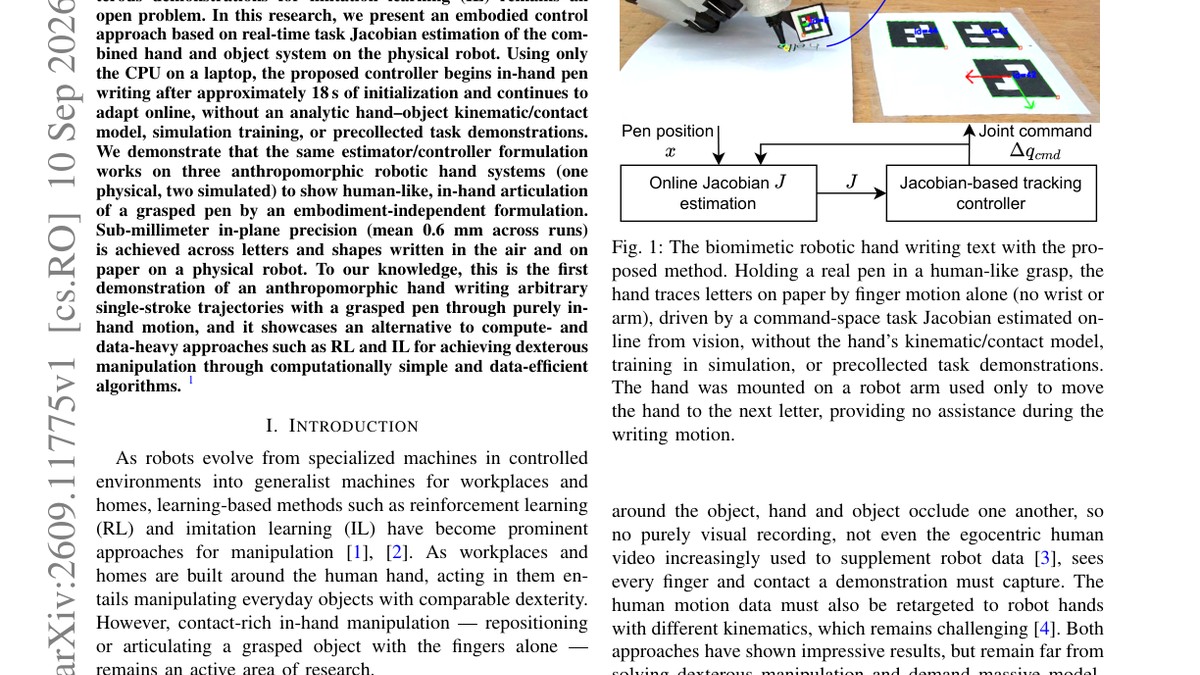
Rapid Learning of Dexterous In-Hand Pen Writing through Real-Time Jacobian Estimation
arXiv preprint

Rapid Learning of Dexterous In-Hand Pen Writing through Real-Time Jacobian Estimation

Kai Stewart, Yasunori Toshimitsu, Robert K. Katzschmann

Dexterous in-hand manipulation of a grasped object with an anthropomorphic hand is an unsolved frontier for robot dexterity. The contact-richness and highly dynamic nature of object-hand interactions tend to require extensive modeling or data-collection efforts for learning-based approaches.

manipulation reinforcement-learning control learning-from-demonstration
Code PDF Intermediate
GitHub ★ —
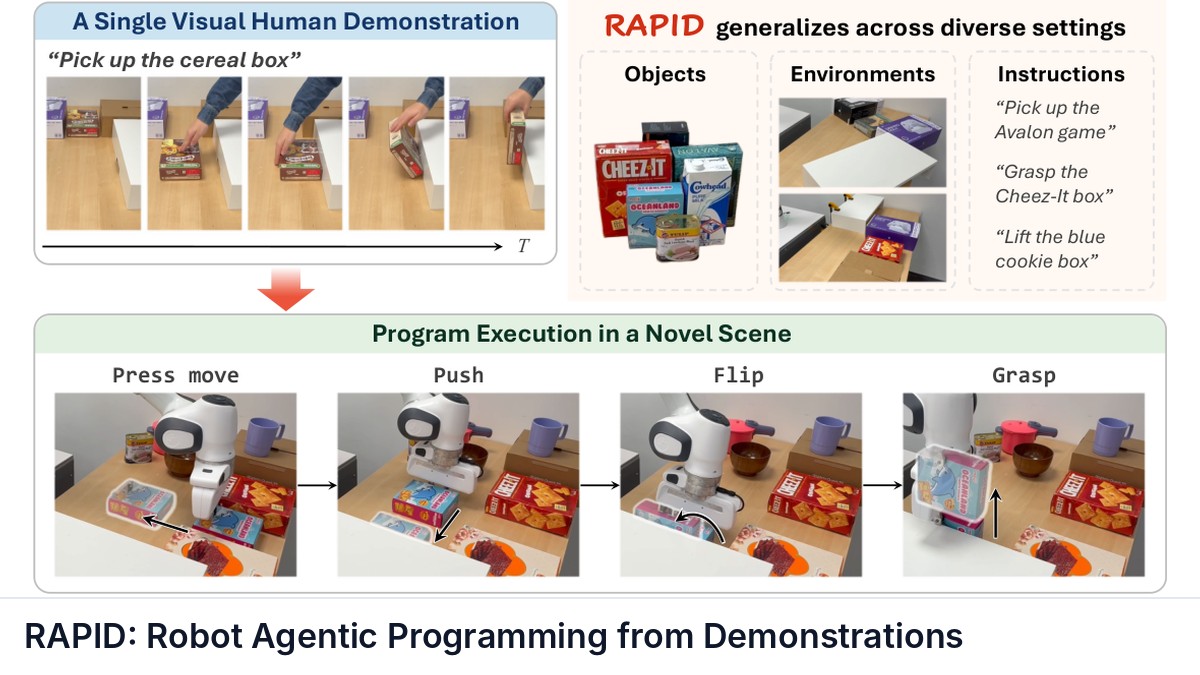
RAPID: Robot Agentic Programming from Demonstrations
arXiv preprint

RAPID: Robot Agentic Programming from Demonstrations

Yuyao Liu, Jiayuan Mao, David Hsu et al.

Coding agents have demonstrated enormous success in solving complex programming problems.

manipulation vision reinforcement-learning control learning-from-demonstration benchmark
PDF Intermediate
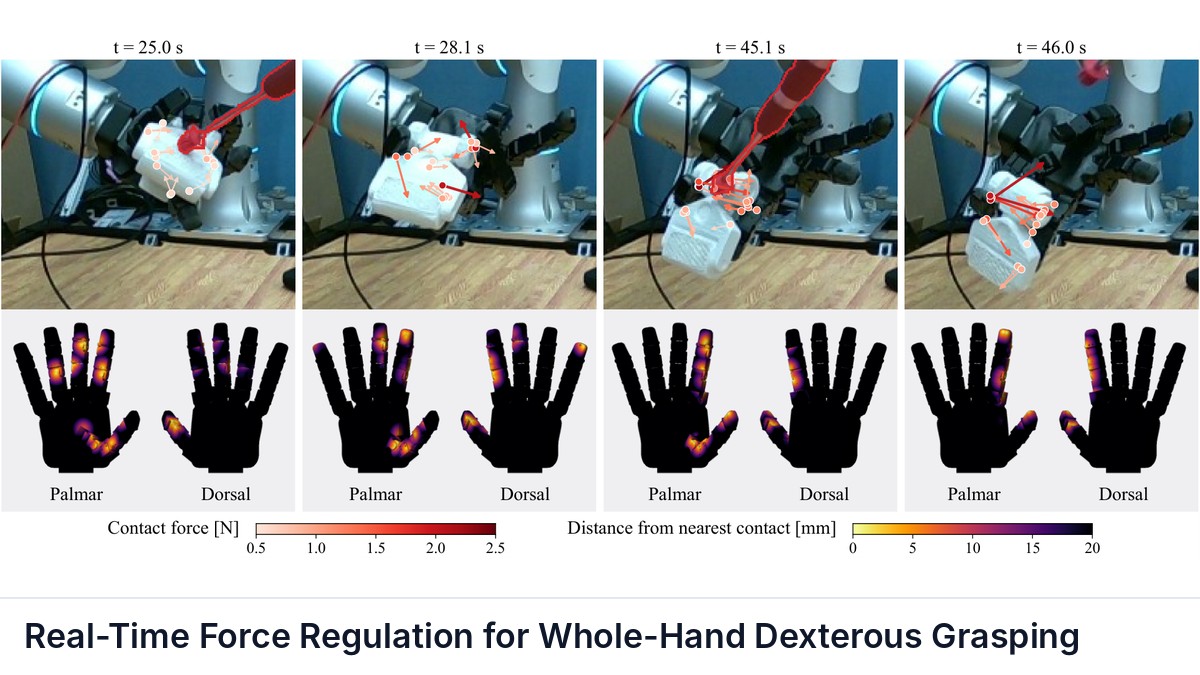
Real-Time Force Regulation for Whole-Hand Dexterous Grasping
arXiv preprint

Real-Time Force Regulation for Whole-Hand Dexterous Grasping

Sang Min Kim, Alexander Alexiev, Tzu-Yuan Lin et al.

Robust dexterous grasping requires maintaining physical stability despite contacts interactively evolving across the entire hand. A precomputed force distribution can easily fail under object motion, modeling errors, or external disturbances.

manipulation reinforcement-learning control tactile
PDF Intermediate
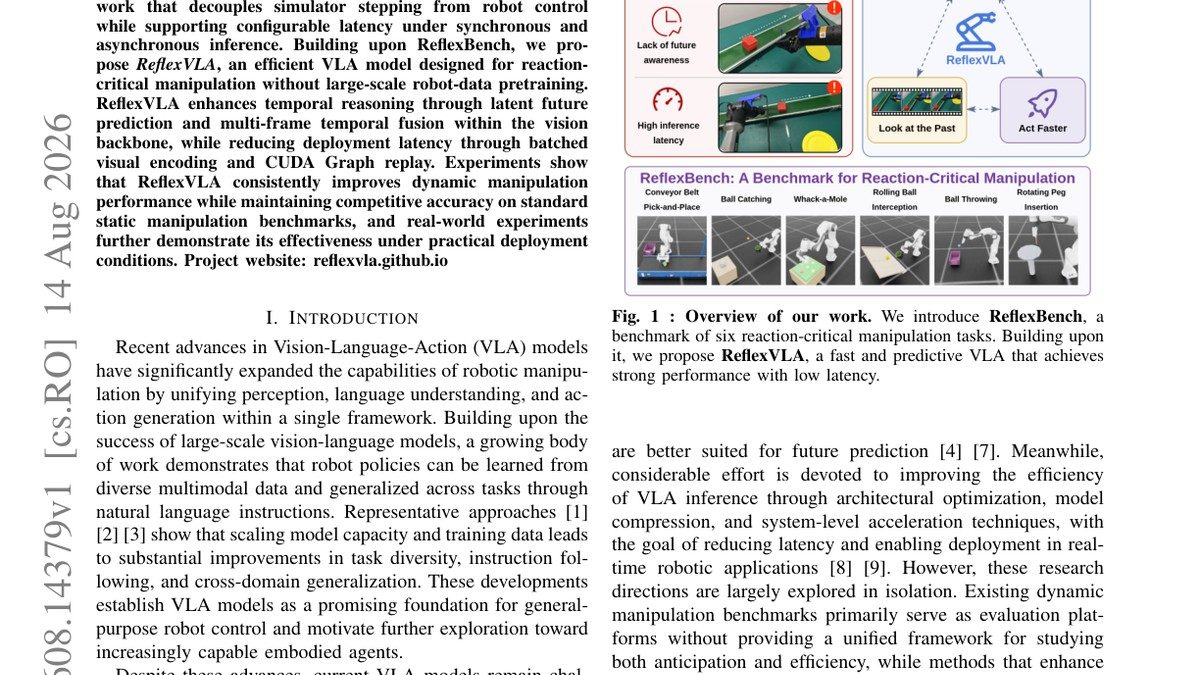
Reflex: Enabling Fast and Predictive Vision-Language-Action Models for Reaction-Critical Manipulation
arXiv preprint

Reflex: Enabling Fast and Predictive Vision-Language-Action Models for Reaction-Critical Manipulation

Yuxuan Chen, Wanruo Zhang, Xiao Li

Vision-Language-Action (VLA) models have recently achieved promising performance in robotic manipulation. However, existing benchmarks mainly evaluate generalization on static manipulation tasks and largely overlook dynamic interaction scenarios.

manipulation vision vla reinforcement-learning control benchmark
Code PDF Advanced
GitHub ★ —
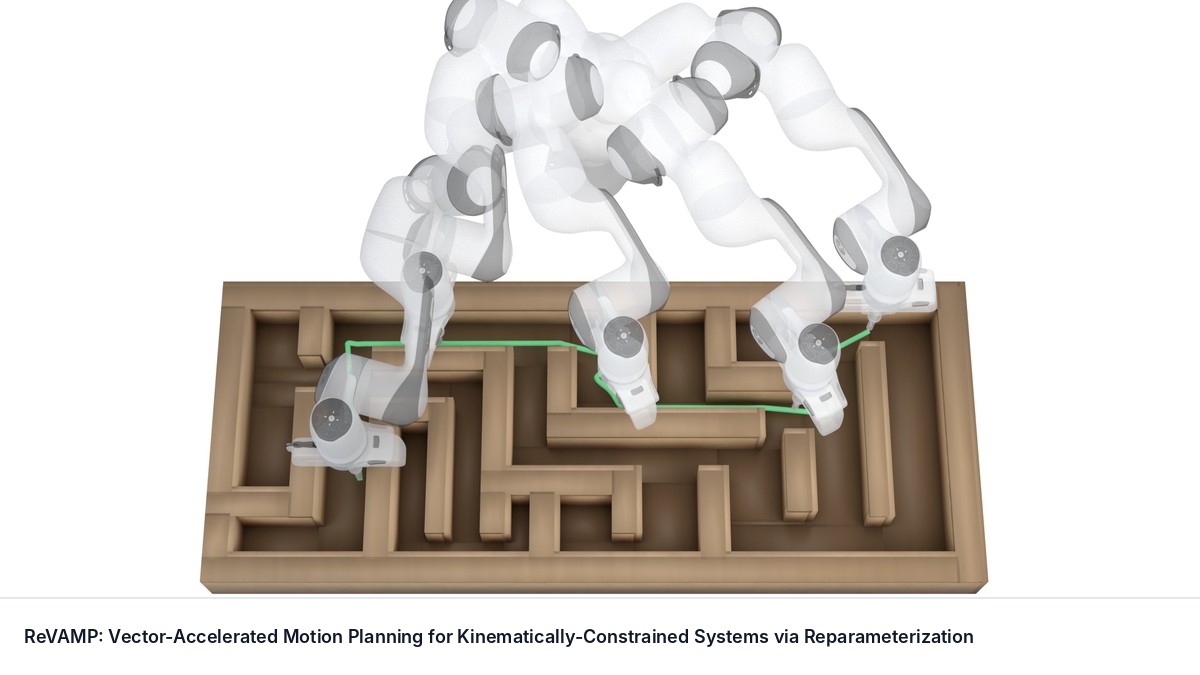
ReVAMP: Vector-Accelerated Motion Planning for Kinematically-Constrained Systems via Reparameterization
arXiv preprint

ReVAMP: Vector-Accelerated Motion Planning for Kinematically-Constrained Systems via Reparameterization

Shrutheesh R. Iyer, Thomas Cohn, Zachary Kingston

Robots often must satisfy one or more constraints during motion planning for real-world tasks. When such constraints reduce the valid configuration space to a measure-zero subset, sampling based planning algorithms require modifications to draw feasible samples.

manipulation reinforcement-learning planning
PDF Intermediate
RoboTTT: Context Scaling for Robot Policies
arXiv preprint

RoboTTT: Context Scaling for Robot Policies

Yunfan Jiang, Yevgen Chebotar, Ruijie Zheng et al.

Recent robot foundation models operate with single-step or short-history visuomotor context.

manipulation vision vla reinforcement-learning learning-from-demonstration
Code PDF Advanced
GitHub ★ —
Rolling-WAM: World Action Models with Rolling Imagination
arXiv preprint

Rolling-WAM: World Action Models with Rolling Imagination

Yinghua Zhou, Junjie Ye, Yiqi Zhao et al.

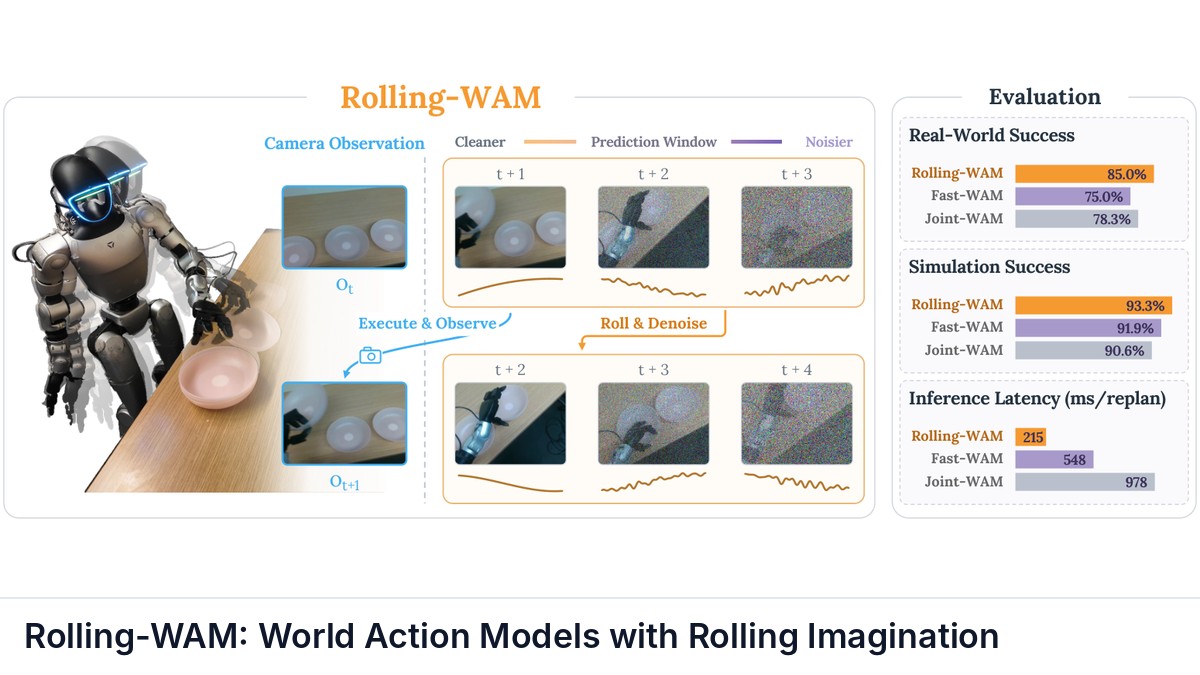
World Action Models (WAMs) couple action generation with future visual prediction for robotic manipulation. However, completing the joint video-action denoising process at each replanning cycle incurs substantial latency, delaying action updates and limiting closed-loop responsiveness.

manipulation vision reinforcement-learning planning benchmark
Code PDF Intermediate
GitHub ★ —
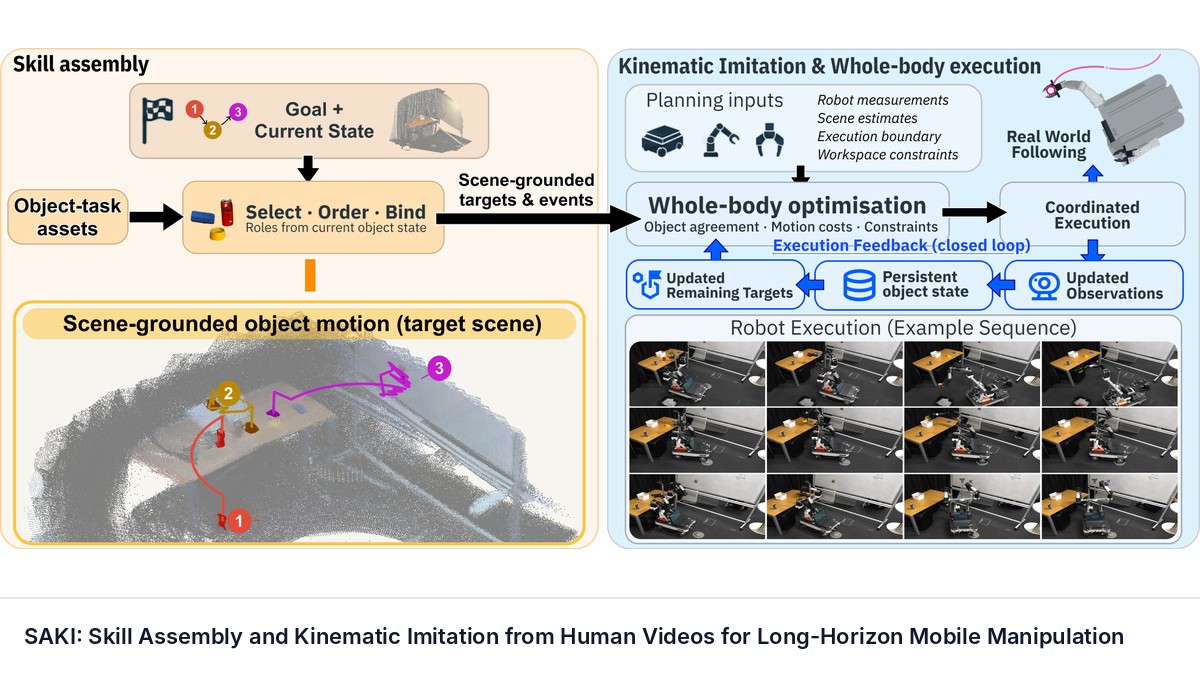
SAKI: Skill Assembly and Kinematic Imitation from Human Videos for Long-Horizon Mobile Manipulation
arXiv preprint

SAKI: Skill Assembly and Kinematic Imitation from Human Videos for Long-Horizon Mobile Manipulation

Yijie Lu, James Zhao, Weiming Zhi

Learning from human videos offers a promising route to acquiring diverse manipulation skills. Extending this capability beyond tabletop settings to long-horizon mobile manipulation requires adapting and composing demonstrated interactions across changing scenes and robot configurations.

manipulation vision learning-from-demonstration
PDF Intermediate
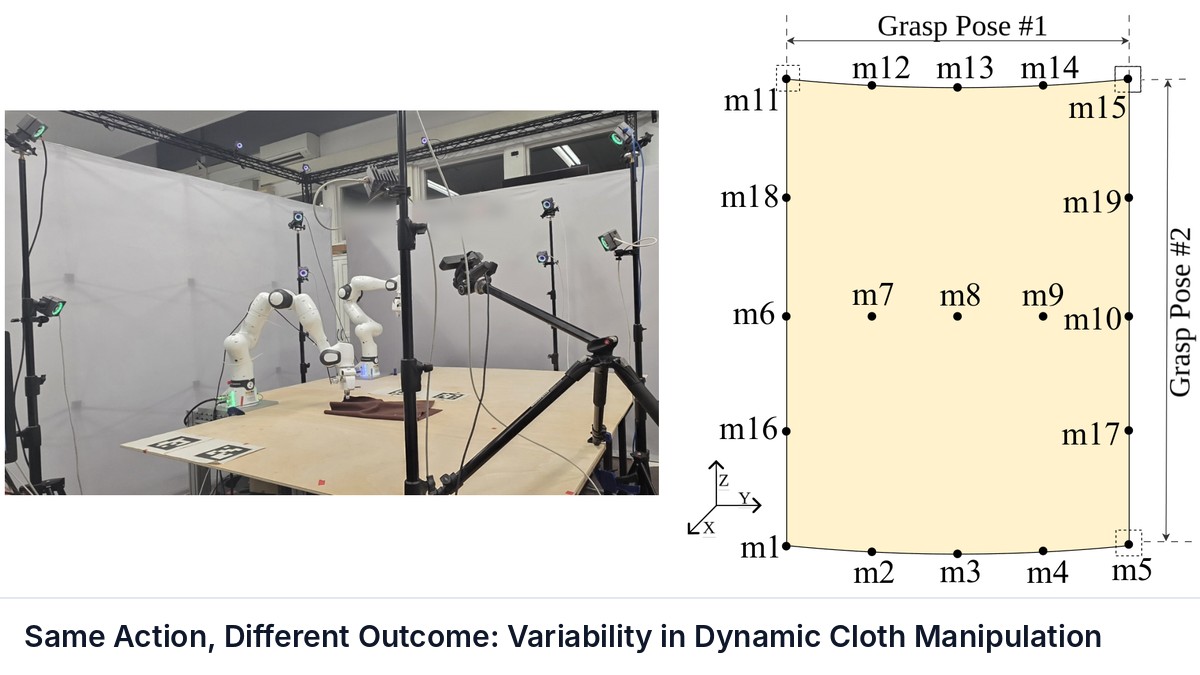
Same Action, Different Outcome: Variability in Dynamic Cloth Manipulation
arXiv preprint

Same Action, Different Outcome: Variability in Dynamic Cloth Manipulation

Mahed Dadgostar, Guillem Aleny\`a, J\'ulia Borr\`as

Although cloth is known to exhibit different outcomes under repeated fast dynamic motions, even when the same trajectory is applied, this variability has not yet been systematically characterized.

manipulation vision reinforcement-learning benchmark
Code PDF Intermediate
GitHub ★ —
Sample-Efficient Diffusion-based Reinforcement Learning with Critic Guidance
ICML 2026

Sample-Efficient Diffusion-based Reinforcement Learning with Critic Guidance

Shutong Ding, Zejia Zhong, Zhongyi Wang et al.

Recent advances in reinforcement learning (RL) have achieved great successes by leveraging the multimodality and exploration capability of diffusion policies. Among these approaches, one representativ

diffusion-policy reinforcement-learning locomotion manipulation
PDF Advanced
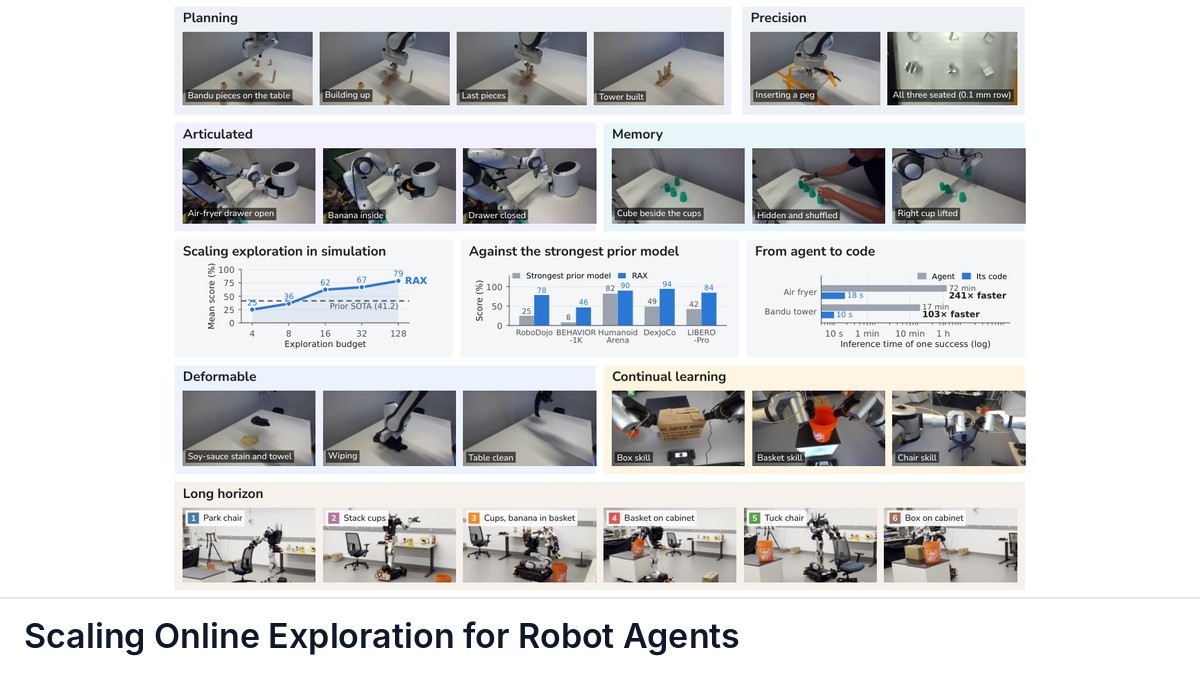
Scaling Online Exploration for Robot Agents
arXiv preprint

Scaling Online Exploration for Robot Agents

Runhan Huang, Xiangcheng Zhang, Haoyu Chen et al.

Robot learning has advanced by scaling demonstration datasets and model capacity; however, deploying a new robot embodiment or task typically necessitates a dedicated teleoperation corpus.

manipulation vision reinforcement-learning planning control learning-from-demonstration benchmark
PDF Intermediate
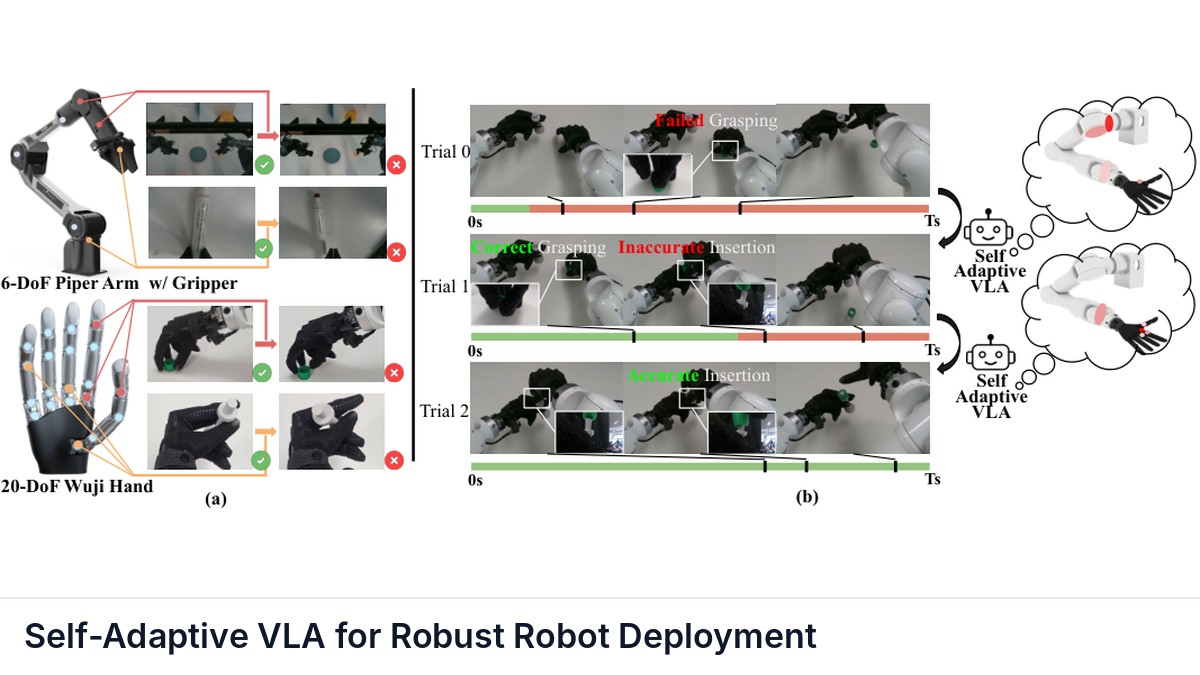
Self-Adaptive VLA for Robust Robot Deployment
arXiv preprint

Self-Adaptive VLA for Robust Robot Deployment

Hongxin Zhang, Chunru Lin, Tsun-Hsuan Wang et al.

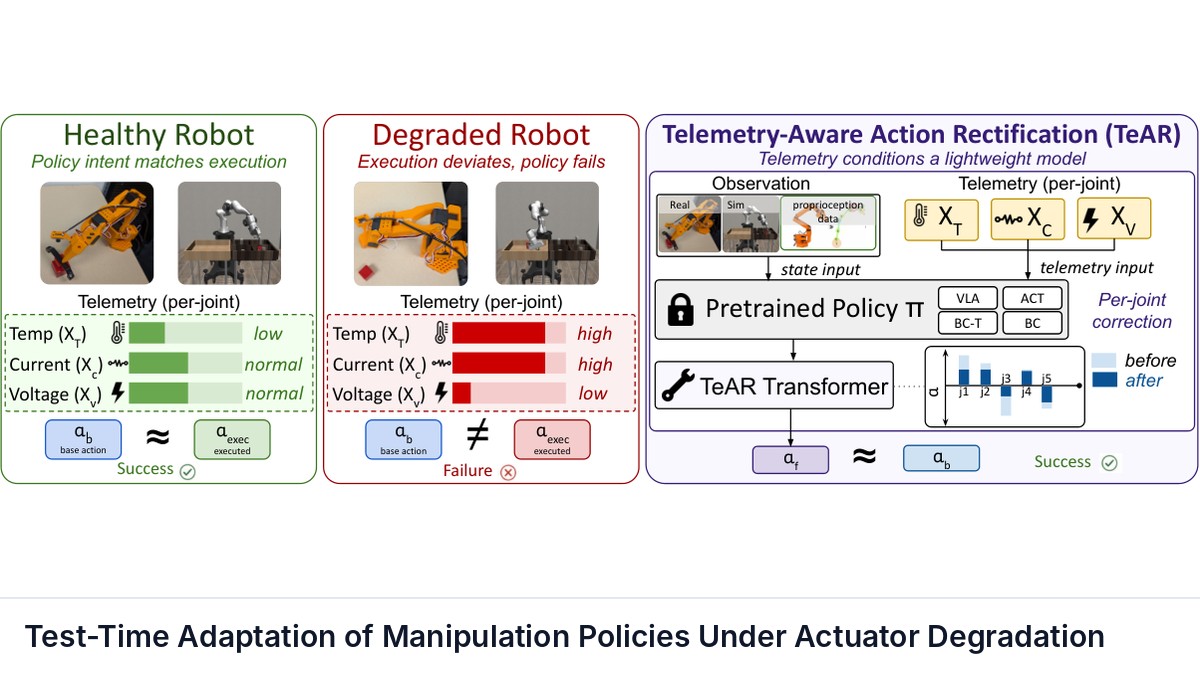
While Vision-Language-Action (VLA) models demonstrate impressive capabilities in robotic manipulation, their memoryless nature renders them brittle to test-time environment shifts, particularly hardware shifts caused by wear or imperfect calibration.

manipulation vision vla reinforcement-learning learning-from-demonstration
Code PDF Advanced
GitHub ★ —
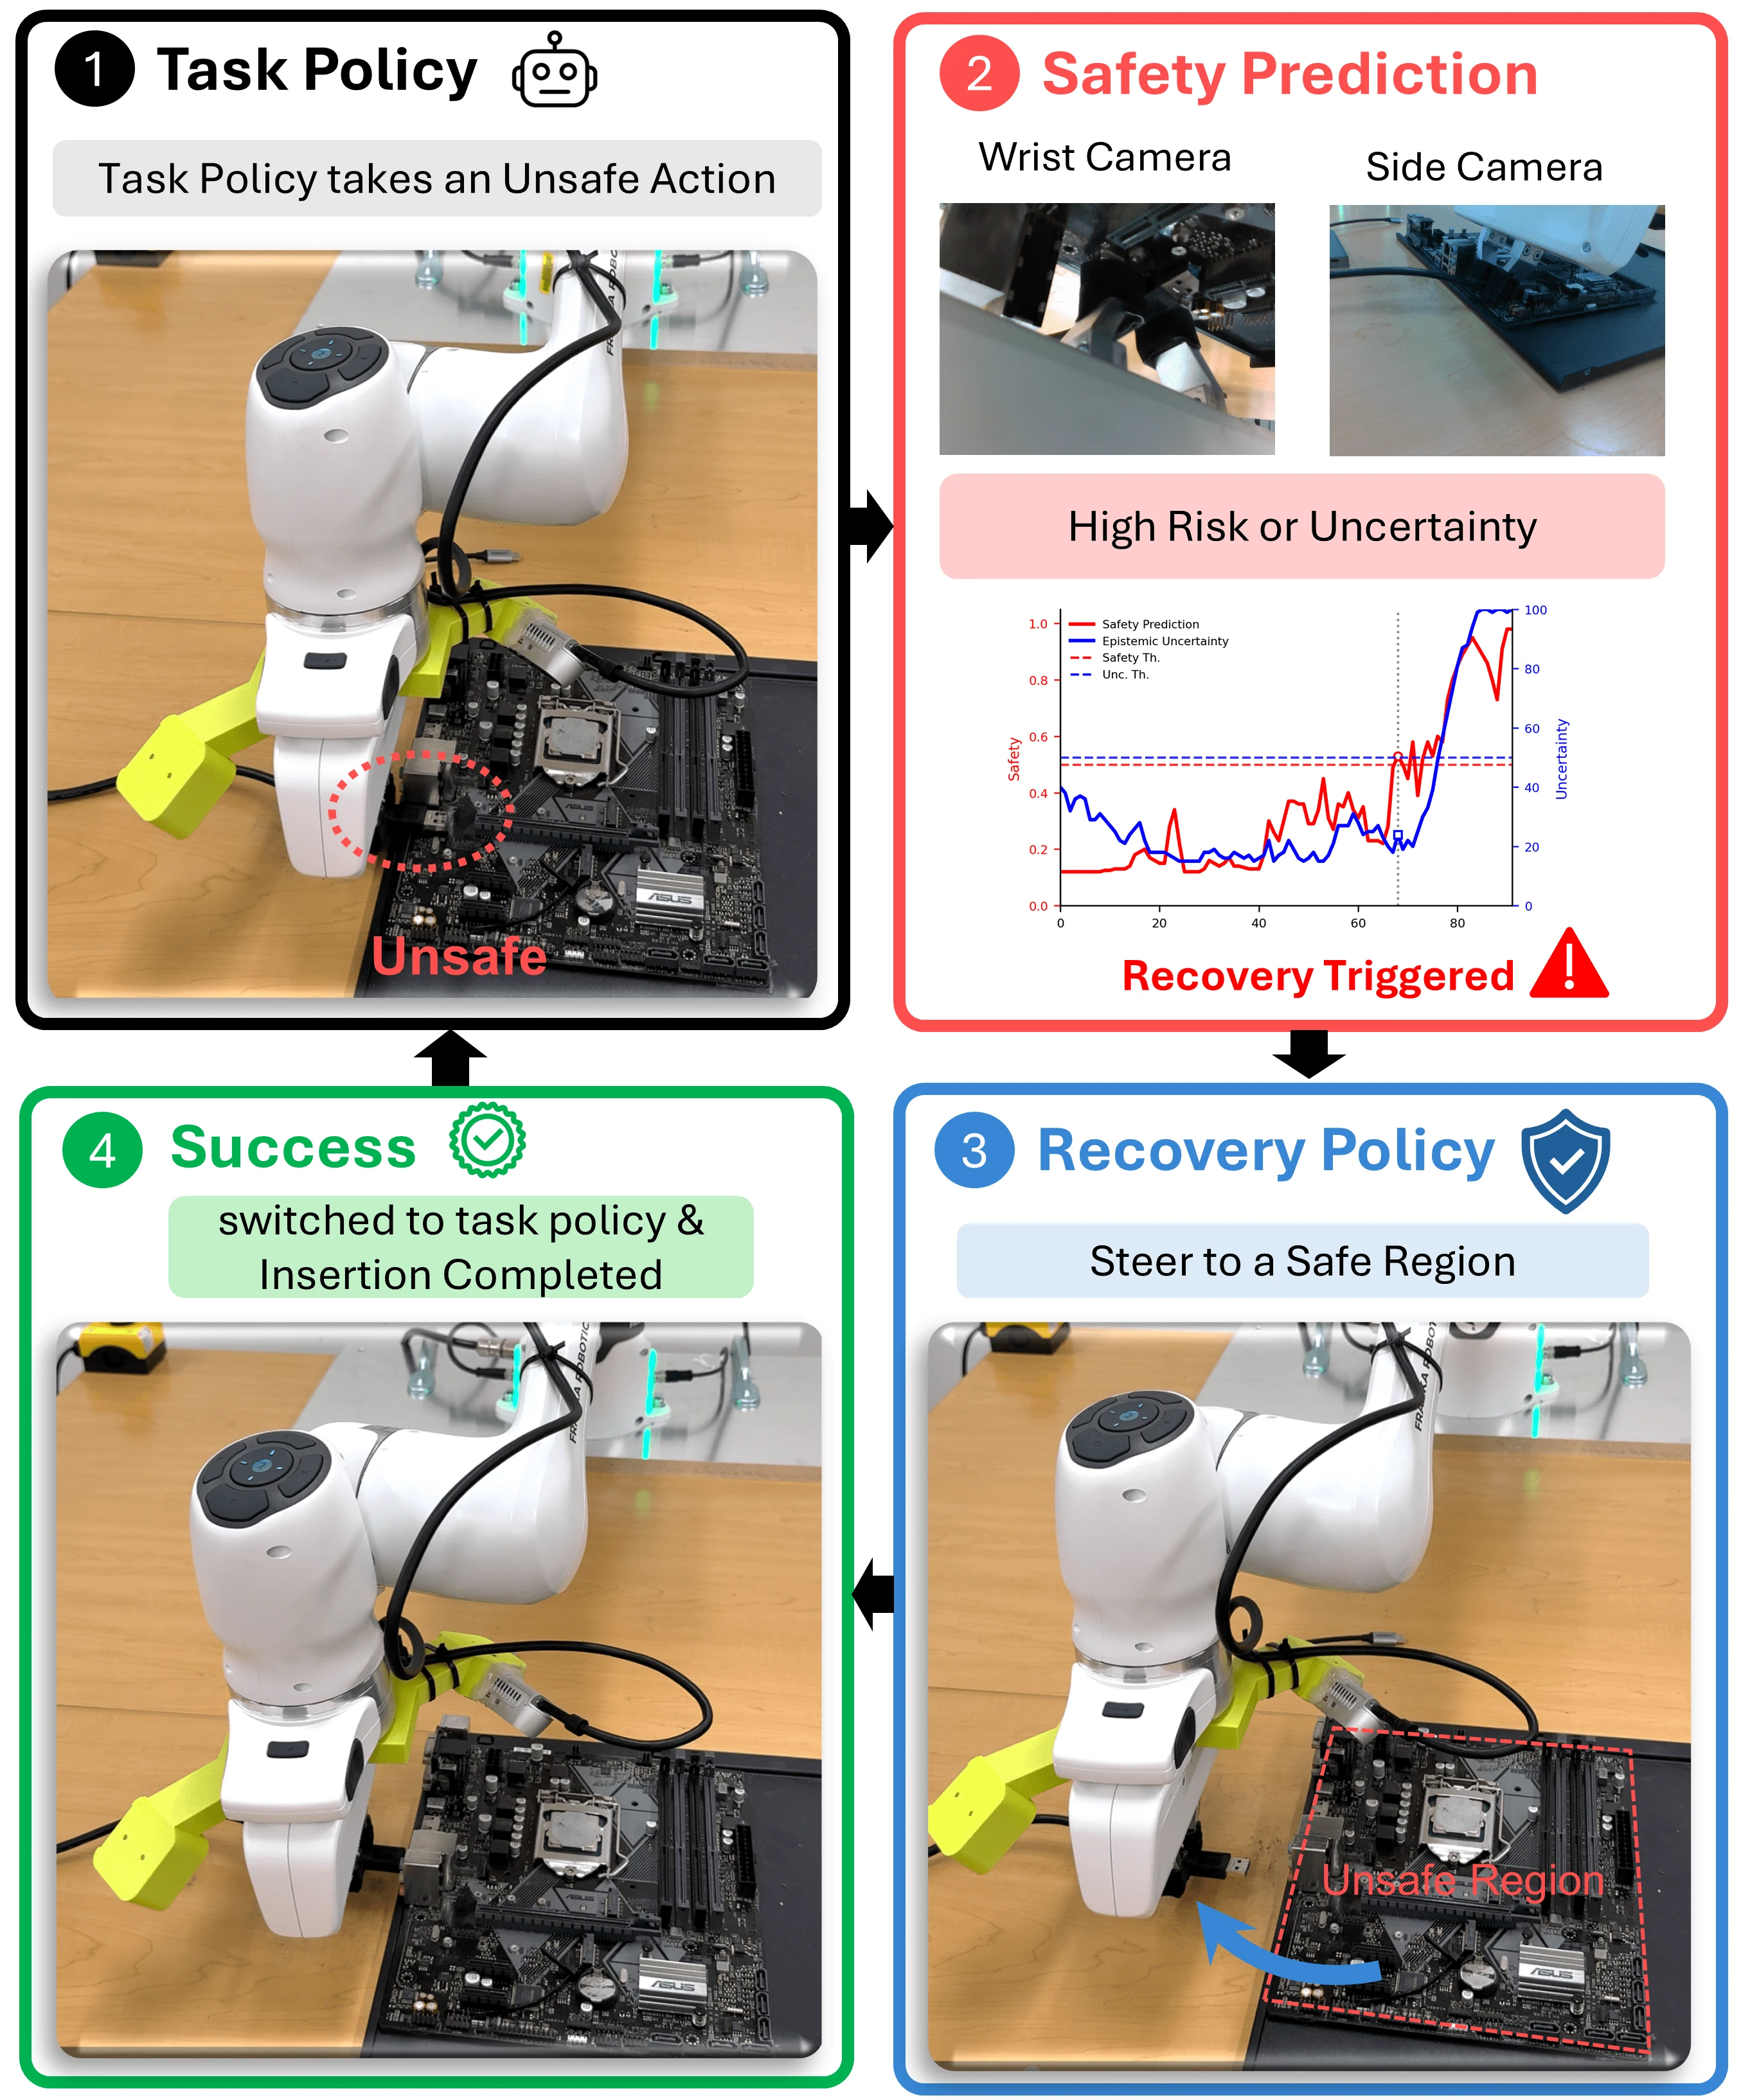
SEVI: Safe Evidential Real-World Reinforcement Learning
arXiv preprint

SEVI: Safe Evidential Real-World Reinforcement Learning

Shaekh Mohammad Shithil, Lantao Liu

SEVI targets unsafe interactions during online reinforcement learning on physical robots by deciding when a proposed action should be replaced with a recovery behavior.

manipulation reinforcement-learning
PDF Intermediate
SkeleWAM: Skeleton World-Action Modeling for Efficient Robotic Manipulation
arXiv preprint

SkeleWAM: Skeleton World-Action Modeling for Efficient Robotic Manipulation

Juyi Sheng, Hua Wang, Mengyuan Liu

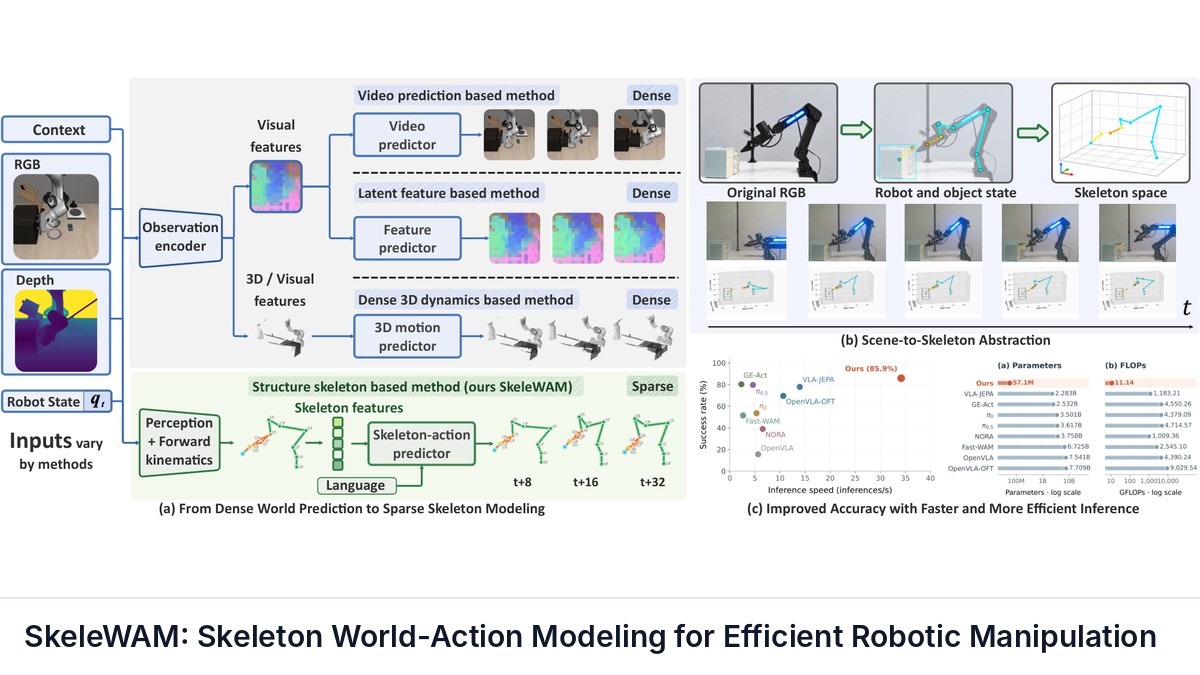
World action models (WAMs) combine robot action generation with future state prediction. Existing WAMs typically predict videos or learned visual latents, which represent interaction geometry only implicitly and may retain appearance information unrelated to control.

manipulation vision reinforcement-learning control
PDF Intermediate
SocialVLA: A Social Perception Gateway for Human-Reaction-Based Failure Detection and Recovery in VLA Manipulation
arXiv preprint

SocialVLA: A Social Perception Gateway for Human-Reaction-Based Failure Detection and Recovery in VLA Manipulation

Sofya Konstantinova, Miguel Altamirano Cabrera, Artem Lykov et al.

Vision-language-action (VLA) policies enable diverse robotic manipulation but can fail during execution without recognizing their own errors. Human observers provide complementary signals, as unexpected robot behavior can trigger rapid vocal, facial, or verbal reactions before failure is completed.

manipulation vision vla reinforcement-learning control
Code PDF Intermediate
GitHub ★ —
SoTa: Soft Tactile Skins for Dexterous Manipulation
arXiv preprint

SoTa: Soft Tactile Skins for Dexterous Manipulation

Jingyun Yang, Baiyu Shi, Timothy Yu et al.

A growing body of work suggests that tactile sensing gives robot policies contact information that complements vision in dexterous manipulation. However, visuo-tactile robot data remains scarce: dexterous demonstrations require teleoperating robots, which limits dataset scale.

manipulation vision reinforcement-learning learning-from-demonstration tactile benchmark
PDF Intermediate
SUAVE: Unified Video-Action Models via Masked Diffusion
arXiv preprint

SUAVE: Unified Video-Action Models via Masked Diffusion

Rhythm Syed, Jean Mercat, Sedrick Keh et al.

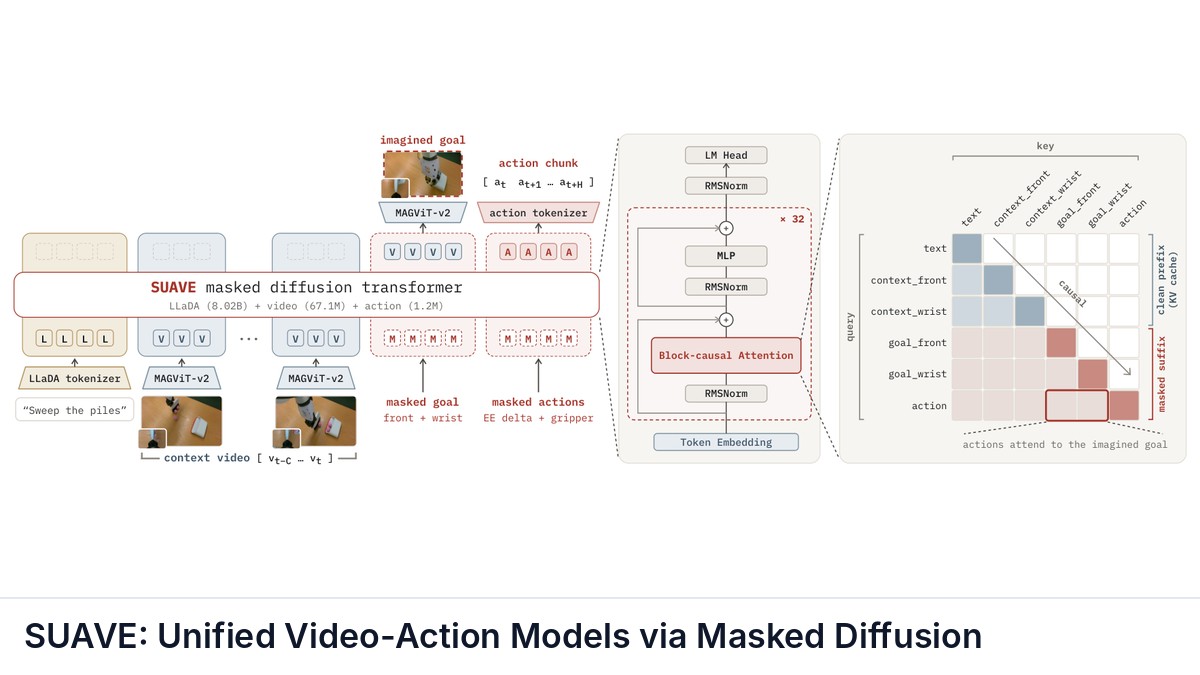
Vision-language-action models (VLAs) inherit strong semantic grounding from pretrained vision-language backbones but are typically optimized for predicting actions rather than future observations. They can see and act, but they do not imagine the future before acting.

manipulation vision vla reinforcement-learning control
PDF Advanced
SWAP: Stepwise Action Policy Routing for Vision-Language-Action Models
arXiv preprint

SWAP: Stepwise Action Policy Routing for Vision-Language-Action Models

Mousumi Das, Aditeya Prajapati, Abrar Anwar et al.

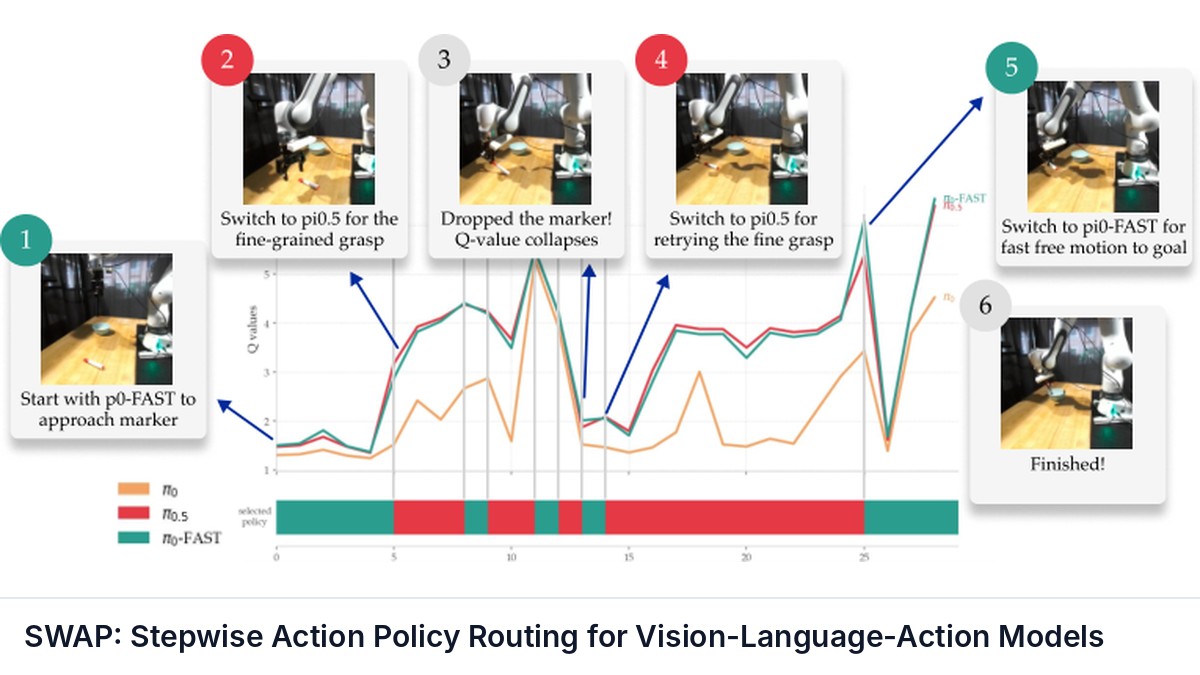
Robot manipulation systems using Vision-Language-Action (VLA) model backbones typically use just one VLA for task execution. However, individual VLAs do not perform well across different task states and environments.

manipulation vision vla reinforcement-learning
Code PDF Intermediate
GitHub ★ —
SWIM: Vision-Language-Grounded Soft Whole-Body Interactive Manipulation
arXiv preprint

SWIM: Vision-Language-Grounded Soft Whole-Body Interactive Manipulation

Tingcong Liu, Aye Phyu Phyu Aung, Junjie Xiong et al.

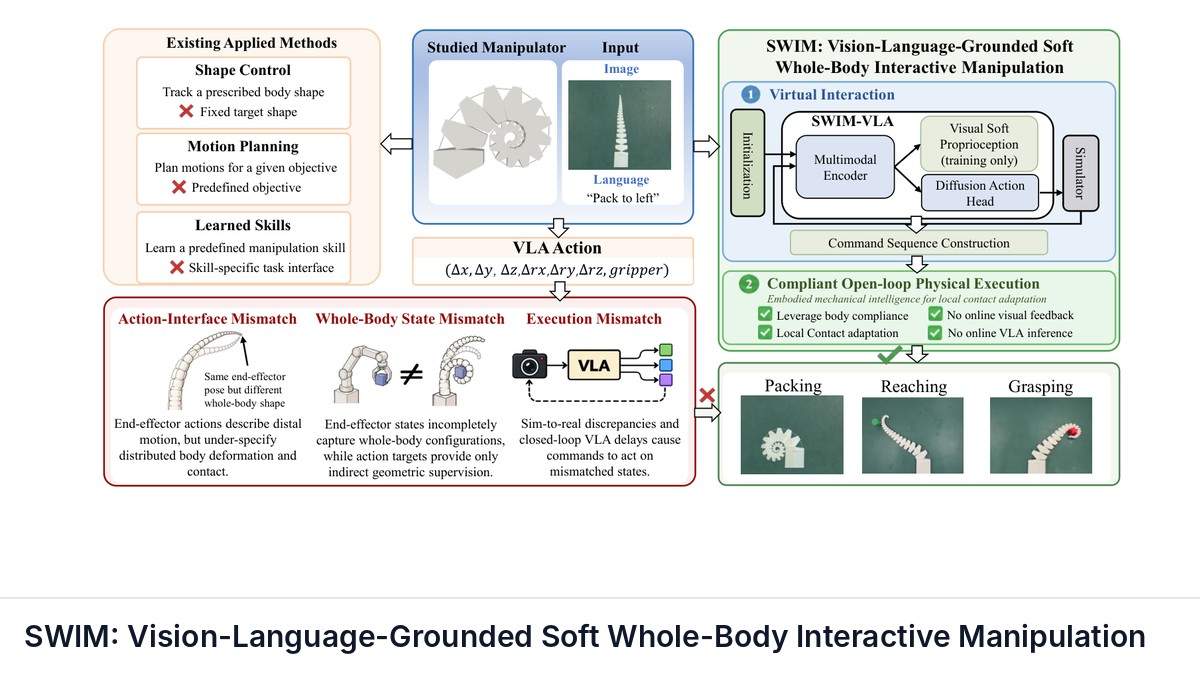
Soft and continuum robots enable manipulation through distributed body deformation and contact, yet translating language and visual context into executable whole-body actuation remains a fundamental challenge.

manipulation vision vla reinforcement-learning control learning-from-demonstration
PDF Advanced
Task-space model-based control of pneumatic soft actuators
arXiv preprint

Task-space model-based control of pneumatic soft actuators

Nithin S. Kumar, Joshua Gaston, D. Caleb Rucker et al.

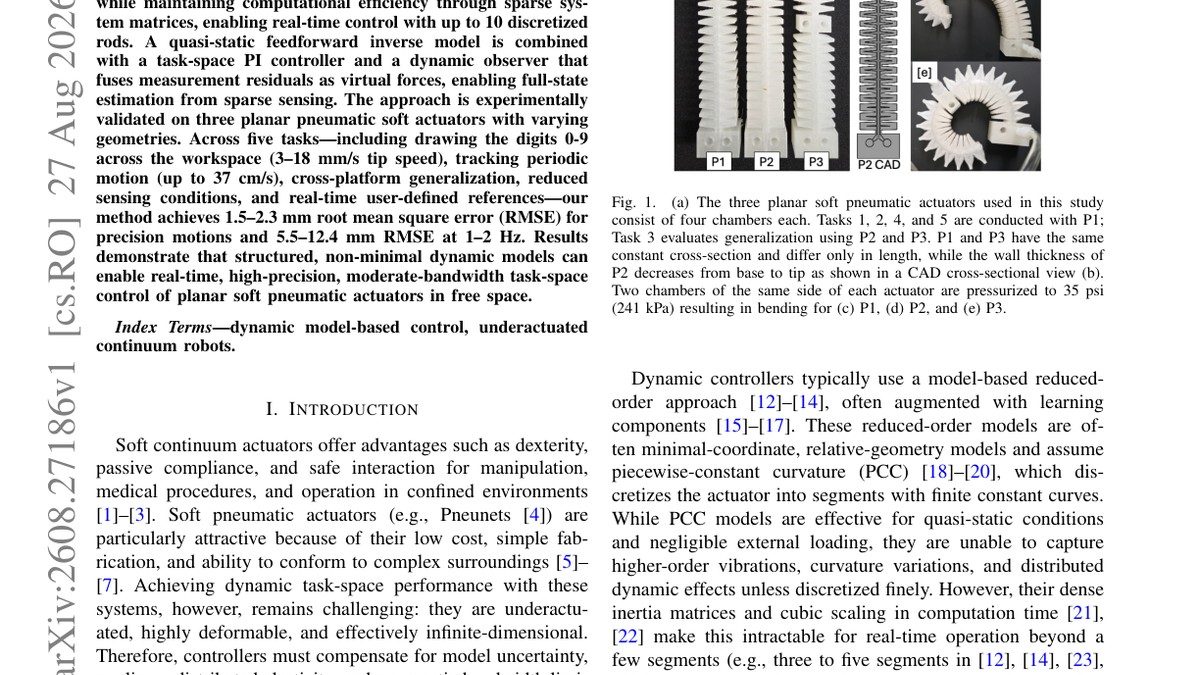
Soft actuators enable dexterous and compliant interaction, but closed-loop task-space control remains challenging due to strong nonlinearities, distributed deformation, and uncertainty in their dynamics.

manipulation control
PDF Advanced
THRIVE: Therapeutic Humanoid Robot In Virtual Environment
arXiv preprint

THRIVE: Therapeutic Humanoid Robot In Virtual Environment

Jin Xu, Yu-Ping Chen, Ayanna Howard

This paper presents THRIVE (Therapeutic Humanoid Robot In Virtual Environment), an at-home rehabilitation platform that integrates a suite of virtual-reality upper-body rehabilitation games, a real-time camera-based motion-tracking system, and a socially interactive robot therapist.

manipulation vision reinforcement-learning human-robot-interaction
PDF Intermediate
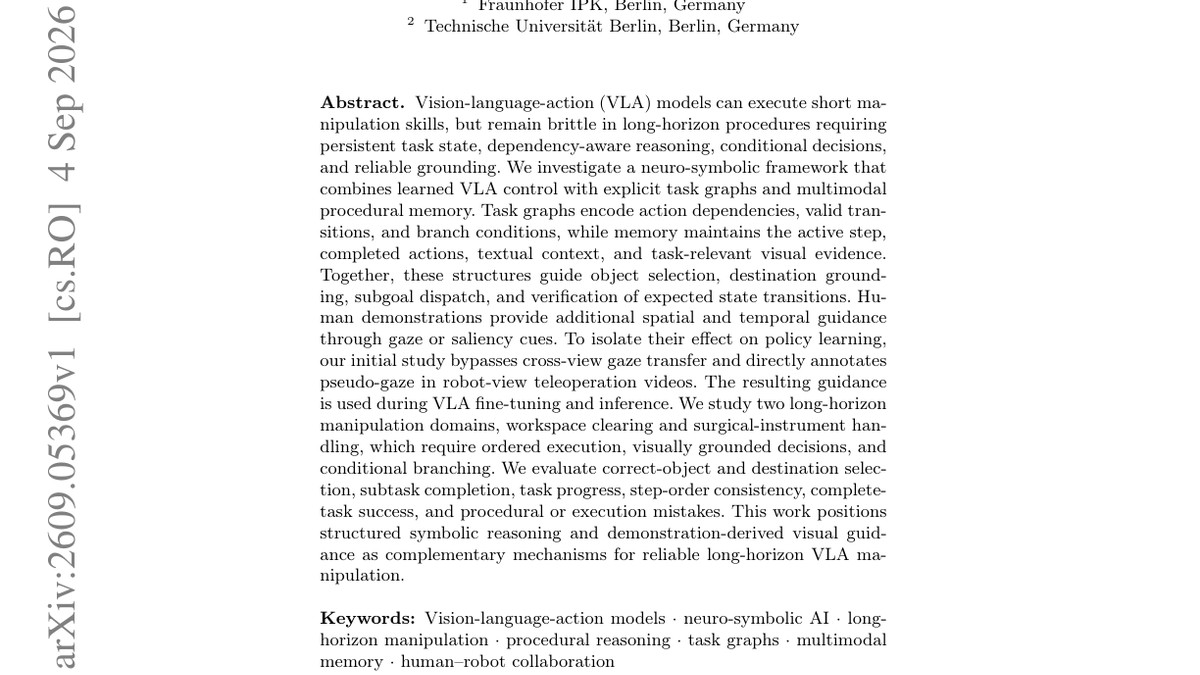
Towards Neuro-Symbolic Procedural Reasoning for Long-Horizon Vision-Language-Action Manipulation
arXiv preprint

Towards Neuro-Symbolic Procedural Reasoning for Long-Horizon Vision-Language-Action Manipulation

Vivek Chavan, Yahuan Shi, Oliver Heimann et al.

Vision-language-action (VLA) models can execute short manipulation skills, but remain brittle in long-horizon procedures requiring persistent task state, dependency-aware reasoning, conditional decisions, and reliable grounding.

manipulation vision vla reinforcement-learning control learning-from-demonstration
PDF Intermediate
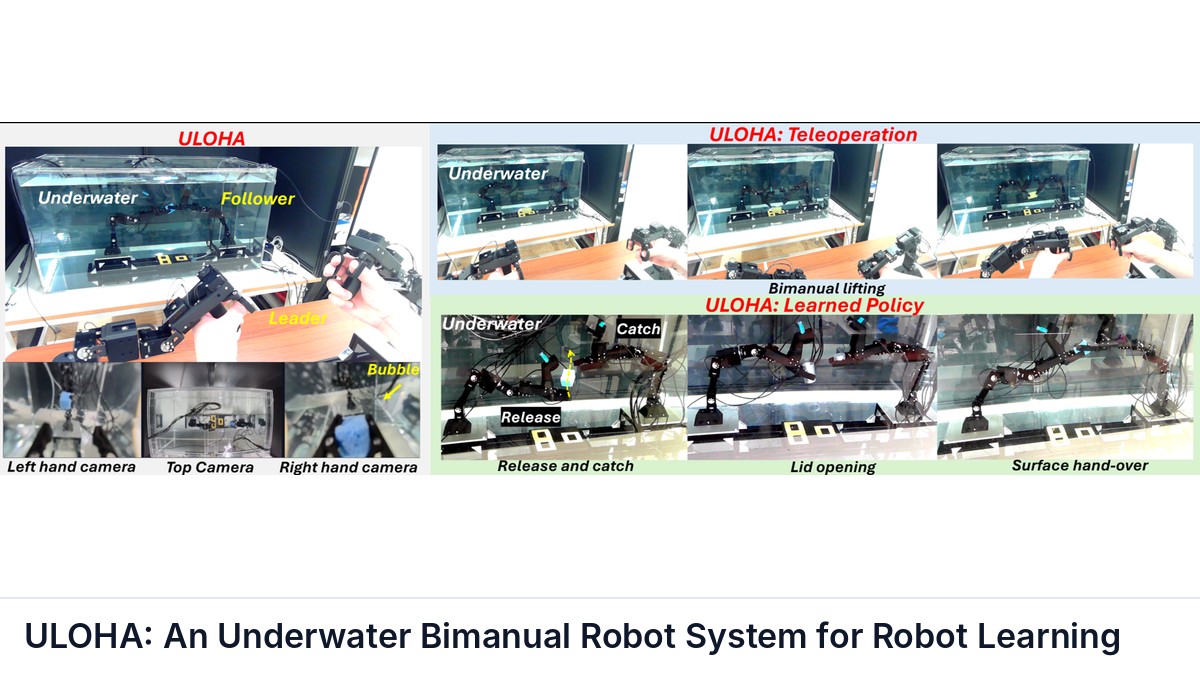
ULOHA: An Underwater Bimanual Robot System for Robot Learning
arXiv preprint

ULOHA: An Underwater Bimanual Robot System for Robot Learning

Masato Kobayashi, Takeru Tsunoori

Underwater visuomotor policy learning has focused primarily on single manipulators, while bimanual imitation learning has been studied largely in air.

manipulation vision vla reinforcement-learning learning-from-demonstration
Code PDF Advanced
GitHub ★ —
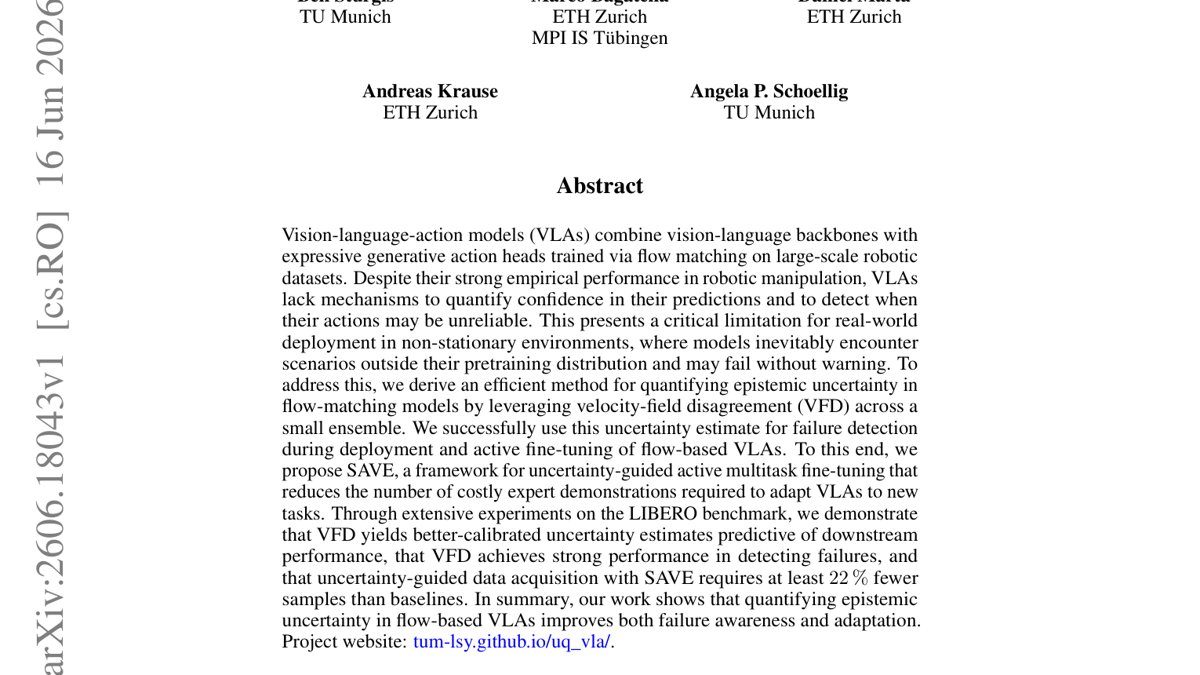
Uncertainty Quantification for Flow-Based Vision-Language-Action Models
RSS 2026 — Best Paper Award

Uncertainty Quantification for Flow-Based Vision-Language-Action Models

Ralf Römer, Maximilian Seeliger, Saida Liu et al.

Quantifies epistemic uncertainty in flow-matching VLAs using velocity-field disagreement (VFD) across a small ensemble, enabling failure detection at deployment and sample-efficient active fine-tuning (SAVE).

vla foundation-models safety manipulation
Code PDF Advanced
GitHub ★ —
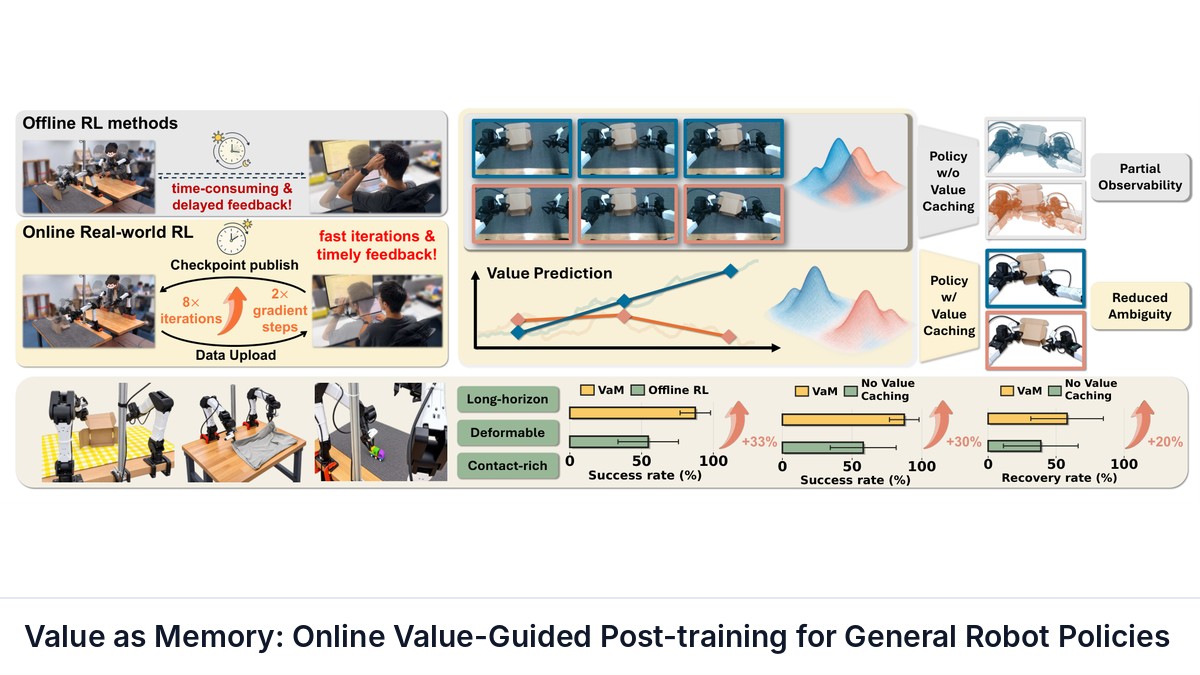
Value as Memory: Online Value-Guided Post-training for General Robot Policies
arXiv preprint

Value as Memory: Online Value-Guided Post-training for General Robot Policies

Wenye Yu, Yijin Chen, Kaiyi Xiong et al.

Real-world post-training of generalist robot policies faces two challenges: partial observability makes action selection ambiguous, while offline post-training methods delay feedback from deployment experience.

manipulation reinforcement-learning learning-from-demonstration
Code PDF Intermediate
GitHub ★ —
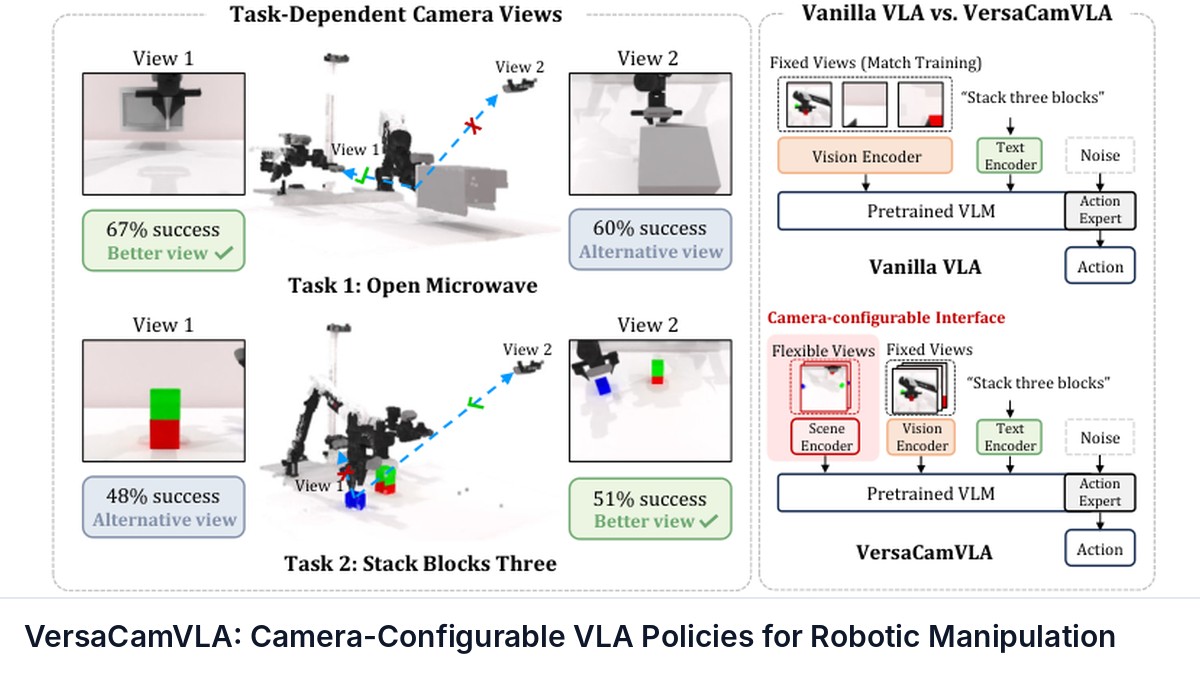
VersaCamVLA: Camera-Configurable VLA Policies for Robotic Manipulation
arXiv preprint

VersaCamVLA: Camera-Configurable VLA Policies for Robotic Manipulation

Boyao Han, Chen Shi, Jingjing Qian et al.

Vision-Language-Action (VLA) models have emerged as powerful foundations for robotic manipulation, but their reliance on fixed camera configurations during training makes them brittle to changes in camera count or pose during deployment.

manipulation vision vla reinforcement-learning
Code PDF Intermediate
GitHub ★ —
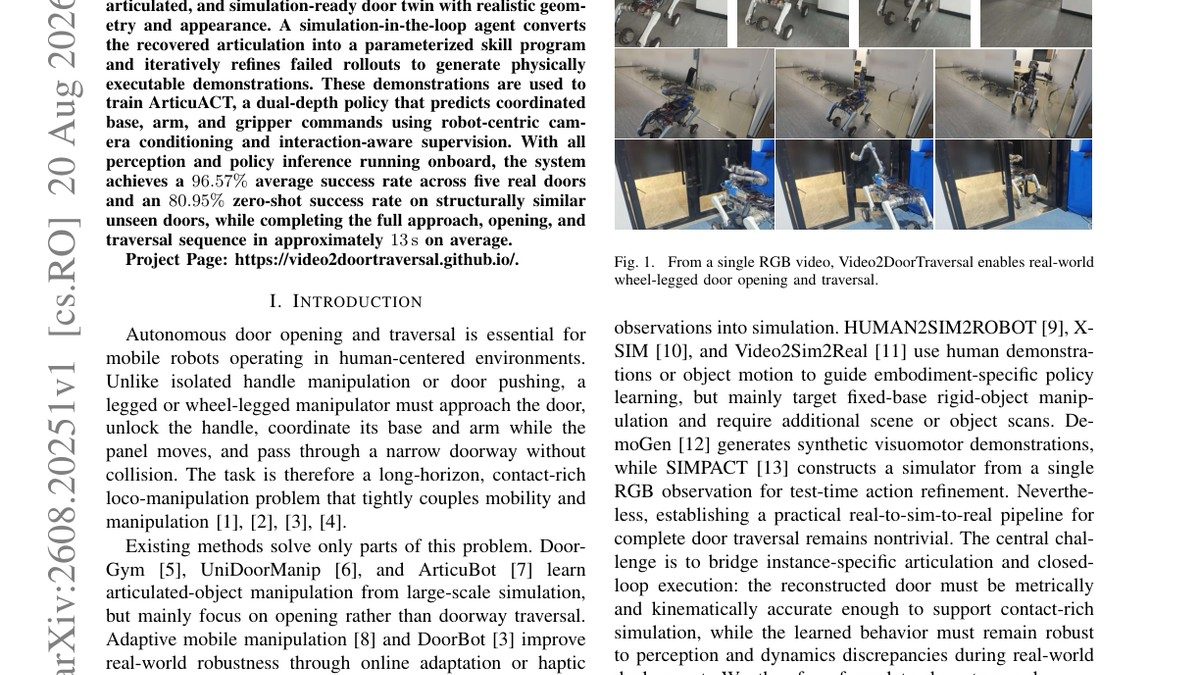
Video2DoorTraversal: Push Door Traversal via Simulated Door Twins
arXiv preprint

Video2DoorTraversal: Push Door Traversal via Simulated Door Twins

Xincheng Tang, Yiji Chen, Youhan Xie et al.

Door opening and traversal is a long-horizon loco-manipulation task that requires precise handle interaction and coordinated base-arm control. We present Video2DoorTraversal, a single-video real-to-sim-to-real framework for wheel-legged mobile manipulators.

manipulation locomotion vision reinforcement-learning sim-to-real control learning-from-demonstration
PDF Intermediate
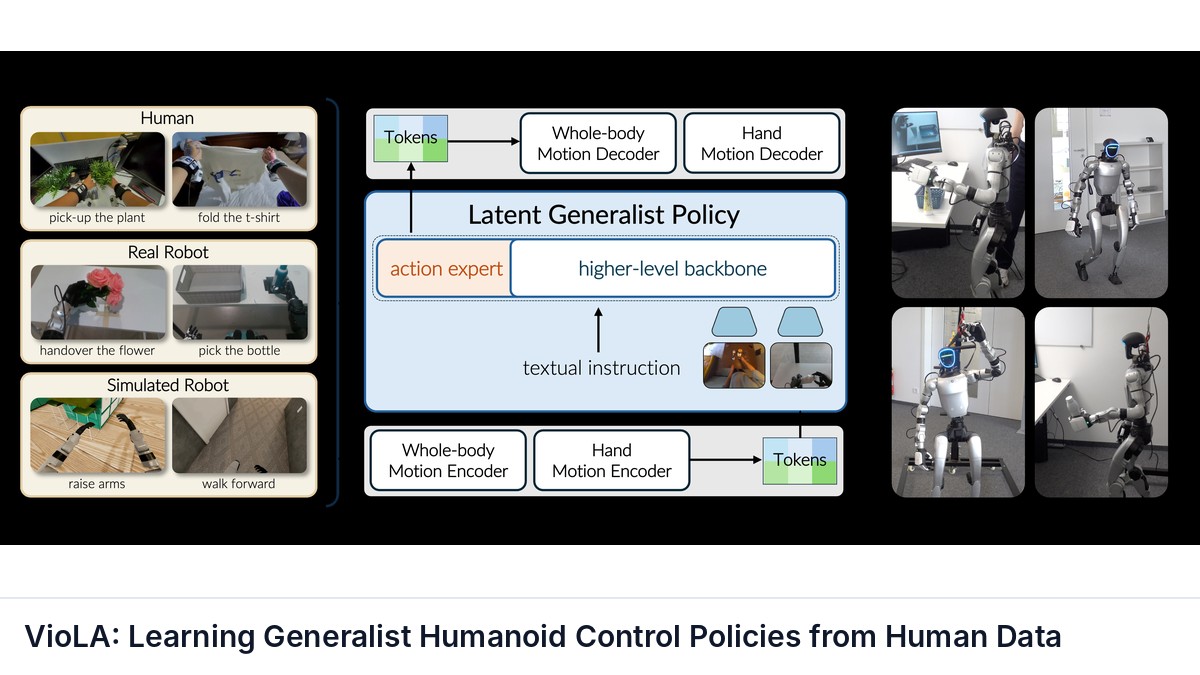
VioLA: Learning Generalist Humanoid Control Policies from Human Data
arXiv preprint

VioLA: Learning Generalist Humanoid Control Policies from Human Data

Mert Albaba, Jens Beißwenger, Anna Manasyan et al.

Teaching a humanoid to follow instructions with its whole body runs into two obstacles. Its action space is large and tightly coupled: legs, arms, and fingers must move together while the robot keeps its balance, which makes joint-level actions hard to learn.

manipulation locomotion vla reinforcement-learning control learning-from-demonstration
Code PDF Intermediate
GitHub ★ —
VLA-Corrector: Stage-Aware Observable State Understanding for Prompt-Based Closed-Loop Recovery of Vision-Language-Action Policies
arXiv preprint

VLA-Corrector: Stage-Aware Observable State Understanding for Prompt-Based Closed-Loop Recovery of Vision-Language-Action Policies

Chang Song, Bin Qian, Yan Feng et al.

Long-horizon robot manipulation with Vision-Language-Action (VLA) policies remains vulnerable to execution-time deviations, as final task success provides little information for diagnosing and correcting failures caused by action noise, object displacement, or goal misalignment.

manipulation vision vla reinforcement-learning benchmark
PDF Intermediate
Workhorse: Learning Robust Whole-Body Humanoid Loco-Manipulation from Human Data
ICRA (under review)

Workhorse: Learning Robust Whole-Body Humanoid Loco-Manipulation from Human Data

Hu, Songbo, Liao, Qiayuan, Chi, Yufeng et al.

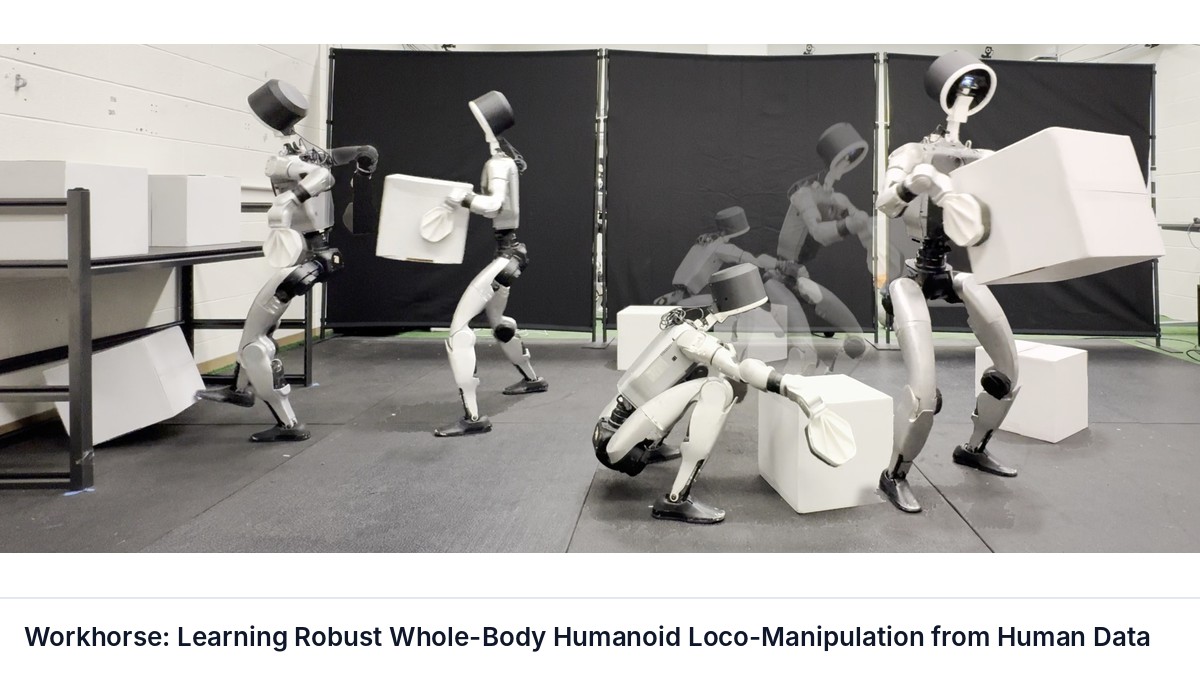
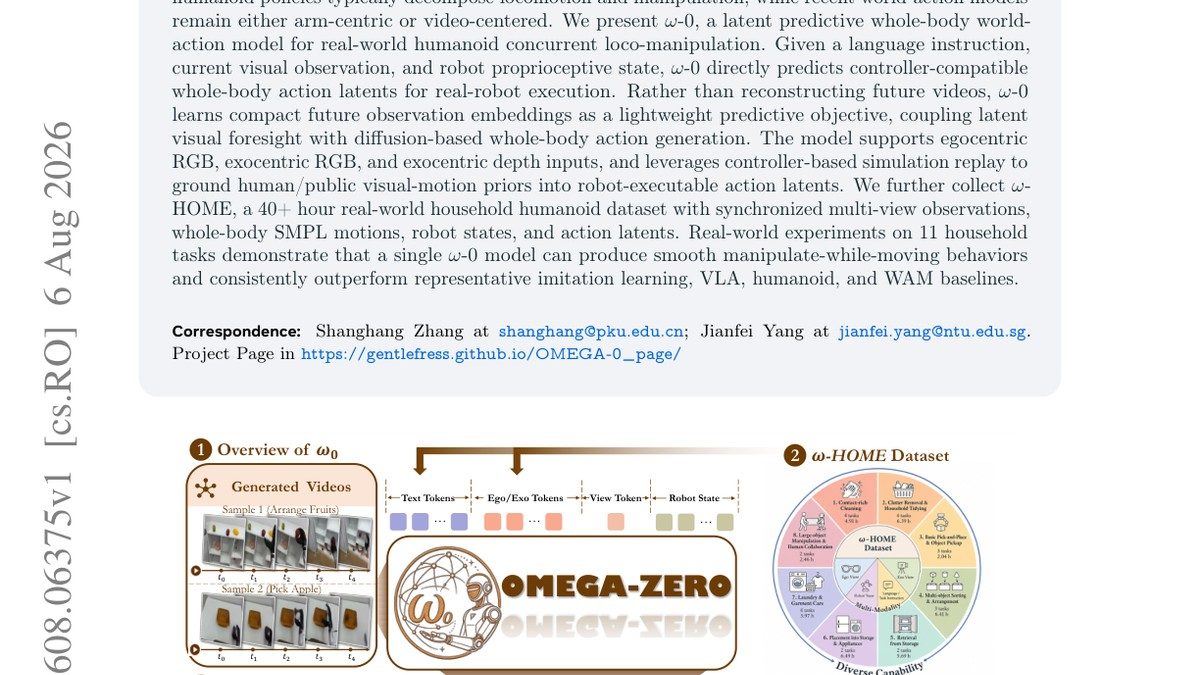
Humanoid robots still struggle to plan contact-rich whole-body manipulation from egocentric RGB and proprioception. Workhorse learns such manipulation from robot-free human demonstrations. A visual planner predicts five-link targets: the poses of the torso, both wrists, and both feet.

manipulation vision reinforcement-learning learning-from-demonstration
PDF Intermediate
GR00T N1: An Open Foundation Model for Generalist Humanoid Robots
arXiv preprint

GR00T N1: An Open Foundation Model for Generalist Humanoid Robots

NVIDIA, :, Johan Bjorck et al.

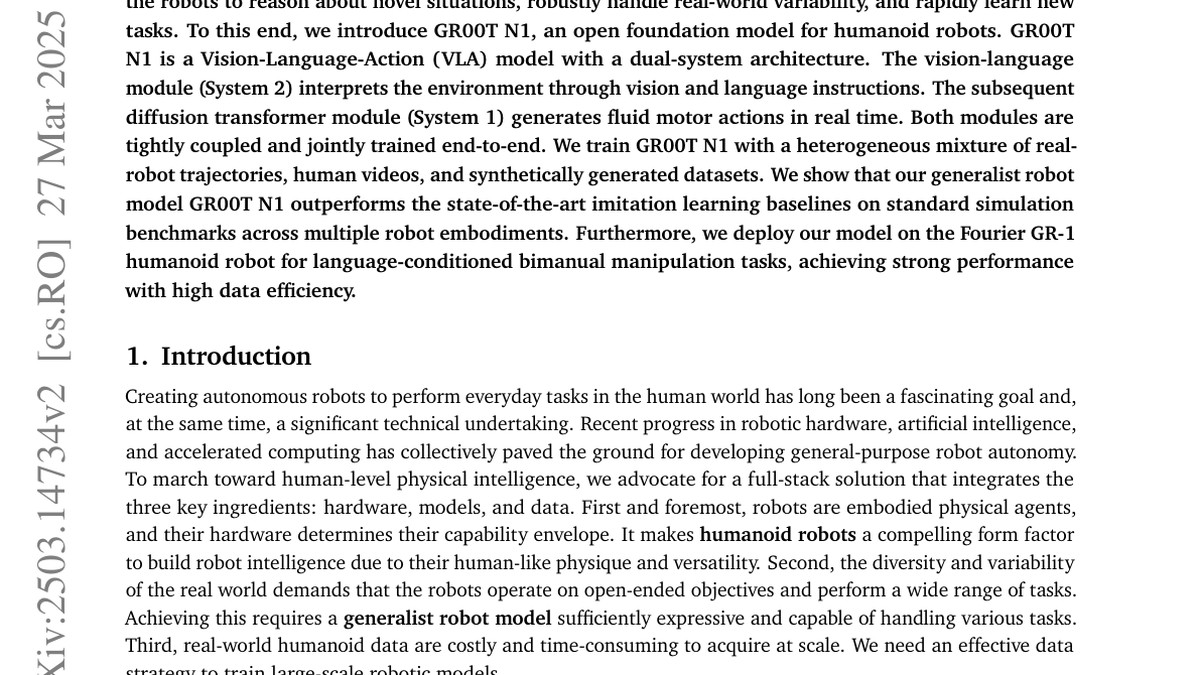
General-purpose robots need a versatile body and an intelligent mind. Recent advancements in humanoid robots have shown great promise as a hardware platform for building generalist autonomy in the human world.

manipulation vision vla reinforcement-learning control learning-from-demonstration benchmark
Code PDF Advanced
GitHub ★ —
WholeBodyVLA: Towards Unified Latent VLA for Whole-Body Loco-Manipulation Control
arXiv preprint

WholeBodyVLA: Towards Unified Latent VLA for Whole-Body Loco-Manipulation Control

Haoran Jiang, Jin Chen, Qingwen Bu et al.

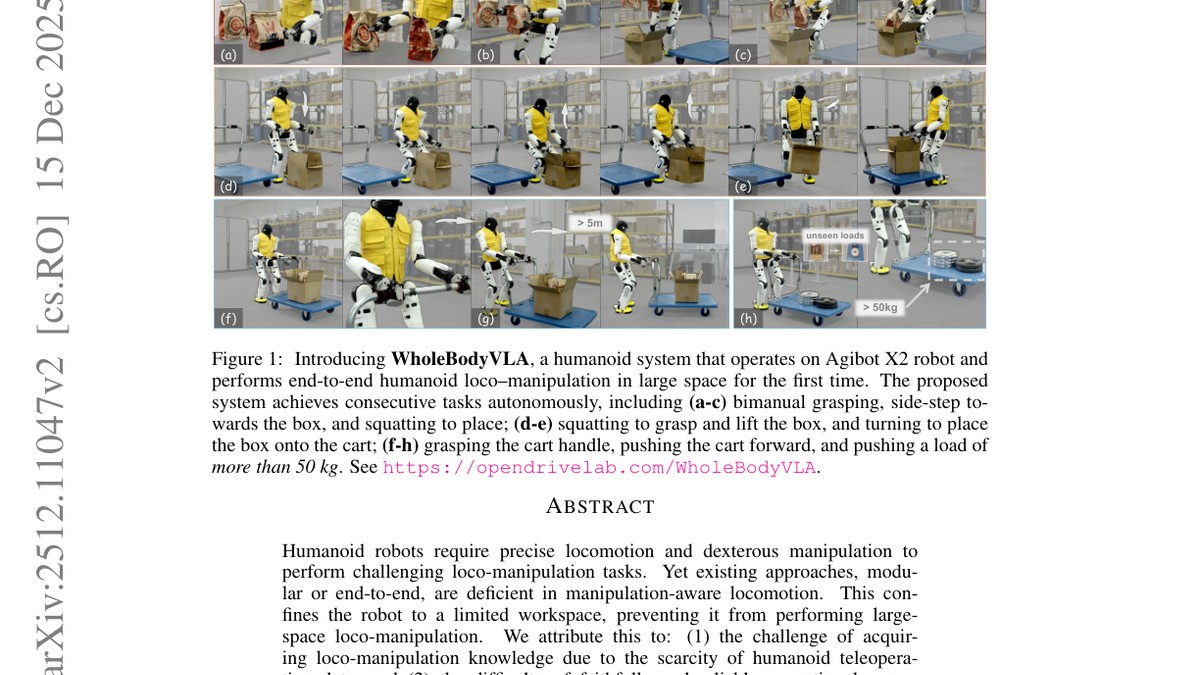
Humanoid robots require precise locomotion and dexterous manipulation to perform challenging loco-manipulation tasks. Yet existing approaches, modular or end-to-end, are deficient in manipulation-aware locomotion.

manipulation locomotion vision vla reinforcement-learning control learning-from-demonstration benchmark
Code PDF Advanced
GitHub ★ —
DROID: A Large-Scale In-the-Wild Robot Manipulation Dataset
RSS 2024

DROID: A Large-Scale In-the-Wild Robot Manipulation Dataset

Alexander Khazatsky, Karl Pertsch, Suraj Nair et al.

A 350-hour dataset of diverse real-world robot manipulation across 22 robots in 71 scenes, designed to train scalable and generalist imitation learning policies.

imitation-learning manipulation foundation-models
Code PDF Advanced
GitHub ★ 362 Updated May 2026
LeRobot: A Library for Real-World Robot Learning
NeurIPS 2024 Workshop

LeRobot: A Library for Real-World Robot Learning

Remi Cadene, Simon Alibert, Alexander Soare et al.

Hugging Face's LeRobot is an open-source PyTorch framework providing pretrained models, datasets, and training scripts for imitation and reinforcement learning on real robots, lowering the entry barrier to robot learning.

imitation-learning rl foundation-models manipulation
Code PDF Beginner
GitHub ★ 24,333 Updated May 2026
Octo: An Open-Source Generalist Robot Policy
RSS 2024

Octo: An Open-Source Generalist Robot Policy

Dibya Ghosh, Homer Walke, Karl Pertsch et al.

Octo is a large open-source transformer-based generalist robot policy trained on 800k trajectories, supporting language-conditioned and goal-image-conditioned control across 9 robotic platforms with efficient fine-tuning on consumer GPUs.

foundation-models manipulation imitation-learning open-source
Code PDF Intermediate
GitHub ★ 1,652 Updated May 2026
π0: A Vision-Language-Action Flow Model for General Robot Control
arXiv preprint

π0: A Vision-Language-Action Flow Model for General Robot Control

Karl Pertsch, Oliver Groth, Jonas Frey et al.

π0 is a 3.5B-parameter VLA flow model from Physical Intelligence that achieves state-of-the-art general robot manipulation by mixing online RL with high-quality human demonstrations, available as an open-source PyTorch implementation.

foundation-models vla manipulation il
Code PDF Advanced
GitHub ★ 11,990 Updated May 2026
OpenVLA: An Open-Source Vision-Language-Action Model
arXiv

OpenVLA: An Open-Source Vision-Language-Action Model

Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti et al.

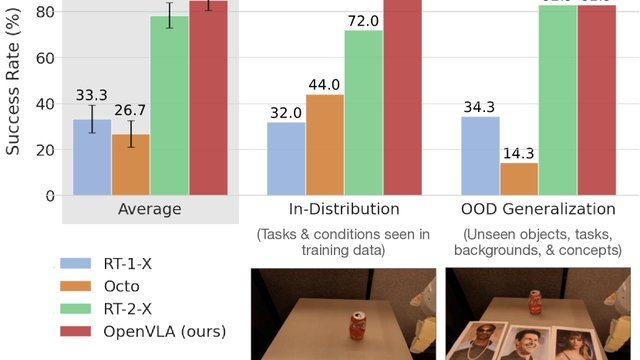
A 7B-parameter open-source Vision-Language-Action model pre-trained on 970k real-world robot demonstrations, achieving strong generalization across robots and tasks.

vla llm-robotics foundation-models manipulation
Code PDF Intermediate
GitHub ★ 6,260 Updated May 2026
RT-2: Vision-Language-Action Models That Generalize to Novel Tasks
ICRA 2024

RT-2: Vision-Language-Action Models That Generalize to Novel Tasks

Anthony Brohan, Noah Brown, Justice Carbajal et al.

Google DeepMind's VLA model combining a vision-language foundation model with robot action outputs, showing emergent generalization to novel objects, backgrounds, and semantic instructions far beyond training data.

llm-robotics foundation-models manipulation
Code Advanced
GitHub ★ 1,853 Updated May 2026
Diffusion Policy: Visuomotor Policy Learning via Action Diffusion
RSS 2023

Diffusion Policy: Visuomotor Policy Learning via Action Diffusion

Cheng Chi, Siyuan Feng, Yilun Du et al.

A behavior cloning approach that models robot policies as conditional diffusion processes, enabling multimodal action distributions and smooth action sequences.
imitation-learning diffusion-models manipulation behavior-cloning
Code PDF Intermediate
GitHub ★ 4,194 Updated May 2026
Stretch: A Small, Capable, and Affordable Mobile Manipulator
ICRA Workshop

Stretch: A Small, Capable, and Affordable Mobile Manipulator

Charlie C. Kemp, Bilsen D. Kim, Blake S. Kim et al.

A low-cost mobile manipulator designed for indoor home and office environments, with a large open-source ecosystem and teleoperation-based data collection.

manipulation uav imitation-learning
Code PDF Beginner
GitHub ★ 1,200 Updated Dec 2024
ManiSkill: A Unified Benchmark for Generalizable Manipulation Skills
ICLR 2023 (Oral)

ManiSkill: A Unified Benchmark for Generalizable Manipulation Skills

Jiayuan Gu, Sean Xiang, Stone Tao et al.

ManiSkill is a GPU-parallelized robotics simulation benchmark with 20+ manipulation tasks, PartNet-Mobility assets, and unified observation/action spaces, supporting RL, IL, and VLA training at millions of steps per hour.

sim-to-real rl manipulation foundation-models
Code PDF Beginner
GitHub ★ 2,914 Updated May 2026
Open X-Embodiment: Robotic Learning Datasets and RT-X Models
arXiv

Open X-Embodiment: Robotic Learning Datasets and RT-X Models

Open X-Embodiment Collaboration

The largest collaborative robot learning dataset ever assembled, spanning 22 robots from 21 institutions, enabling training of generalist RT-X policies that exhibit positive cross-embodiment transfer.

imitation-learning foundation-models manipulation dataset
Code PDF Intermediate
GitHub ★ 1,853 Updated May 2026
RT-1: Robotics Transformer for Real-World Control at Scale
RSS 2023

RT-1: Robotics Transformer for Real-World Control at Scale

Anthony Brohan, Yevgen Chebotar, Chelsea Finn et al.

RT-1 is a 35M-parameter transformer trained on 130K robot demonstrations that generalizes to new tasks, objects, and environments, forming the foundation for Google's RT-2 and RT-X line of VLA models.

foundation-models vla il manipulation
Code PDF Intermediate
GitHub ★ 1,723 Updated May 2026
CLIPort: What and Where Pathways for Robotic Manipulation
CoRL 2021

CLIPort: What and Where Pathways for Robotic Manipulation

Mohit Shridhar, Lucas Manuelli, Dieter Fox

CLIPort fuses CLIP's semantic understanding with Transporter Networks' spatial precision to perform language-conditioned manipulation tasks like 'stack the red block on the blue block' with 2D pick-and-place affordances.

foundation-models manipulation il
Code PDF Beginner
GitHub ★ 546 Updated May 2026

Suggested Learning Path

Read these papers in order to build expertise in Manipulation.

  1. 1
  2. 2
  3. 3
  4. 4
  5. 5
  6. 6

…and 236 more papers.