

Pose6DAug: Physically Plausible Multi-view Object Swapping for Robot Data Augmentation
Jonghoon Lee, Seong Hyeon Park, Byungwoo Jeon, Minha Lee, Jinwoo Shin · · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Vision-language-action (VLA) policies have shown strong potential for general-purpose manipulation, yet they often fail on novel, out-of-distribution objects whose appearance or geometry deviates from the training distribution.
Abstract Summary
Key Points
- Proposes Pose6DAug for robotics.
- Evaluated on real or simulated robotic tasks.
- Primary contribution in ar-vr.
Method
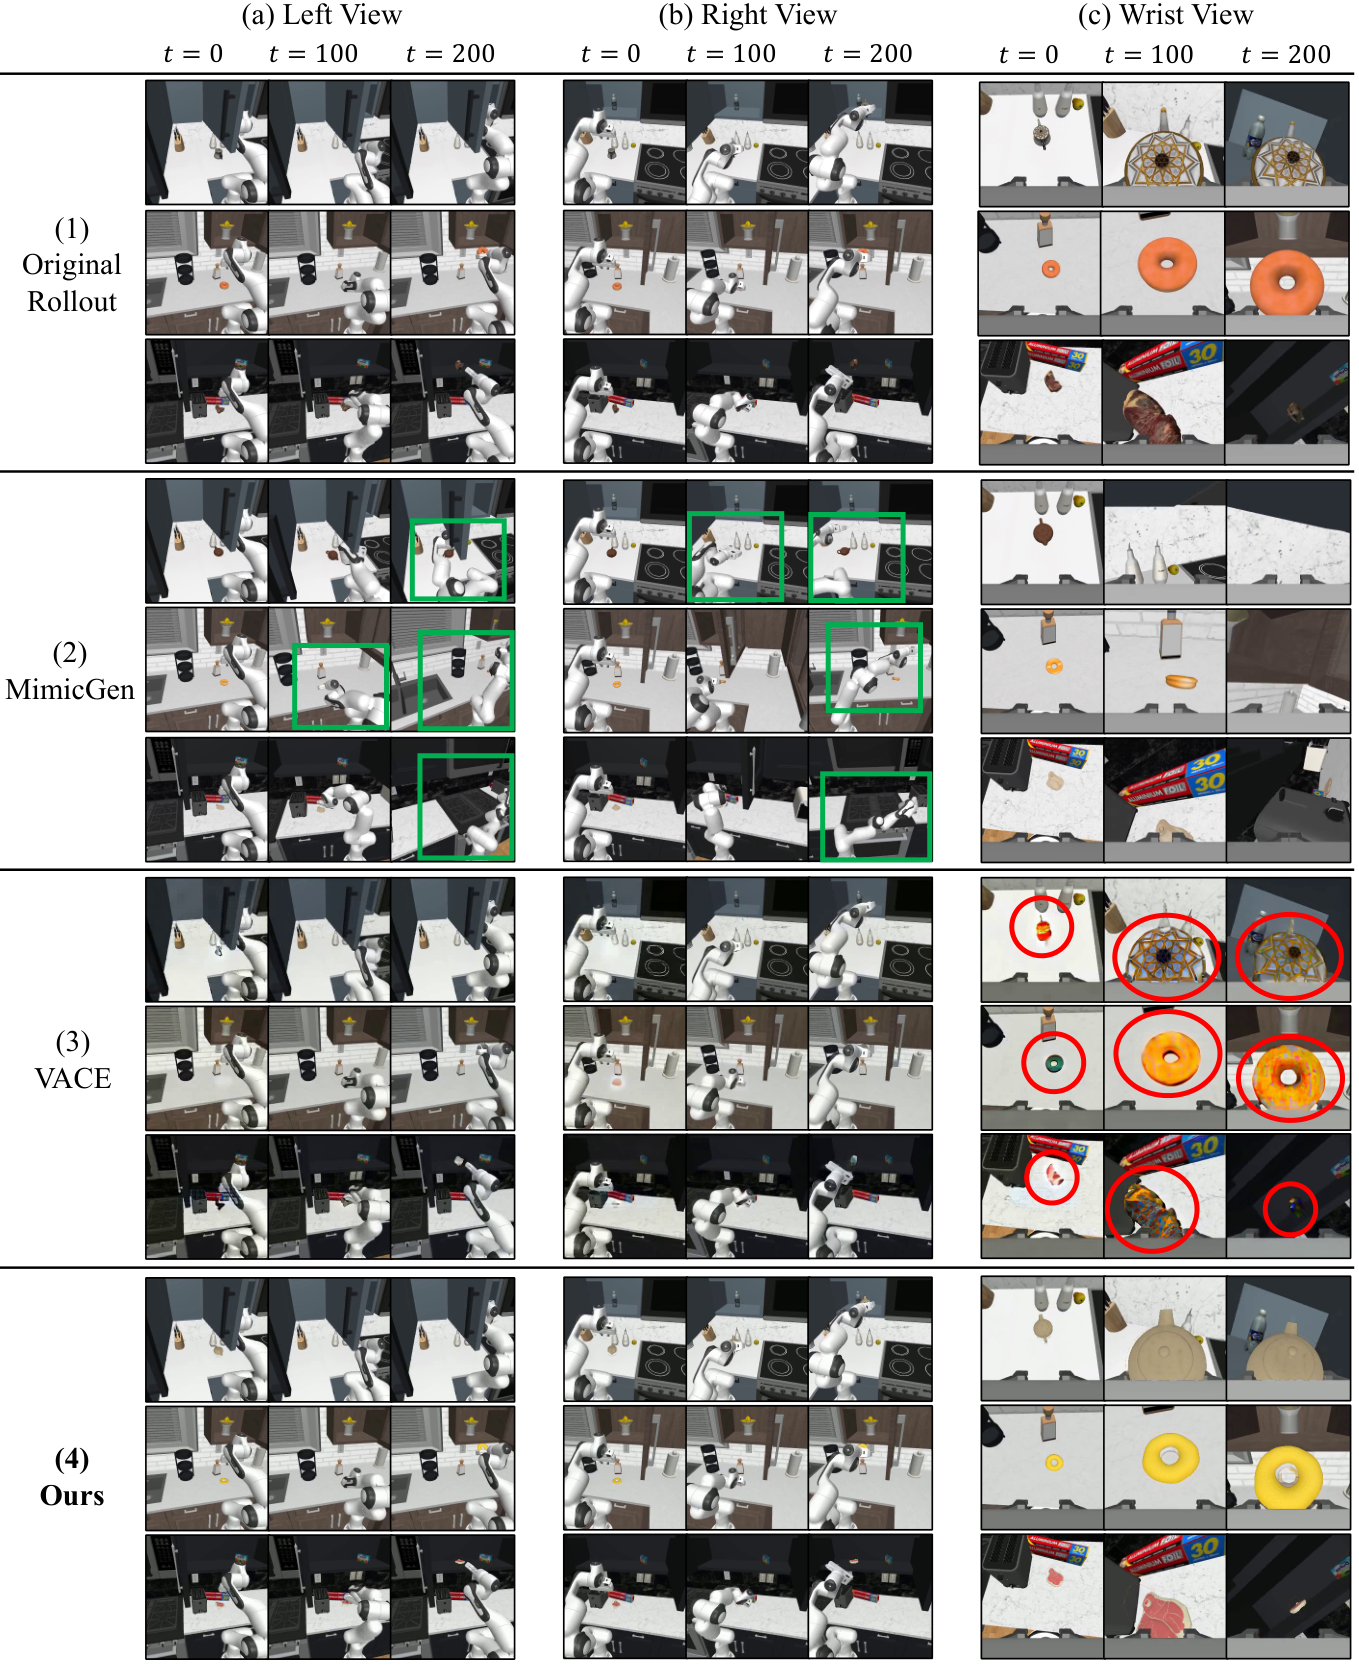
Given a successful manipulation episode with a source object, our goal is to replace the source object with a target object across all camera views while preserving the physical plausibility of the recorded trajectory. Rather than applying view-independent generative editing, which struggles with multi-view consistency and out-of-distribution egocentric views, we operate directly in 3D.
Experiments
To evaluate the effectiveness of our augmentation pipeline, we test whether Pose6DAug can improve a state-of-the-art robot foundation model on a realistic household manipulation task. Our experiments are designed to answer two questions: (1) Does augmented training data improve overall task success when combined with the original dataset?
(2) Does augmentation specifically recover performance on object instances that the base policy consistently fails on? We conduct experiments on RoboCasa365 [ 22 ] , a large-scale simulation benchmark for hous...
Sources and Demonstrations
Figures are reproduced from Lee et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
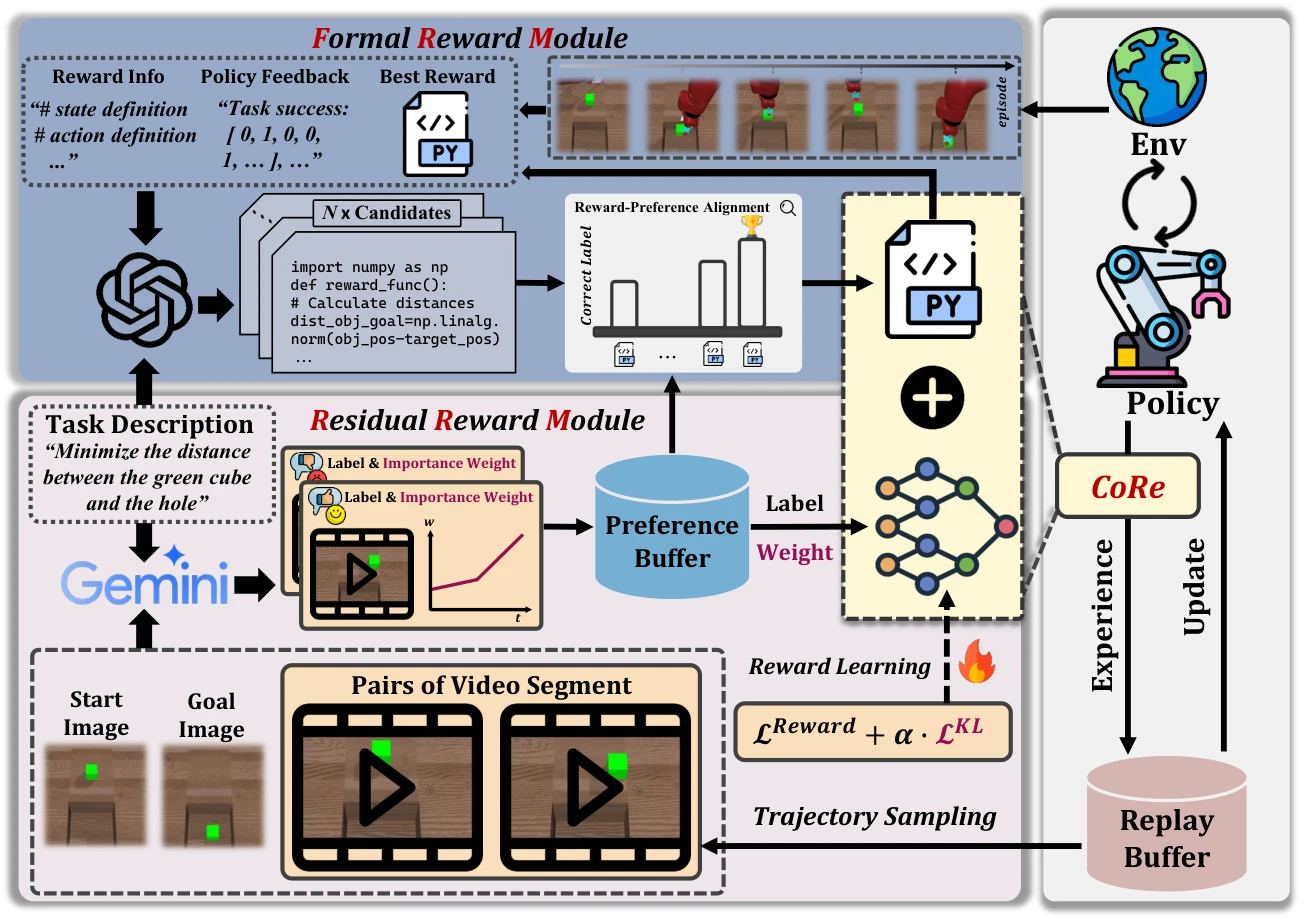
CoRe: Combined Rewards with Vision-Language Model Feedback for Preference-Aligned Reinforcement Learning
Hexian Ni, Tao Lu, Yinghao Cai
CoRe combines code-based rewards with learned visual preferences so that neither reward source has to capture the entire task alone.
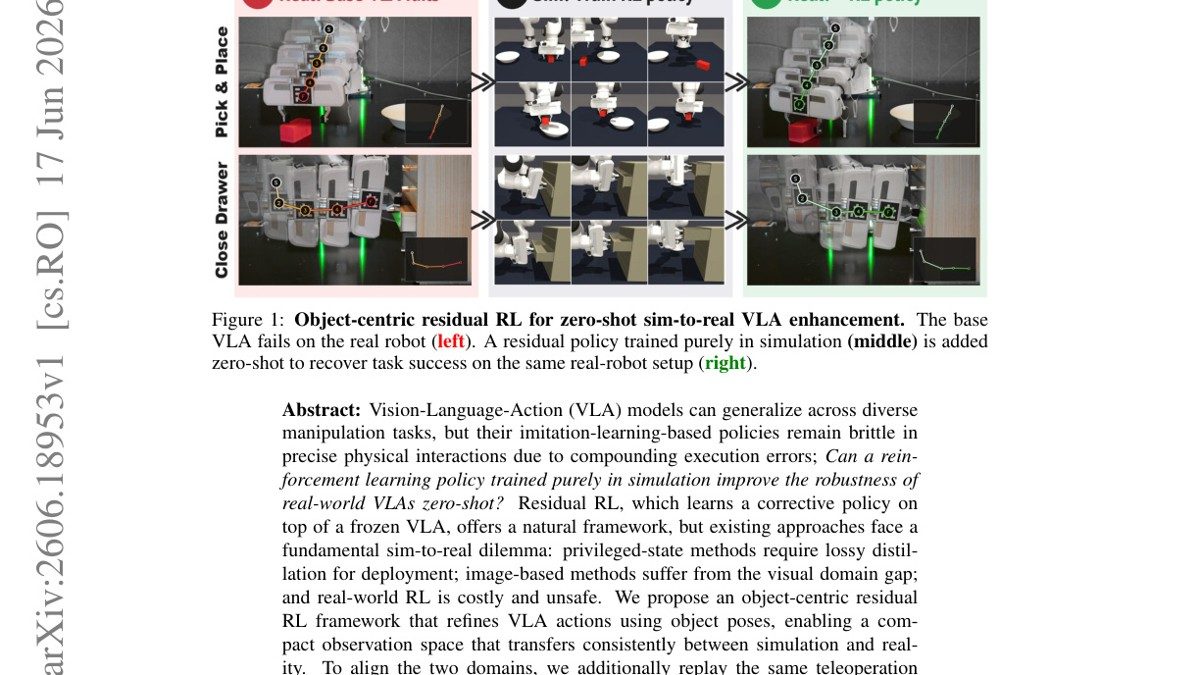
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
Kinam Kim, Namiko Saito, Heecheol Kim et al.
Vision-Language-Action (VLA) models can generalize across diverse manipulation tasks, but their imitation-learning-based policies remain brittle in precise physical interactions due to compounding execution errors; Can a reinforcement learning policy trained purely in simulation improve the robustness of real-world VLAs zero-shot?
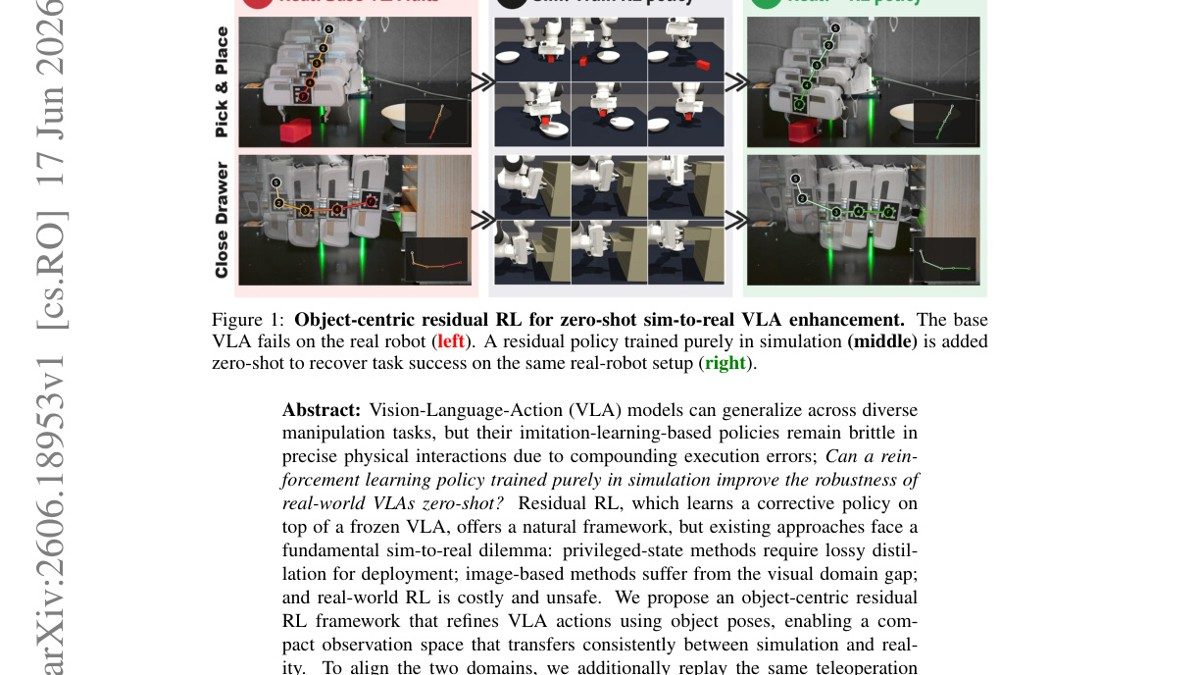
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
Kinam Kim, Namiko Saito, Heecheol Kim et al.
Vision-Language-Action (VLA) models can generalize across diverse manipulation tasks, but their imitation-learning-based policies remain brittle in precise physical interactions due to compounding execution errors; Can a reinforcement learning policy trained purely in simulation improve the robustness of real-world VLAs zero-shot?
Pose6DAug: Physically Plausible Multi-view Object Swapping for Robot Data Augmentation
Jonghoon Lee, Seong Hyeon Park, Byungwoo Jeon et al.
Vision-language-action (VLA) policies have shown strong potential for general-purpose manipulation, yet they often fail on novel, out-of-distribution objects whose appearance or geometry deviates from the training distribution.