Papers

Sorted by year (newest first)
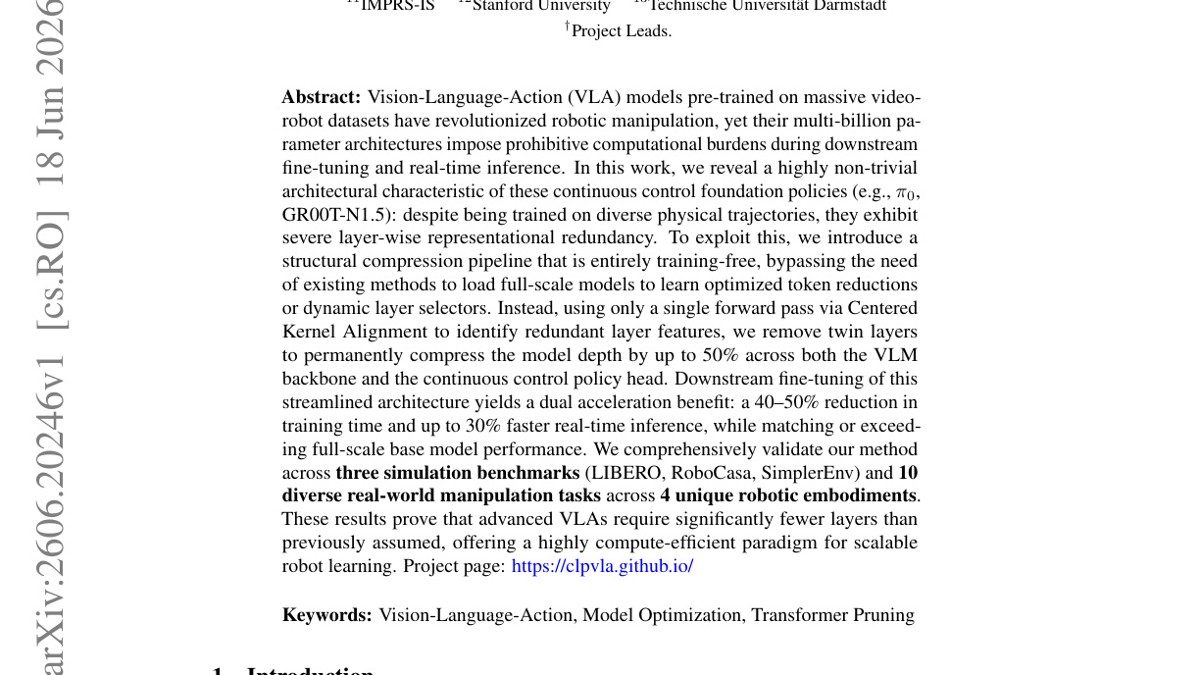
Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think
arXiv preprint

Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think

Gia-Binh Nguyen, Trong-Bao Ho, Thien-Loc Ha et al.

Vision-Language-Action (VLA) models pre-trained on massive video-robot datasets have revolutionized robotic manipulation, yet their multi-billion parameter architectures impose prohibitive computational burdens during downstream fine-tuning and real-time inference.

ar-vr evaluation manipulation
PDF Intermediate
Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think
arXiv preprint

Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think

Gia-Binh Nguyen, Trong-Bao Ho, Thien-Loc Ha et al.

Vision-Language-Action (VLA) models pre-trained on massive video-robot datasets have revolutionized robotic manipulation, yet their multi-billion parameter architectures impose prohibitive computational burdens during downstream fine-tuning and real-time inference.

ar-vr evaluation manipulation
PDF Intermediate
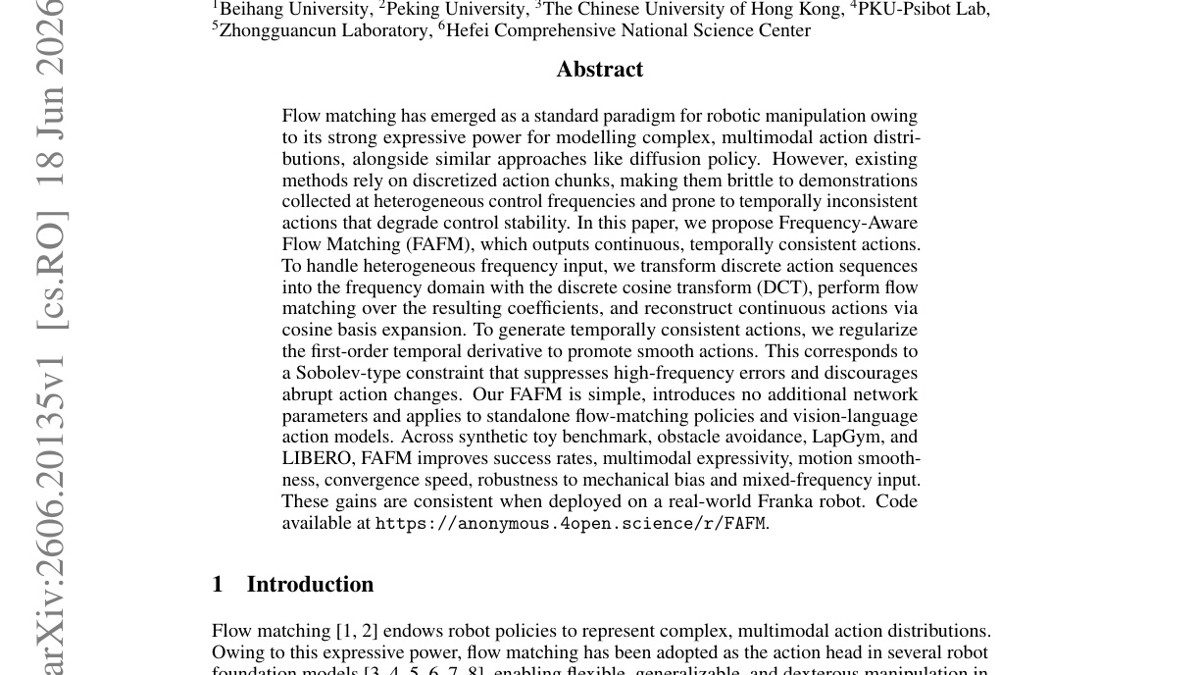
Invertible Neural Network Adapter for One-Step Flow Matching in Robot Manipulation
arXiv preprint

Invertible Neural Network Adapter for One-Step Flow Matching in Robot Manipulation

Yu Zhang, Kangyi Ji, Yongxiang Zou et al.

This paper presents an invertible neural network adapter for general robotic manipulation, designed to generate precise high-dimensional actions conditioned on multimodal observations, including visual, linguistic, and proprioceptive inputs, through a one-step denoising process.

ar-vr evaluation generation
PDF Intermediate
Invertible Neural Network Adapter for One-Step Flow Matching in Robot Manipulation
arXiv preprint

Invertible Neural Network Adapter for One-Step Flow Matching in Robot Manipulation

Yu Zhang, Kangyi Ji, Yongxiang Zou et al.

This paper presents an invertible neural network adapter for general robotic manipulation, designed to generate precise high-dimensional actions conditioned on multimodal observations, including visual, linguistic, and proprioceptive inputs, through a one-step denoising process.

ar-vr evaluation generation
PDF Intermediate
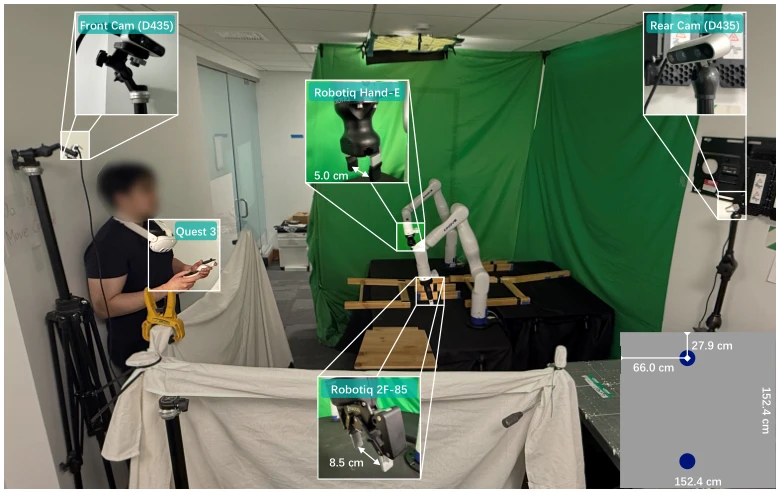
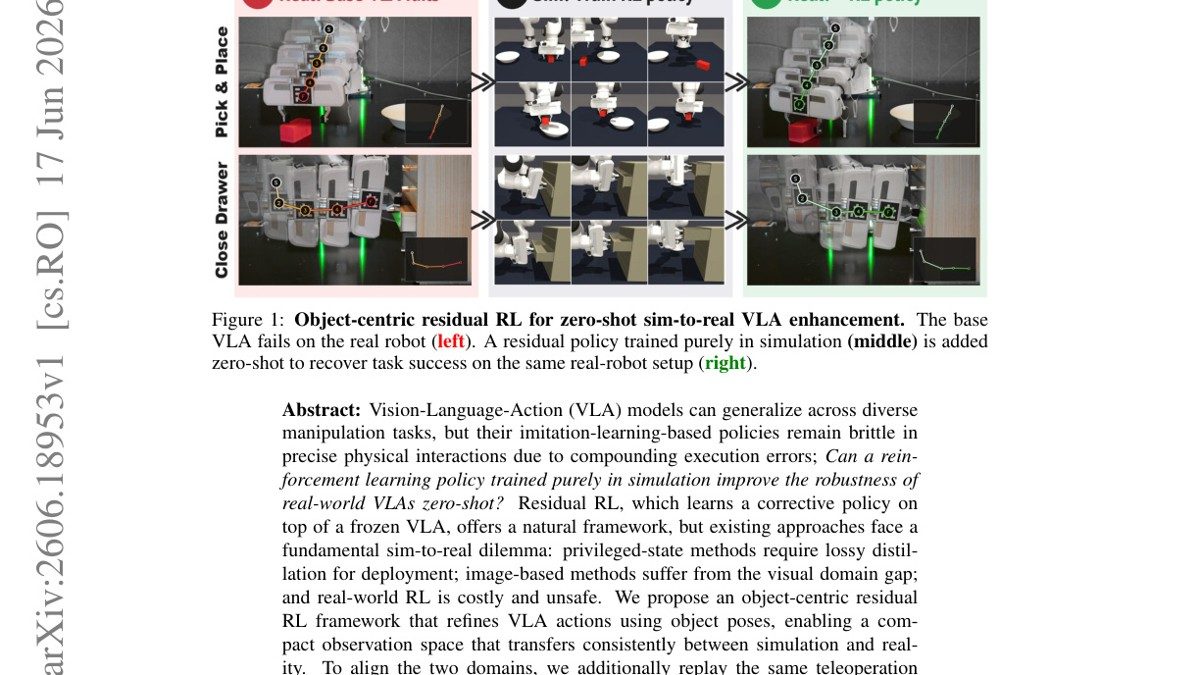
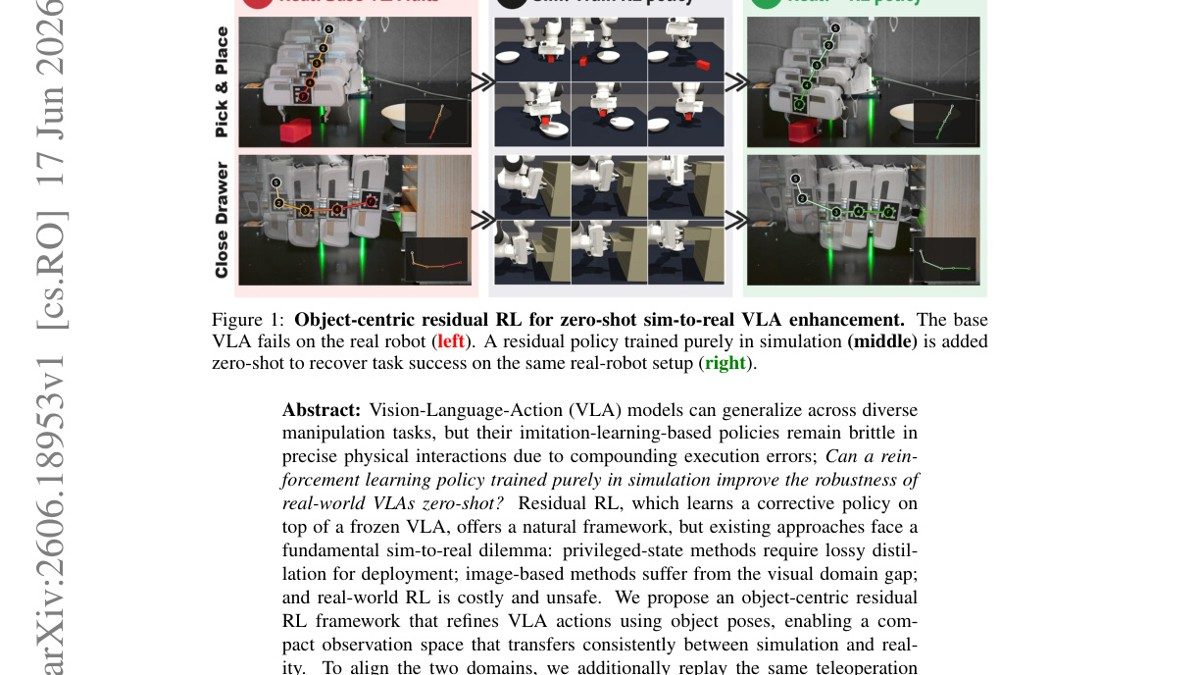
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
arXiv preprint

Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement

Kinam Kim, Namiko Saito, Heecheol Kim et al.

Vision-Language-Action (VLA) models can generalize across diverse manipulation tasks, but their imitation-learning-based policies remain brittle in precise physical interactions due to compounding execution errors; Can a reinforcement learning policy trained purely in simulation improve the robustness of real-world VLAs zero-shot?

ar-vr manipulation rl
PDF Intermediate
Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement
arXiv preprint

Object-Centric Residual RL for Zero-Shot Sim-to-Real VLA Enhancement

Kinam Kim, Namiko Saito, Heecheol Kim et al.

Vision-Language-Action (VLA) models can generalize across diverse manipulation tasks, but their imitation-learning-based policies remain brittle in precise physical interactions due to compounding execution errors; Can a reinforcement learning policy trained purely in simulation improve the robustness of real-world VLAs zero-shot?

ar-vr manipulation rl
PDF Intermediate
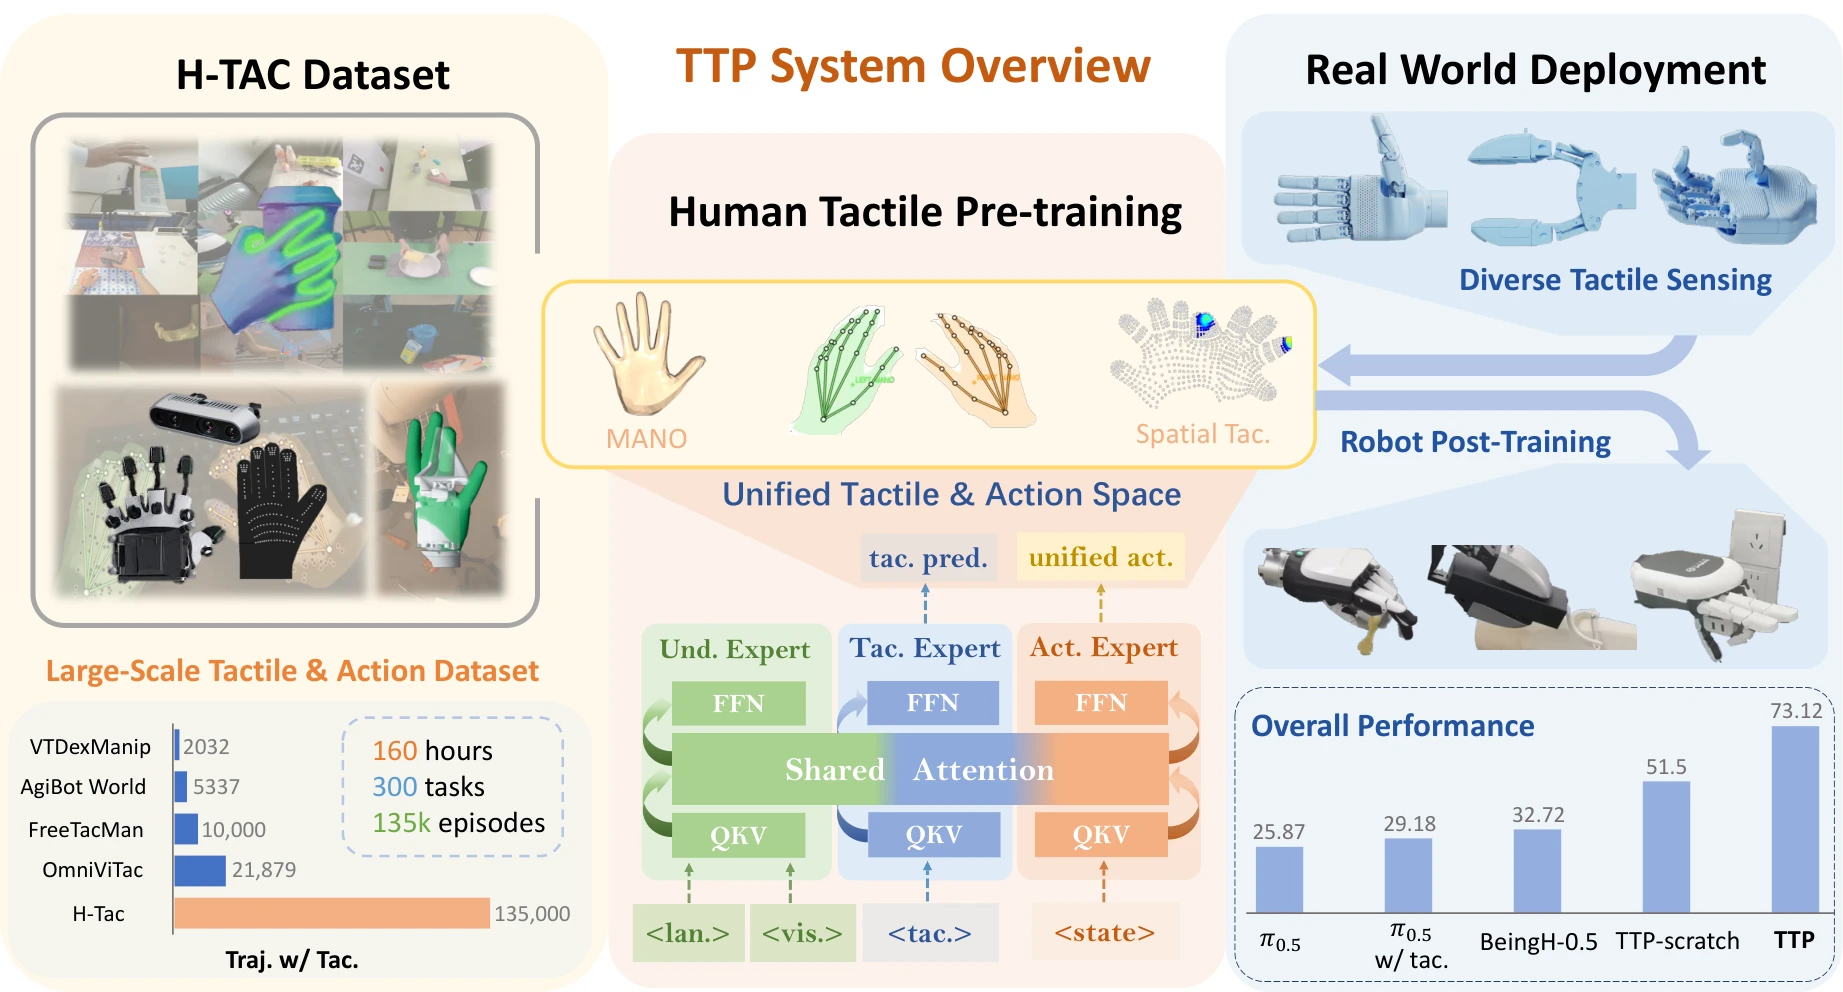
WorldSample: Closed-loop Real-robot RL with World Modelling
arXiv preprint

WorldSample: Closed-loop Real-robot RL with World Modelling

Yuquan Xue, Le Xu, Zeyi Liu et al.

Reinforcement learning (RL) can overcome the demonstration-coverage limitation of imitation learning (IL) by allowing robots to improve through trial-and-error interaction beyond the states observed in demonstrations.

ar-vr generation imitation-learning
PDF Intermediate

Suggested Learning Path

Read these papers in order to build expertise in ar-vr.

  1. 1
    Actuator Reality Shaping for Zero-Shot Sim-to-Real Robot Learning

    Satoshi Yamamori, Koji Ishihara et al. · 2026

  2. 2
  3. 3
  4. 4
  5. 5
  6. 6

…and 18 more papers.