
At a glance
- Problem: actuator mismatch can break a policy trained in simulation. Source
- Idea: combine feedforward response shaping, feedback and disturbance rejection at each joint. Source
- Evidence: measured tracking tests plus zero-shot demonstrations on additional robot platforms. Source
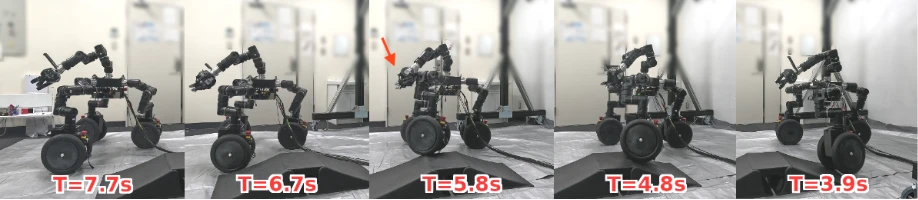
Evaluation scope Single-servo and seven-joint arm experiments provide quantitative evidence; wheeled-legged and humanoid demonstrations illustrate transfer. Source
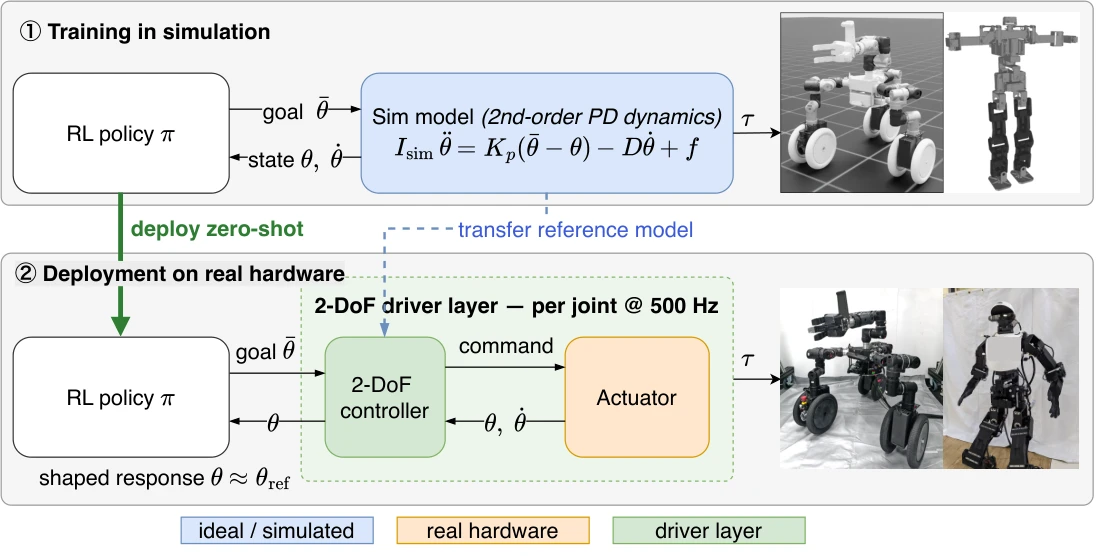
How it works
Evidence & results
- Across five reaching trials, the authors report 96.5% lower end-effector deviation than the factory PID cascade and 72% lower than tuned Simple PD. Evidence
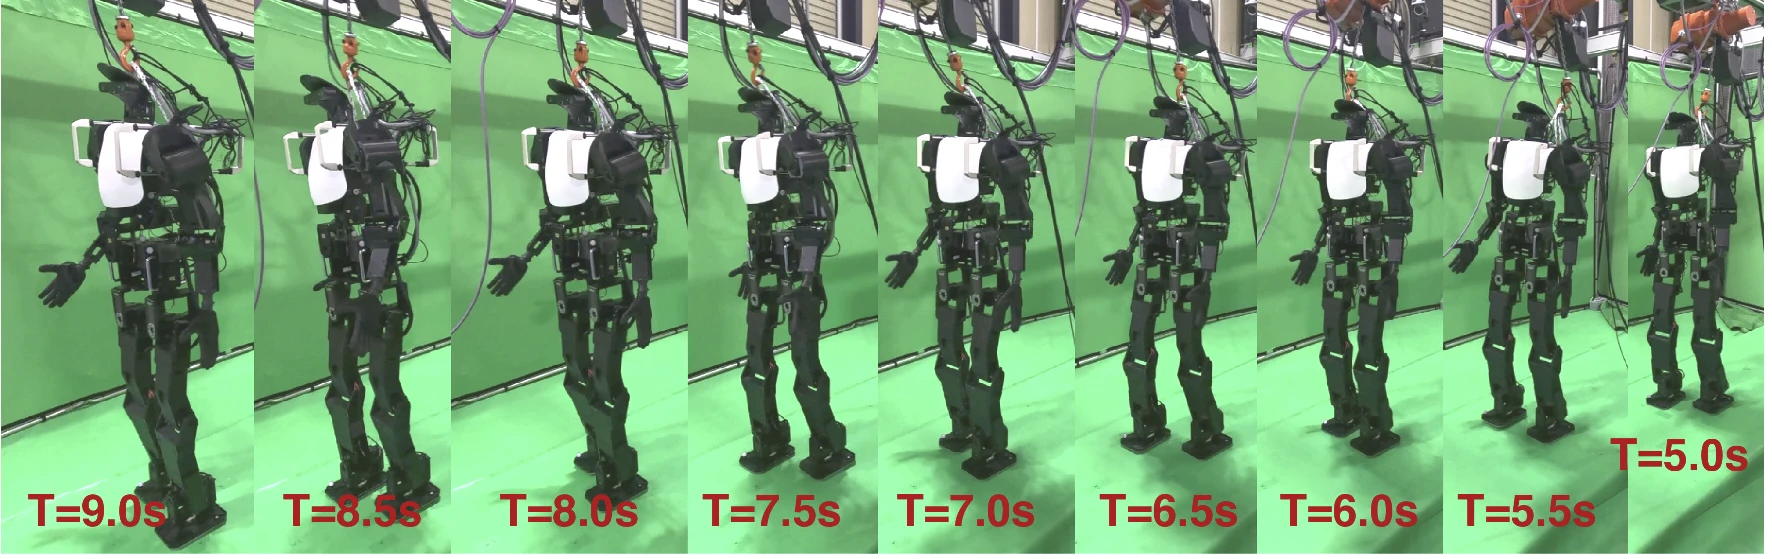
- The humanoid demonstration transfers a walking policy using a different servo; this is not a broad locomotion benchmark. Evidence
Limitations & boundaries
Takeaway
Standardizing the actuator interface is a promising transfer strategy, but its hardware assumptions still need checking. Source
Resources
Figures: the paper's authors. Editorial source and image review: 2026-10-21. Findings are author-reported, not independently reproduced by Robotics Research Hub.
Original abstract
Sim-to-real transfer in robot learning is often limited by discrepancies between the ideal actuator dynamics assumed during policy training and the nonlinear, hardware-dependent behavior of physical motors. While conventional approaches attempt to bridge this gap by increasing simulator fidelity through system identification, domain randomization, or learned actuator models, we introduce an alternative paradigm: actuator reality shaping. Instead of modifying the simulator to match the real world, our method shapes the closed-loop behavior of physical actuators to match the idealized second-order reference dynamics used in simulation. By equipping each joint with a two-degree-of-freedom feedforward--feedback controller, we decouple reference-response shaping from robust stabilization, thereby providing a standardized actuator interface for reinforcement learning policies. As a result, policies trained only with the prescribed reference model can be deployed zero-shot on real hardware without task-level fine-tuning or learned actuator models. We validate the approach on a single-joint high-gear-ratio servo under external loads and a 7-DOF robotic arm reaching task, where actuator reality shaping substantially reduces sim-to-real tracking error and improves zero-shot task performance compared with standard servo-control and representative real-to-sim-to-real baselines. We further demonstrate zero-shot transfer on a wheeled-legged robot driving over a slope and a humanoid robot walking, suggesting that actuator reality shaping can serve as a reusable interface for robot learning across diverse hardware platforms.