
GuideWalk: Learning Unified Autonomous Navigation and Locomotion for Humanoid Robots across Versatile Terrains
Haoxuan Han, Chen Chen, Linao Gong, Xin Yang, Hao Hu, Junhong Guo, Zhicheng He, Yao Su, Fenghua He · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
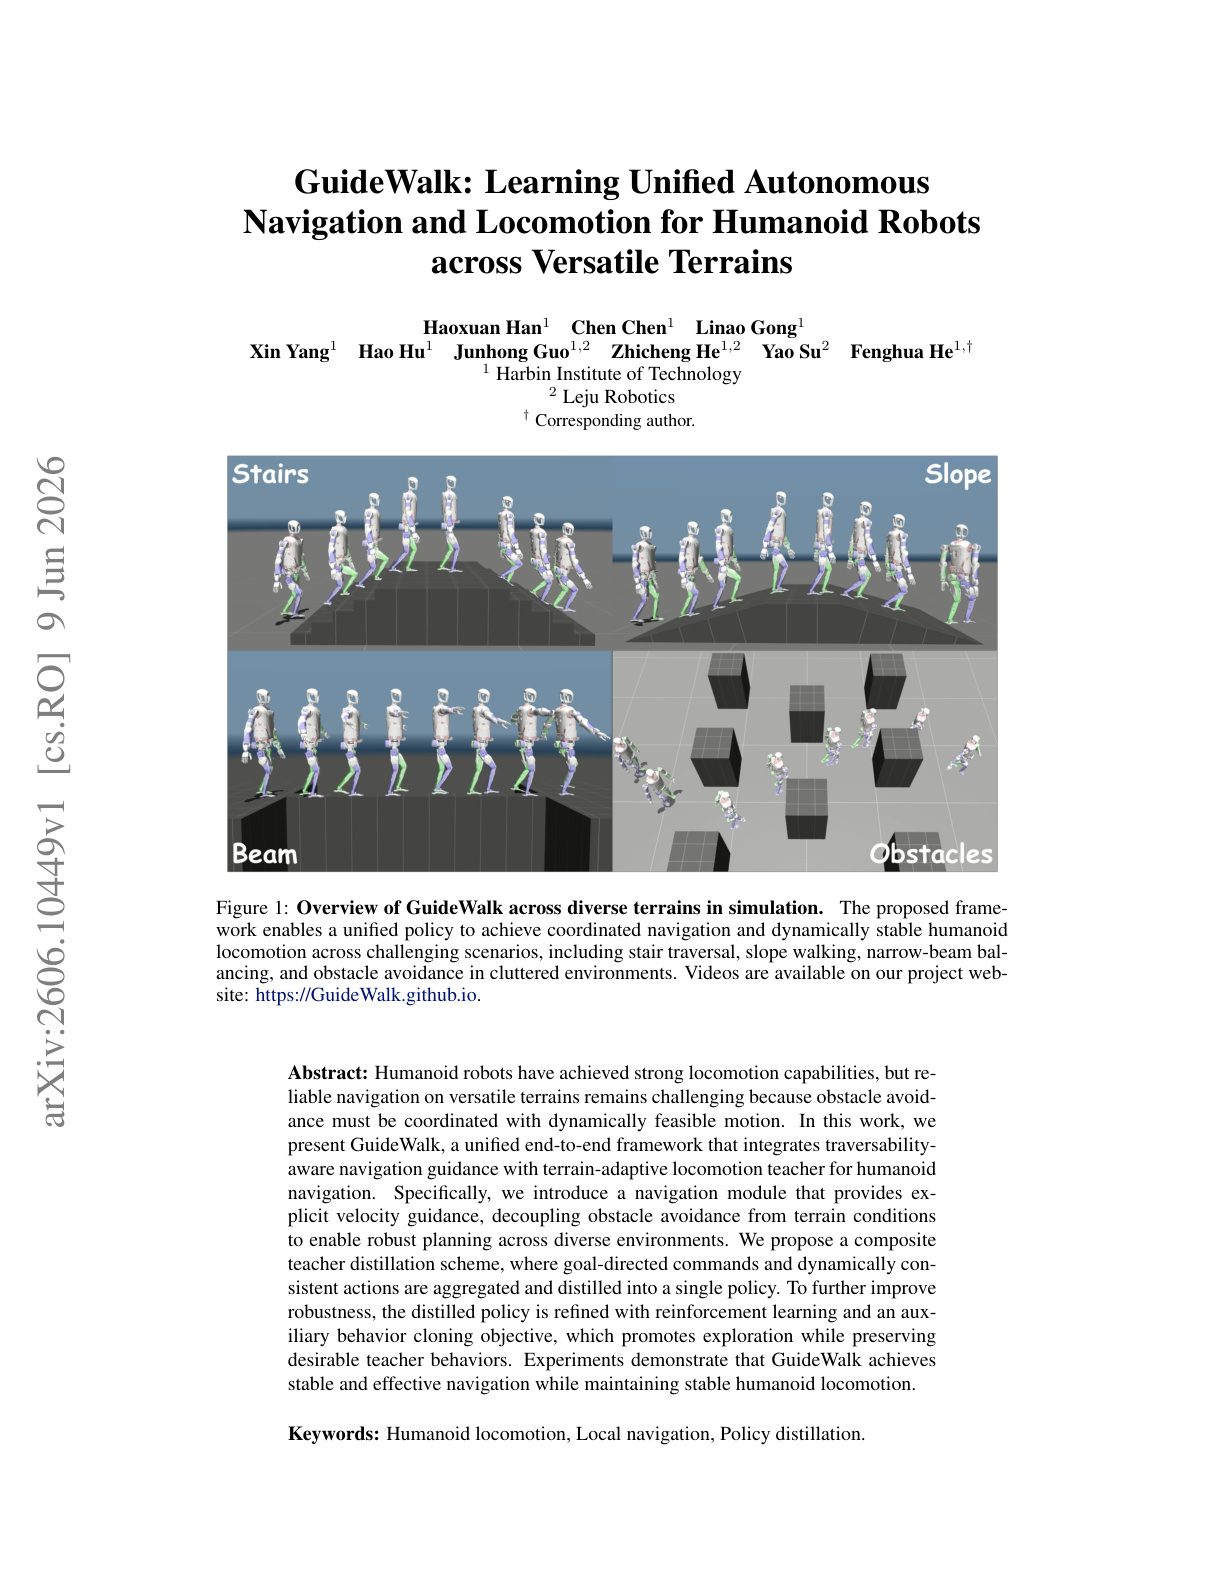
Humanoid robots have achieved strong locomotion capabilities, but reliable navigation on versatile terrains remains challenging because obstacle avoidance must be coordinated with dynamically feasible motion.
Abstract Summary
Key Points
- Proposes a unified end-to-end framework combining traversability-aware navigation with terrain-adaptive locomotion.
- Introduces velocity guidance that decouples obstacle avoidance from terrain conditions.
- Uses composite teacher distillation followed by RL refinement and behavior cloning for robust policy learning.
- Demonstrates stable navigation across versatile terrains on humanoid robots.
Methodology
The proposed framework combines guidance from a composite teacher with policy optimization via rl , enabling the student to efficiently acquire coordinated navigation and locomotion behaviors while improving robustness and performance. As illustrated in Fig. 1 , this is achieved through a two-stage training pipeline featuring a composite teacher and a unified student policy.
Experiments
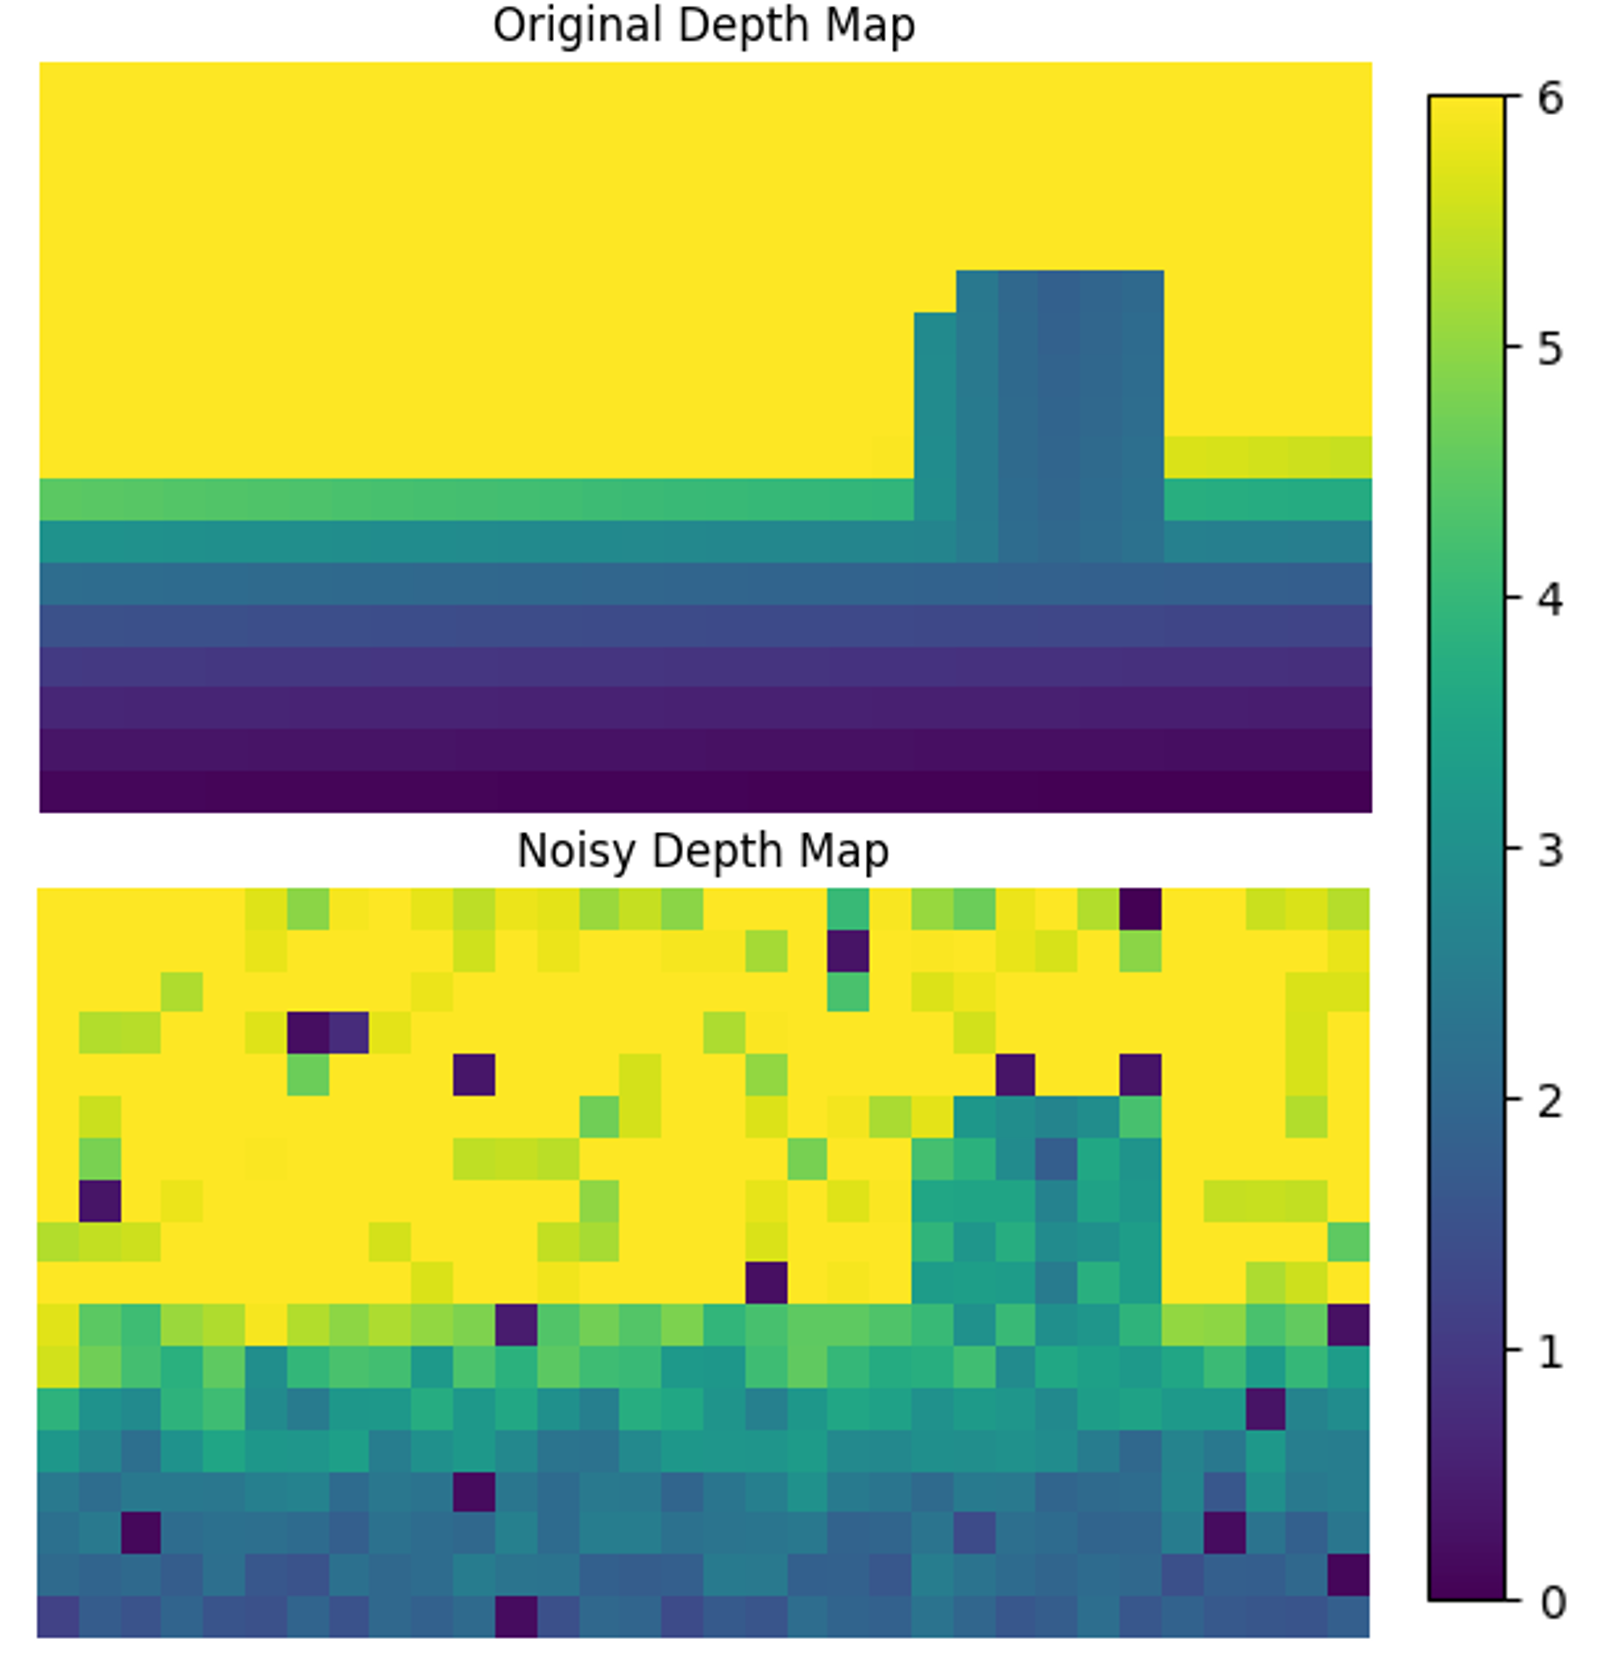
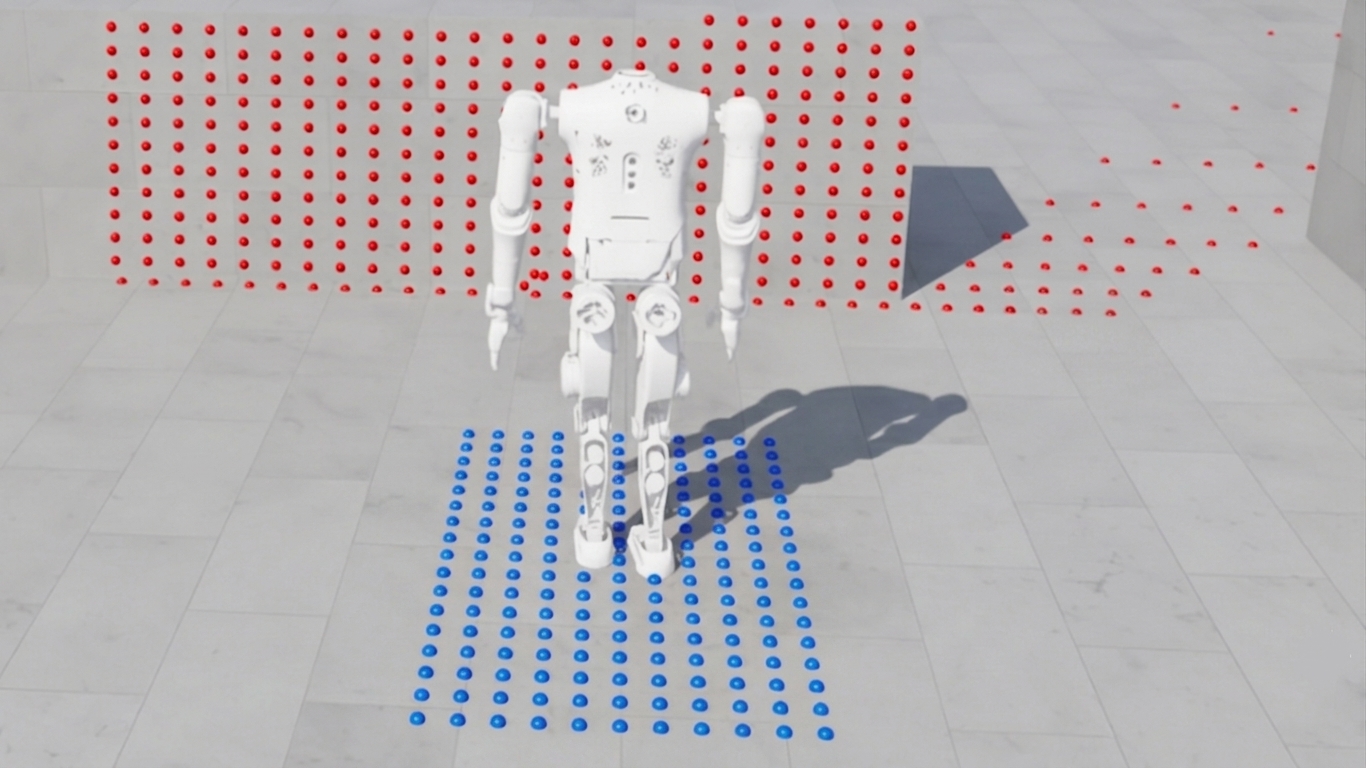
We train our policy in the Isaac Sim simulation platform on a single NVIDIA RTX 5080 GPU with 16 GB of memory using 2048 parallel environments. Across the two student training stages, the policy is trained for 10,000 iterations, with a total training cost of 37.7 GPU hours, including the training of the privileged locomotion teacher. The training environments, shown in Fig.
Sources and Demonstrations
Figures are reproduced from Han et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
Accelerating and Scaling MPC-Guided Reinforcement Learning for Humanoid Locomotion and Manipulation
Junheng Li, Liang Wu, Sergio A. Esteban et al.
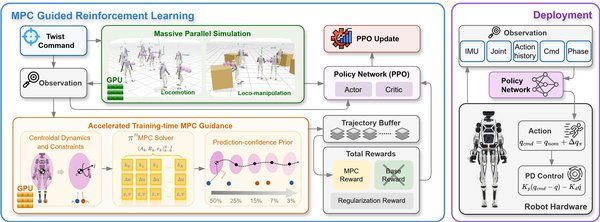
In humanoid motion control, model predictive control (MPC) offers physically grounded prediction and constraint handling, while reinforcement learning (RL) enables robust whole-body skills through large-scale simulation. However, using MPC inside RL often requires time-consuming problem construction or excessive training overhead, making such frameworks difficult to justify in practice. This work studies efficient training-time MPC guidance for humanoid locomotion and manipulation, termed MPC-RL. We introduce a centroidal-dynamics MPC reward formulation that leverages guidance from MPC trajectories in training time. To make this practical in massively parallel RL, we develop π^nMPC, a parallel-in-horizon and construction-free batched GPU MPC solver that operates directly on time-varying dynamics to avoid high memory usage and pre-compilation. Through a variety of comparative studies and hardware validations, we have found that MPC-RL achieves superior performance in locomotion and manipulation skills.
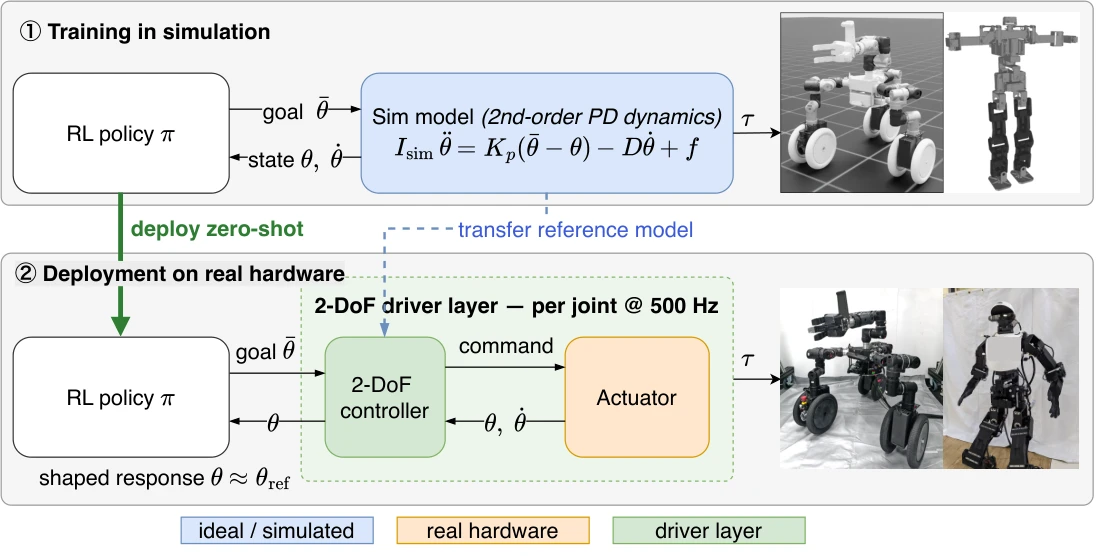
Actuator Reality Shaping for Zero-Shot Sim-to-Real Robot Learning
Satoshi Yamamori, Koji Ishihara, Kentaro Minamikawa et al.
Instead of making simulation imitate every motor imperfection, this work shapes the physical actuator to follow the simulated reference.
M3imic: Learning a Versatile Whole-Body Controller for Multimodal Motion Mimicking
Zuxing Lu, Ziang Zheng, Yao Lyu et al.
Building a general-purpose whole-body controller is essential for enabling diverse motion capabilities in humanoid robots across a wide range of downstream tasks, including locomotion and loco-manipulation.
Stubborn: A Streamlined and Unified Reinforcement Learning Framework for Robust Motion Tracking and Fall Recovery for Humanoids
Xiao Ren, Yuhui Yang, Zongbiao Weng et al.
Recent reinforcement learning approaches have shown great promise in improving humanoid motion tracking performance and achieving fall recovery under disturbances.