arXiv preprint
Co-VLA: Coordination-Aware Structured Action Modeling for Dual-Arm Vision-Language-Action Systems
Yandong Wang, Jiaqian Yu, Xiongfeng Peng et al.
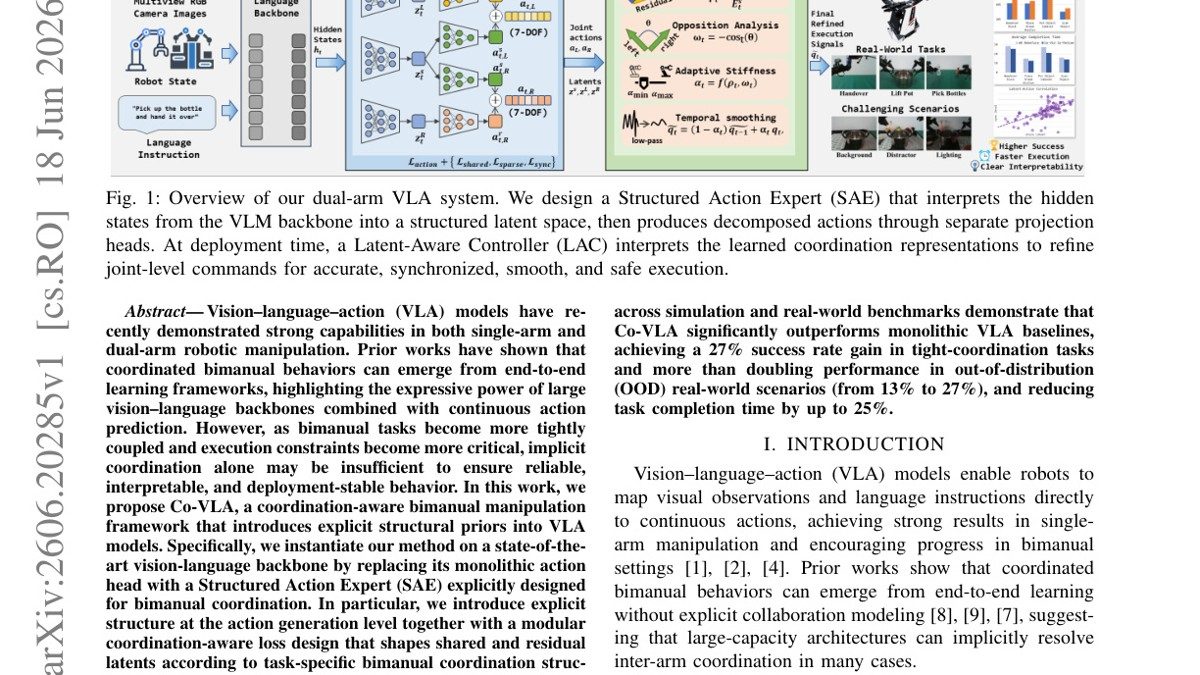
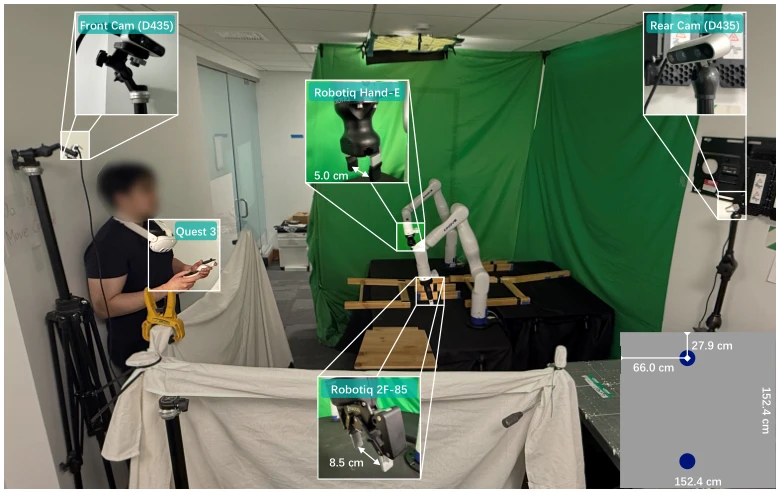
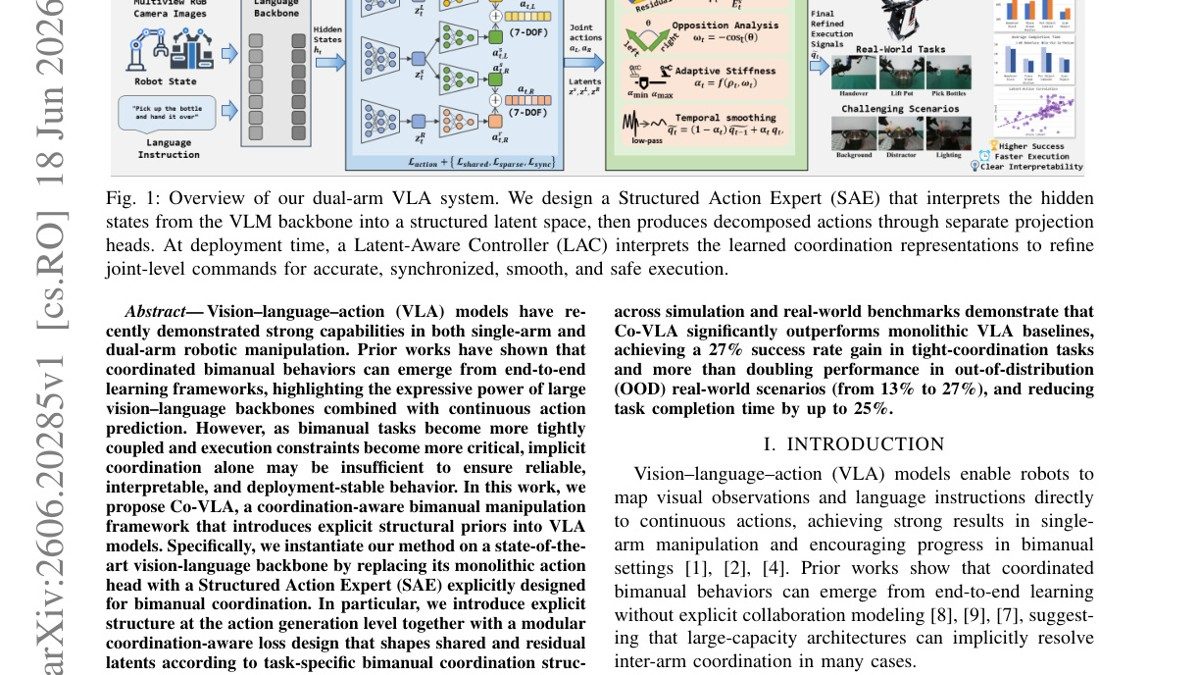
Vision-language-action (VLA) models show strong capabilities in single and dual-arm robotic manipulation. Prior works show coordinated bimanual behaviors can emerge from end-to-end learning, leveraging large vision-language backbones with continuous action prediction.
ar-vr evaluation generation
PDF
Intermediate