
Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think
FeaturedGia-Binh Nguyen, Trong-Bao Ho, Thien-Loc Ha, Khoa Vo, Philip Lund Møller, Quang T. Nguyen, Long Dinh, Tuan Dam, Vu Duong, Tung M. Luu, Trung Le, Tran Nguyen Le, Minh Vu, An Thai Le, Ngan Le, Daniel Sonntag, James Zou, Jan Peters, Duy M. H. Nguyen, Ngo Anh Vien · · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Vision-Language-Action (VLA) models pre-trained on massive video-robot datasets have revolutionized robotic manipulation, yet their multi-billion parameter architectures impose prohibitive computational burdens during downstream fine-tuning and real-time inference.
Abstract Summary
Key Points
- Proposes Finetuning Vision-Language-Action Models Requires Fewer Laye for robotics.
- Evaluated on real or simulated robotic tasks.
- Primary contribution in ar-vr.
Preliminaries
Vision-Language-Action Model. Let $\mathbf{x}^{\text{lang}}$ denote a text instruction and $\mathbf{x}^{\text{img}}\in\mathbb{R}^{H\times W\times 3}$ denote the RGB observation. A continuous-action VLA policy predicts an action chunk $\mathbf{a}\in\mathbb{R}^{T_{a}\times d_{a}}$ conditioned on these multimodal inputs.
CKA-Guided Layer Pruning
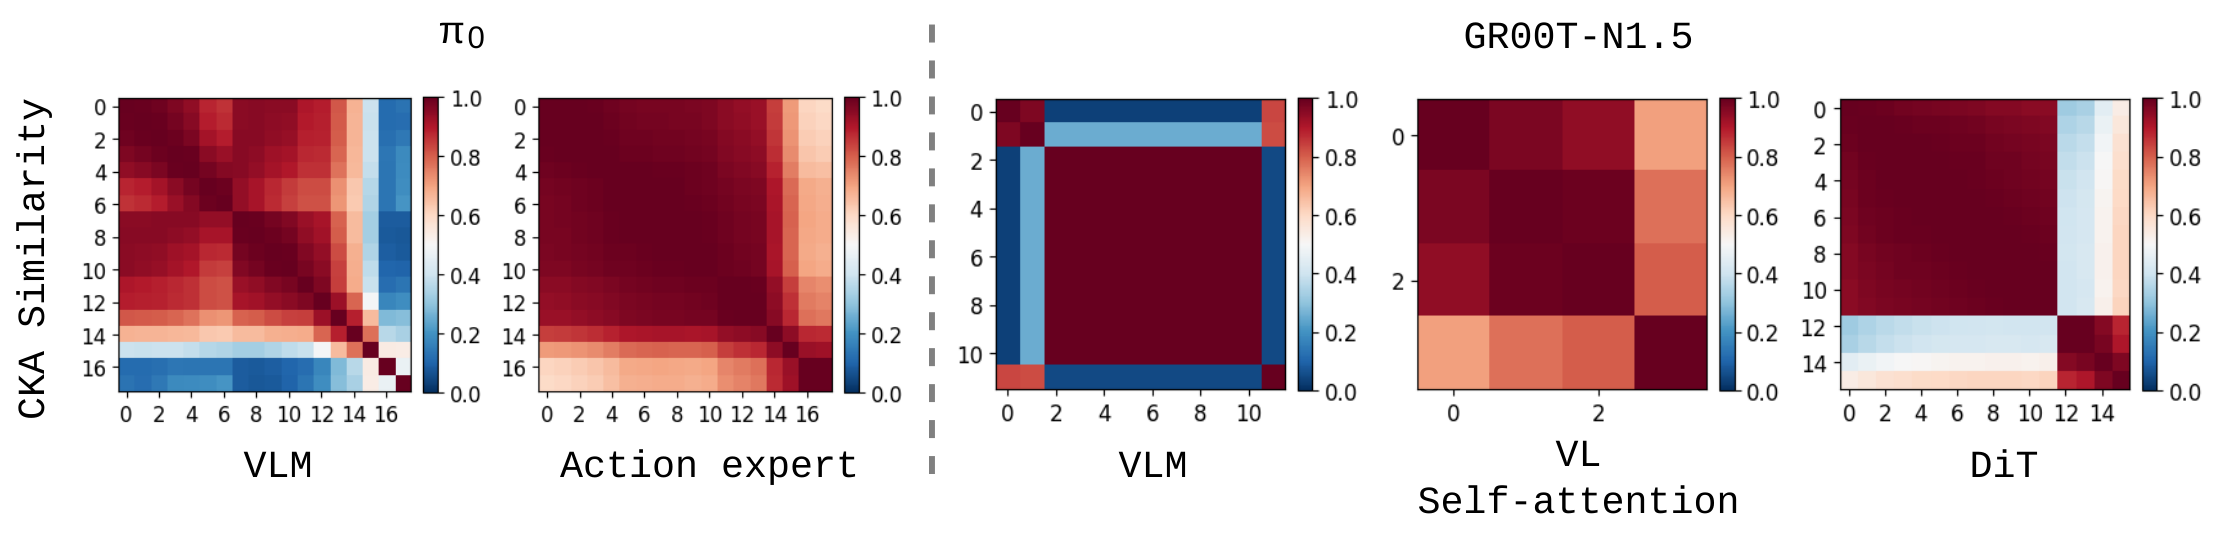
Diagnosing Layer Redundancy in Deep VLAs. To better understand the internal mechanics driving deep VLA architectures, we initiate an empirical exploration into a central question: “how does information actually evolve across network depth?” .
Leveraging the CKA metric established in Section 1 , we trace the hidden state trajectories of representative continuous-control foundations as they map multimodal context to physical actions.
Experimental Results and Analysis
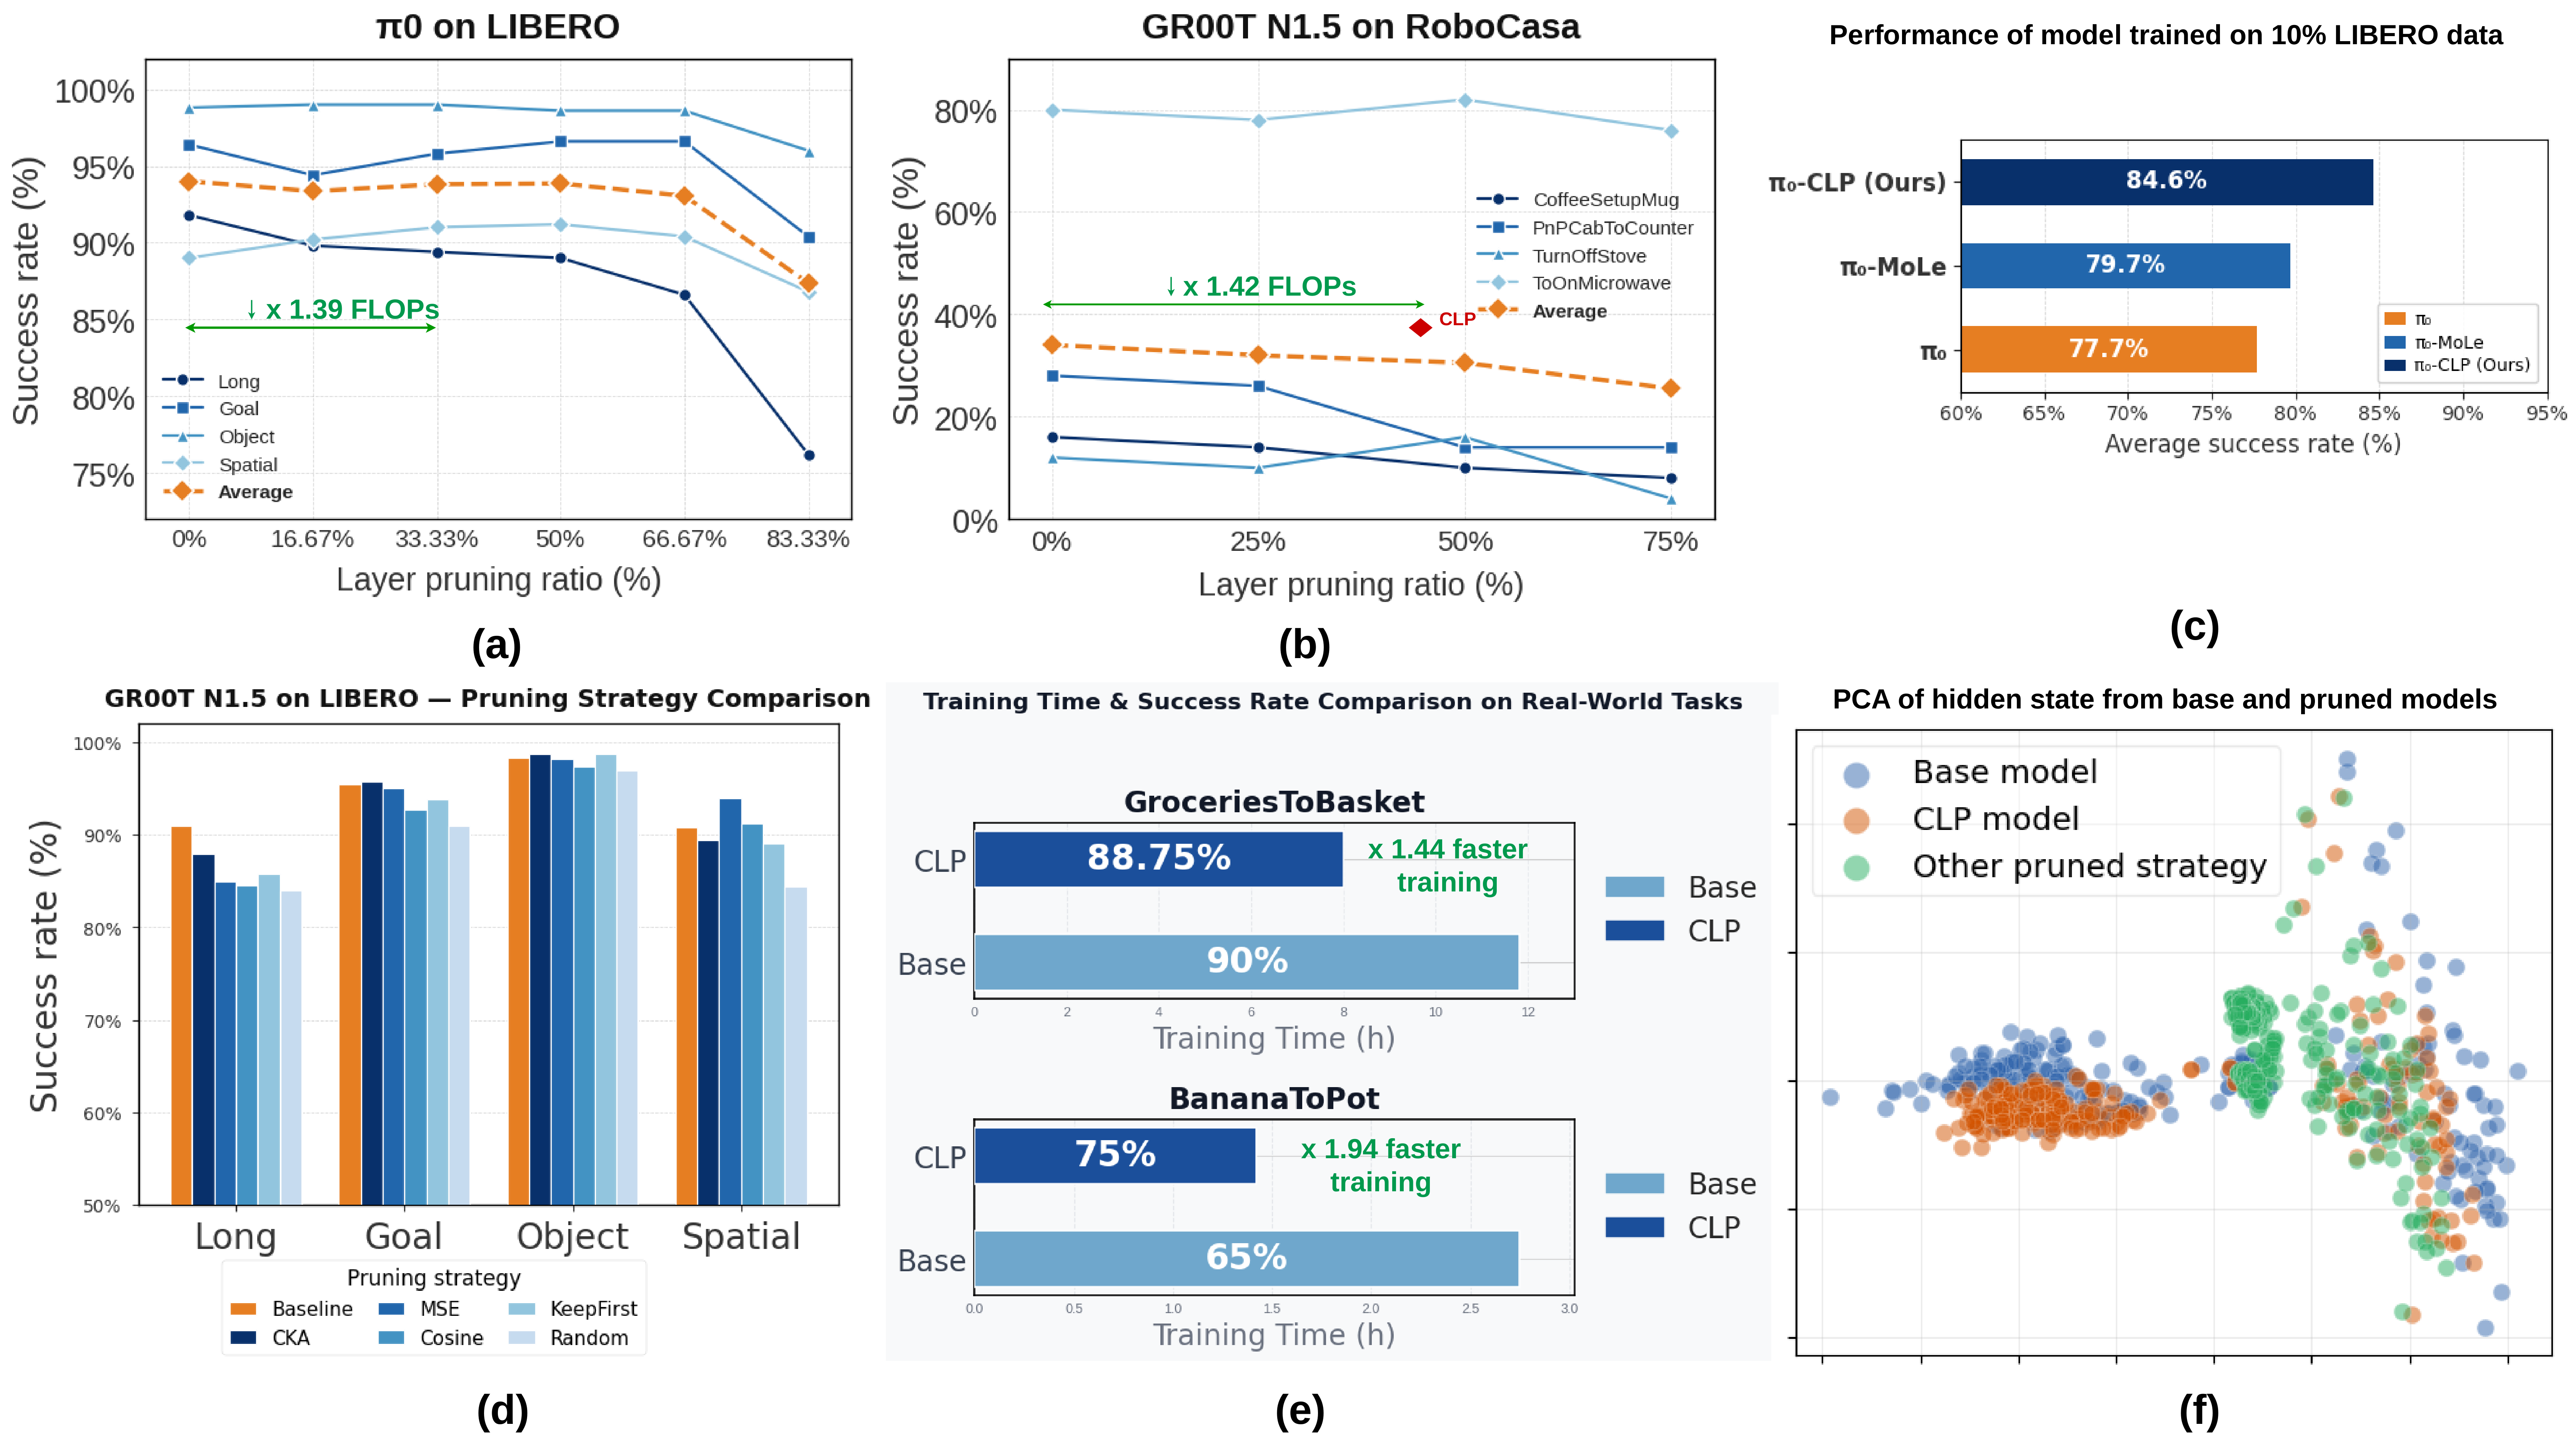
We conduct a diverse set of experiments to examine the performance of pruned VLA models trained with our CLP models across simulation and real-world settings and robot embodiment configurations. Details are presented in the Appendix. We first investigate the fundamental architectural properties of layer redundancy in VLAs and dissect the internal mechanisms of our framework ( RQ1 & RQ2 ).
Limitation
A key limitation of CLP is its use of a global pruning criterion that does not explicitly account for modality-specific token dynamics in manipulation tasks. Our analysis suggests that action and state tokens exhibit distinct representations, motivating future token- or modality-aware pruning strategies.
In addition, the current work investigates CLP exclusively in the context of post-pretraining fine-tuning, leaving its application to the pretraining stage an open direction for future work.
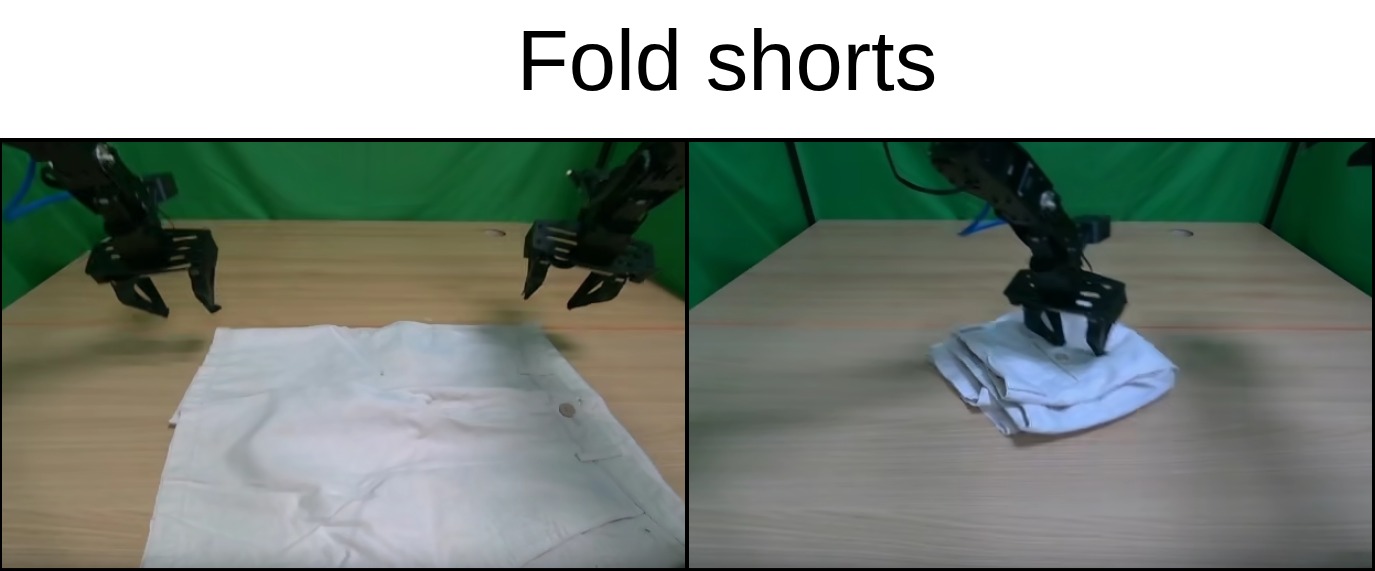
Sources and Demonstrations
Figures are reproduced from Nguyen et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
Finetuning Vision-Language-Action Models Requires Fewer Layers Than You Think
Gia-Binh Nguyen, Trong-Bao Ho, Thien-Loc Ha et al.
Vision-Language-Action (VLA) models pre-trained on massive video-robot datasets have revolutionized robotic manipulation, yet their multi-billion parameter architectures impose prohibitive computational burdens during downstream fine-tuning and real-time inference.
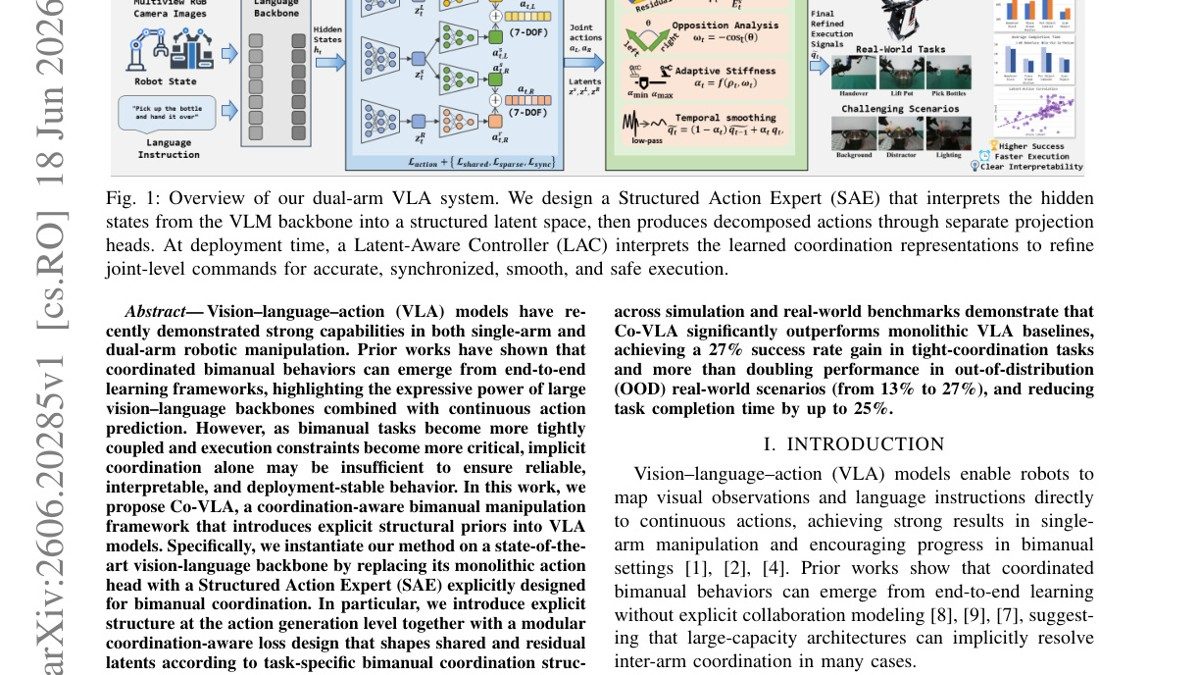
Co-VLA: Coordination-Aware Structured Action Modeling for Dual-Arm Vision-Language-Action Systems
Yandong Wang, Jiaqian Yu, Xiongfeng Peng et al.
Vision-language-action (VLA) models show strong capabilities in single and dual-arm robotic manipulation. Prior works show coordinated bimanual behaviors can emerge from end-to-end learning, leveraging large vision-language backbones with continuous action prediction.
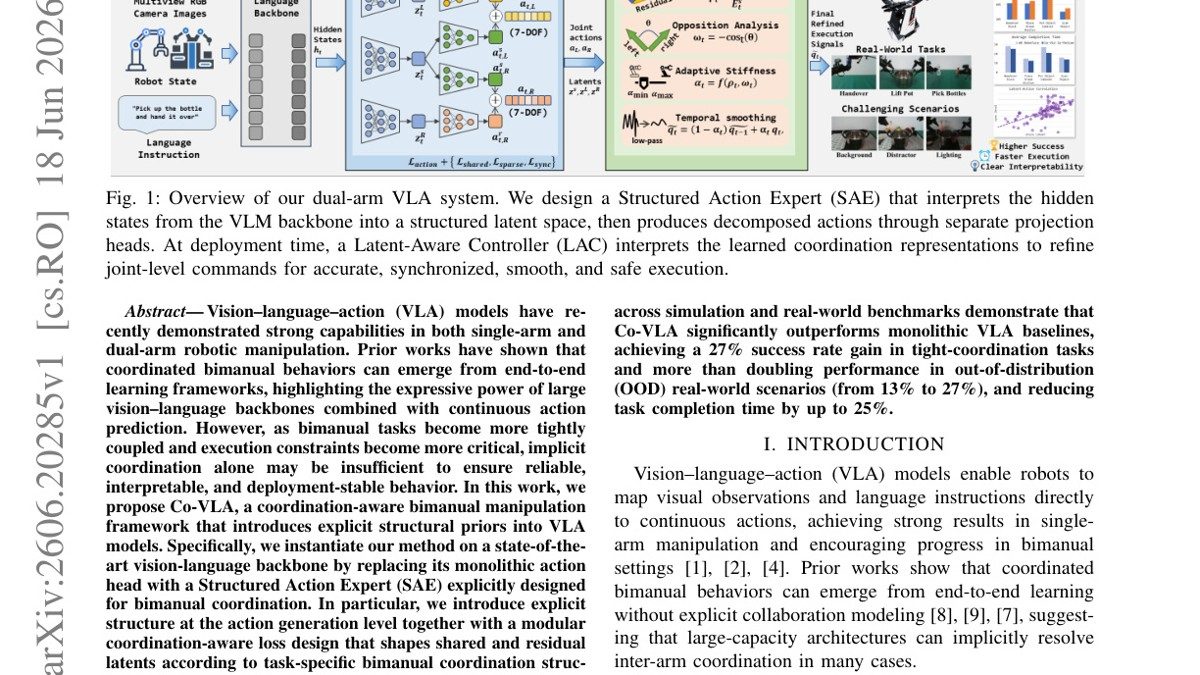
Co-VLA: Coordination-Aware Structured Action Modeling for Dual-Arm Vision-Language-Action Systems
Yandong Wang, Jiaqian Yu, Xiongfeng Peng et al.
Vision-language-action (VLA) models show strong capabilities in single and dual-arm robotic manipulation. Prior works show coordinated bimanual behaviors can emerge from end-to-end learning, leveraging large vision-language backbones with continuous action prediction.
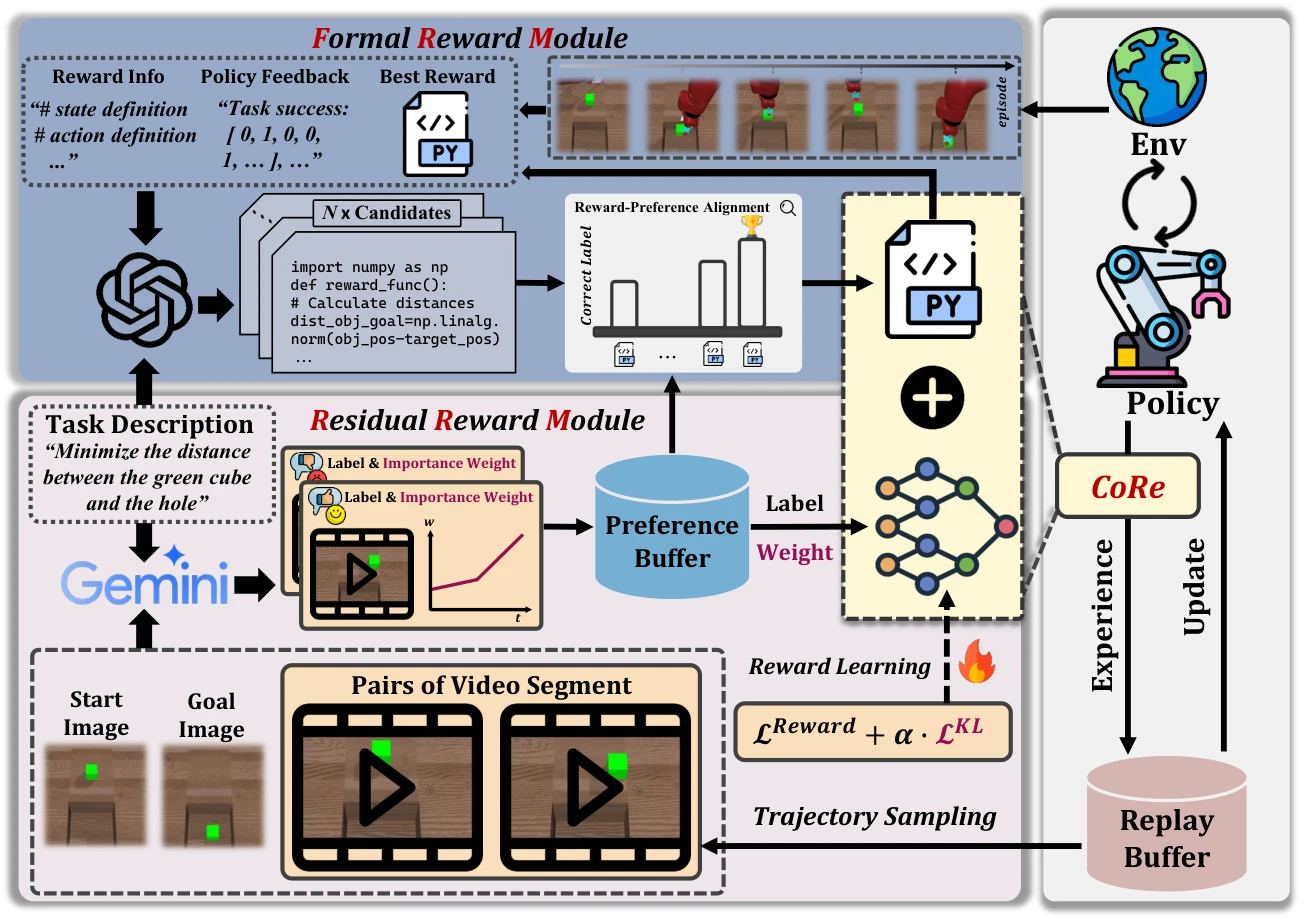
CoRe: Combined Rewards with Vision-Language Model Feedback for Preference-Aligned Reinforcement Learning
Hexian Ni, Tao Lu, Yinghao Cai
CoRe combines code-based rewards with learned visual preferences so that neither reward source has to capture the entire task alone.