ICML 2026
CoRe: Combined Rewards with Vision-Language Model Feedback for Preference-Aligned Reinforcement Learning
Hexian Ni, Tao Lu, Yinghao Cai
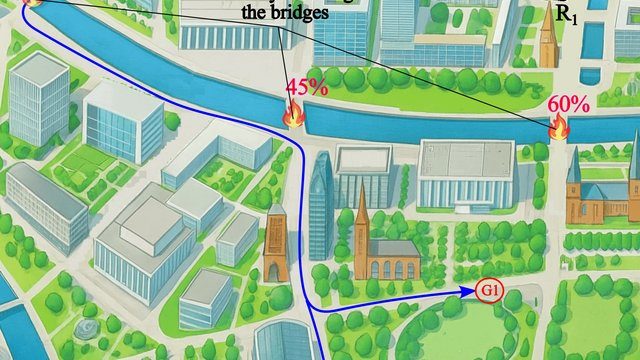
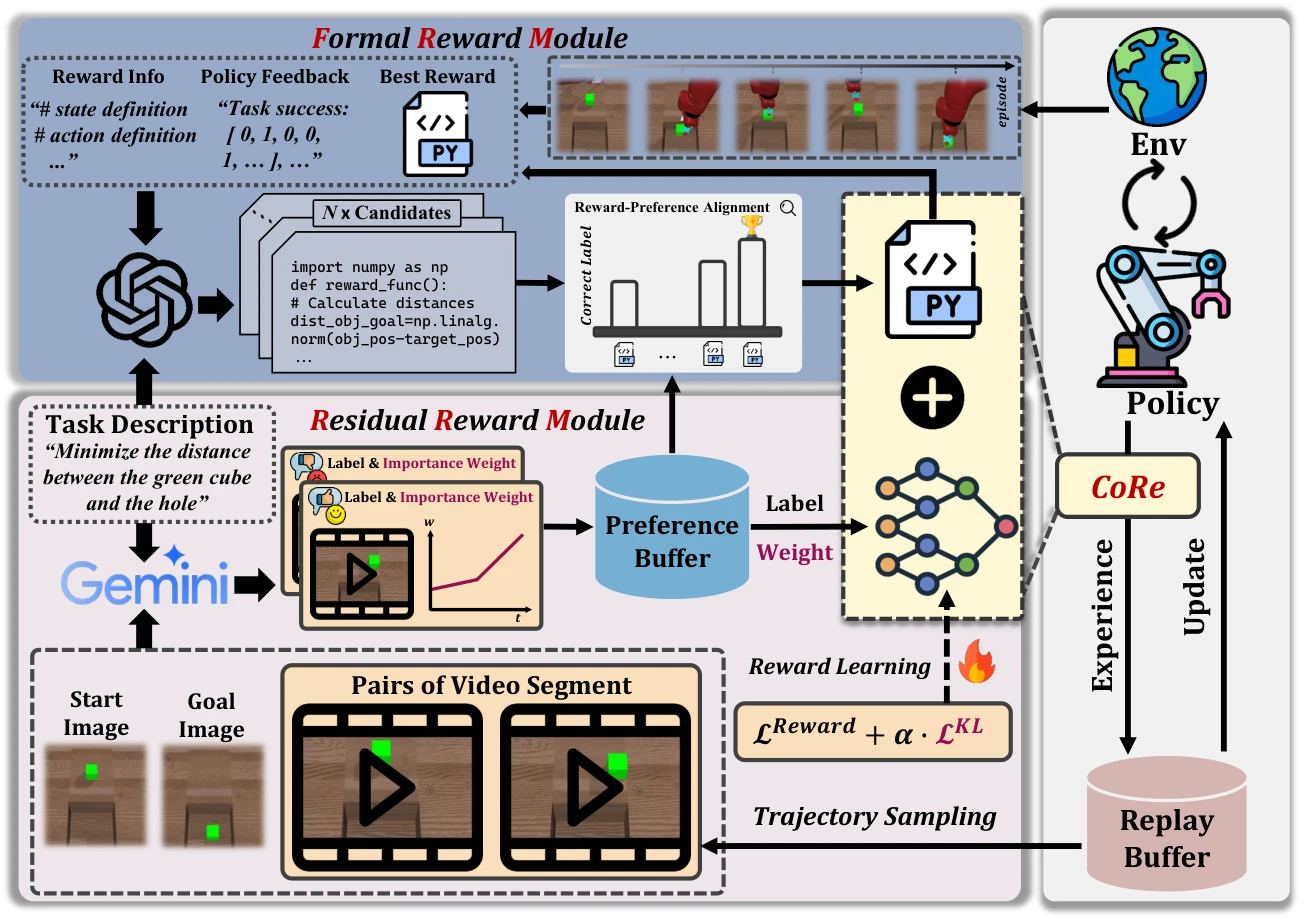
CoRe combines code-based rewards with learned visual preferences so that neither reward source has to capture the entire task alone.
ar-vr manipulation rl
PDF
Advanced