
Superhuman Safe and Agile Racing through Multi-Agent Reinforcement Learning
FeaturedIsmail Geles, Leonard Bauersfeld, Markus Wulfmeier, Davide Scaramuzza · University of Zurich, Google DeepMind · 2026
Summary
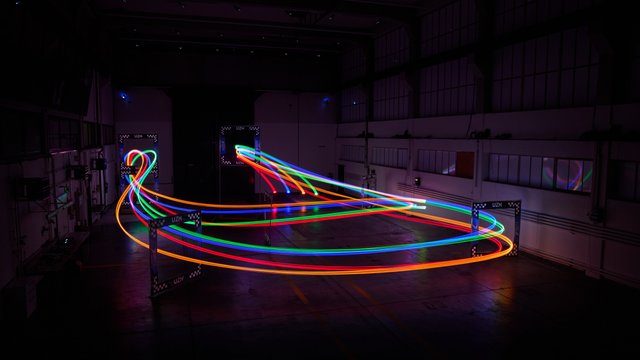
The first demonstration of superhuman, safe, multi-agent drone racing using a MARL framework trained in simulation and transferred to real Crazyflie nano-drones.
Abstract Summary
Key Points
- First demonstration of superhuman safe multi-agent drone racing.
- Multi-agent RL trained in simulation transfers to real Crazyflie drones.
- Safety-conditioned action space balances aggression and collision avoidance.
- Outperforms human world champion lap times with zero collisions.
- Uses photorealistic sim-to-real transfer for outdoor deployment.
Results
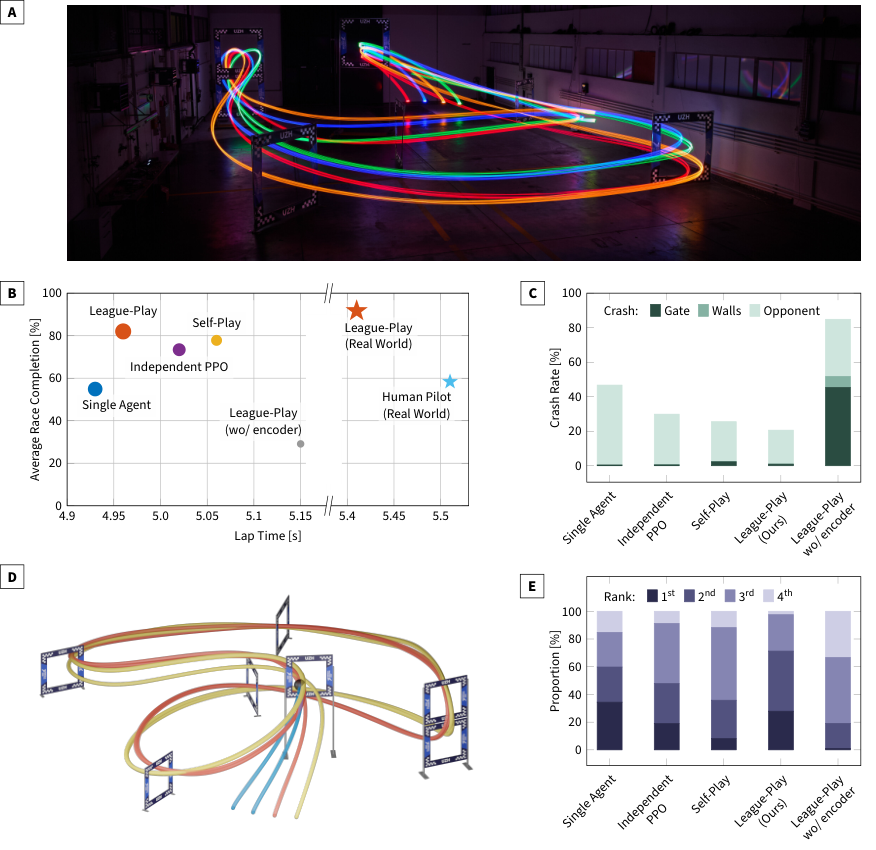
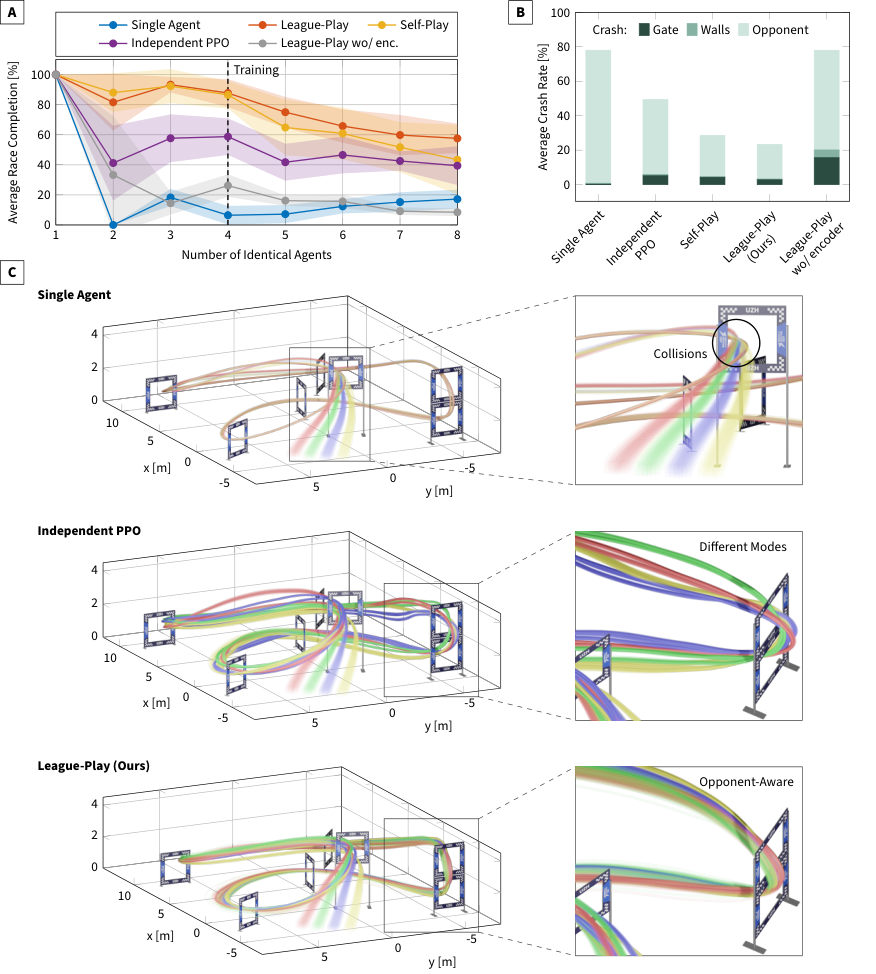
We evaluate our approach in both real-world and simulated multi-agent settings. We use a single policy trained with four agents that generalizes to varying numbers of opponents. In physical experiments, we race with up to 4 competitors, including a champion-level human pilot. The policy maintains both safety and competitive performance across configurations, from solo time trials to dense four-agent races.
Materials and Methods
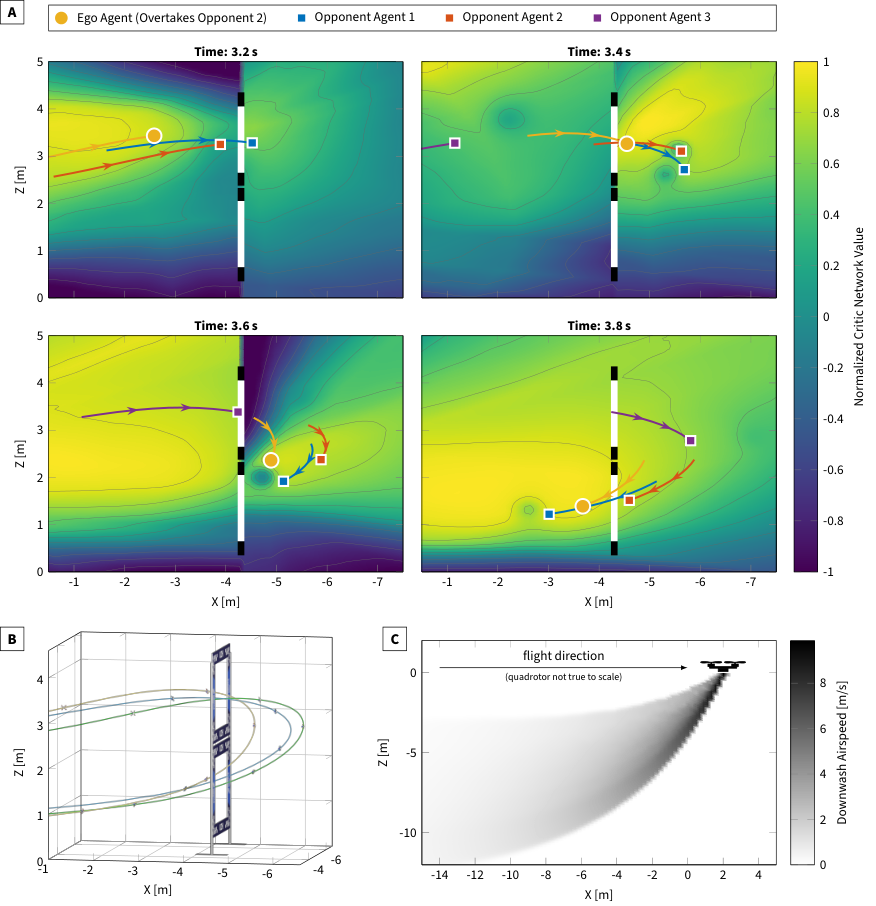
We train and evaluate policies in simulation using Flightmare [ 36 ] integrated with the Agilicious framework [ 13 ] , which provides high-fidelity dynamics for large-scale reinforcement learning. We extended the simulator to support multiple quadrotors simultaneously, enabling collision detection and aerodynamic interactions between agents.
Multi-agent training is parallelized across 144 environments, each simulating four quadrotors, to accelerate data collection while exposing agents to varied multi-agent interaction dynamics.
Supplemetary Material
Table S1 lists the coefficients used in the reward function defined in the Materials and Methods section. The progress coefficient $\lambda_{1}$ provides the primary learning signal, while the remaining coefficients are scaled to balance competing objectives without dominating the progress reward.
The relatively small values for ranking ($\lambda_{3}$) and opponent proximity ($\lambda_{4}$) encourage competitive behavior and safe distancing without overriding the fundamental gate-progress objective.
Sources and Demonstrations
Figures are reproduced from Geles et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
Scout-Assisted Planning for Heterogeneous Robot Teams under Partially Known Environments
Hoang-Dung Bui, Abhish Khanal, Raihan Islam Arnob et al.
SAP pairs aerial scouts with ground robots to gather environmental information ahead of time, reducing mission time by 40% through information-theoretic POMDP planning.

Learning Agile Flight in the Wild
Elia Kaufmann, Mathias Gehrig, Philipp Foehn et al.
An end-to-end neural drone controller trained entirely in simulation flies acrobatic maneuvers in the real world with zero real-world fine-tuning, enabled by domain randomization and reinforcement learning.
AIR-VLA+: Decoupling Movement and Manipulation via Cascaded Dual-Action Decoders with Asymmetric MoE for Aerial Robots
Jianli Sun, Bin Tian, Qiyao Zhang et al.
Aerial manipulation systems have long suffered from representation coupling in end-to-end control, as platform-level Unmanned Aerial Vehicle (UAV) movement and end-effector-level arm manipulation differ substantially in action scale, dynamics, and control objectives.
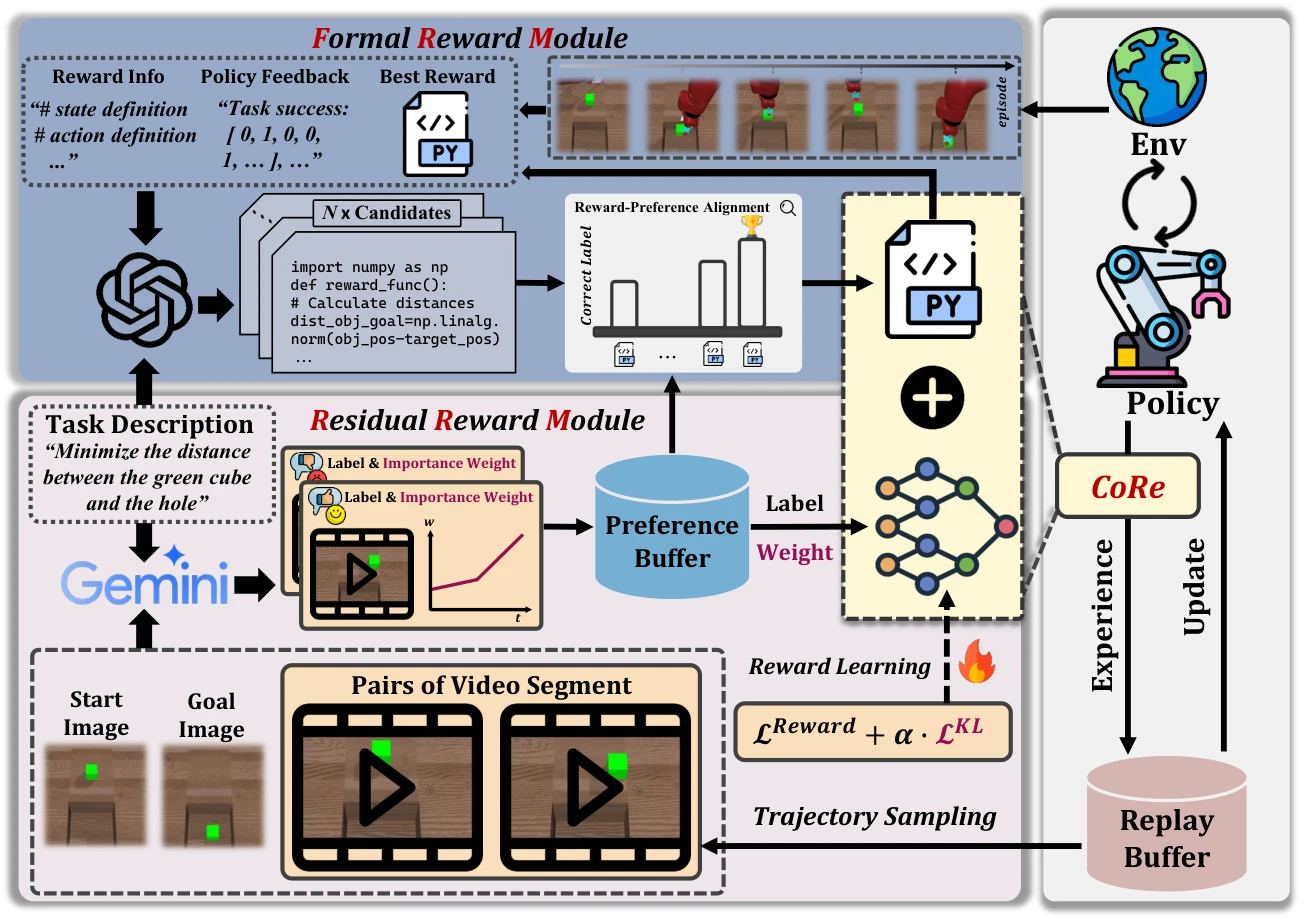
CoRe: Combined Rewards with Vision-Language Model Feedback for Preference-Aligned Reinforcement Learning
Hexian Ni, Tao Lu, Yinghao Cai
CoRe combines code-based rewards with learned visual preferences so that neither reward source has to capture the entire task alone.