

Humanoid-Gym: Reinforcement Learning for Humanoid Robot with Zero-Shot Sim2Real Transfer
Wang J., Xiao B., Wang J., Heider P., Li H., Zhang Y. · RobotEra / K-Scale Labs · 2024
Framework
Isaac Gym / PyTorch
License
MIT
Stars
10
Summary
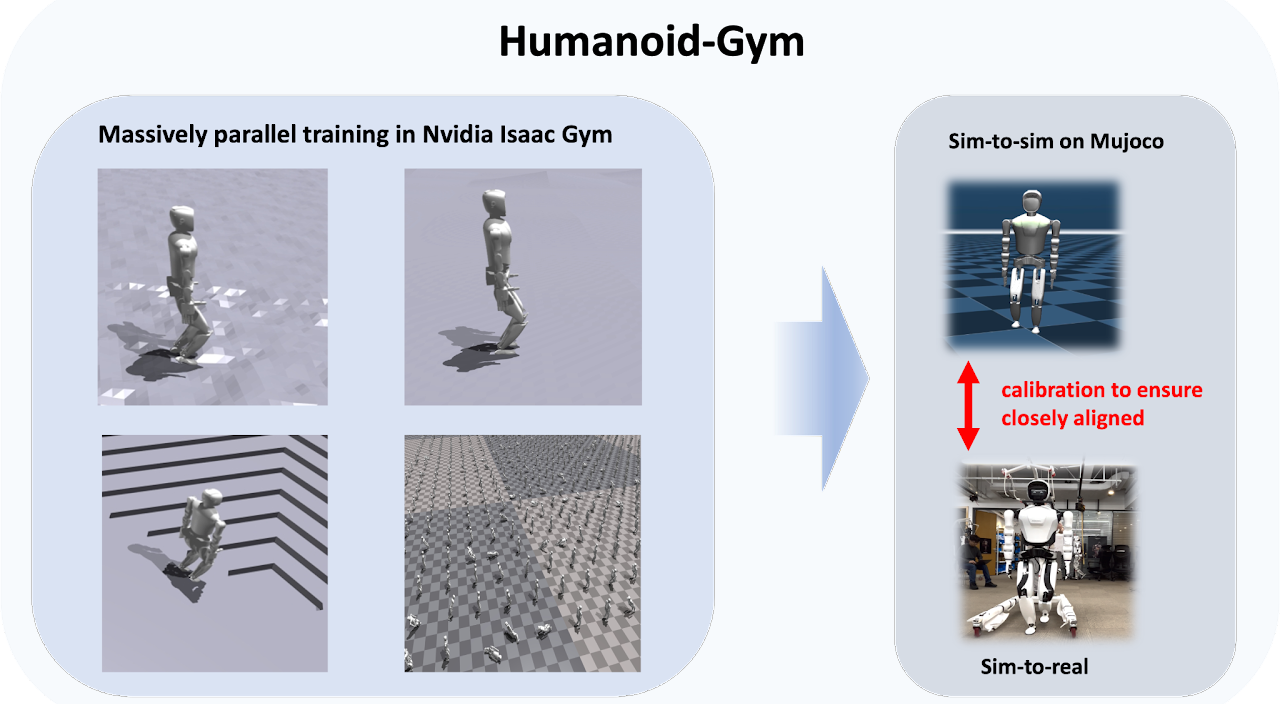
An Isaac-Gym-based training framework for humanoid locomotion that enables zero-shot sim-to-real transfer on XBot-L/XBot-S robots via domain randomization.
Abstract Summary
Key Points
- Isaac-Gym PPO training at 4096 parallel environments with humanoid-specific rewards.
- Zero-shot sim-to-real demonstrated on XBot-L and XBot-S hardware.
- Built-in sim2sim pipeline (Isaac Gym -> MuJoCo) for pre-transfer validation.
- Domain randomization across terrain, actuator dynamics, and sensor delay.
- Open-source release with URDF, training configs, and deployment scripts.
Method
The workflow of Humanoid-Gym is illustrated in Fig. 2 . In this section, we will introduce the problem setting, system design, and reward design of our Humanoid-Gym.
Our approach employs a reinforcement learning model $\mathcal{M}=\langle\mathcal{S},\mathcal{A},T,\mathcal{O},R,\gamma\rangle$, with $\mathcal{S}$ and $\mathcal{A}$ denoting state and action spaces, $T(\mathbf{s}^{\prime}/\mathbf{s},\mathbf{a})$ the transition dynamics, $R(\mathbf{s},\mathbf{a})$ the reward function, $\gamma\in[0,1]$ the discount factor, and $\mathcal{O}$ the obser...
Experiments
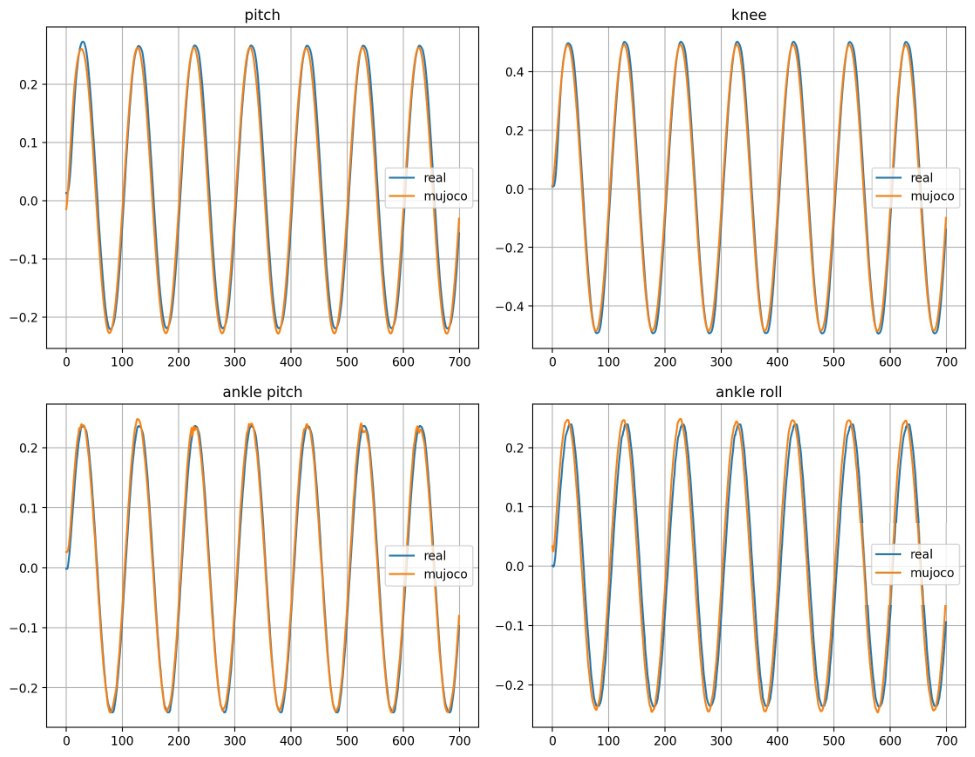
In this section, we will illustrate the result of zero-shot transfer for both sim-to-sim and sim-to-real scenarios. Additionally, we also provide visualization of the calibration for MuJoCo to verify the effectiveness of sim-to-sim. For the validation, we utilized Robot Era’s humanoid robots, XBot-S and XBot-L, measuring 1.2 meters and 1.65 meters in height, shown in Appendix Fig. 5 , respectively.
Sources and Demonstrations
Figures are reproduced from Wang J. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
Berkeley Humanoid: A Low-Cost 3D-Printed Humanoid for Research
Zachary Kousik, Shanpu Fang, Rohan Thakker et al.
An open-source 3D-printed humanoid robot platform designed for reinforcement-learning based locomotion research with affordable hardware.

SafeManip: A Property-Driven Benchmark for Temporal Safety Evaluation in Robotic Manipulation
Chengyue Huang, Khang Vo Huynh, Sebastian Elbaum et al.
Robotic manipulation is typically evaluated by task success, but successful completion does not guarantee safe execution. Many rl failures are temporal: a robot may touch a clean surface after contamination or release an object before it is fully inside an enclosure.
Unitree Go2: Learning Vision-Based Quadrupedal Locomotion End-to-End
Nikita Rudin, Fabian Jenelten, Timon Homberger et al.
Unitree Go2 uses cross-modal vision + proprioception transformers trained in Isaac Gym to achieve agile navigation over rough terrain with minimal sim-to-real gap.

Legged Gym: A Framework for Massively Parallel Reinforcement Learning of Legged Locomotion
Nikita Rudin, David Hoeller, Philipp Reist et al.
Legged Gym is an open-source training framework built on NVIDIA Isaac Gym that enables massively parallel deep RL for legged robot locomotion, achieving policy training times of minutes rather than days.