

WorldSample: Closed-loop Real-robot RL with World Modelling
FeaturedYuquan Xue, Le Xu, Zeyi Liu, Zhenyu Wu, Zhengyi Gu, Xinyang Song, Bofang Jia, Ziwei Wang · · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Reinforcement learning (RL) can overcome the demonstration-coverage limitation of imitation learning (IL) by allowing robots to improve through trial-and-error interaction beyond the states observed in demonstrations.
Abstract Summary
Key Points
- Proposes WorldSample for robotics.
- Evaluated on real or simulated robotic tasks.
- Primary contribution in ar-vr.
WorldSample
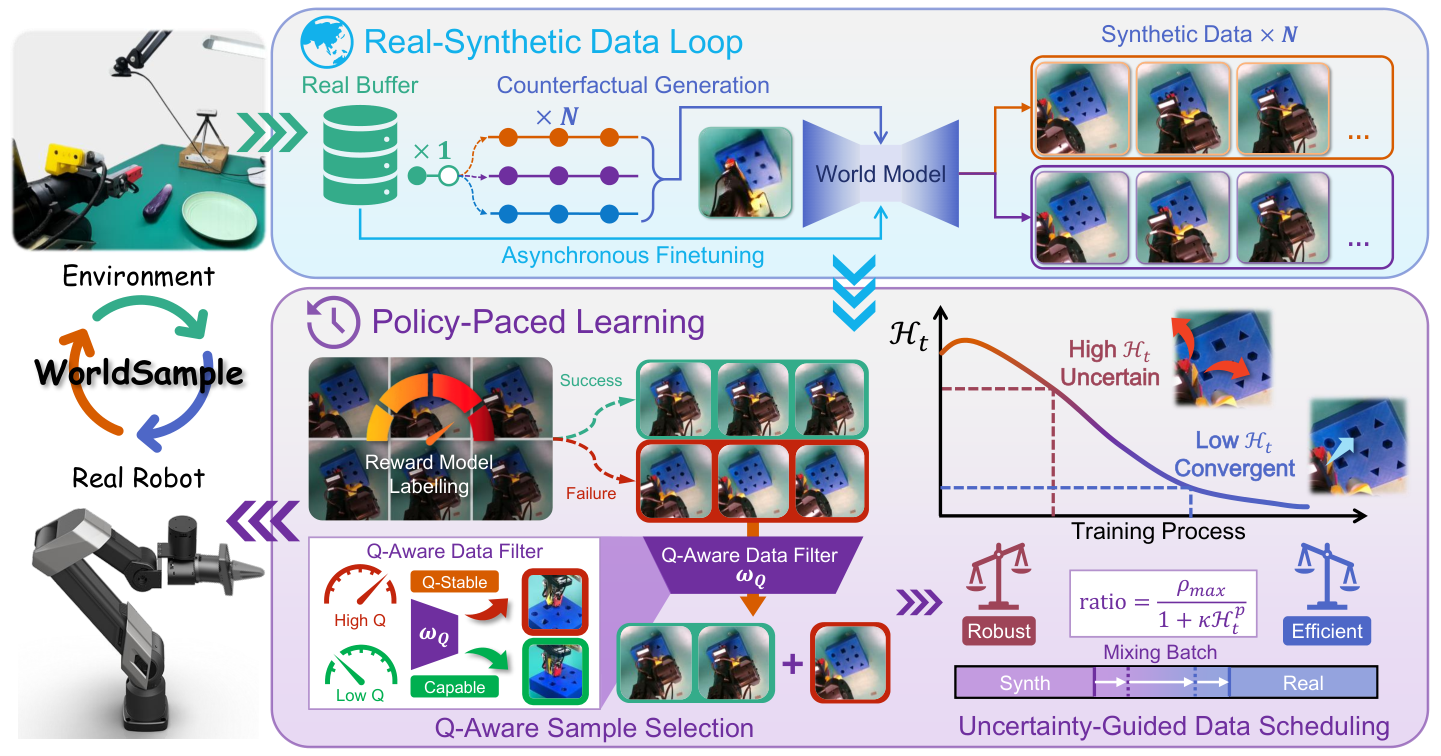
We propose WorldSample , a physically grounded, closed-loop data augmentation framework for online real-world RL. As shown in Fig. 2 , WorldSample consists of two tightly coupled components: real-synthetic data loop and Policy-Paced Learning (PPL) . The real-synthetic data loop starts from physical robot rollouts collected during online interaction.
These rollouts serve two roles simultaneously: they provide training data for policy learning, and they ground synthetic data generation through a action-conditioned world model.
Experimental Results
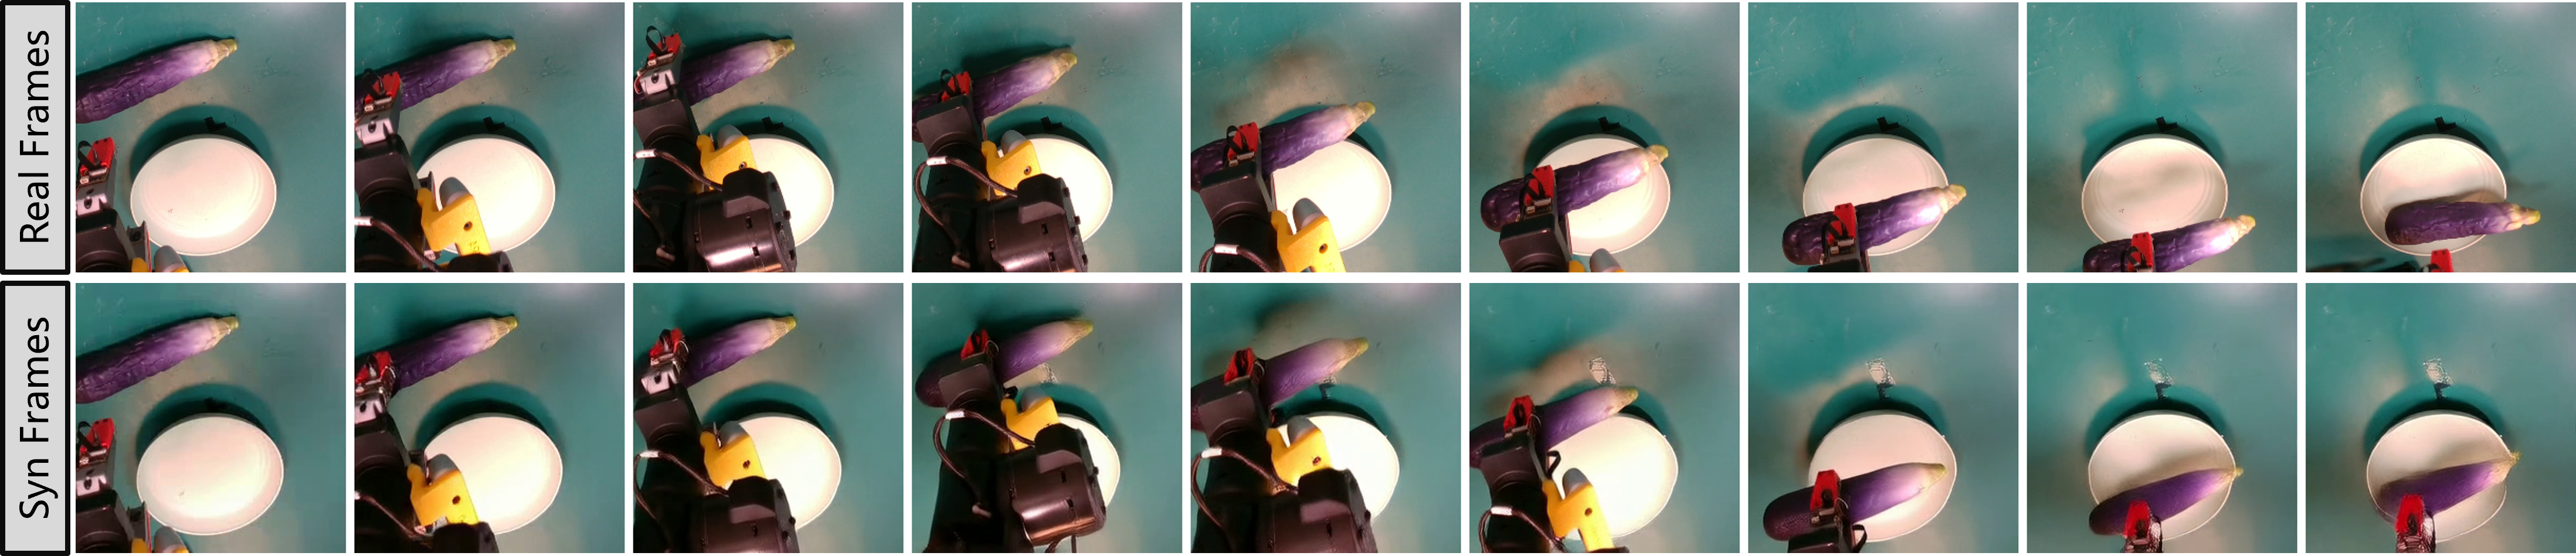
In this section, we conduct extensive experiments on complex and real-world tasks, including precise manipulation and contact-rich interaction, to evaluate WorldSample. Our experiments are designed to answer the following three questions: Does WorldSample improve online real-robot RL efficiency? Does WorldSample improve the video fidelity and physical grounding of the world model?
Is Policy-Paced Learning necessary for stable and effective use of synthetic data? We conduct experiments on a Galaxea A1X robotic arm equipped with a binary gripper....
Limitaions
WorldSample currently focuses on augmenting real-robot learning within a single task and a relatively fixed scene distribution. Although online rollout adaptation improves the world model within this setting, extending this framework to instance-, task-, or scene-level generalization remains an important direction for future work.
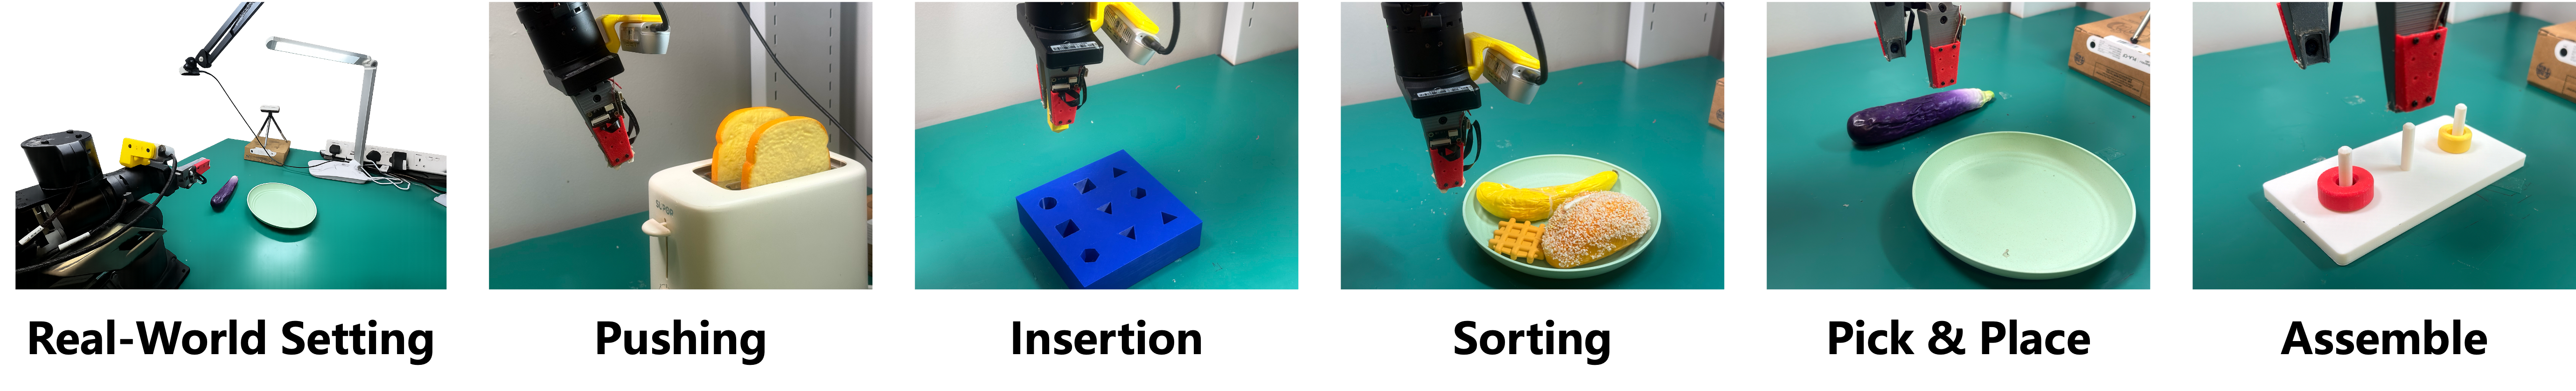
In this paper, we evaluate WorldSample and all baselines on a suite of real-world manipulation tasks, as illustrated in Fig. 6 .
Sources and Demonstrations
Figures are reproduced from Xue et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
Co-VLA: Coordination-Aware Structured Action Modeling for Dual-Arm Vision-Language-Action Systems
Yandong Wang, Jiaqian Yu, Xiongfeng Peng et al.
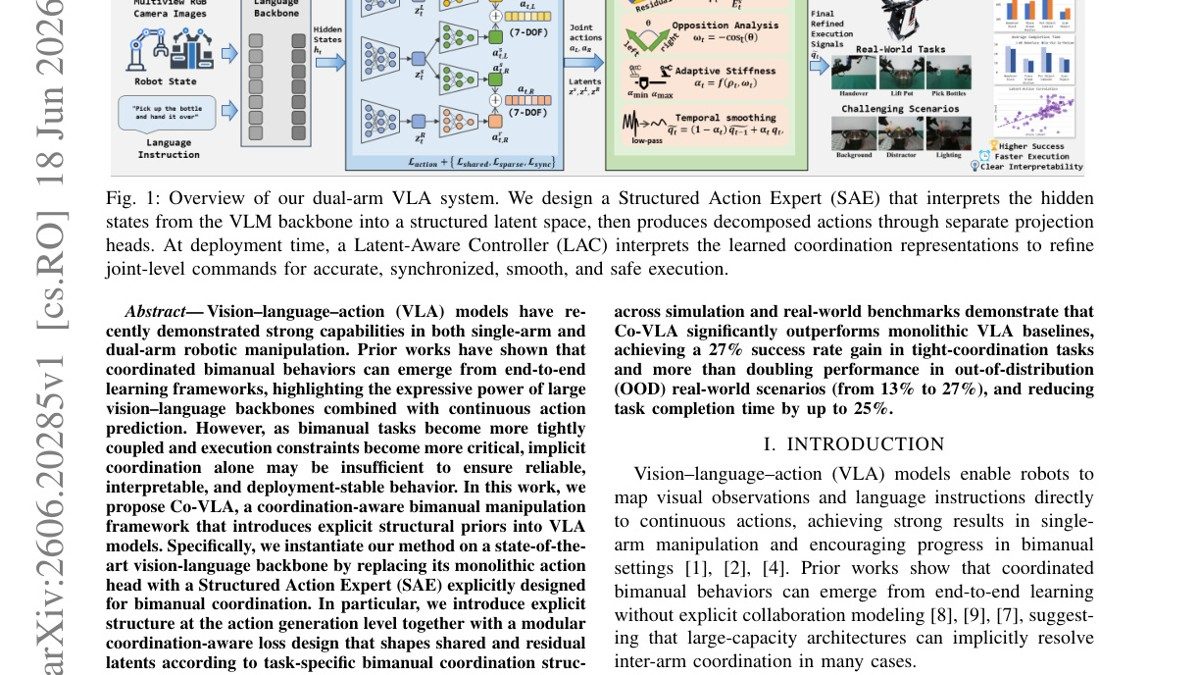
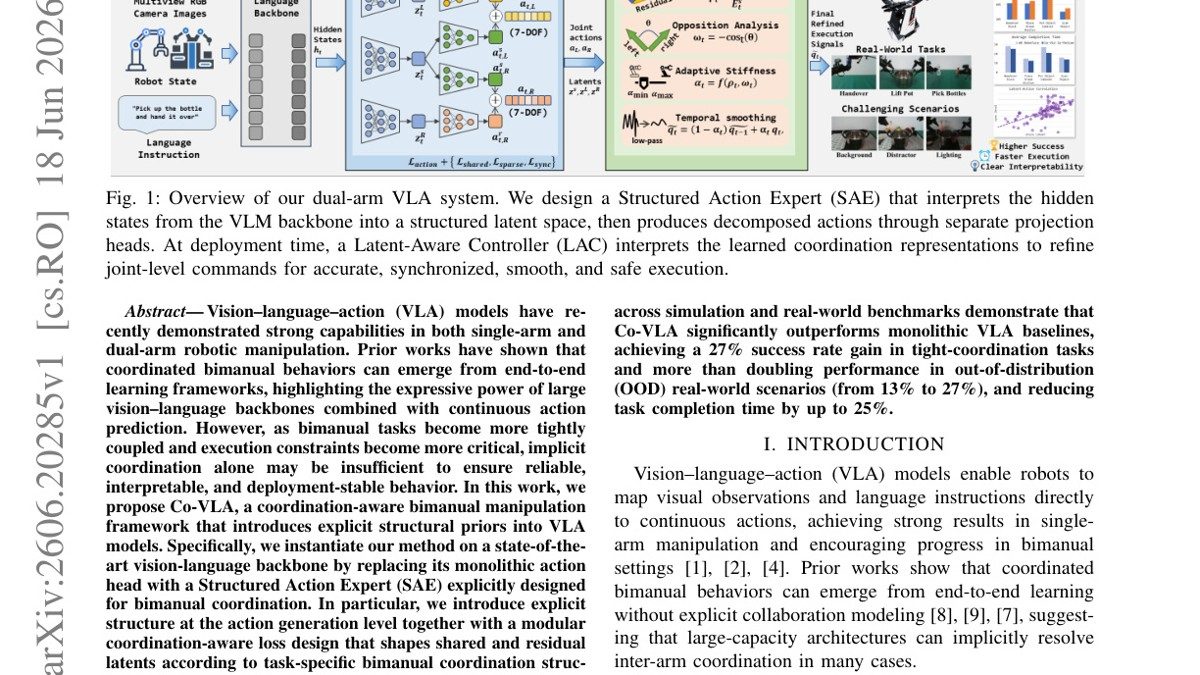
Vision-language-action (VLA) models show strong capabilities in single and dual-arm robotic manipulation. Prior works show coordinated bimanual behaviors can emerge from end-to-end learning, leveraging large vision-language backbones with continuous action prediction.
Co-VLA: Coordination-Aware Structured Action Modeling for Dual-Arm Vision-Language-Action Systems
Yandong Wang, Jiaqian Yu, Xiongfeng Peng et al.
Vision-language-action (VLA) models show strong capabilities in single and dual-arm robotic manipulation. Prior works show coordinated bimanual behaviors can emerge from end-to-end learning, leveraging large vision-language backbones with continuous action prediction.
Invertible Neural Network Adapter for One-Step Flow Matching in Robot Manipulation
Yu Zhang, Kangyi Ji, Yongxiang Zou et al.
This paper presents an invertible neural network adapter for general robotic manipulation, designed to generate precise high-dimensional actions conditioned on multimodal observations, including visual, linguistic, and proprioceptive inputs, through a one-step denoising process.
Invertible Neural Network Adapter for One-Step Flow Matching in Robot Manipulation
Yu Zhang, Kangyi Ji, Yongxiang Zou et al.
This paper presents an invertible neural network adapter for general robotic manipulation, designed to generate precise high-dimensional actions conditioned on multimodal observations, including visual, linguistic, and proprioceptive inputs, through a one-step denoising process.