

Deformable Object Manipulation under Partial Observability via Real-Time Full-Shape Estimation
Kosar Behnia, Ville Kyrki, Gokhan Alcan · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Manipulating deformable objects (DOs) is challenging due to their high-dimensional state space, underactuated dynamics, and partial observability.
Abstract Summary
Key Points
- Manipulating deformable objects (DOs) is challenging due to their high-dimensional state space, underactuated dynamics, and partial observability.
- In this paper, we propose cRVAE, a lightweight conditional recurrent variational autoencoder that estimates the full DO state from only partial corner-node observations during inference.
- The resulting model is used as the forward model in a receding-horizon optimal control framework for obstacle-aware collaborative DO manipulation.
- In simulation on rope and fabric, cRVAE estimates the full DO state from the available corner-node measurements alone, matching the accuracy of a parameter-identified XPBD model.
- At inference it uses no physical parameters as model inputs and performs no online parameter identification.
Problem Formulation
The position of the $i$-th node at time step $k$ is denoted by $x^{i}_{k}\in\mathbb{R}^{3}$, and the full object state is represented by the stacked vector Given a manipulation input $f_{k}\in\mathbb{R}^{m}$, the deformable object dynamics are modeled by an unknown transition function In practical manipulation tasks, the full state $P_{k}$ is not directly available during inference.
Proposed Method
The formulation in Section III requires a predictor that can infer the full DO state from sparse measurements, retain temporal information, and remain differentiable and lightweight for receding-horizon optimization. To instantiate the generic predictor $\Phi_{\theta}$ in ( 4 ), we propose cRVAE, a conditional recurrent variational autoencoder.
During training , full simulated states are available and are used to learn a posterior latent distribution and reconstruct the next full state.
Experiments
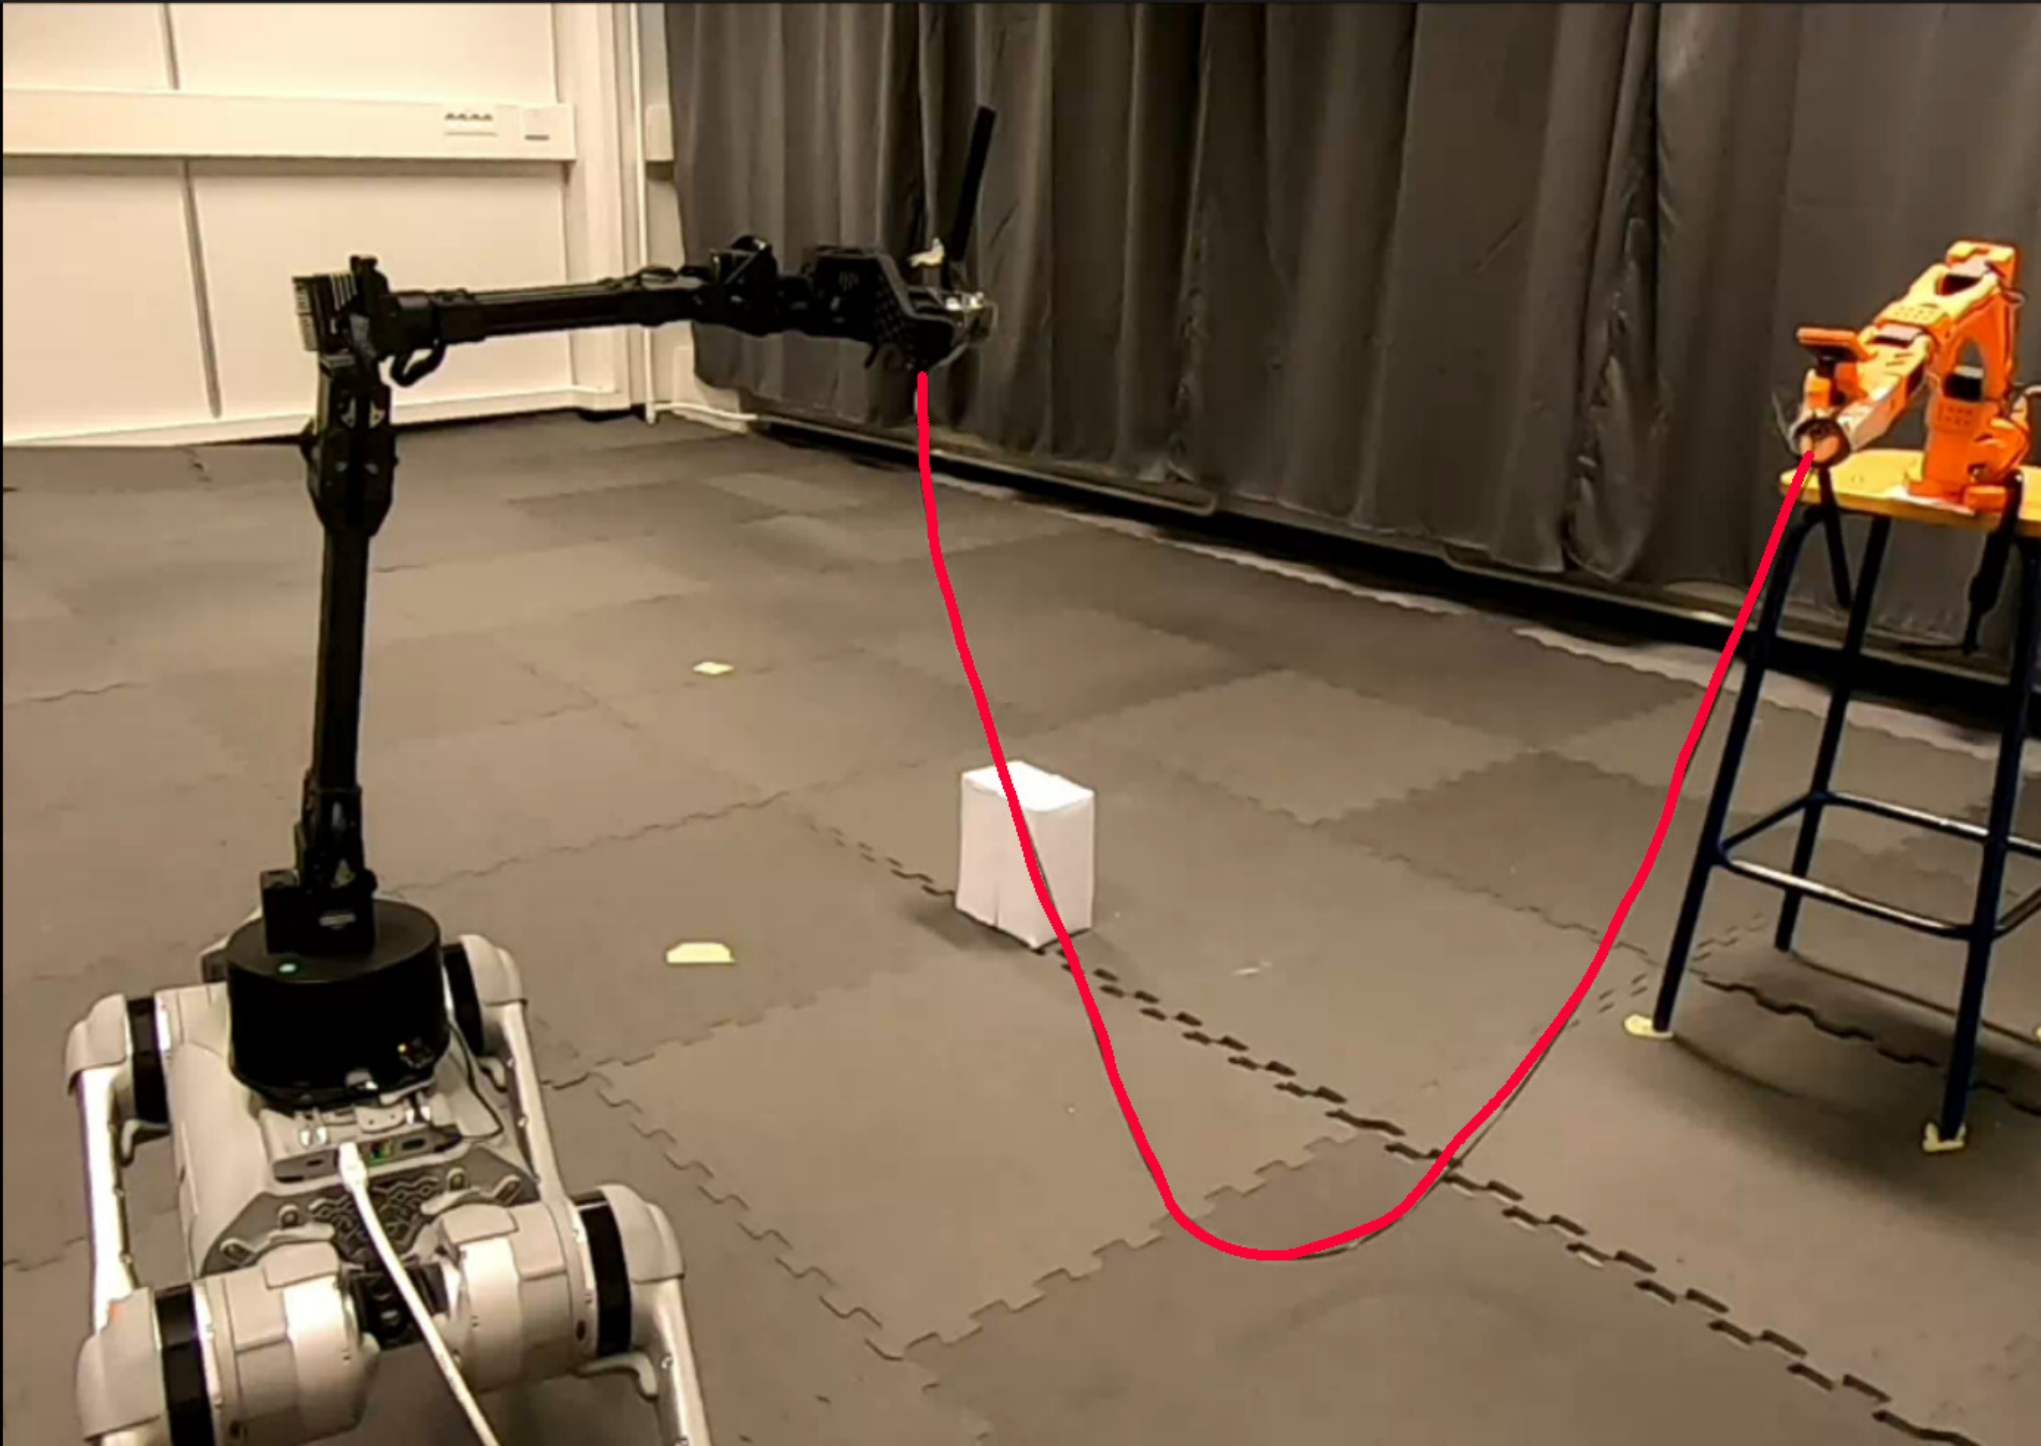
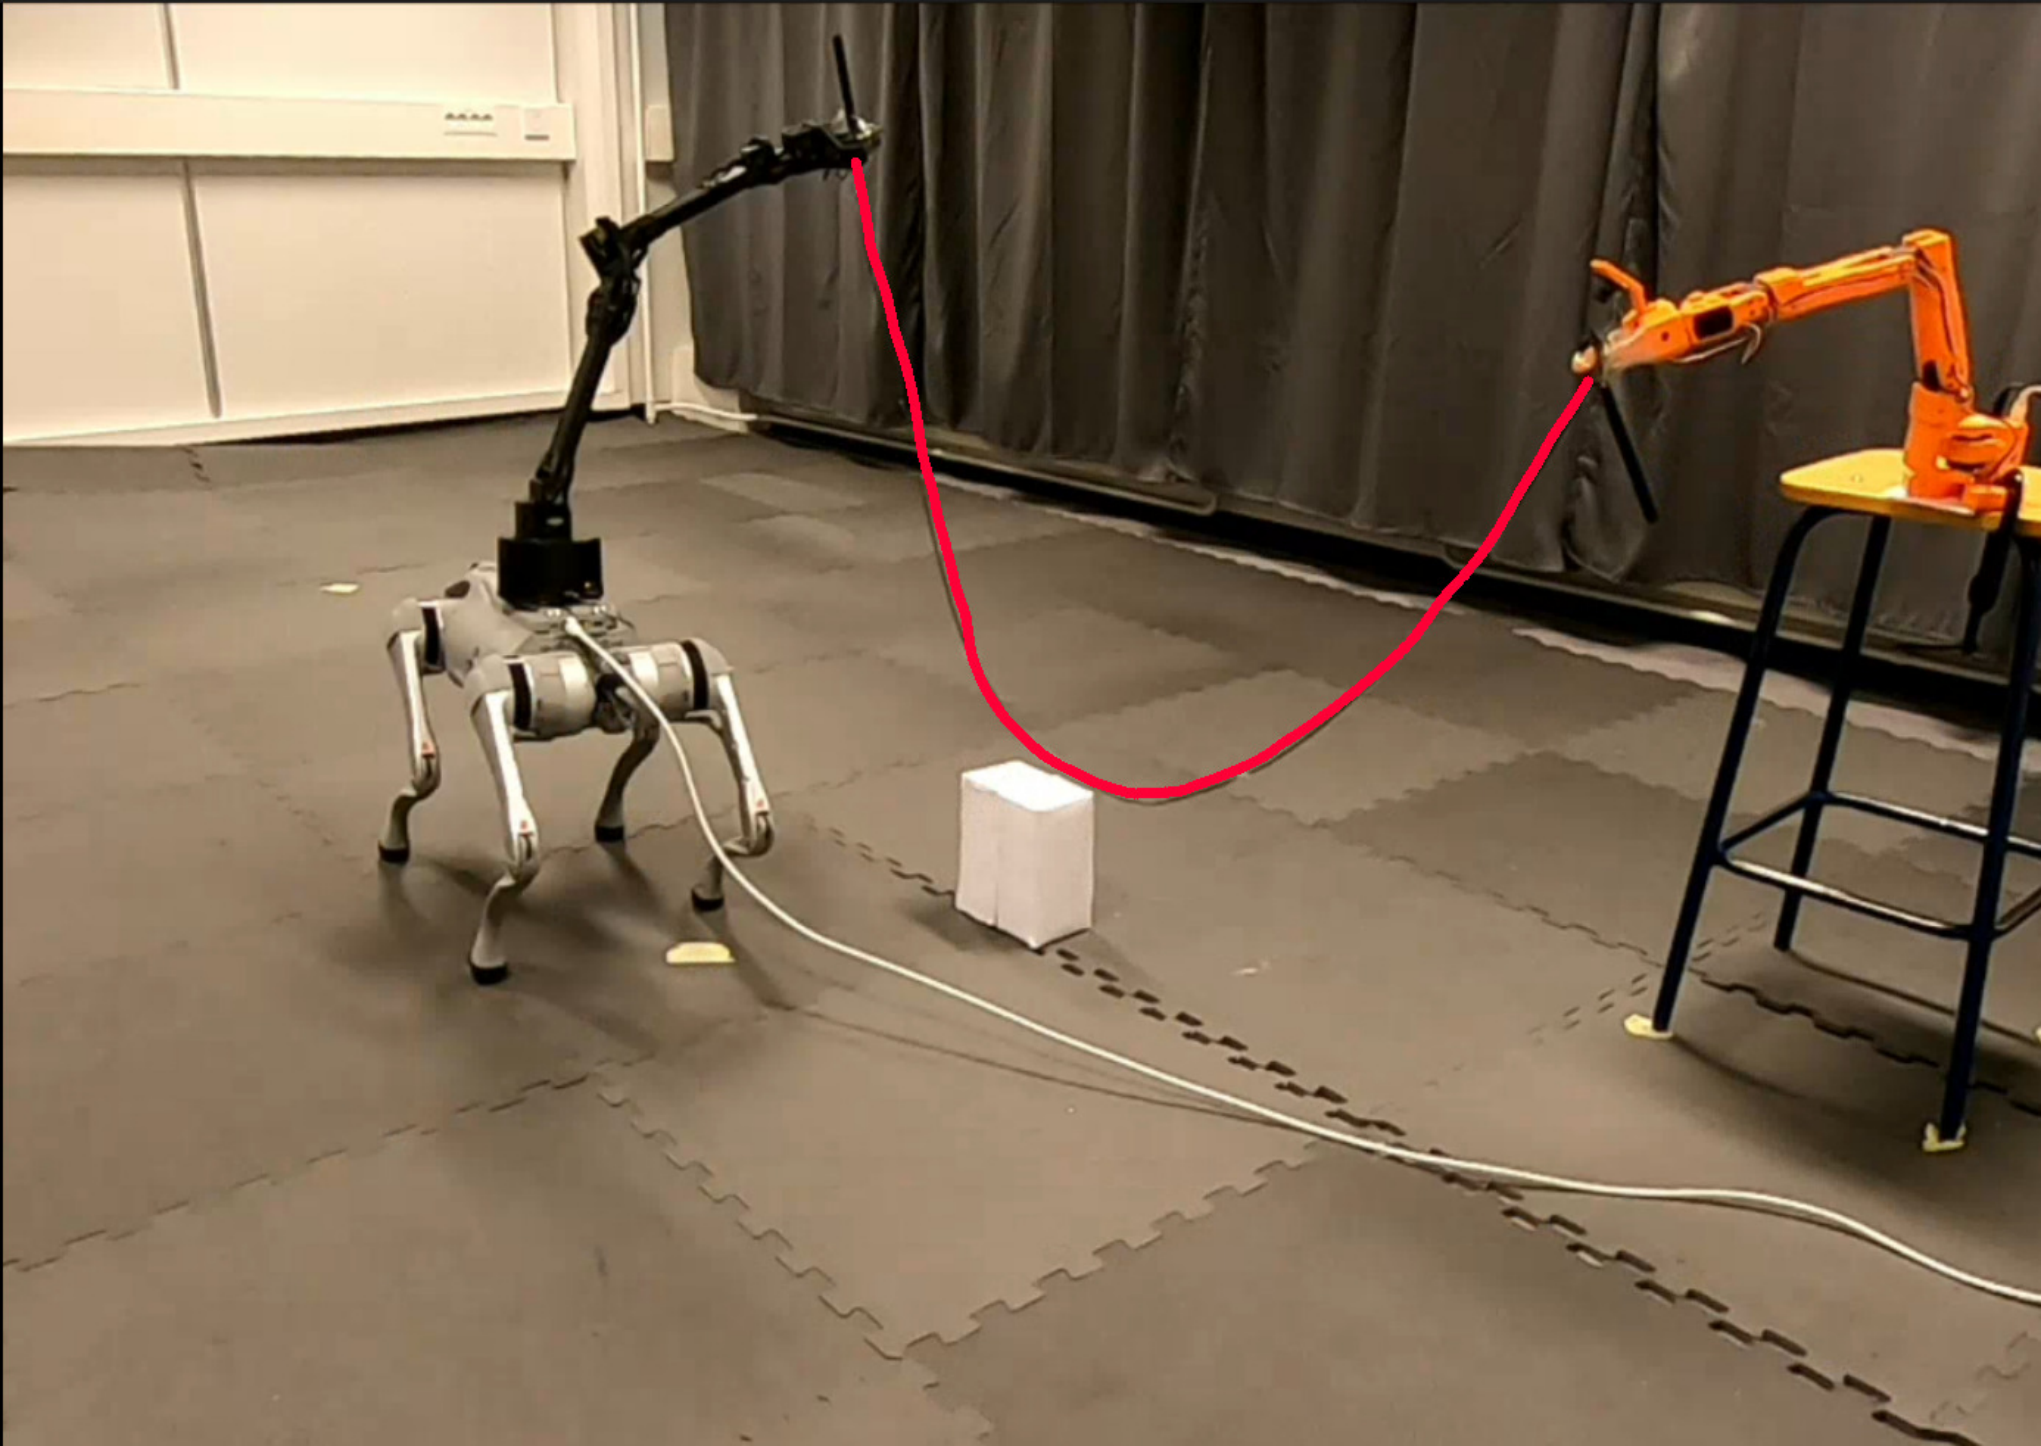
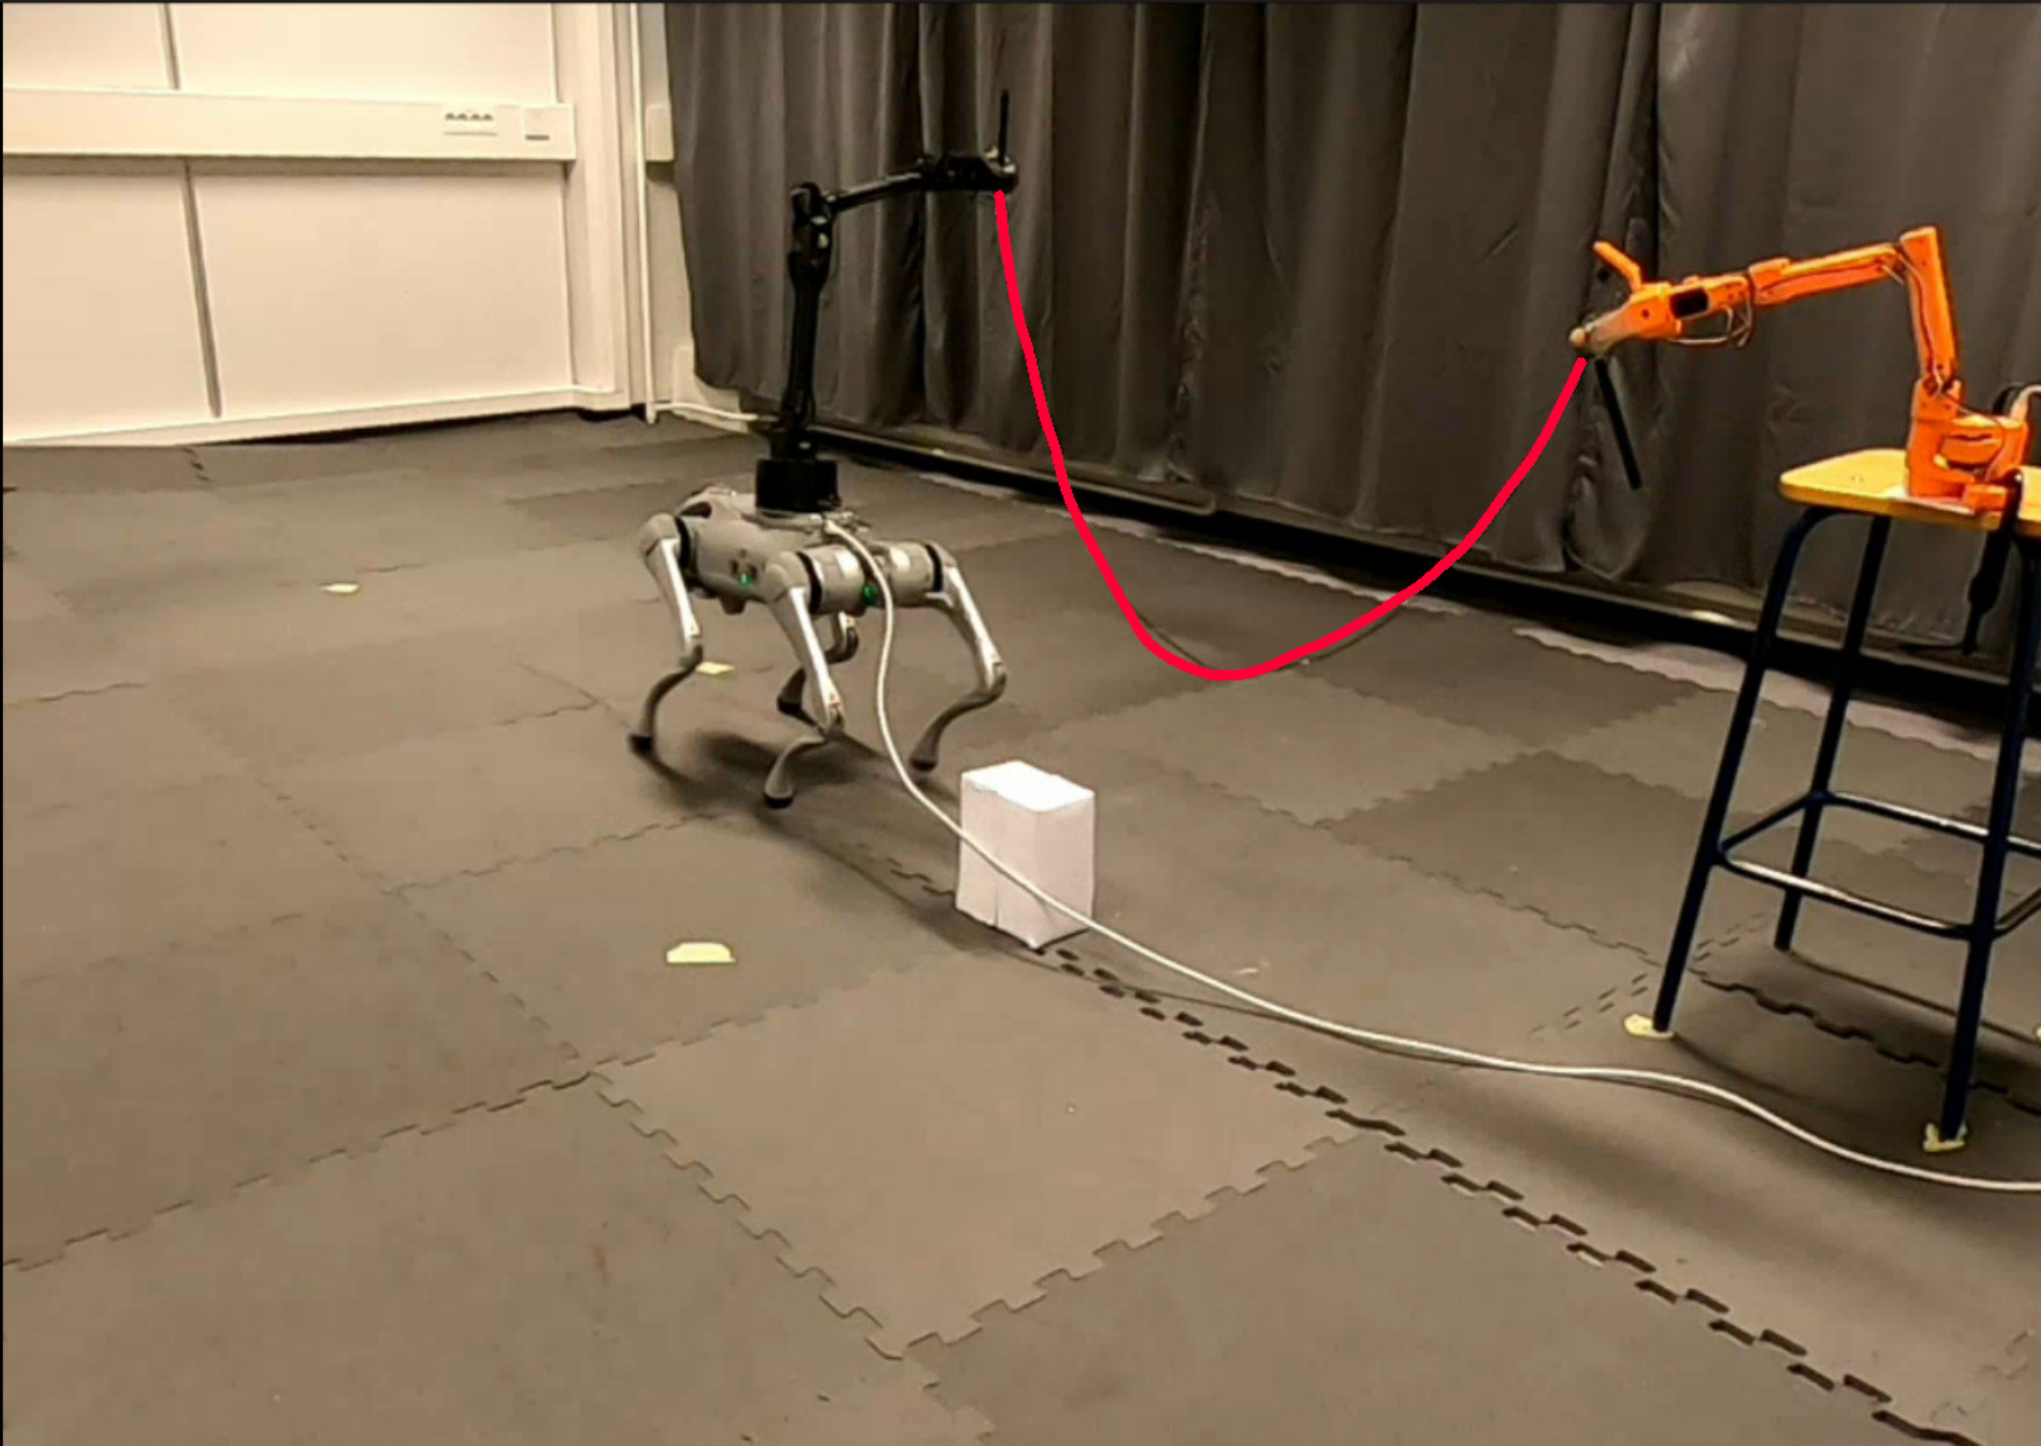
The proposed method is evaluated in three stages: (1) a rope simulation, assessing cRVAE’s prediction accuracy and its use in leader-follower obstacle avoidance (Section V-A ); (2) a fabric simulation, extending the evaluation to a 2D deformable object (Section V-B ); (3) real-world rope manipulation on a Unitree Go2 robot, assessing the framework on physical hardware under the sim-to-real and real-to-sim gap (Section V-C ).
Sources and Demonstrations
Figures are reproduced from Behnia et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
A Physics-Informed Collision Learning Framework for Collaborative Robot Motion Generation
Chen Cai, Steven Liu
Close-proximity multi-arm manipulation requires collision models that are both geometrically accurate and differentiable enough for real-time optimization.

AD-WM: Action-Discriminative World Models for Counterfactual Model Predictive Control
Jiabin Qiu, Zixuan Chen, Hongye Cao et al.
Latent world models are typically trained to predict factual transitions, whereas model predictive control (MPC) must compare alternative actions from the same state. A model can therefore achieve low factual prediction error yet poorly distinguish candidate actions.

AHEAD: Anticipatory Hand-Driven Teleoperation via Human Intent Prediction
Seok Joon Kim, Junho Lee, Federica Spinola et al.
Direct hand-driven teleoperation maps an operator's hand motion to robot end-effector commands at every frame, enabling precise control, but it requires constant monitoring and correction during approach, grasp, and placement, which can be slow and fatiguing.

Autonomous Droplet Navigation via Model-Based Reinforcement Learning: Zero-Shot Transfer and Emergent Dynamics
Rajneesh Anand, Mayuresh V. Kothare
Self-driving laboratories (SDLs) are transforming chemical and materials discovery through closed-loop automation, yet automated infrastructure for physical manipulation of soft, deformable matter remains beyond current robotic platforms.