
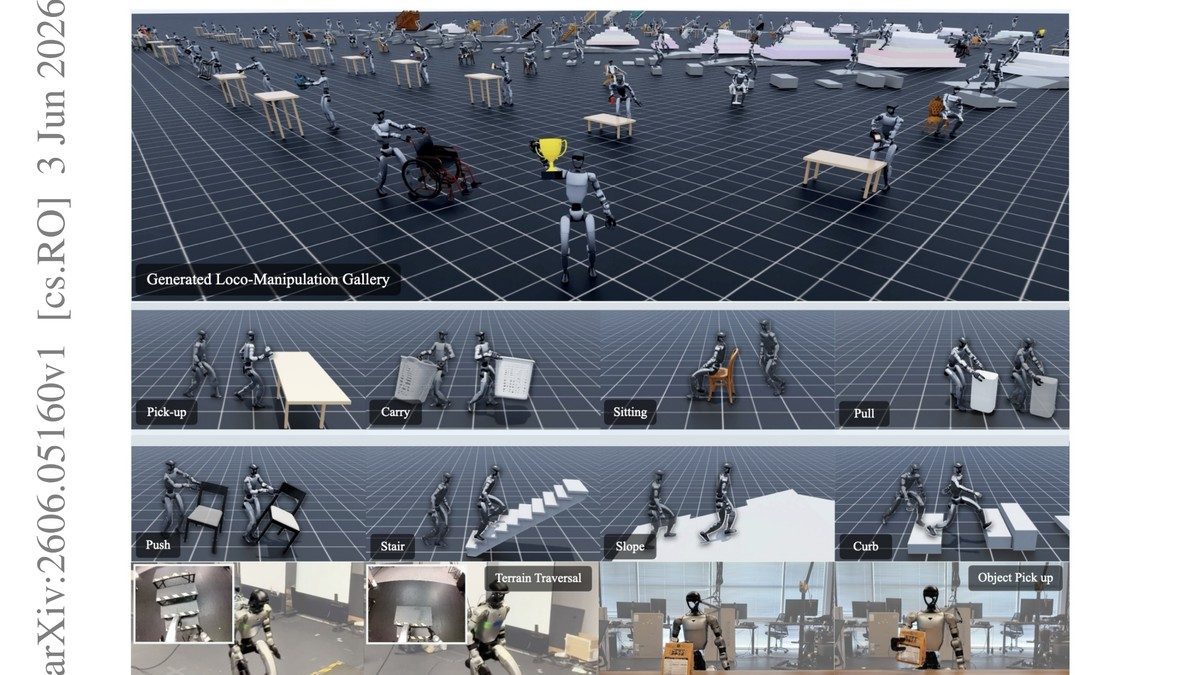
GRAIL: Generating Humanoid Loco-Manipulation from 3D Assets and Video Priors
FeaturedTianyi Xie, Haotian Zhang, Jinhyung Park, Zi Wang, Bowen Wen, Jiefeng Li, Xueting Li, Qingwei Ben, Haoyang Weng, Yufei Ye, David Minor, Tingwu Wang, Chenfanfu Jiang, Sanja Fidler, Jan Kautz, Linxi Fan, Yuke Zhu, Zhengyi Luo, Umar Iqbal, Ye Yuan · NVIDIA, UCLA · 2026
Framework
Python
License
N/A
Stars
275
Summary
Scaling humanoid loco-manipulation requires robot-compatible demonstrations across diverse objects, whole-body motions, and scene geometries, but teleoperation and motion capture are difficult to scale because each collection depends on physical setups, instrumented actors, and robot operation.
Abstract Summary
Key Points
- Demonstrates humanoid robot control on real hardware
- Addresses dexterous manipulation challenges
- Uses simulation or synthetic data for training
- Leverages 3D geometric reasoning for perception
- Enables complex whole-body climbing behaviors
- Learns multimodal motion skills from human demonstrations
Method
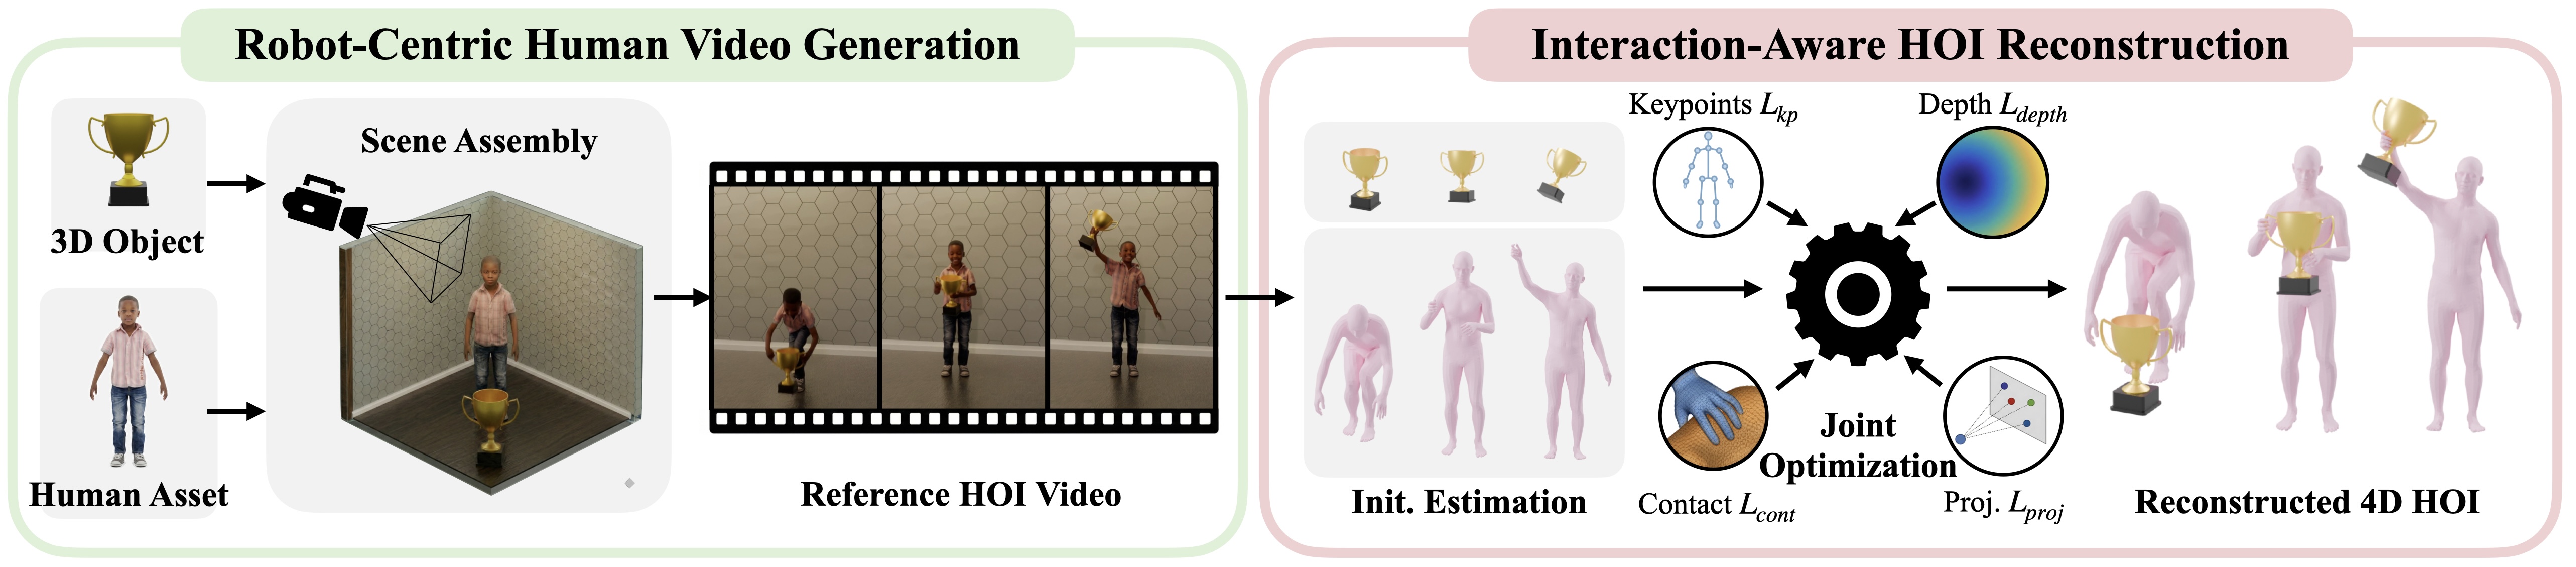
Given a 3D object asset $\mathcal{M}^{\mathcal{O}}$, GRAIL produces humanoid loco-manipulation demonstrations comprising humanoid kinematic motion $\{\bm{\Theta}^{\mathcal{R}}_{t}\}_{t=1}^{T}$, object kinematic motion $\{\bm{\Theta}^{\mathcal{O}}_{t}\}_{t=1}^{T}$, and robot actions $\{\bm{a}^{\mathcal{R}}_{t}\}_{t=1}^{T}$. Our data generation pipeline proceeds in three stages.
Results
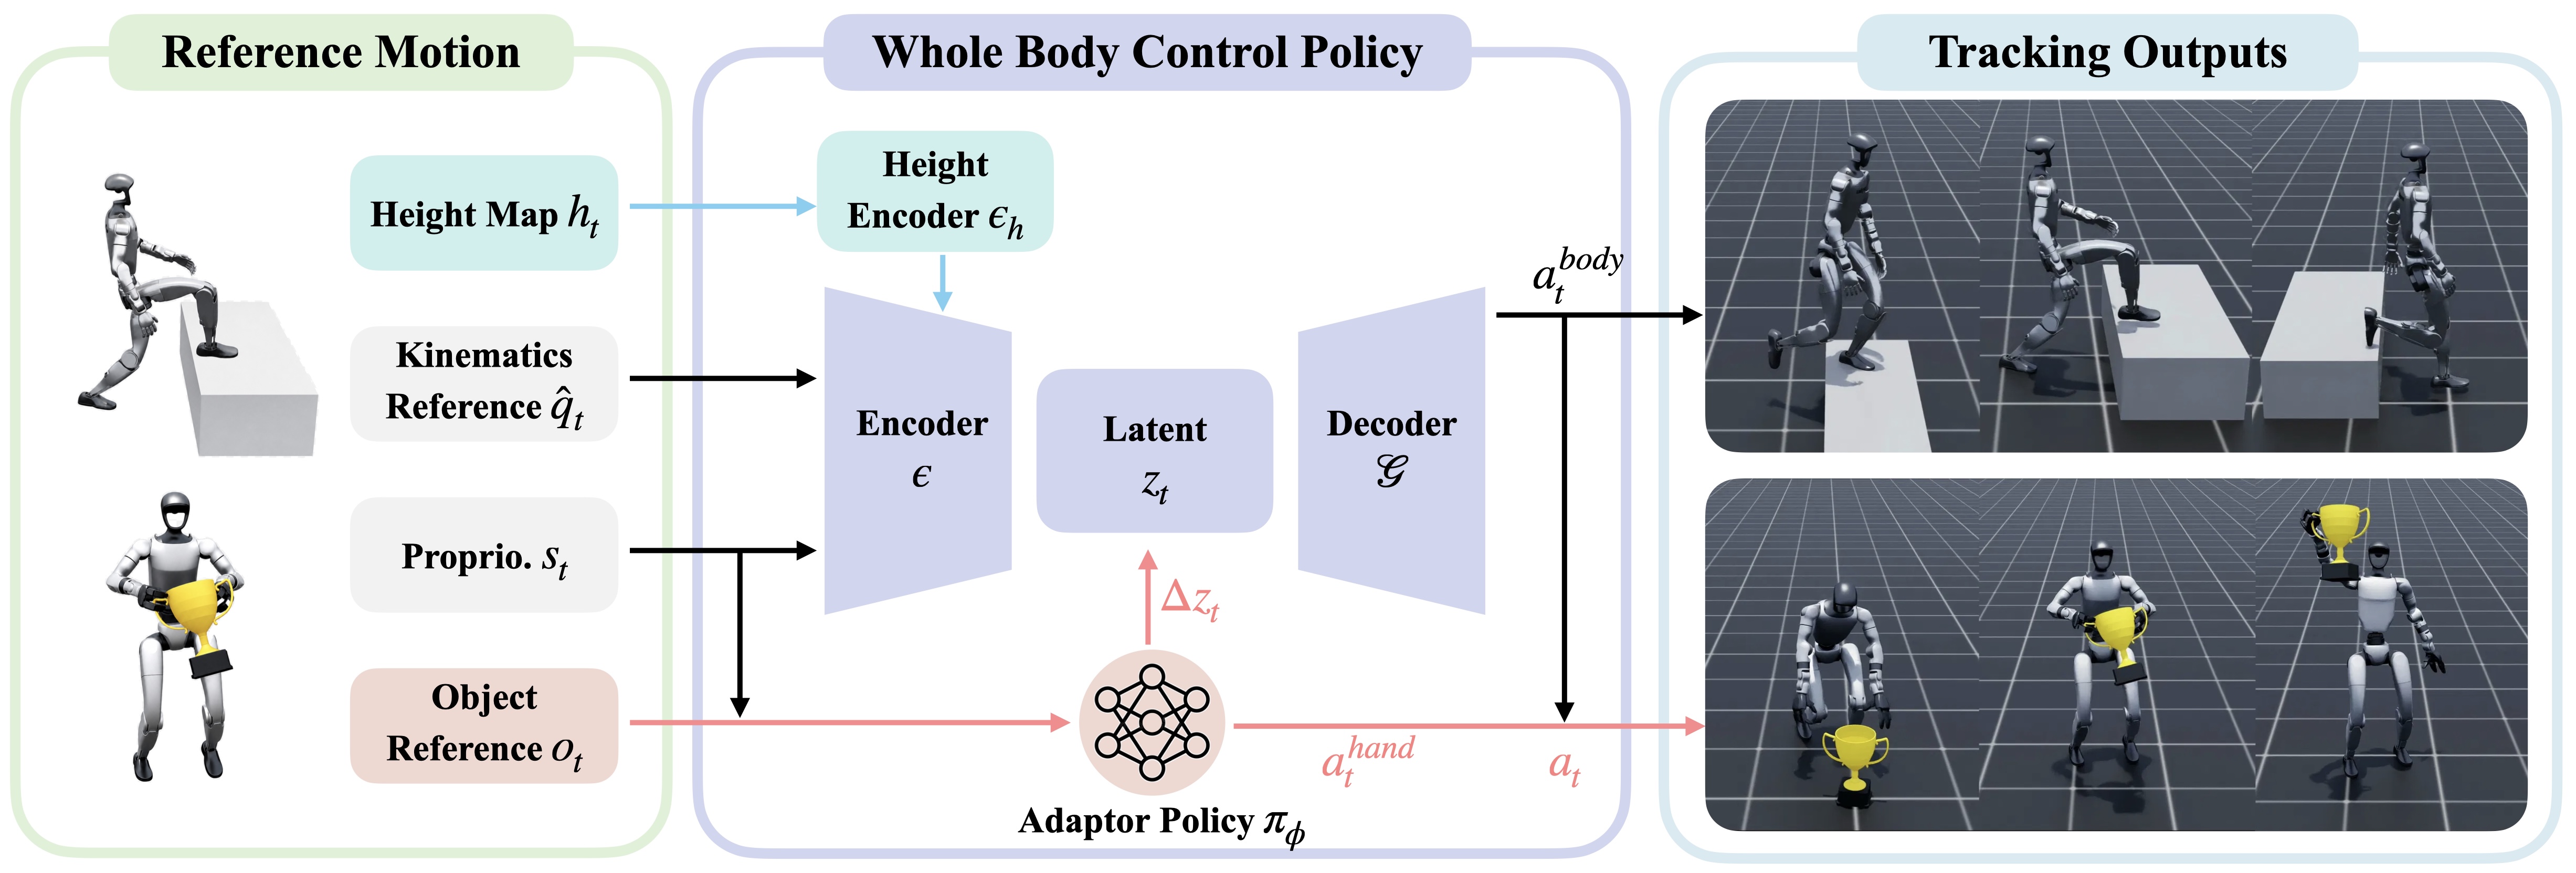
Our experiments cover the three stages of the GRAIL pipeline. We first evaluate whether the generated 4D HOI sequences are more physically executable than existing generation baselines. We then ask whether these 4D HOI sequences can be converted into task-general loco-manipulation policies at scale, rather than only replayed through per-sequence tracking.
Finally, we demonstrate the practical value of the generated data by deploying egocentric visual policies on the real robot for autonomous loco-manipulation. Setup.
Sources and Demonstrations
Figures are reproduced from Xie et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
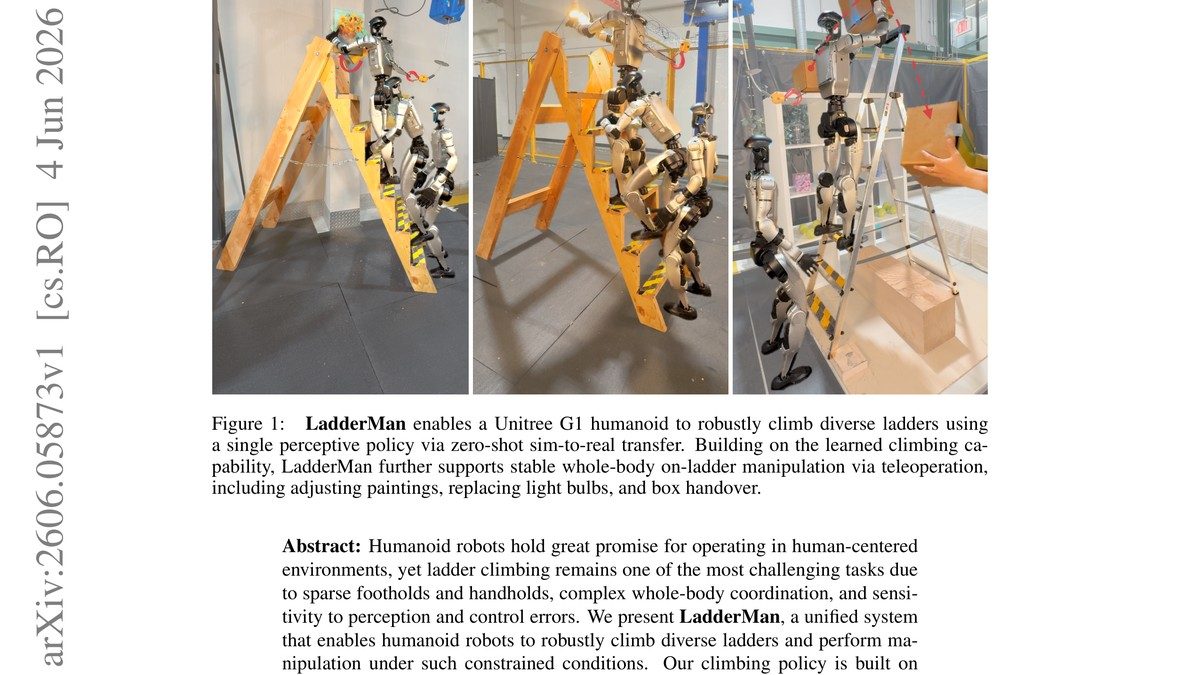
LadderMan: Learning Humanoid Perceptive Ladder Climbing
Siheng Zhao, Yuanhang Zhang, Ziqi Lu et al.
Humanoid robots hold great promise for operating in human-centered environments, yet ladder climbing remains one of the most challenging tasks due to sparse footholds and handholds, complex whole-body coordination, and sensitivity to perception and control errors.

3DThinkVLA: Endowing Vision-Language-Action Models with Latent 3D Priors via 3D-Thinking-Guided Co-training
Jiaxin Shi, Xidong Zhang, Fucai Zhu et al.
We propose a 3D-thinking-guided co-training framework that enables vision-language-action (VLA) models to perform 3D spatial reasoning implicitly during action prediction.

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.
Flash-WAM: Modality-Aware Distillation for World Action Models
Arman Akbari, Ci Zhang, Arash Akbari et al.
World-action models (WAMs) jointly generate future video and robot actions through iterative diffusion, achieving strong performance on manipulation benchmarks but requiring tens of denoising steps, a cost that precludes real-time control.