
From Imagined Futures to Executable Actions: Mixture of Latent Actions for Robot Manipulation
Yajie Li, Bozhou Zhang, Chun Gu, Zipei Ma, Jiahui Zhang, Jiankang Deng, Xiatian Zhu, Li Zhang · · 2026
Framework
N/A
License
N/A
Stars
0
Summary
Video foundation-models models offer a promising imagination mechanism for robot manipulation by predicting long-horizon future observations, but effectively exploiting these imagined futures for action execution remains challenging.
Abstract Summary
Key Points
- Introduces From Imagined Futures to Executable Actions, advancing vla research.
- Detailed evaluation demonstrates effectiveness on benchmarks and real-world scenarios.
- Provides insights into methodology and architectural choices.
Method
MoLA (Mixture of Latent Actions) is an imagination-based manipulation framework that uses MoIDM as a latent-action interface to transform predicted future visual trajectories into structured, executable action representations, as shown in Figure 2 . Given the current observation and task instruction, MoLA first employs a video generation model to synthesize future visual rollouts as an imagination space.
Experiments
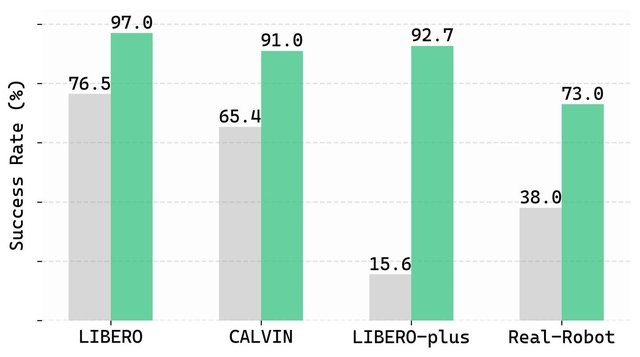
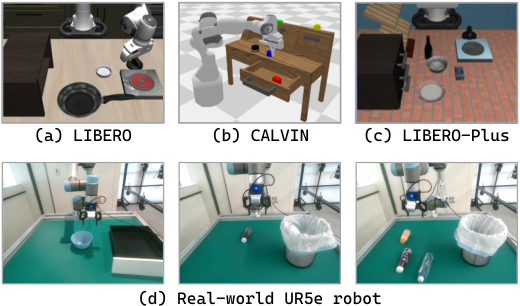
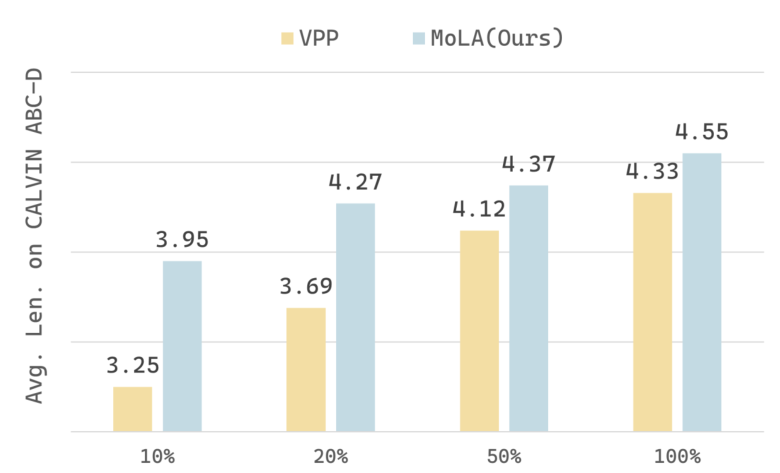
In this section, we perform extensive experiments in both simulated and real-world settings to evaluate the effectiveness of our MoLA, as illustrated in Figure 3 . Model and training details, detailed ablation tables, and qualitative analysis are provided in Appendix Sections A.1 , A.2 , and A.6 .
We evaluate our approach on three widely used robotic manipulation benchmarks: CALVIN ( Mees et al., 2022 ) , LIBERO ( Liu et al., 2023a ) , and LIBERO-Plus ( Fei et al., 2025 ) .
Sources and Demonstrations
Figures are reproduced from Li et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

DynaFLIP: Rethinking Robotics Perception via Tri-Modal-Dynamics Guided Representation
Jusuk Lee, Seungjae Lee, Jonghun Shin et al.
Robot manipulation critically depends on perception that preserves the action-relevant aspects of a scene. Yet most robot learning pipelines are built upon visual encoders pre-trained for static recog
GuidedVLA: Specifying Task-Relevant Factors via Plug-and-Play Action Attention Specialization
Xiaosong Jia, Bowen Yang, Zuhao Ge et al.
Vision-Language-Action (VLA) models aim for general robot learning by aligning action as a modality within powerful Vision-Language Models (VLMs). Existing VLAs rely on end-to-end supervision to implicitly enable the action decoding process to learn task-relevant features.
Qwen-VLA: Unifying Vision-Language-Action Modeling across Tasks, Environments, and Robot Embodiments
Qiuyue Wang, Mingsheng Li, Jian Guan et al.
Embodied intelligence is often studied through specialized models for individual tasks such as manipulation or navigation, resulting in fragmented capabilities and limited generalization across tasks,
Spatial Memory for Out-of-Vision Manipulation in Vision-Language-Action
Pengteng Li, Weiyu Guo, He Zhang et al.
SOMA introduces an explicit spatial memory framework that enables VLA models to track and manipulate objects even after they leave the camera's field of view.