
Spatial Memory for Out-of-Vision Manipulation in Vision-Language-Action
Pengteng Li, Weiyu Guo, He Zhang, Tiefu Cai, Xiao He, Yandong Guo, Hui Xiong · OPPO Research, BUPT, USTC · 2026
Summary
SOMA introduces an explicit spatial memory framework that enables VLA models to track and manipulate objects even after they leave the camera's field of view.
Abstract Summary
Key Points
- Introduces SOMA, a spatial memory augmentation for VLA models.
- Addresses occlusion and out-of-field-of-view manipulation failures.
- Uses object-centric memory buffer with cross-attention retrieval.
- Validated on simulated and real robot manipulation tasks.
- Maintains in-view performance while improving out-of-vision success rates.
Method
As shown in Figure 2 , SOMA addresses the challenge of out-of-vision manipulation by equipping VLA with a spatial memory that supports persistent scene understanding beyond the current camera view.
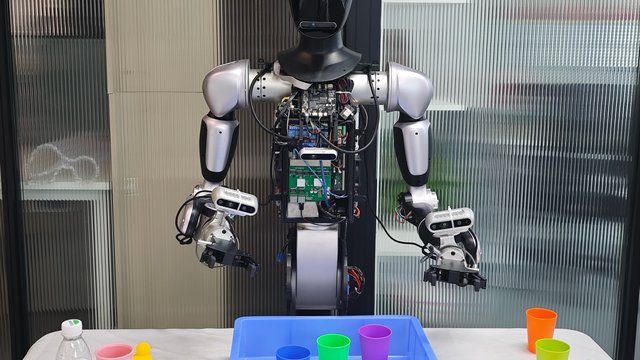
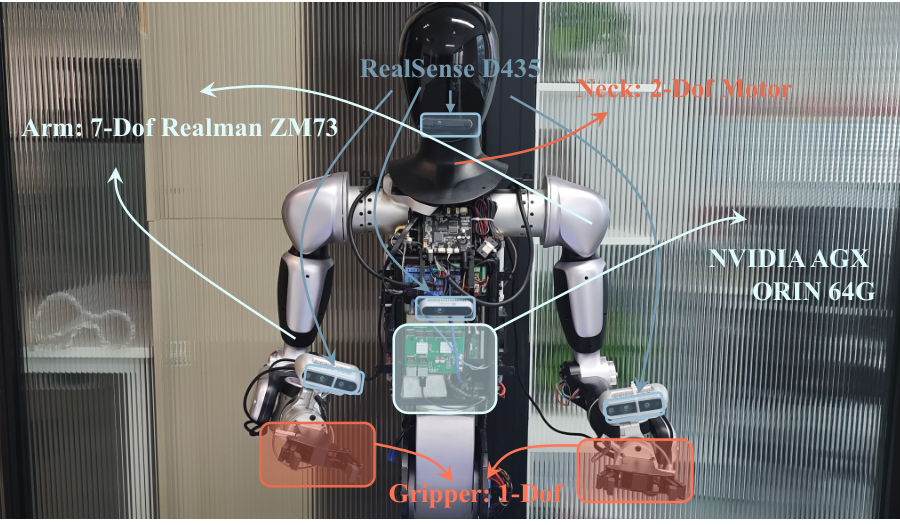
Prior to manipulation, if the target object referenced in the instruction cannot be localized in the current camera observation by the perception module, the robot performs a dedicated scene observation phase using a movable head camera to initialize Spatial Memory Construction .
Experiments
We conduct extensive real-world experiments to validate the effectiveness of SOMA in OOV manipulation. We further evaluate its memory-centric design on RoboCasa Tabletop GR1 ( Bjorck et al., 2025 ) and SimplerEnv ( Li et al., 2024 ) . Real World OOV Tasks.
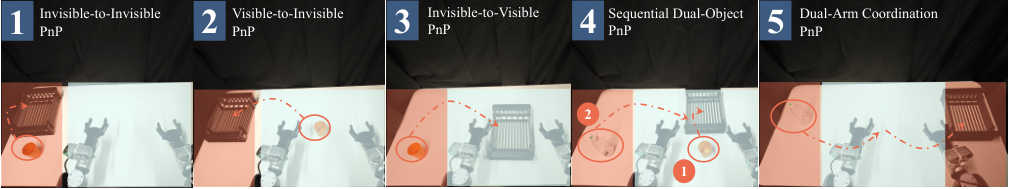
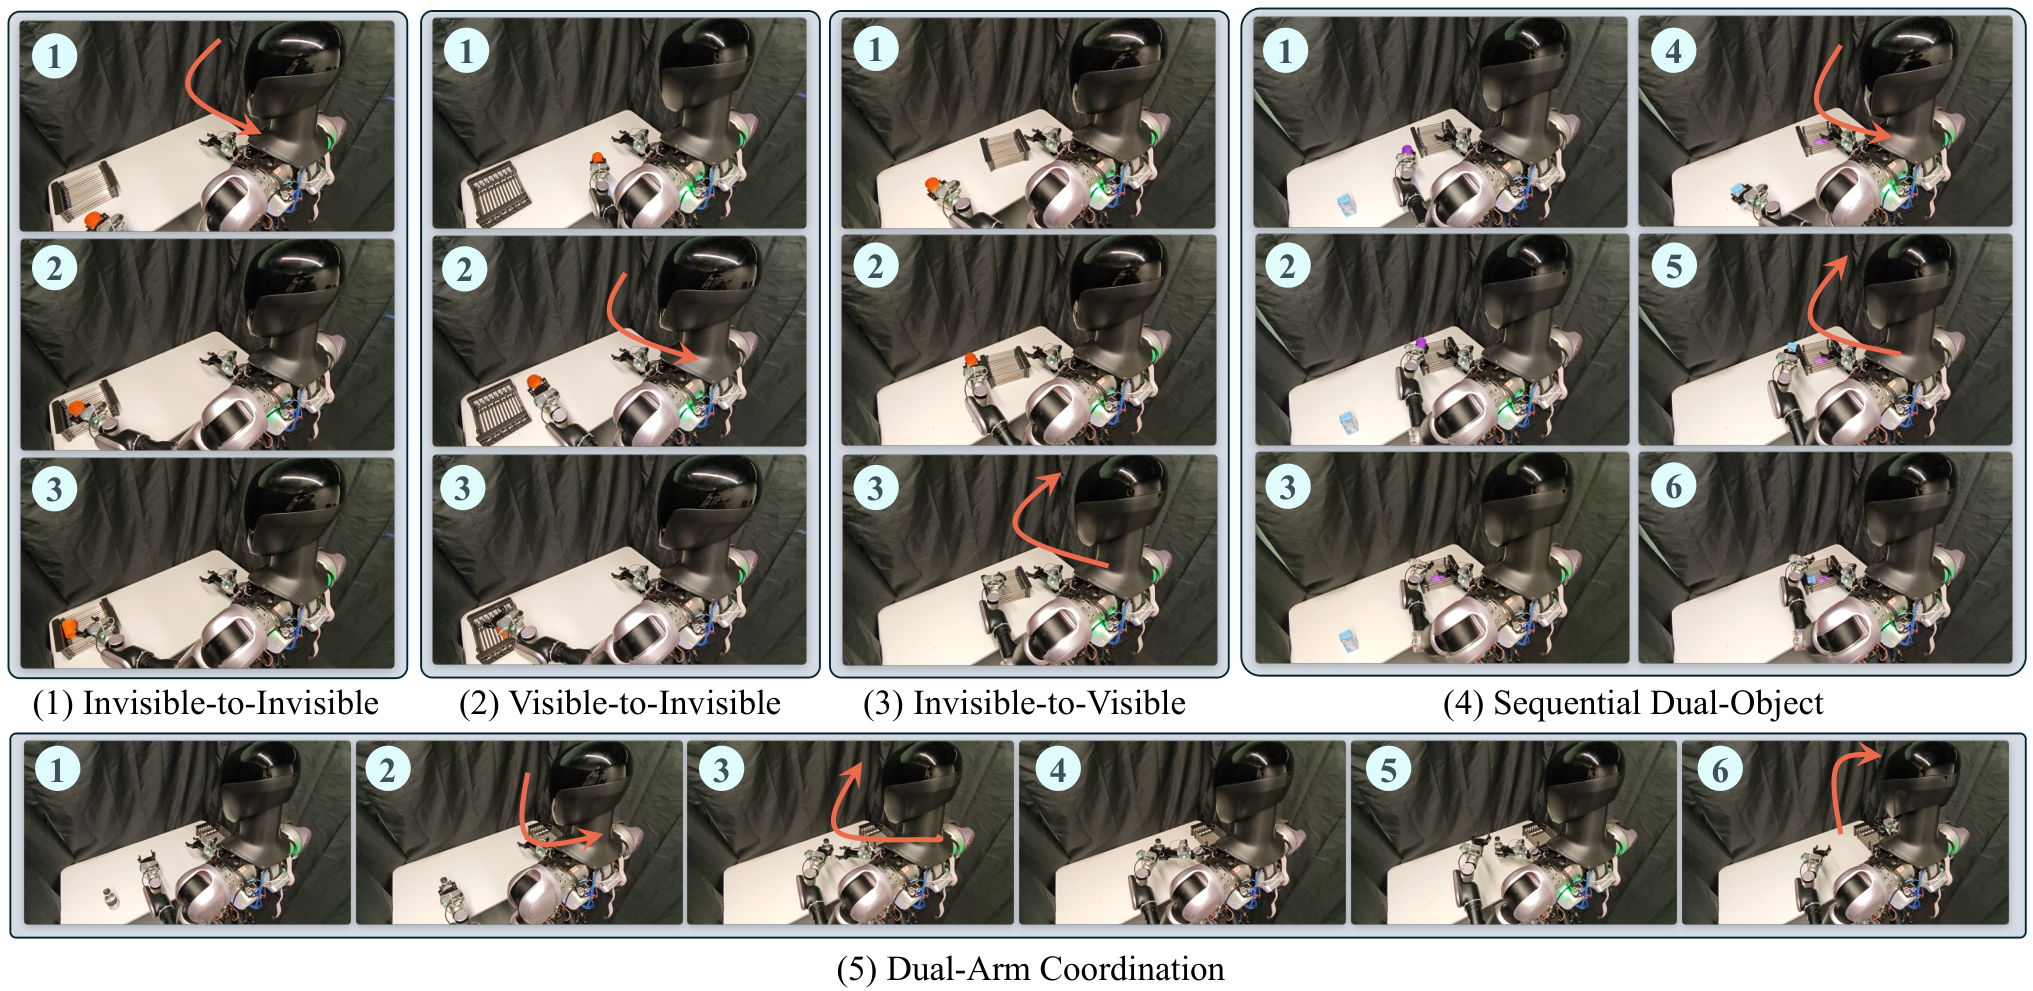
As shown in Figure 3 and 5 , we construct a real-world benchmark of five out-of-vision pick-and-place (PnP) tasks with increasing difficulty to evaluate SOMA under partial observability.
mpact Statement
This work addresses the challenge of manipulation under limited operational field of view by introducing a spatial memory framework that enables robots to reason about and act on objects beyond the current camera view.
By integrating multi-view scene exploration, persistent spatial memory, and contextual interaction, the proposed approach improves robustness in long-horizon manipulation tasks where relevant objects cannot be directly observed at execution time.
Sources and Demonstrations
Figures are reproduced from Li et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

DynaFLIP: Rethinking Robotics Perception via Tri-Modal-Dynamics Guided Representation
Jusuk Lee, Seungjae Lee, Jonghun Shin et al.
Robot manipulation critically depends on perception that preserves the action-relevant aspects of a scene. Yet most robot learning pipelines are built upon visual encoders pre-trained for static recog
GuidedVLA: Specifying Task-Relevant Factors via Plug-and-Play Action Attention Specialization
Xiaosong Jia, Bowen Yang, Zuhao Ge et al.
Vision-Language-Action (VLA) models aim for general robot learning by aligning action as a modality within powerful Vision-Language Models (VLMs). Existing VLAs rely on end-to-end supervision to implicitly enable the action decoding process to learn task-relevant features.
From Imagined Futures to Executable Actions: Mixture of Latent Actions for Robot Manipulation
Yajie Li, Bozhou Zhang, Chun Gu et al.
Video foundation-models models offer a promising imagination mechanism for robot manipulation by predicting long-horizon future observations, but effectively exploiting these imagined futures for action execution remains challenging.
Qwen-VLA: Unifying Vision-Language-Action Modeling across Tasks, Environments, and Robot Embodiments
Qiuyue Wang, Mingsheng Li, Jian Guan et al.
Embodied intelligence is often studied through specialized models for individual tasks such as manipulation or navigation, resulting in fragmented capabilities and limited generalization across tasks,