Octo: An Open-Source Generalist Robot Policy

Octo: An Open-Source Generalist Robot Policy

Featured

Dibya Ghosh, Homer Walke, Karl Pertsch, Kevin Black, Oier Mees, Sudeep Dasari, Joey Hejna, Tobias Kreiman, Charles Xu, Jianlan Luo, You Liang Tan, Lawrence Yunliang Chen, Pannag Sanketi, Quan Vuong, Ted Xiao, Dorsa Sadigh, Chelsea Finn, Sergey Levine · UC Berkeley, Stanford, TRI · 2024

Framework

JAX / Flax

License

MIT

Stars

1,652

Summary

Octo is a large open-source transformer-based generalist robot policy trained on 800k trajectories, supporting language-conditioned and goal-image-conditioned control across 9 robotic platforms with efficient fine-tuning on consumer GPUs.

Abstract Summary

Octo addresses a critical gap in robot foundation models: while proprietary generalist policies like RT-2 showed impressive results, there was no open-source alternative that researchers could freely fine-tune, inspect, and modify. Octo fills this niche. Trained on 800,000 trajectories from the Open X-Embodiment dataset, Octo is a transformer-based policy capable of conditioning on language commands or goal images and generating actions for diverse sensor and actuator configurations. It supports both visual and proprioceptive observations and can output continuous robot actions at interactive rates. The architecture is designed for practical flexibility. Unlike prior work that couples the policy tightly to specific robot hardware, Octo employs an observation-action tokenizer that projects heterogeneous sensor streams into a common token space. This means the same pretrained backbone can be fine-tuned to a new robot with different camera counts, image resolutions, or action dimensions in just a few hours on a single consumer GPU. The authors demonstrate this cross-platform capability on 9 robotic platforms, ranging from low-cost WidowX arms to Franka Research robots and mobile manipulators, confirming that Octo serves as an effective policy initialization across the board. Training at this scale required careful engineering. The authors release their full pre-training pipeline, including data loading, tokenization, and distributed training scripts, all built on top of JAX and Flax. They conduct extensive ablations on architectural choices—such as whether to condition on language tokens early or late in the transformer stack—and on dataset curation, finding that data diversity and quality filtering matter more than sheer scale for generalization. These ablation studies provide valuable guidance for future efforts in building generalist robot models. Empirically, Octo achieves competitive or superior performance compared to prior open methods and serves as a strong initialization for downstream tasks. When fine-tuned on a small amount of in-domain data, it quickly adapts to new manipulation skills, object geometries, and environments that were not present in the pre-training dataset. The authors also provide a Hugging Face integration, making it possible to download pretrained weights and fine-tune models with a few lines of Python. For the robot learning community, Octo represents a foundational open generalist policy that can be used as a starting point for a wide variety of research projects.

Key Points

  • Large open-source generalist policy trained on 800k trajectories from Open X-Embodiment.
  • Supports language and goal-image conditioning with a flexible transformer architecture.
  • Observation-action tokenizer enables cross-robot fine-tuning on consumer GPUs within hours.
  • Evaluated on 9 distinct robot platforms with strong few-shot transfer to new tasks.
  • Full training and fine-tuning stack released in JAX/Flax with Hugging Face integration.

The Octo Model

In this section, we describe the Octo model, our open-source generalist robot policy that can be adapted to new robots and tasks — including new sensory inputs and action spaces — via finetuning. We discuss the key design decisions, training objectives, training dataset, and infrastructure.

The design of the Octo model emphasizes flexibility and scale: it supports a variety of commonly used robots, sensor configurations, and actions while providing a generic and scalable recipe that can be trained on large amounts of data.
The Octo Model — Octo: An Open-Source Generalist Robot Policy
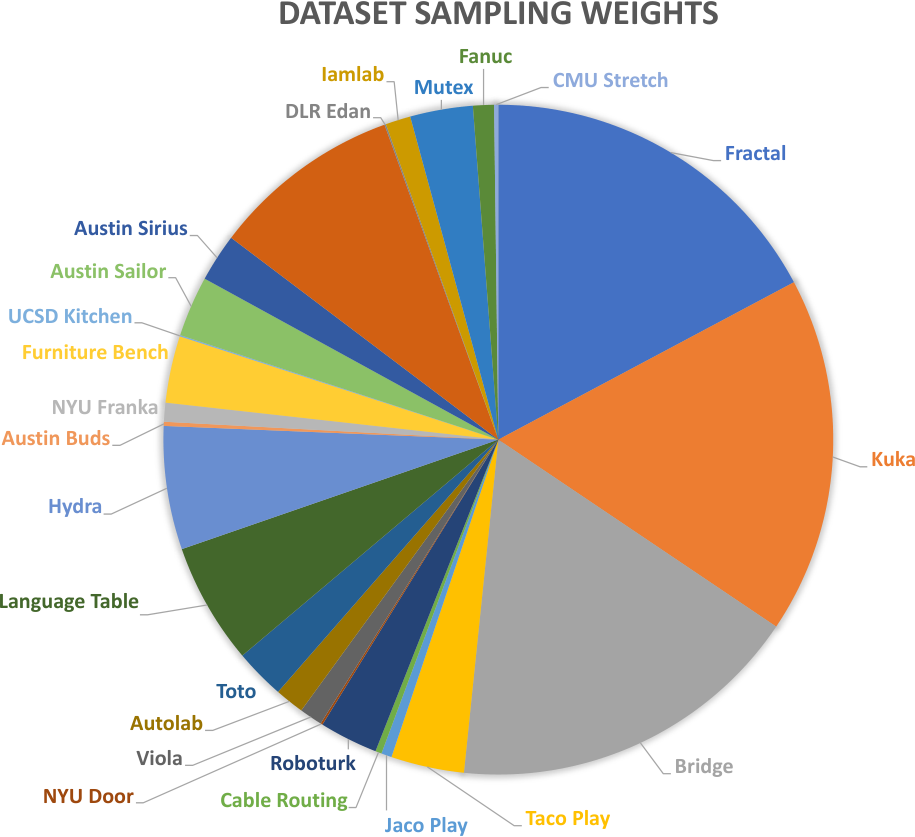
Fig. 2: Training dataset composition. We curate a subset of 25 datasets from the Open X-Embodiment dataset that have image observations, end-effector actions, and show diverse behaviors. The pie chart visualizes the fractions that each dataset contributes to every training batch on average. The dataset weights are determined by the number of samples in each dataset with small modifications to balance dataset size and diversity (see Section III-B for details).

Experiments

Our experiments provide an empirical analysis of Octo, evaluating its ability to serve as a general robotic foundation model across several axes: Can Octo control multiple robot embodiments and solve language and goal tasks out of the box?

Do Octo weights serve as a good initialization for data-efficient finetuning to new tasks and robots, and does it improve over training from scratch and commonly used pretrained representations? Which design decisions in Octo matter most for building generalist robot policies? We evaluate Octo’s capabilities...
Experiments — Octo: An Open-Source Generalist Robot Policy
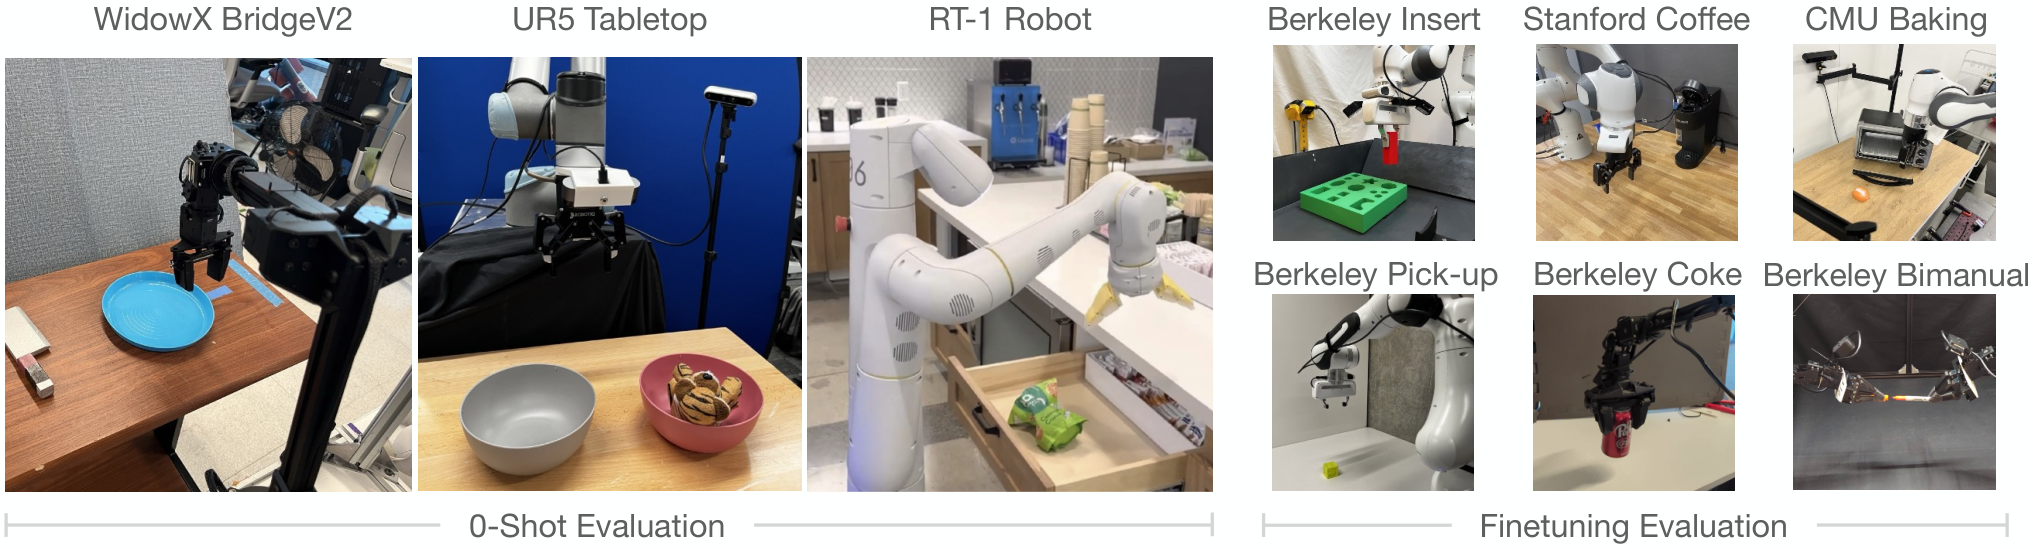
Fig. 3: Evaluation Tasks. We evaluate Octo on 9 real robot setups across 4 institutions. Our evaluations capture diverse object interactions (e.g., “WidowX BridgeV2”), long task horizons (e.g., “Stanford Coffee”) and precise manipulation (e.g., “Berkeley Peg Insertion”). We evaluate Octo’s capabilities to control robots in environments from the pretraining data out-of-the-box and to efficiently finetune to new tasks and environments with small target domain datasets. We also test finetuning with new observations (force-torque inputs for “Berkeley Peg Insertion”), action spaces (joint position control in “Berkeley Pick-Up” and “Berkeley Bimanual”) and new robot embodiments (e.g., “Berkeley Bimanual” and “Berkeley Coke”).

Sources and Demonstrations

Figures are reproduced from Ghosh et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.

Share

Related Papers

DROID: A Large-Scale In-the-Wild Robot Manipulation Dataset
RSS 2024

DROID: A Large-Scale In-the-Wild Robot Manipulation Dataset

Alexander Khazatsky, Karl Pertsch, Suraj Nair et al.

A 350-hour dataset of diverse real-world robot manipulation across 22 robots in 71 scenes, designed to train scalable and generalist imitation learning policies.
imitation-learning manipulation foundation-models
Code PDF Advanced
GitHub ★ 362 Updated May 2026
LeRobot: A Library for Real-World Robot Learning
NeurIPS 2024 Workshop

LeRobot: A Library for Real-World Robot Learning

Remi Cadene, Simon Alibert, Alexander Soare et al.

Hugging Face's LeRobot is an open-source PyTorch framework providing pretrained models, datasets, and training scripts for imitation and reinforcement learning on real robots, lowering the entry barrier to robot learning.
imitation-learning rl foundation-models manipulation
Code PDF Beginner
GitHub ★ 24,333 Updated May 2026
Open X-Embodiment: Robotic Learning Datasets and RT-X Models
arXiv

Open X-Embodiment: Robotic Learning Datasets and RT-X Models

Open X-Embodiment Collaboration

The largest collaborative robot learning dataset ever assembled, spanning 22 robots from 21 institutions, enabling training of generalist RT-X policies that exhibit positive cross-embodiment transfer.

imitation-learning foundation-models manipulation dataset
Code PDF Intermediate
GitHub ★ 1,853 Updated May 2026