
$ω$-0: A Latent Predictive World Action Model for Concurrent Humanoid Loco-Manipulation
Zhe Li, Zhenzhe Zhang, Yangyang Wei, Wenjie Zhang, Xichen Yuan, Peiyuan Zhi, Gen Li, Xinying Guo, Fengjie Gao, Jianfei Yang, Shanghang Zhang · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Humanoid household tasks often require concurrent loco-manipulation, where the robot must move, adjust posture, maintain balance, and manipulate objects as a single coordinated behavior.
Abstract Summary
Key Points
- Humanoid household tasks often require concurrent loco-manipulation, where the robot must move, adjust posture, maintain balance, and manipulate objects as a single coordinated behavior.
- Yet existing humanoid policies typically decompose locomotion and manipulation, while recent world-action models remain either arm-centric or video-centered.
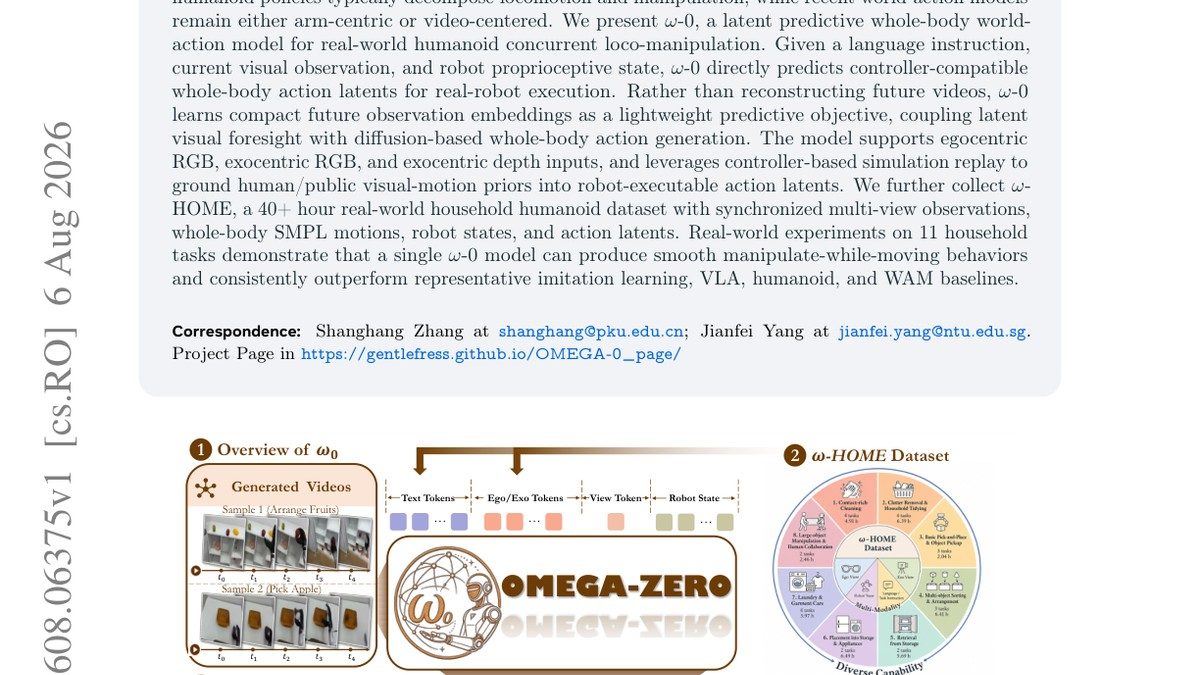
- We present $ω$-0, a latent predictive whole-body world-action model for real-world humanoid concurrent loco-manipulation.
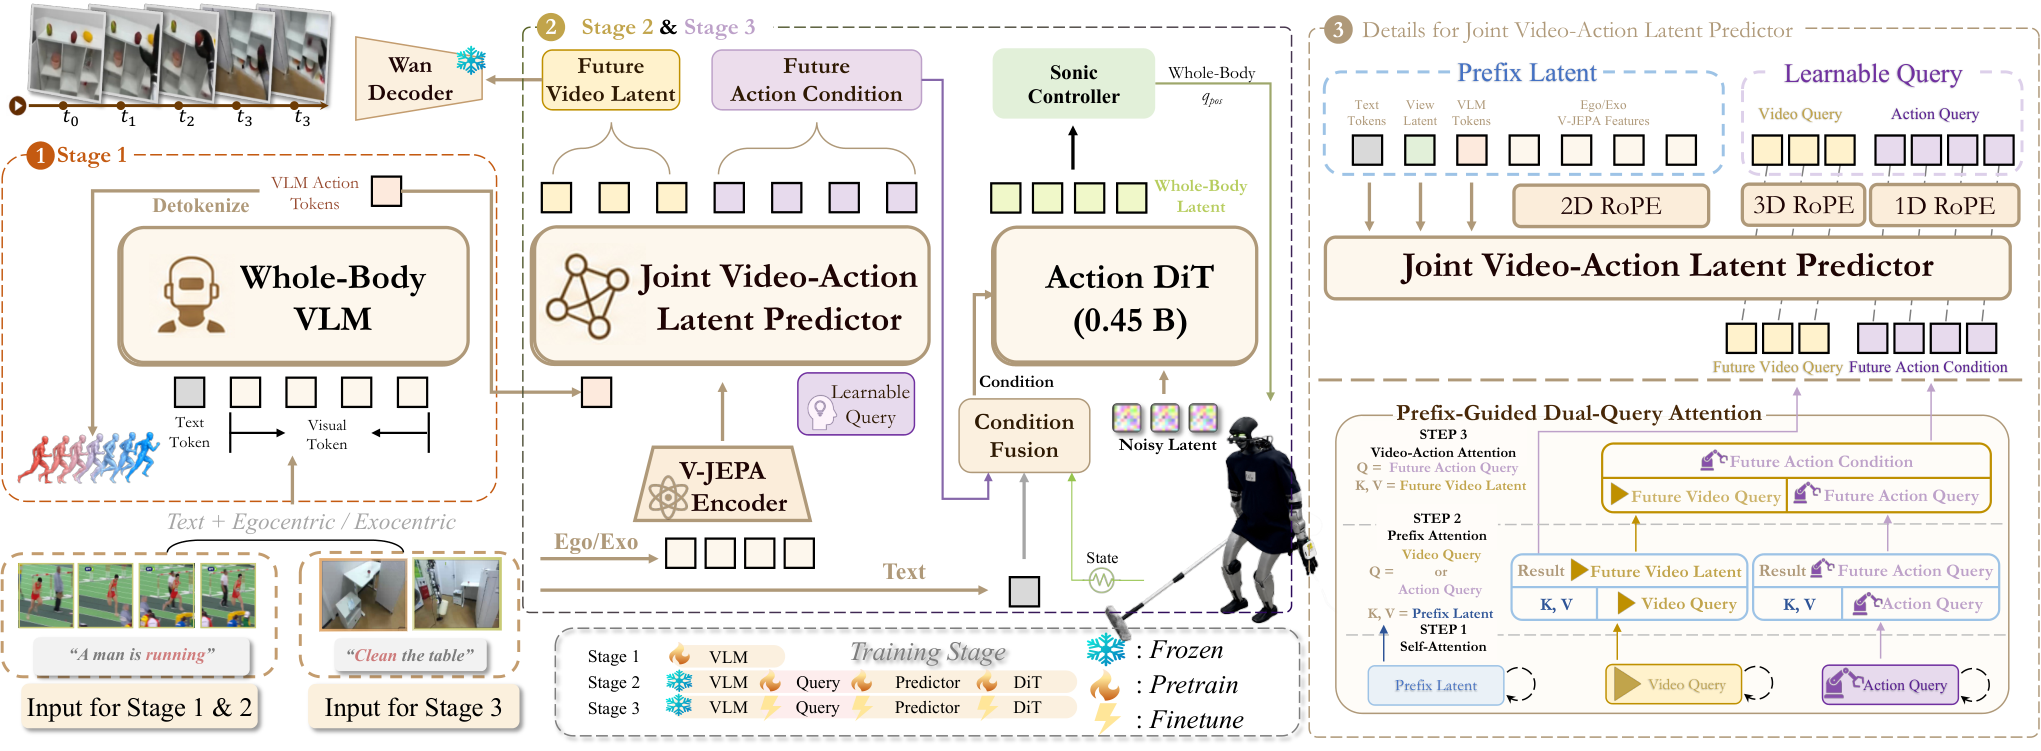
- Given a language instruction, current visual observation, and robot proprioceptive state, $ω$-0 directly predicts controller-compatible whole-body action latents for real-robot execution.
- Rather than reconstructing future videos, $ω$-0 learns compact future observation embeddings as a lightweight predictive objective, coupling latent visual foresight with diffusion-based whole-body action generation.
Method
This section presents the core components of $\omega$-0, as illustrated in Figure 2 . We first introduce the overall architecture and problem formulation in Section 3.1 . Section 3.2 describes whole-body action VLM pretraining, where continuous humanoid actions are converted into discrete action tokens for autoregressive visual-language learning.
Section 3.3 introduces human-to-humanoid action-latent pretraining, which aligns future visual latent prediction with diffusion-based whole-body action generation.
ω \omega -HOME Dataset
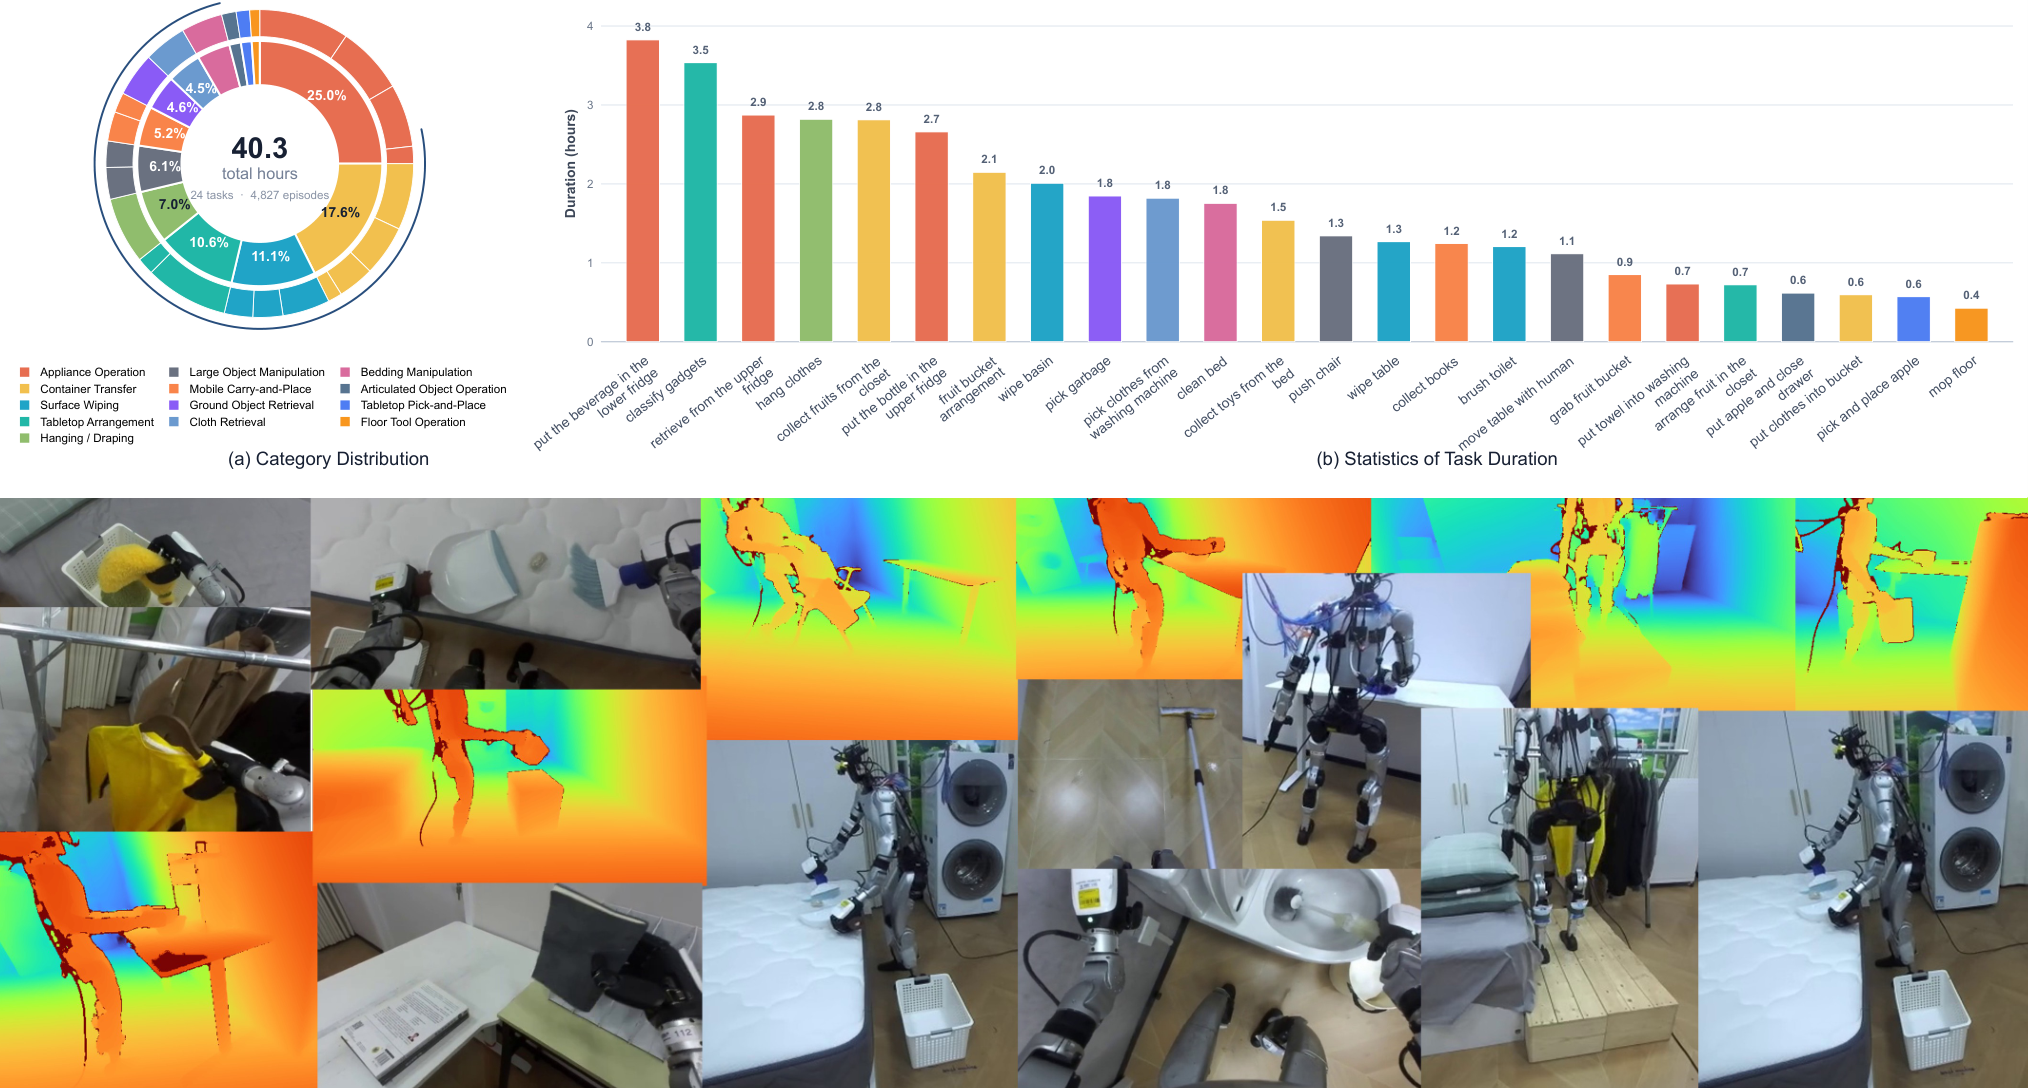
Real-world data for humanoid loco-manipulation remains limited, especially for household tasks that require coordinated locomotion, posture adjustment, dexterous manipulation, and interaction with furniture or tools.
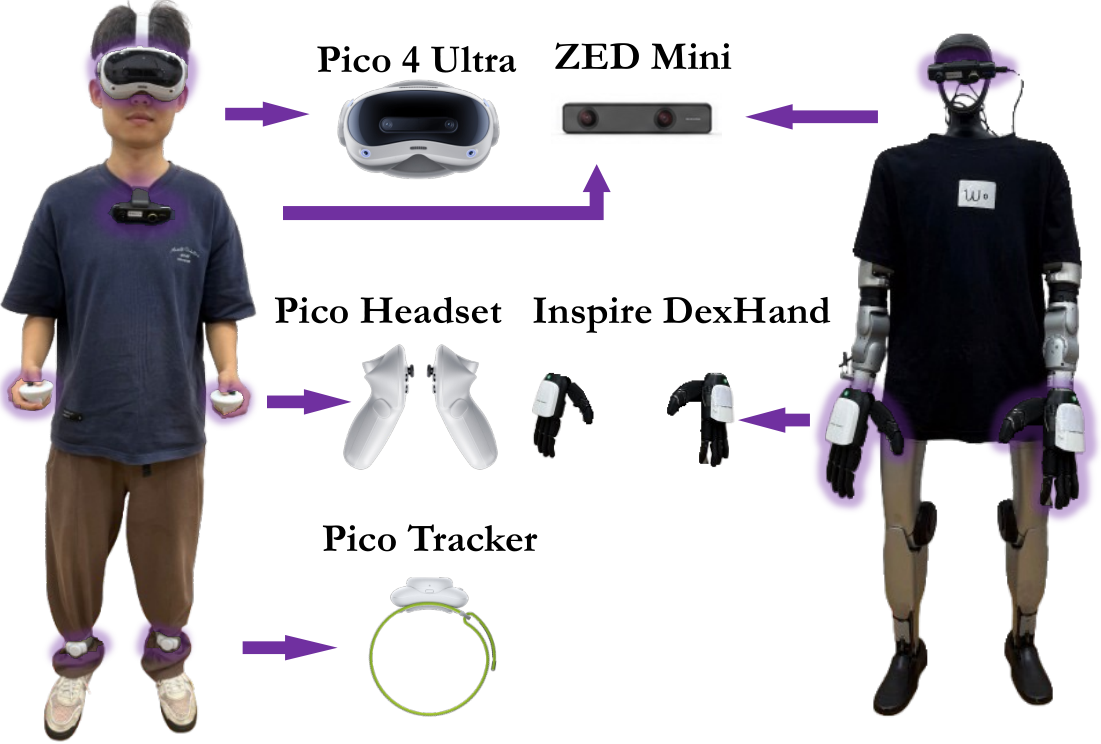
To support learning whole-body world-action models in realistic domestic environments, we collect $\omega$-HOME, a multimodal household humanoid dataset containing 40.3 hours of demonstrations, 4,827 episodes, and 24 tasks recorded at 30 Hz.
Implementation and Experiments
Whole-body action data with paired visual observations remains limited, especially for models that must operate from both egocentric and exocentric views. To build a viewpoint-flexible whole-body action model, we combine three public datasets: ARCTIC ( Fan et al., 2023 ) , Xperience-10M ( Ropedia, 2026 ) , and Motion-X ( Zhang et al., 2025 ) .
ARCTIC contains both egocentric and exocentric videos, making it useful for learning view-conditioned action prediction.
Implementation Details
We implement $\omega$-0 with Qwen3-VL-2B-Instruct as the whole-body action VLM, a frozen V-JEPA image encoder for visual latent extraction, and a pretrained T5 encoder for language features. The whole-body FAST tokenizer is trained on the unified SMPL motion representation and is used to convert continuous whole-body action trajectories into discrete action tokens for Stage-1 VLM pretraining.
Sources and Demonstrations
Figures are reproduced from Li et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
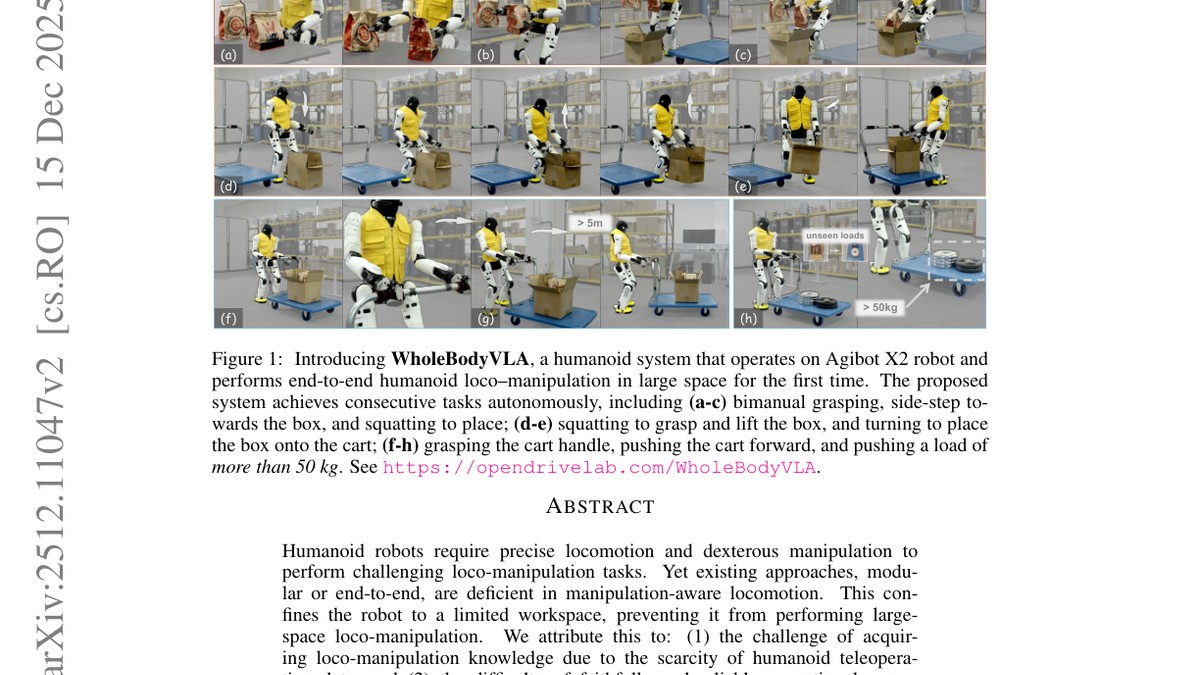
WholeBodyVLA: Towards Unified Latent VLA for Whole-Body Loco-Manipulation Control
Haoran Jiang, Jin Chen, Qingwen Bu et al.
Humanoid robots require precise locomotion and dexterous manipulation to perform challenging loco-manipulation tasks. Yet existing approaches, modular or end-to-end, are deficient in manipulation-aware locomotion.

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.

Capability-Aware Arbitration for Semantic Intent-Based Shared Control
Zhaoda Du, Michael Bowman, Xiaoli Zhang
Shared control often allocates robot authority based on confidence in inferred human intent, assuming reliable autonomous execution. When this assumption fails, high intent confidence can cause over-helping.

DexVerse: A Modular Benchmark for Multi-Task, Multi-Embodiment Dexterous Manipulation
Yunchao Yao, Zhuxiu Xu, Tianqi Zhang et al.
Building general-purpose dexterous manipulation policies requires benchmarks that go beyond isolated tasks to systematically evaluate policies across diverse interaction modes, sensory conditions, and robot embodiments.