
FlashVLA: Streaming Action Decoding for Fast and Asynchronous VLA Inference
Zekai Li, Jiaming Tang, Zhijian Liu · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Vision-Language-Action (VLA) models are increasingly promising for robotic manipulation, yet their real-world deployment remains bottlenecked by high inference latency and unstable asynchronous execution.
Abstract Summary
Key Points
- Vision-Language-Action (VLA) models are increasingly promising for robotic manipulation, yet their real-world deployment remains bottlenecked by high inference latency and unstable asynchronous execution.
- This challenge is particularly pronounced in flow-matching-based VLA models, where action decoding requires multiple iterative steps conditioned on the VLM context.
- While efficient inference methods improve control frequency and asynchronous methods reduce execution idle time, existing approaches often fail to jointly achieve low-latency inference and accurate, temporally consistent asynchronous execution.
- We introduce \textbf{FlashVLA}, a streaming action decoding framework that addresses both challenges in a unified formulation.
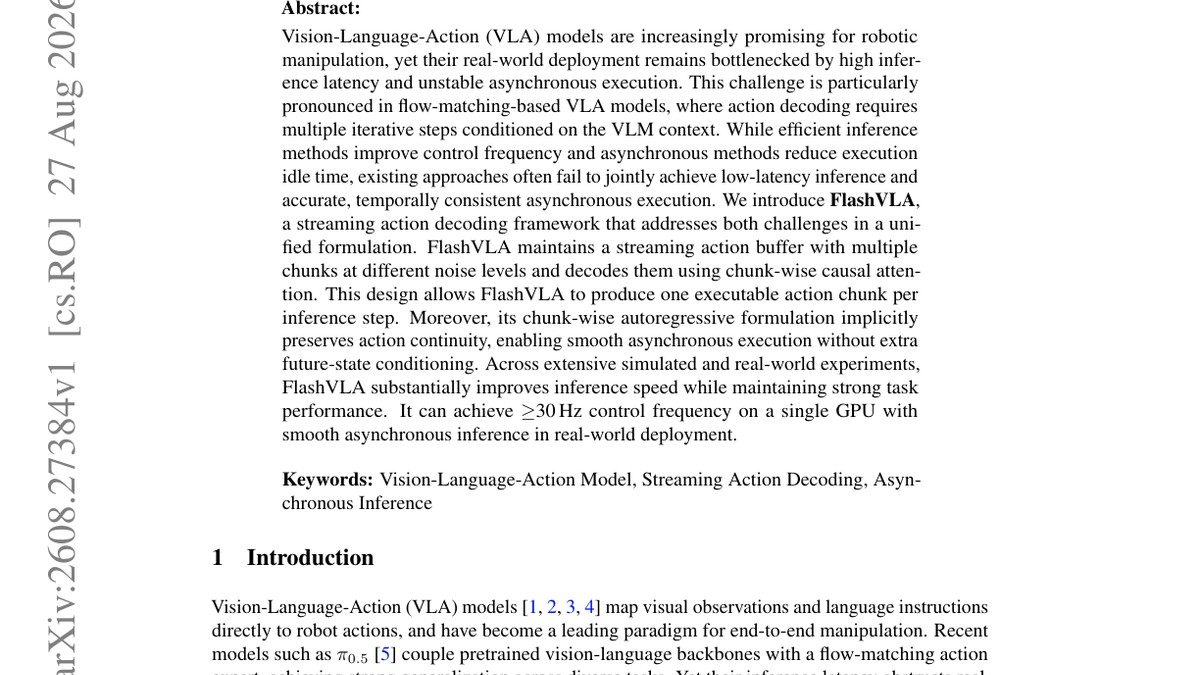
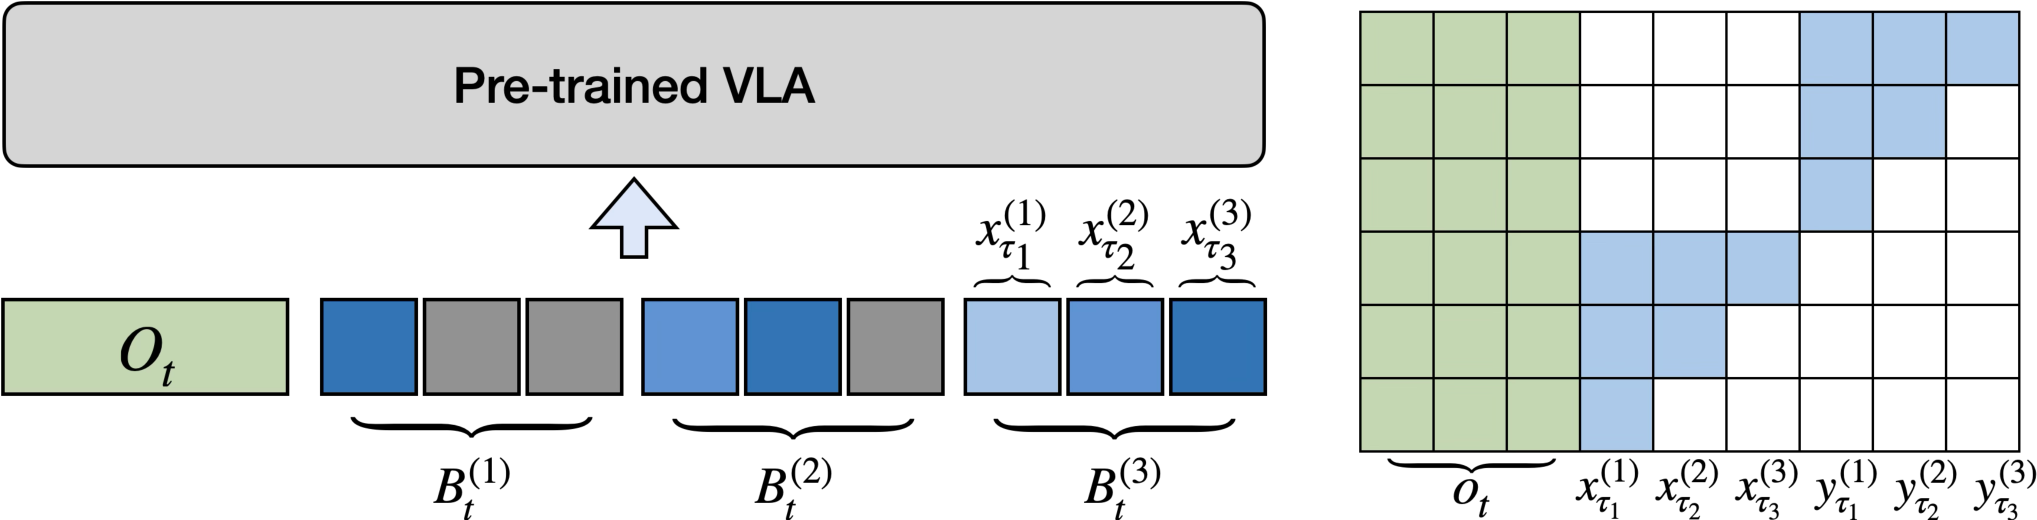
- FlashVLA maintains a streaming action buffer with multiple chunks at different noise levels and decodes them using chunk-wise causal attention.
Method
We introduce FlashVLA, a streaming action decoding framework that realizes the central idea from § 1 : decode action chunks jointly rather than in isolation. FlashVLA is a drop-in modification to any flow-matching-based VLA model, requiring only light architectural changes and a fine-tuning pass.
We describe the chunk-wise autoregressive formulation (§ 3.1 ), the streaming inference algorithm (§ 3.2 ), and the multi-buffer joint fine-tuning procedure used to adapt pretrained VLA models (§ 3.3 ).
Simulated Experiments
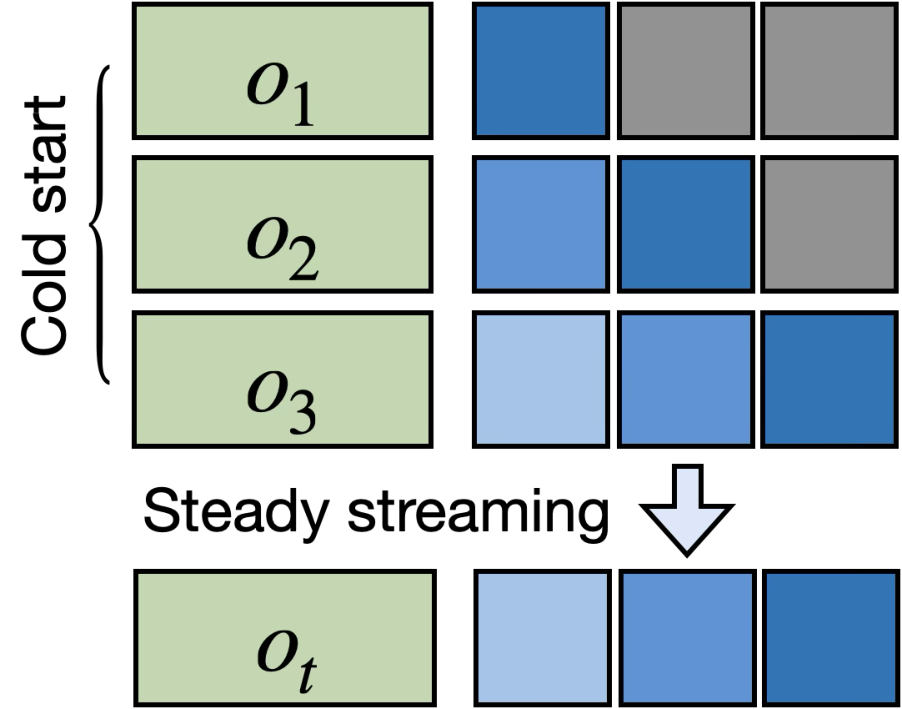
We evaluate FlashVLA against three claims it inherits from § 1 and § 3 : (i) at fixed task quality, decoding chunks jointly is substantially faster than decoding them in isolation; (ii) under asynchronous execution, chunk-wise causal attention preserves trajectory continuity without an explicit future-state module; and (iii) the chunk-level memory created by the streaming buffer translates into measurable long-horizon gains.
Real-World Deployment
We deploy FlashVLA on a 7-DoF Franka arm with a single RTX A4000 GPU and ask whether the simulated latency and asynchronous-continuity benefits transfer to a real robot at 30 Hz control.
We evaluate three tasks chosen to span the horizon range observed in simulation: pick and place (short: pick a fruit, place it in a basket), whiteboard wiping (medium: pick up a brush, wipe all marks), and table cleaning (long: clean three objects one by one into a basket).
Sources and Demonstrations
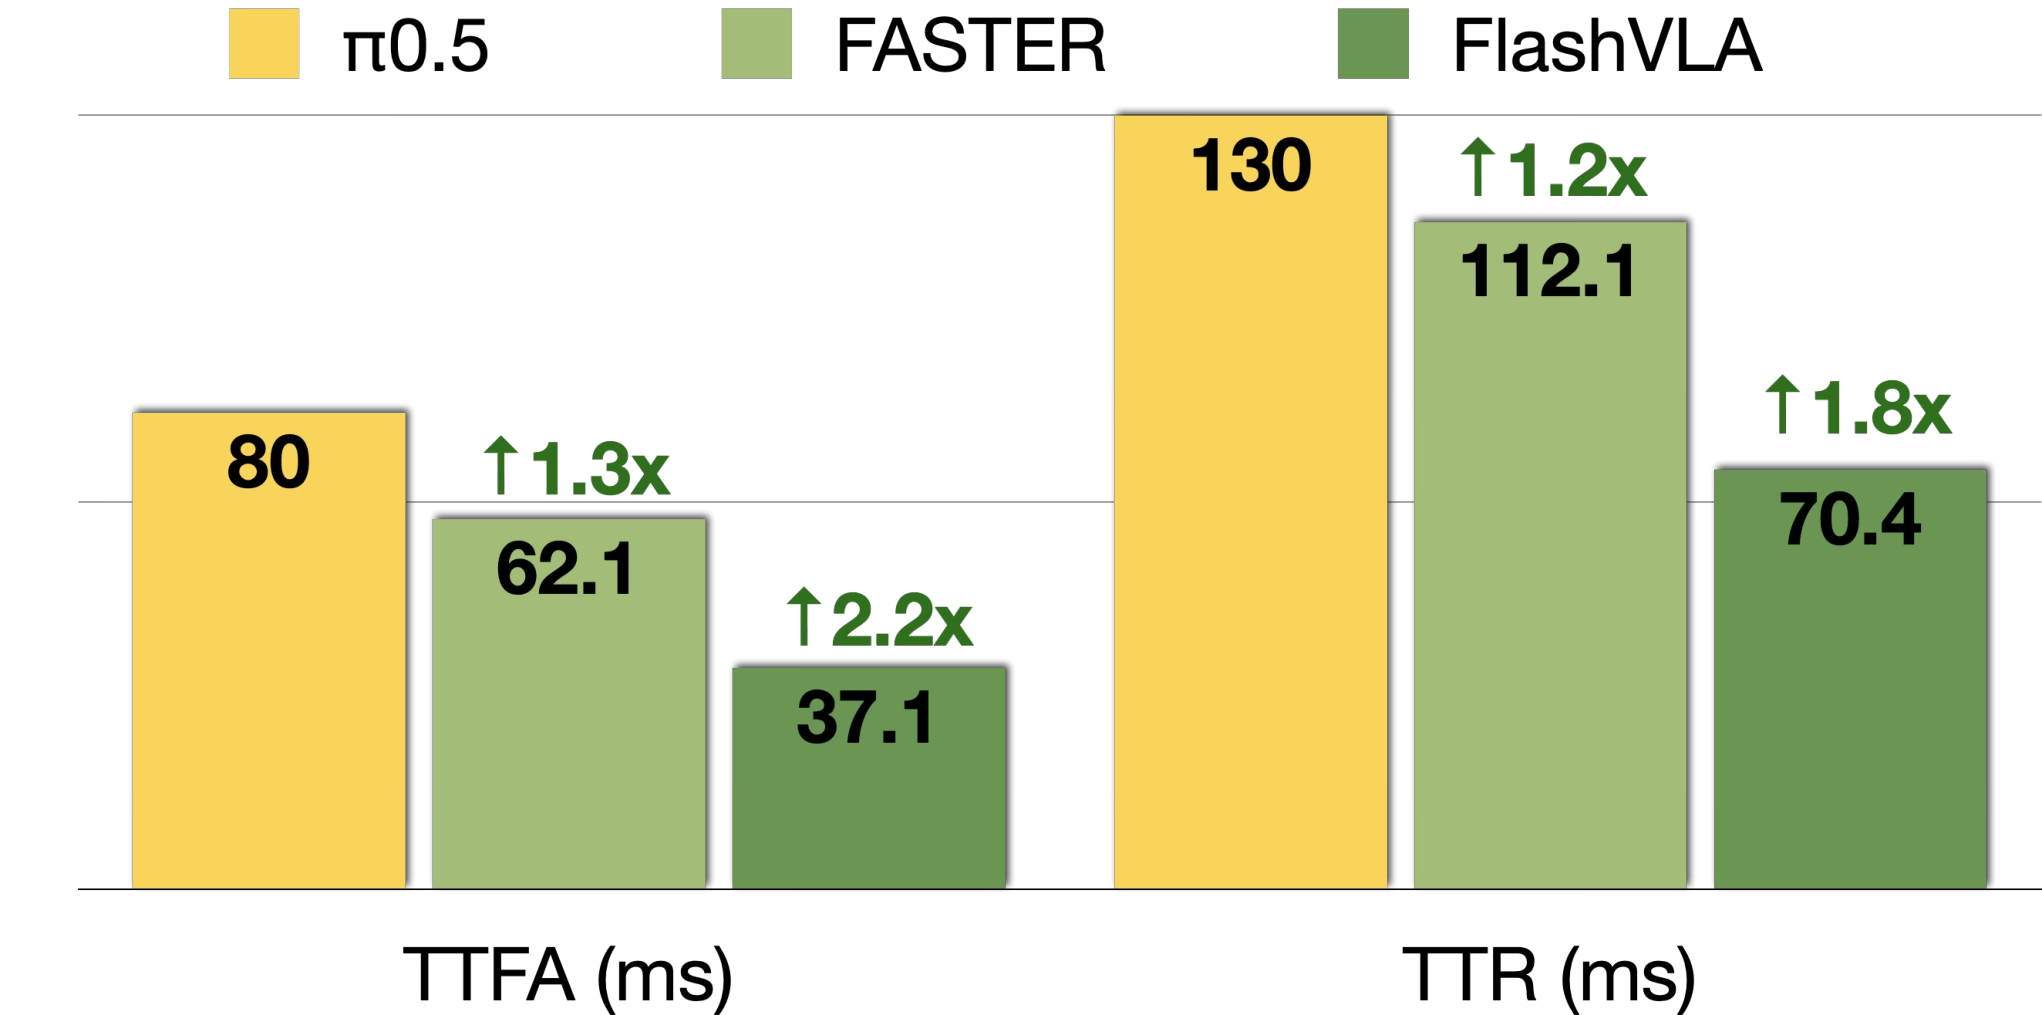
Figures are reproduced from Li et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

A Phenomenology of Neural Geometry in Vision-Language-Action Models
Mozes Jacobs, Aiden Swann, Mathilde Papillon et al.
Robotic manipulation is inherently geometric, but what shape does the world take inside the policy that performs it?

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.

Beyond Reconstruction: What Matters in Action Tokenization for Robot Policies?
Haoran Chen, Jingtian Ji, Samuel Wheeler et al.
Autoregressive action-token policies such as vision-language-action models require action tokenizers to translate discrete token sequences into precise control actions in continuous space. Many action tokenizers learn the mapping between tokens and actions via a reconstruction objective.

Capability-Aware Arbitration for Semantic Intent-Based Shared Control
Zhaoda Du, Michael Bowman, Xiaoli Zhang
Shared control often allocates robot authority based on confidence in inferred human intent, assuming reliable autonomous execution. When this assumption fails, high intent confidence can cause over-helping.