
OIL: An Object Interaction Layer for Humanoid Whole-Body Control
Pranay Dugar, Mohitvishnu S. Gadde, Rajesh Mangannavar, Aayam Kumar Shrestha, Alan Fern · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Recent progress in learned whole-body controllers for humanoid robots has enabled robust free-space motion by tracking kinematic targets such as joint or end-effector trajectories.
Abstract Summary
Key Points
- Recent progress in learned whole-body controllers for humanoid robots has enabled robust free-space motion by tracking kinematic targets such as joint or end-effector trajectories.
- This interface provides a useful abstraction for upstream systems, including motion capture, teleoperation, or generative models, which can specify desired motion without reasoning about forces or balance.
- However, this abstraction has largely been limited to robot motion, requiring task-specific controllers or retraining for object interaction.
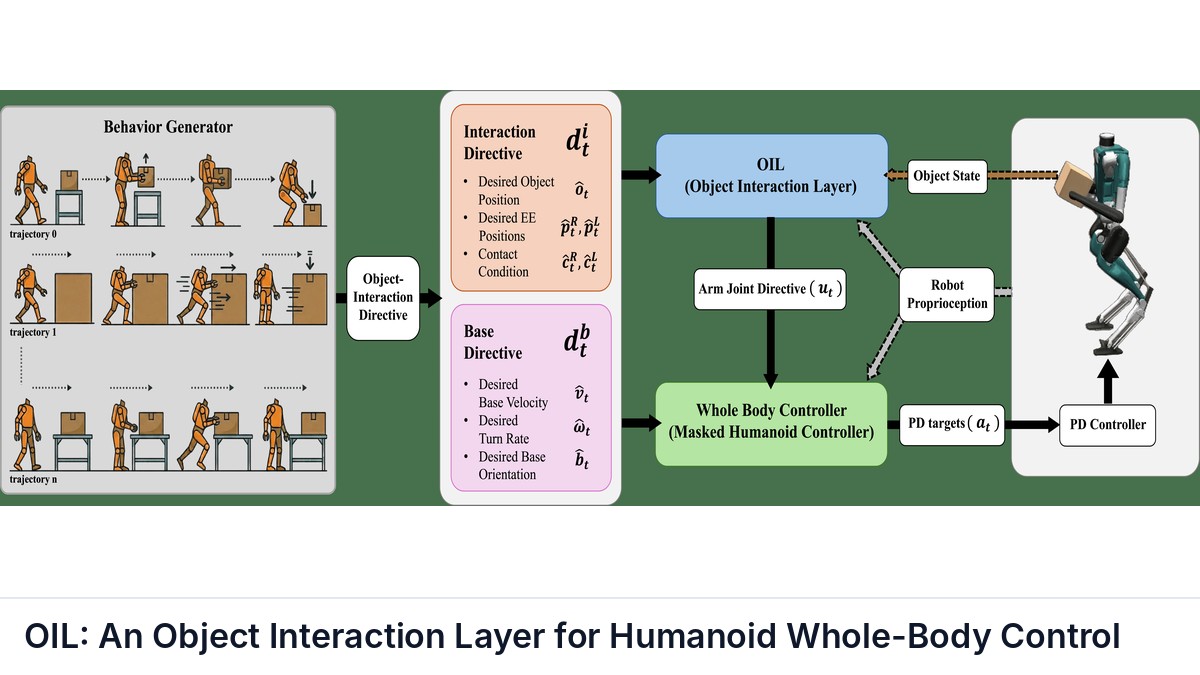
- We introduce OIL, an Object Interaction Layer that extends the kinematic command interface of whole-body control to include desired object motion and contact.
- OIL augments a standard controller with object-centric commands and translates them into coordinated whole-body behavior while preserving locomotion and balance.
Problem Formulation
We consider the problem of learning a humanoid controller capable of executing a broad distribution of object-interaction behaviors specified through kinematic directives. We focus on non-prehensile bimanual end-effector interaction, where the robot manipulates objects using coordinated whole-body motion and contact without dexterous grasping.
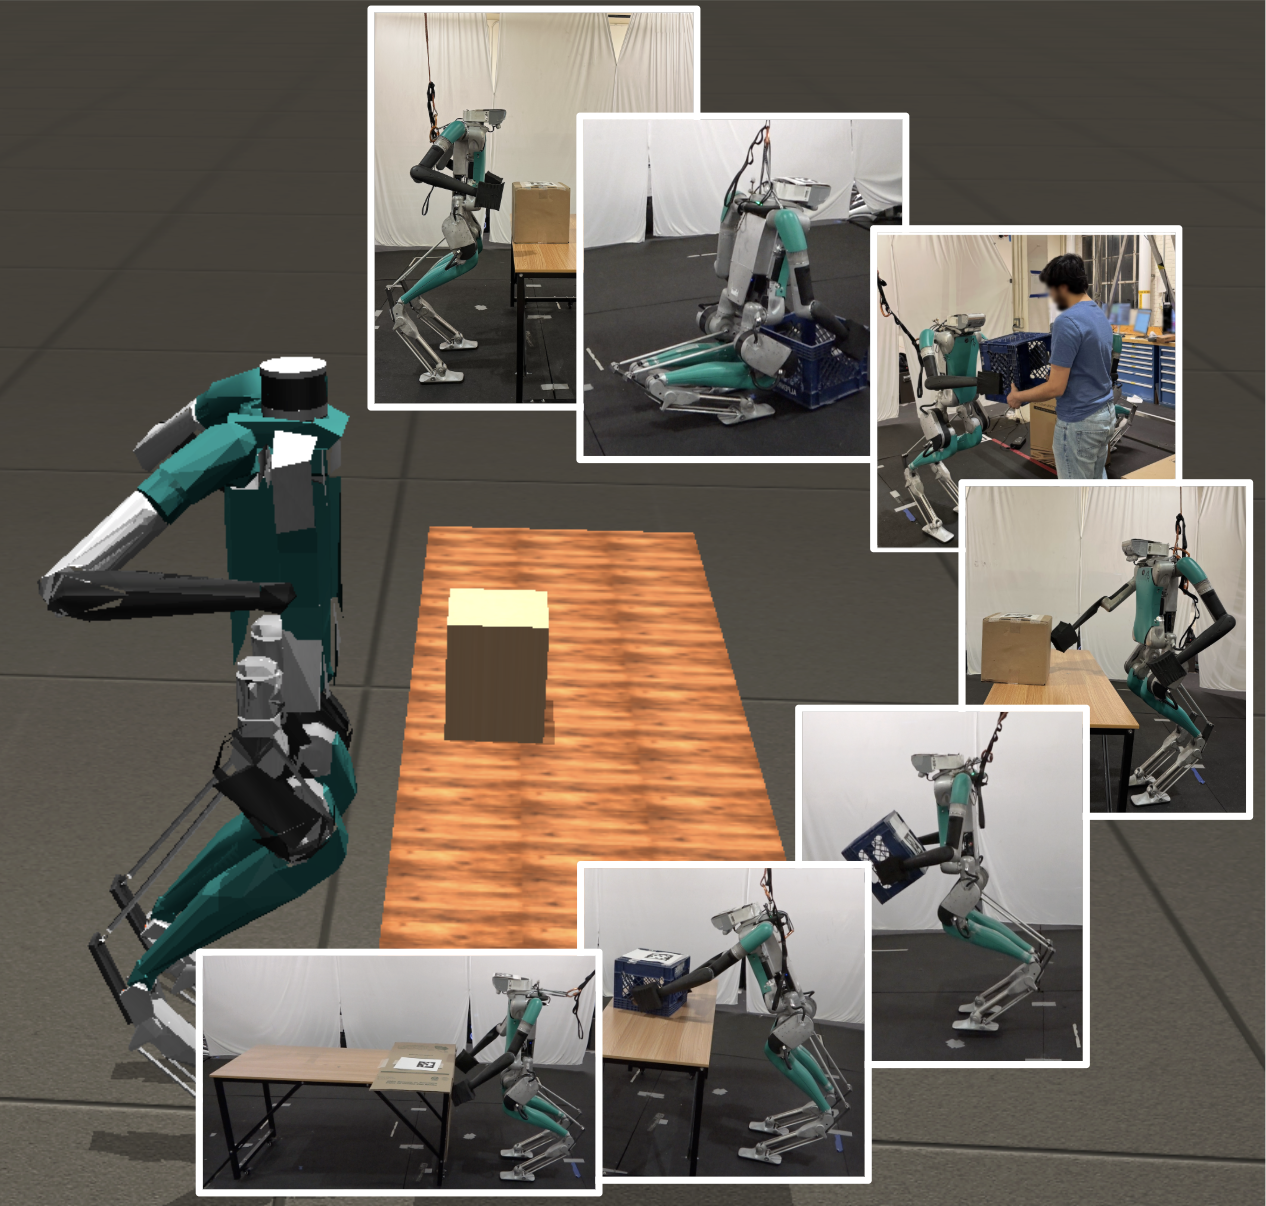
These behaviors include pushing, pulling, lifting, carrying, and locomotion-coupled transport, with variations in object motion, contact timing, and base movement.
Object-Interactive Whole-Body Control
We now describe how the directive formulation introduced in the previous section is realized in practice. Our approach builds an object-interactive controller by layering an Object-Interaction Layer (OIL) on top of an existing, well-trained whole-body controller (WBC) trained for free-space (non-interactive) motion.
In this work, we use the Masked Humanoid Controller (MHC) as the underlying WBC due to its robustness, support for partially specified kinematic directives, and demonstrated sim-to-real transfer capabilities.
OIL Training
We train the OIL policy $\pi^{\mathrm{OIL}}$ via reinforcement learning in the MuJoCo simulator with the Digit V3 humanoid model using Proximal Policy Optimization (PPO) ( Schulman et al. 2017 ) . The underlying whole-body controller $\pi^{\mathrm{WBC}}$ (MHC in our experiments) remains frozen throughout, so learning is confined to $\pi^{\mathrm{OIL}}$.
Below, we describe the training procedure, including episode sampling, reward design, and domain randomization. Training is episodic.
Results
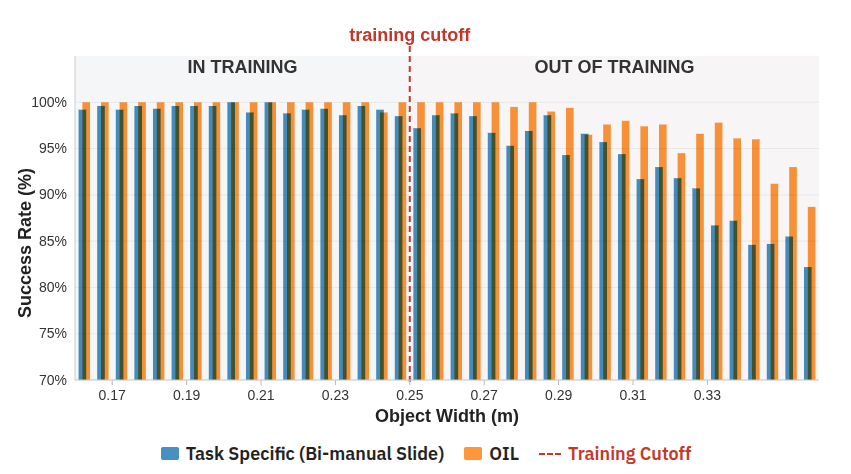
We evaluate OIL along three axes that correspond to its design claims: (i) whether a single policy with object-level commands improves over robot-only control and matches task-specific policies trained per behavior, (ii) whether the OIL controller generalizes to object properties outside its training distribution, and (iii) whether a single controller supports zero-shot composition of novel behavior sequences.
FUTURE WORK
Future work will expand the interaction directives to include full SE(3) object orientation, different grasp modes, and force/contact targets when this information is available upstream. Another direction is to generate directives in a closed loop, allowing the system to replan when contact fails or degrades instead of being limited to a single attempt.
We also plan to incorporate visual observations as input for object sensing, reducing reliance on externally provided object state estimates.
Sources and Demonstrations
Figures are reproduced from Dugar et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

A Balanced Data Diet: Addressing the Exploration Bottleneck in Mega-Scale RL for Robot Control
Octi Zhang, Mateo Guaman Castro, Patrick Yin et al.
General-purpose robots must perform a wide range of tasks from agile locomotion to dexterous manipulation.
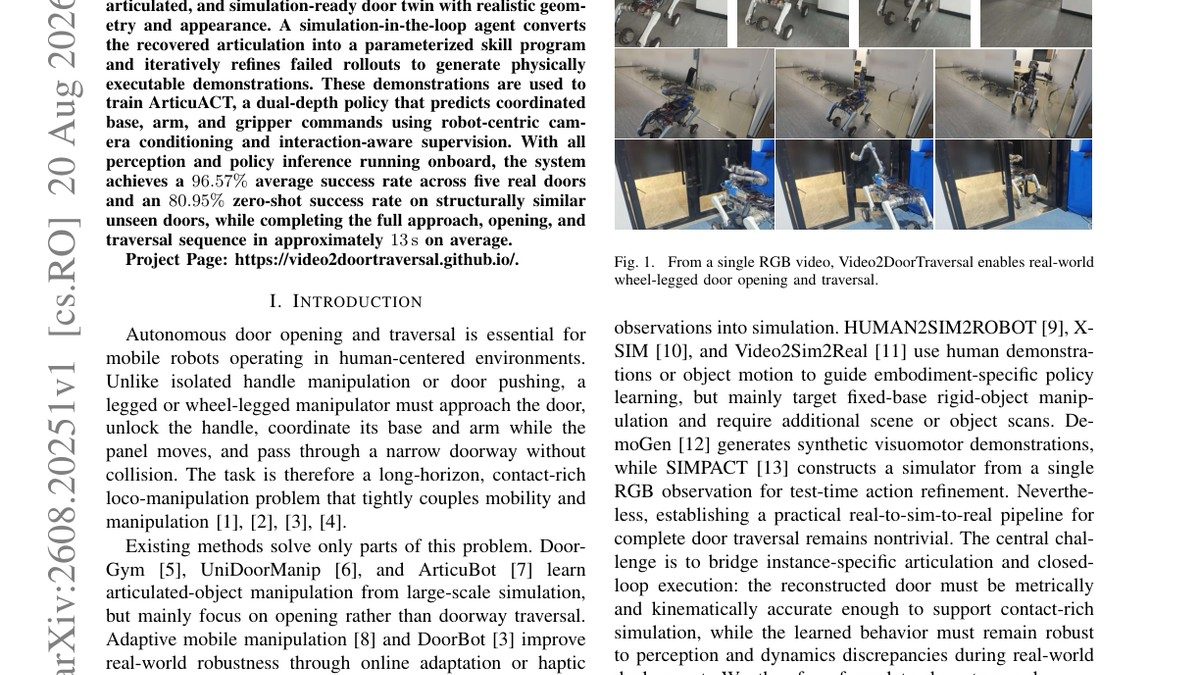
Video2DoorTraversal: Push Door Traversal via Simulated Door Twins
Xincheng Tang, Yiji Chen, Youhan Xie et al.
Door opening and traversal is a long-horizon loco-manipulation task that requires precise handle interaction and coordinated base-arm control. We present Video2DoorTraversal, a single-video real-to-sim-to-real framework for wheel-legged mobile manipulators.

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.

Dexterity from Supervised Play
Botao He, Yiming Dou, Yiannis Aloimonos et al.
How can robots autonomously collect the contact-rich experience needed to learn dexterous manipulation?