
ContactGuard: Pre-Contact Execution Monitoring with Action-Conditioned Latent World Models
Gehan Zheng, Matthew Johnson-Roberson, Weiming Zhi · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Contact-rich manipulation failures are often detected only after the robot has committed to contact.
Abstract Summary
Key Points
- Contact-rich manipulation failures are often detected only after the robot has committed to contact
- This is especially limiting in wrist-camera setups: close gripper--object views help observe contact, but a poor approach may already push, miss, slip, or disturb the object before conventional detectors react.
- We introduce \emph{ContactGuard}, a pre-contact execution monitor for chunked visuomotor policies
- Given the policy's planned action chunk, ContactGuard predicts its short-horizon consequence in latent visual space and aborts if the predicted future latent indicates likely failure.
- Its latent world model is trained from unlabelled robot trajectories to predict compact multi-view visual embeddings under planned actions, avoiding pixel-level video prediction.
Latent World Models for Pre-Contact Grasp Monitoring
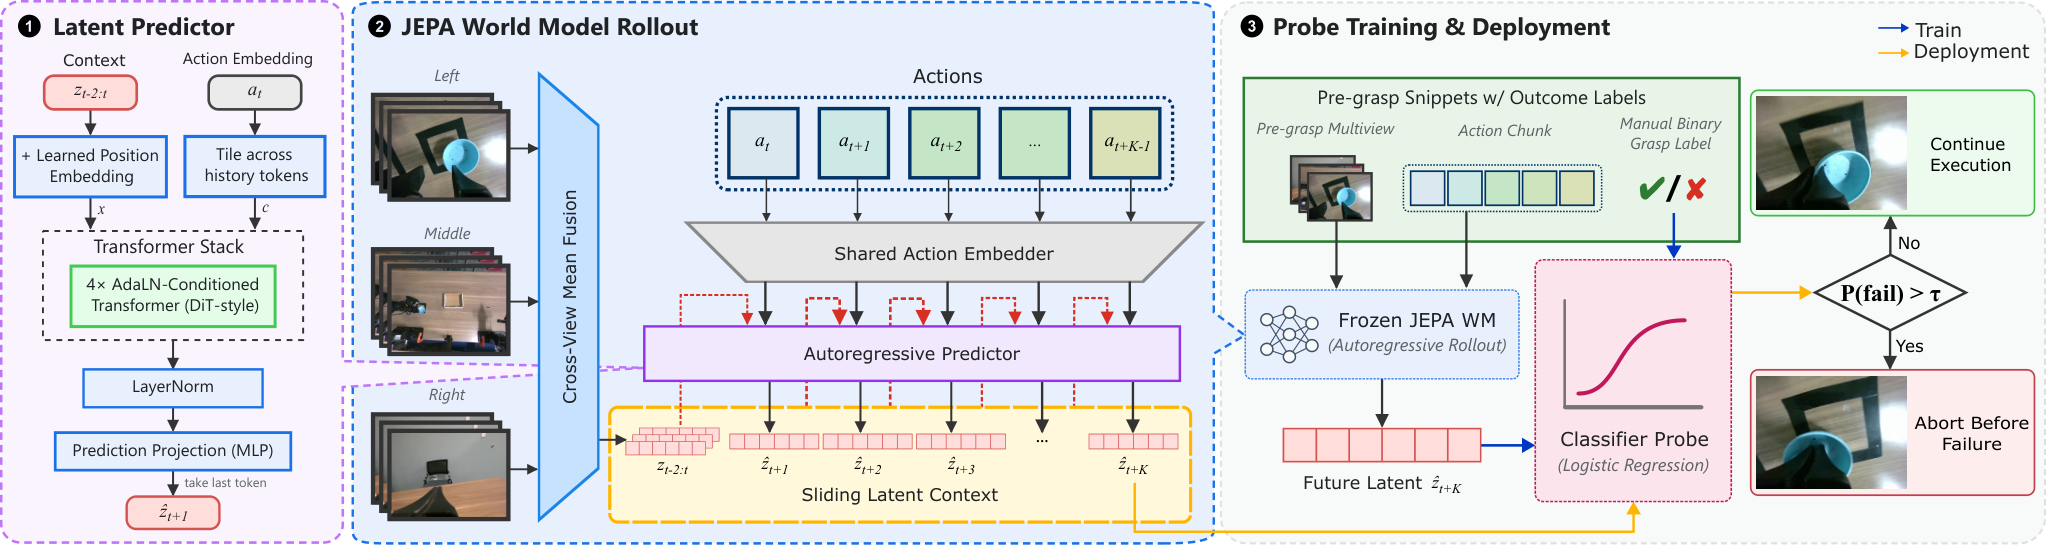
We present ContactGuard , a pre-contact grasp monitor that predicts whether an imminent grasp is likely to fail before the gripper closes. It combines a JEPA-style latent world model with a frozen linear failure probe.
The world model is trained from unlabelled robot trajectories to predict action-conditioned future latents; the probe is trained from a smaller labelled grasp set to score the predicted post-contact latent.
Experimental Results
We instantiate ContactGuard on grasp closure, a canonical short-horizon imminent-contact event with challenging visual geometry, occlusion, object variation, and a strict real-time pre-contact budget. We evaluate four grasp settings with ACT [ 30 ] as the underlying chunked visuomotor policy.
All metrics evaluate the predictor’s decision at the triggered pre-contact state, not the trigger itself or post-abort recovery. Our experiments ask four questions: Prediction quality.
Sources and Demonstrations
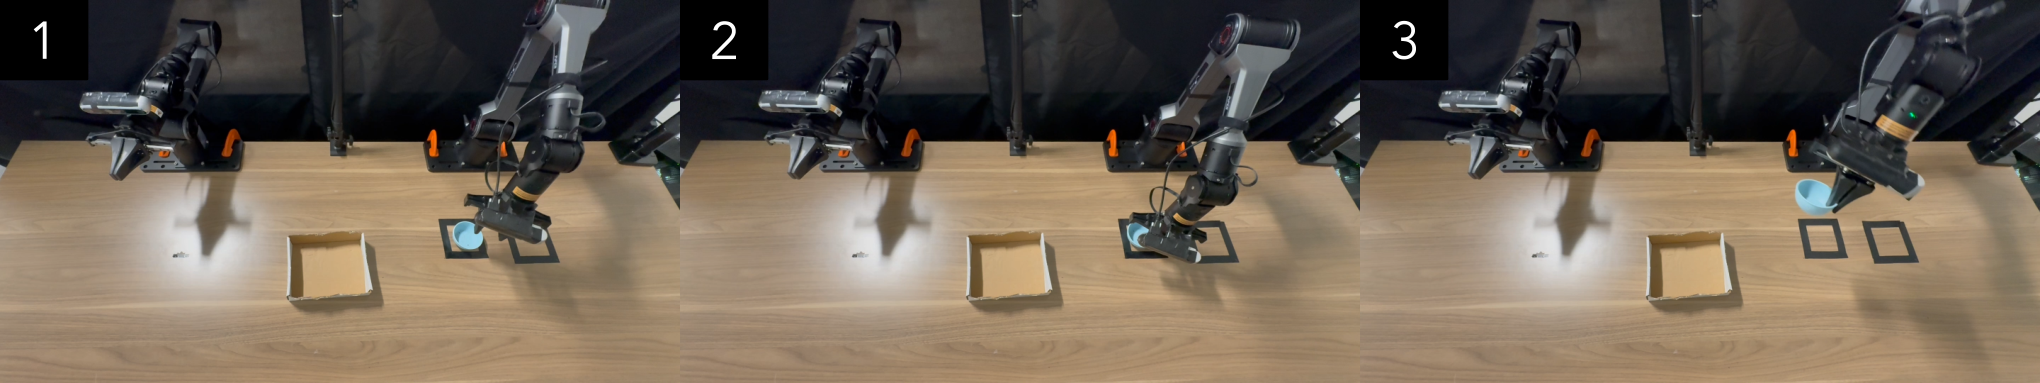
Figures are reproduced from Zheng et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

3DThinkVLA: Endowing Vision-Language-Action Models with Latent 3D Priors via 3D-Thinking-Guided Co-training
Jiaxin Shi, Xidong Zhang, Fucai Zhu et al.
We propose a 3D-thinking-guided co-training framework that enables vision-language-action (VLA) models to perform 3D spatial reasoning implicitly during action prediction.

A Phenomenology of Neural Geometry in Vision-Language-Action Models
Mozes Jacobs, Aiden Swann, Mathilde Papillon et al.
Robotic manipulation is inherently geometric, but what shape does the world take inside the policy that performs it?

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.
Adaptive Vision-Language Grasping via Composable Foundation Priors and Generalizable Grasp Synthesis
Sixu Yan, Shikang Wang, Binhua Huang et al.
This paper proposes AdaRoboVLG, a task-adaptive Vision-Language-Grasp (VLG) framework that supports generalizable grasp synthesis across different robotic hands.