
RT-1: Robotics Transformer for Real-World Control at Scale
Anthony Brohan, Yevgen Chebotar, Chelsea Finn, Karol Hausman, Alexander Herzog, Julian Ibarz, Brian Ichter, Alex Irpan, Tomas Jackson, Sally Jesmonth, Nikhil Joshi, Ryan Julian, Dmitry Kalashnikov, Yuheng Kuang, Isabel Leal, Kuang-Huei Lee, Sergey Levine, Yao Lu, Utsav Malla, Devesh K. Misra, Igor Mordatch, Ofir Nachum, Carolina Parada, Jodilyn Peralta, Emily Perez, Karl Pertsch, Jornell Quiambao, Kanishka Rao, Michael Ryoo, Grecia Salazar, Pannag Sanketi, Kevin Sayed, Jaspiar Singh, Sumedh Sontakke, Austin Stone, Clayton Tan, Huong Tran, Vincent Vanhoucke, Steve Vega, Quan Vuong, Fei Xia, Ted Xiao, Peng Xu, Sichun Xu, Tianhe Yu, Brianna Zitkovich · Google DeepMind, Google Research · 2023
Framework
JAX + TensorFlow
License
Apache-2.0
Stars
1,723
Summary
RT-1 is a 35M-parameter transformer trained on 130K robot demonstrations that generalizes to new tasks, objects, and environments, forming the foundation for Google's RT-2 and RT-X line of VLA models.
Abstract Summary
Key Points
- 35M-parameter transformer trained on 130K real robot demonstrations.
- Generalizes to unseen tasks, objects, and environments.
- Robust to distractors, lighting changes, background clutter.
- Open-source: RLDS format, JAX model, ROS2 inference node.
- Distillable to 6M parameters for edge deployment.
Preliminaries
We aim to learn robot policies to solve language-conditioned tasks from vision. Formally, we consider a sequential decision-making environment. At timestep $t=0$, the policy $\pi$ is presented with a language instruction $i$ and an initial image observation $x_{0}$. The policy produces an action distribution $\pi(\cdot~/~i,x_{0})$ from which an action $a_{0}$ is sampled and applied to the robot.
System Overview
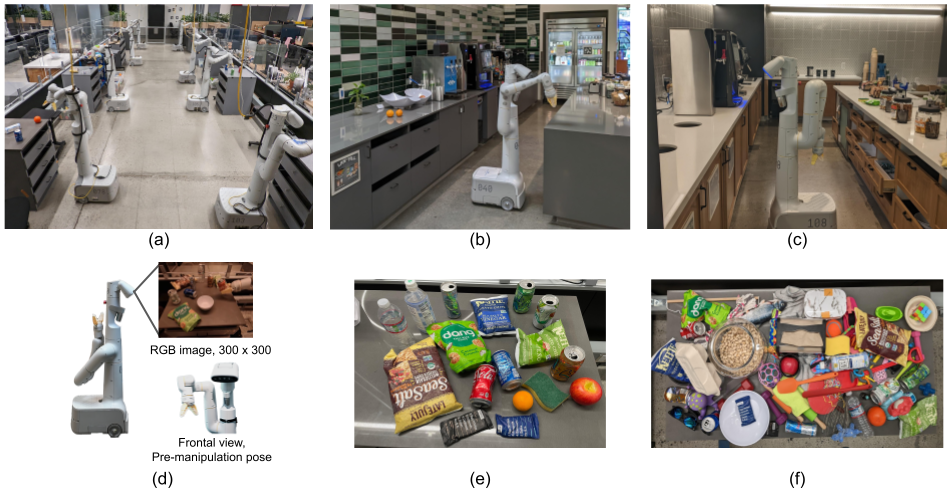
The goal of this work is to build and demonstrate a general robot learning system that can absorb large amounts of data and generalize effectively. We use mobile manipulators from Everyday Robots 3 3 3 everydayrobots.com , which have a 7 degree-of-freedom arm, a two-fingered gripper, and a mobile base (see Fig. 2 (d)).
To collect data and evaluate our method, we use three kitchen-based environments: two real office kitchens and a training environment modelled off these real kitchens. The training environment, shown in Fig.
RT-1: Robotics Transformer
In this section, we describe how we tokenize the images, text, and actions, and then discuss the RT-1 model architecture. We then describe how we attain the runtime speed required for real-time control. Lastly, we describe the data collection procedure and the skills and instructions in our dataset.
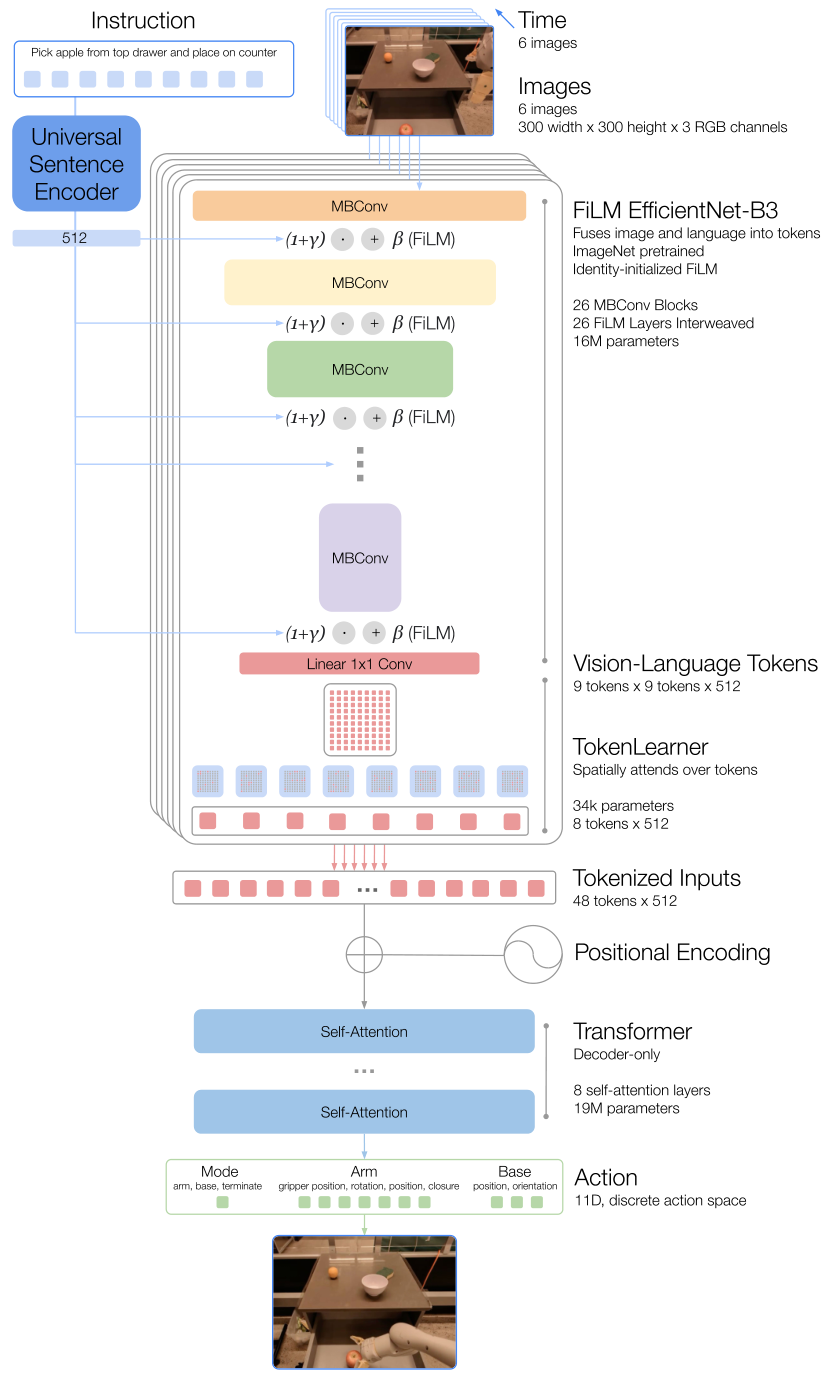
Our model is built on a Transformer architecture ( Vaswani et al., 2017 ) and takes a history of images and task description as input and directly outputs tokenized actions, as shown in Fig. 1(a) and in detail in Fig. 3 .
Experiments
Can an RT-1 learn to perform a large number of instructions, as well as to generalize in zero shot to new tasks, objects and environments? (Section 6.2 ) Can we push the resulting model even further by incorporating heterogeneous data sources, such as simulated data or data from different robots? (Section 6.3 ) How do various methods generalize to long-horizon robotic scenarios?
(Section 6.4 ) How do generalization metrics change with varying amounts of data quantity and data diversity? (Section 6.5 ) What are the important and practical decisi...
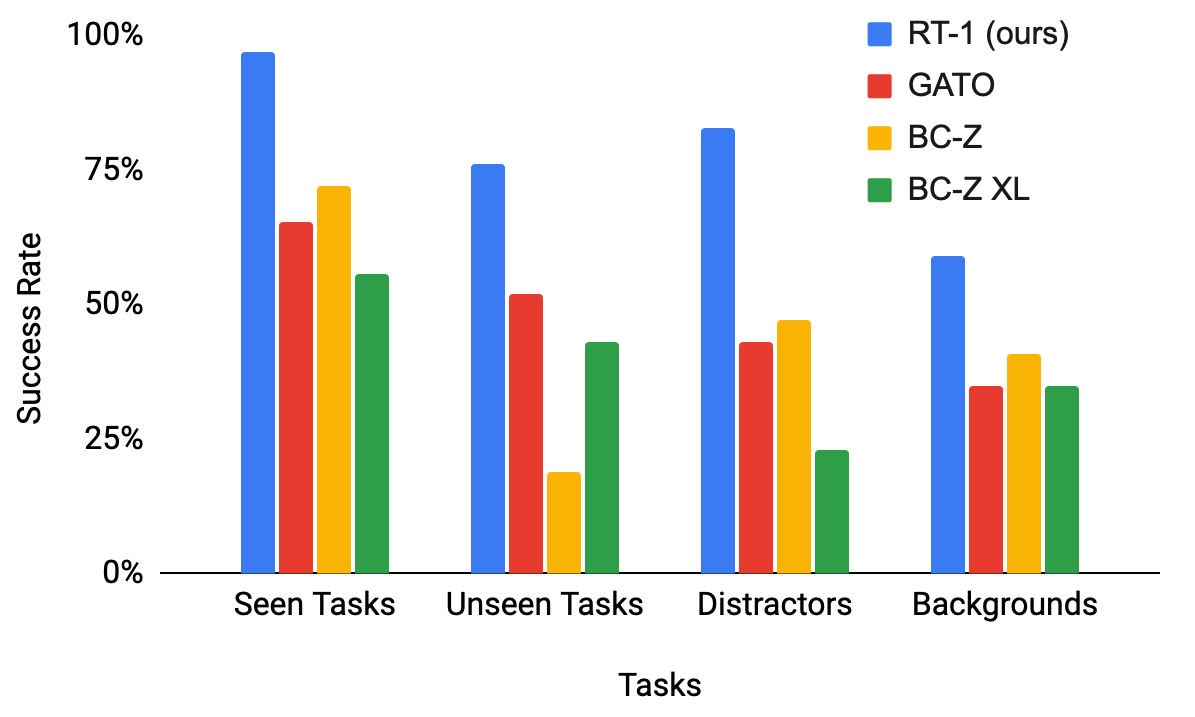
Sources and Demonstrations
Figures are reproduced from Brohan et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
π0: A Vision-Language-Action Flow Model for General Robot Control
Karl Pertsch, Oliver Groth, Jonas Frey et al.
π0 is a 3.5B-parameter VLA flow model from Physical Intelligence that achieves state-of-the-art general robot manipulation by mixing online RL with high-quality human demonstrations, available as an open-source PyTorch implementation.

DynaFLIP: Rethinking Robotics Perception via Tri-Modal-Dynamics Guided Representation
Jusuk Lee, Seungjae Lee, Jonghun Shin et al.
Robot manipulation critically depends on perception that preserves the action-relevant aspects of a scene. Yet most robot learning pipelines are built upon visual encoders pre-trained for static recog
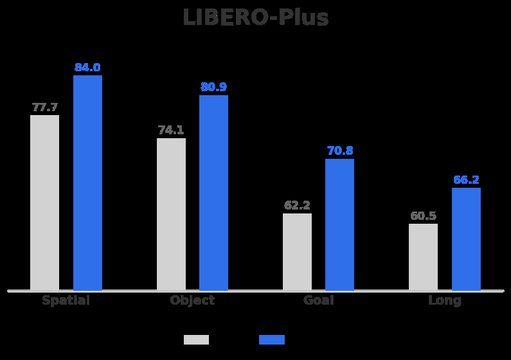
GuidedVLA: Specifying Task-Relevant Factors via Plug-and-Play Action Attention Specialization
Xiaosong Jia, Bowen Yang, Zuhao Ge et al.
Vision-Language-Action (VLA) models aim for general robot learning by aligning action as a modality within powerful Vision-Language Models (VLMs). Existing VLAs rely on end-to-end supervision to implicitly enable the action decoding process to learn task-relevant features.
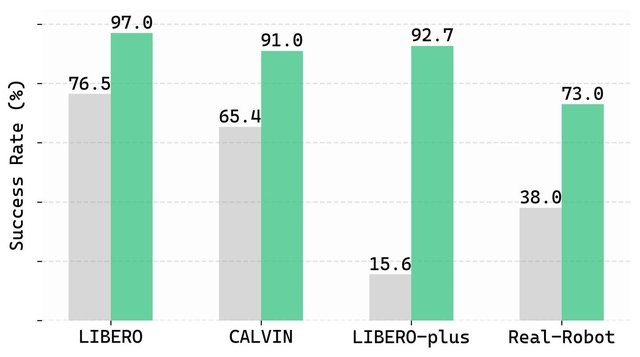
From Imagined Futures to Executable Actions: Mixture of Latent Actions for Robot Manipulation
Yajie Li, Bozhou Zhang, Chun Gu et al.
Video foundation-models models offer a promising imagination mechanism for robot manipulation by predicting long-horizon future observations, but effectively exploiting these imagined futures for action execution remains challenging.