
RT-1: Robotics Transformer for Real-World Control at Scale
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Xi Chen, Krzysztof Choromanski, Tianli Ding, Danny Driess, Avinava Dubey, Chelsea Finn, Pete Florence, Chuyuan Fu, Montse Gonzalez Arenas, Keerthana Gopalakrishnan, Kehang Han, Karol Hausman, Jasmine Hsu, Brian Ichter, Alex Irpan, Nikhil Joshi, Ryan Julian, Dmitry Kalashnikov, Yuheng Kuang, Isabel Leal, Lisa Lee, Tsang-Wei Edward Lee, Sergey Levine, Yao Lu, Henryk Michalewski, Igor Mordatch, Karl Pertsch, Kanishka Rao, Krista Reymann, Michael Ryoo, Grecia Salazar, Pannag Sanketi, Pierre Sermanet, Jaspiar Singh, Anikait Singh, Radu Soricut, Huong Tran, Vincent Vanhoucke, Quan Vuong, Ayzaan Wahid, Stefan Welker, Paul Wohlhart, Jialin Wu, Fei Xia, Ted Xiao, Peng Xu, Sichun Xu, Tianhe Yu, Brianna Zitkovich · Google DeepMind, Google Research, Everyday Robots · 2023
Framework
TensorFlow
License
Apache-2.0
Stars
1,723
Summary
A large transformer model trained on 130k episodes of real robot manipulation to output discretized arm-and-gripper actions from RGB images and natural language instructions.
Abstract Summary
Key Points
- First large-scale transformer model trained end-to-end on real robot manipulation.
- 130K+ episodes across 13 months on Everyday Robots mobile manipulators.
- Pixel-to-action control with natural language instructions; no privileged state.
- Demonstrated scaling benefits and positive cross-robot transfer.
- Precursor to RT-2, Open X-Embodiment, and the broader VLA research wave.
Preliminaries
We aim to learn robot policies to solve language-conditioned tasks from vision. Formally, we consider a sequential decision-making environment. At timestep $t=0$, the policy $\pi$ is presented with a language instruction $i$ and an initial image observation $x_{0}$. The policy produces an action distribution $\pi(\cdot~/~i,x_{0})$ from which an action $a_{0}$ is sampled and applied to the robot.
System Overview
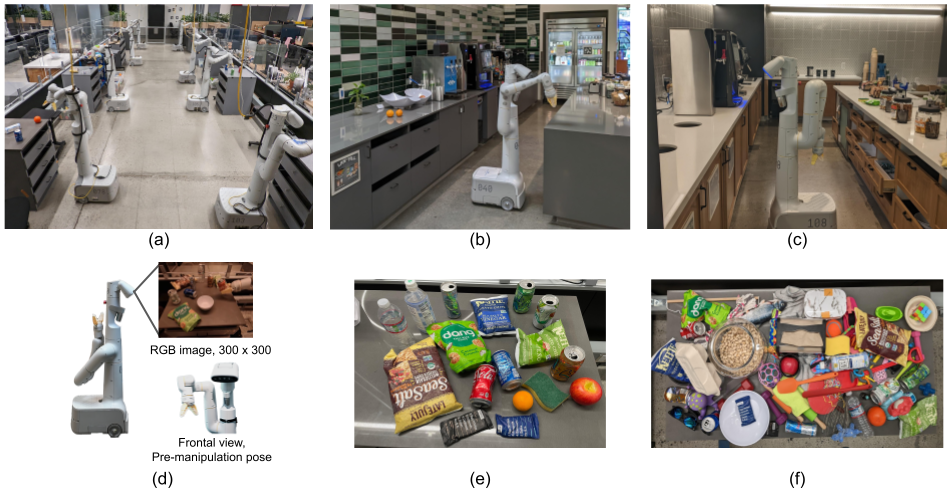
The goal of this work is to build and demonstrate a general robot learning system that can absorb large amounts of data and generalize effectively. We use mobile manipulators from Everyday Robots 3 3 3 everydayrobots.com , which have a 7 degree-of-freedom arm, a two-fingered gripper, and a mobile base (see Fig. 2 (d)).
To collect data and evaluate our method, we use three kitchen-based environments: two real office kitchens and a training environment modelled off these real kitchens. The training environment, shown in Fig.
RT-1: Robotics Transformer
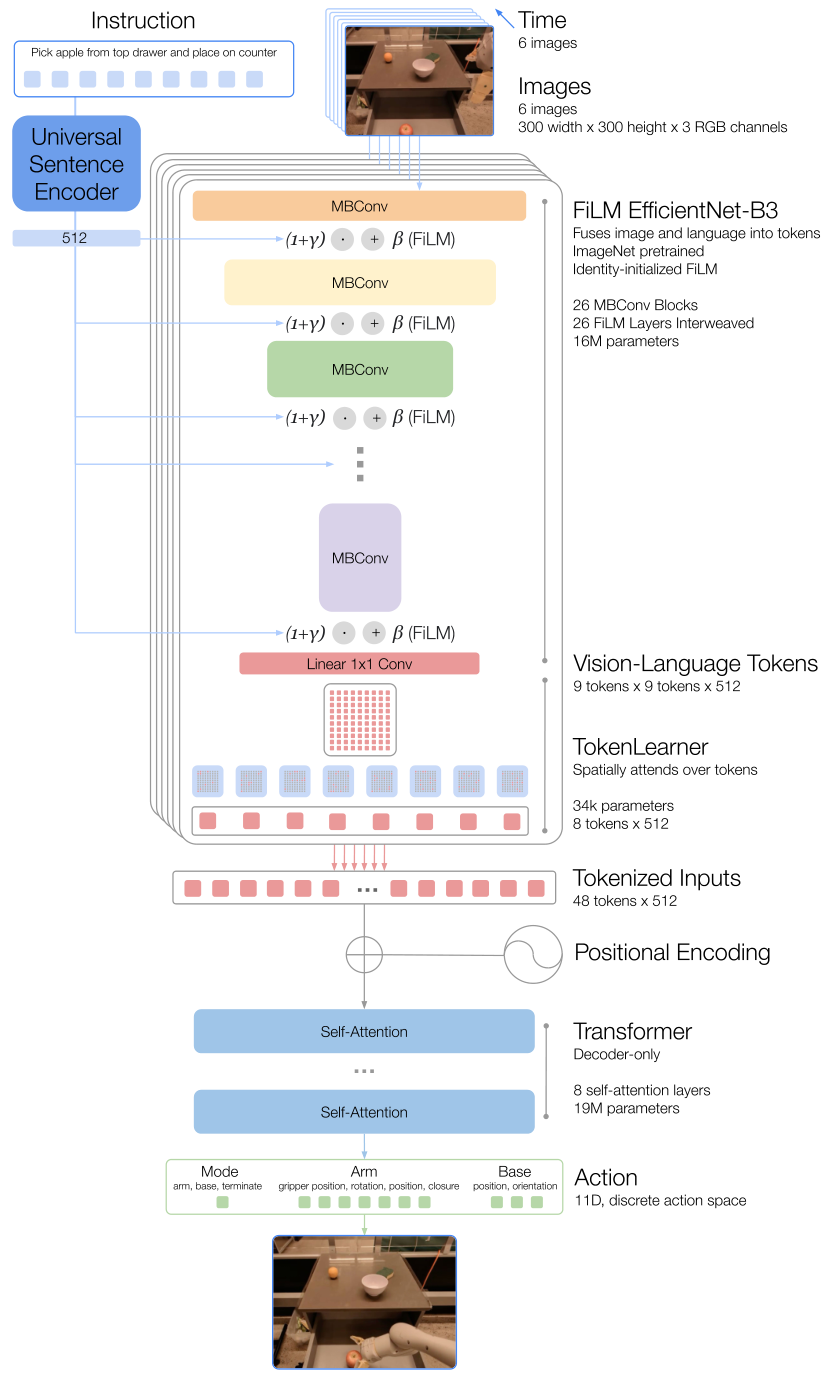
In this section, we describe how we tokenize the images, text, and actions, and then discuss the RT-1 model architecture. We then describe how we attain the runtime speed required for real-time control. Lastly, we describe the data collection procedure and the skills and instructions in our dataset.
Our model is built on a Transformer architecture ( Vaswani et al., 2017 ) and takes a history of images and task description as input and directly outputs tokenized actions, as shown in Fig. 1(a) and in detail in Fig. 3 .
Experiments
Can an RT-1 learn to perform a large number of instructions, as well as to generalize in zero shot to new tasks, objects and environments? (Section 6.2 ) Can we push the resulting model even further by incorporating heterogeneous data sources, such as simulated data or data from different robots? (Section 6.3 ) How do various methods generalize to long-horizon robotic scenarios?
(Section 6.4 ) How do generalization metrics change with varying amounts of data quantity and data diversity? (Section 6.5 ) What are the important and practical decisi...
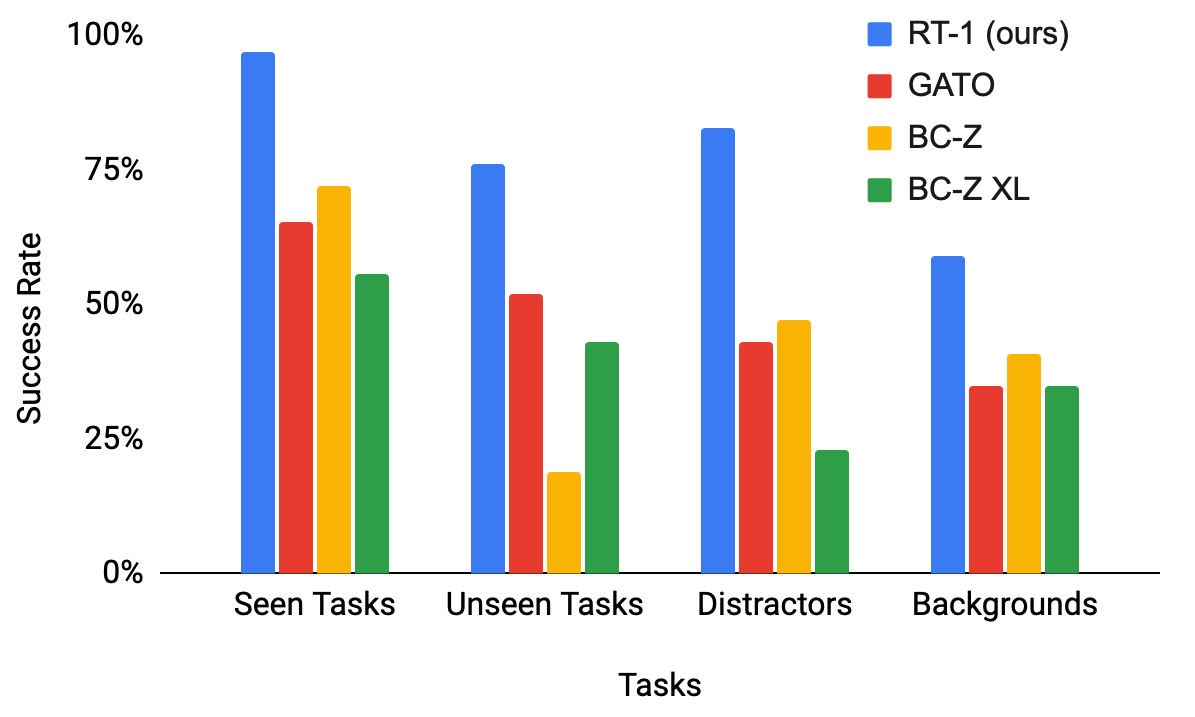
Sources and Demonstrations
Figures are reproduced from Brohan et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
ALAM: Algebraically Consistent Latent Transitions for Vision-Language-Action Models
Zuojin Tang, Haoyun Liu, Xinyuan Chang et al.
Vision-Language-Action (VLA) models map visual observations and language instructions to robot actions through learned latent representations.
PriorVLA: Prior-Preserving Adaptation for Vision-Language-Action Models
Xinyu Guo, Bin Xie, Wei Chai et al.
Vision-Language-Action (VLA) models have shown promise for generalizable robot control but struggle when adapting to new domains while preserving prior capabilities.
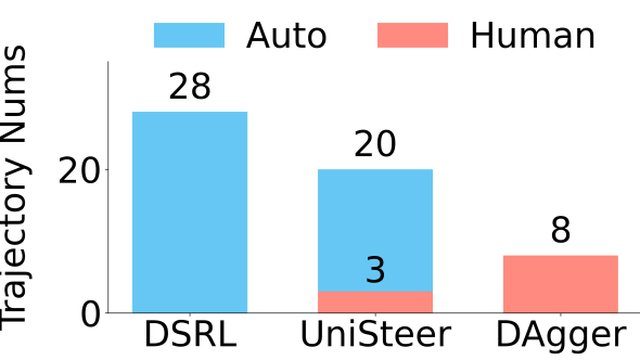
Unified Noise Steering for Efficient Human-Guided VLA Adaptation
Junjie Lu, Xinyao Qin, Yuhua Jiang et al.
Diffusion-based vision-language-action (VLA) models have emerged as strong priors for robotic manipulation, yet adapting them to real-world distributions remains challenging.
X-Imitator: Spatial-Aware Imitation Learning via Bidirectional Action-Pose Interaction
Kai Xiong, Hongjie Fang, Lixin Yang et al.
Effectively handling the interplay between spatial perception and action generation remains a critical bottleneck in robotic manipulation.