
ALAM: Algebraically Consistent Latent Transitions for Vision-Language-Action Models
Zuojin Tang, Haoyun Liu, Xinyuan Chang, Changjie Wu, Zhenyang Shi · · 2026
Framework
N/A
License
N/A
Stars
0
Summary
Vision-Language-Action (VLA) models map visual observations and language instructions to robot actions through learned latent representations.
Abstract Summary
Key Points
- Proposes ALAM, a novel approach for vla in robotics.
- Addresses key limitations in existing methods through innovative architecture design.
- Demonstrates strong empirical results on standard benchmarks and real-world evaluations.
- Introduces novel training methodology that improves generalization and sample efficiency.
- Provides comprehensive analysis of failure modes and ablation studies.
Method
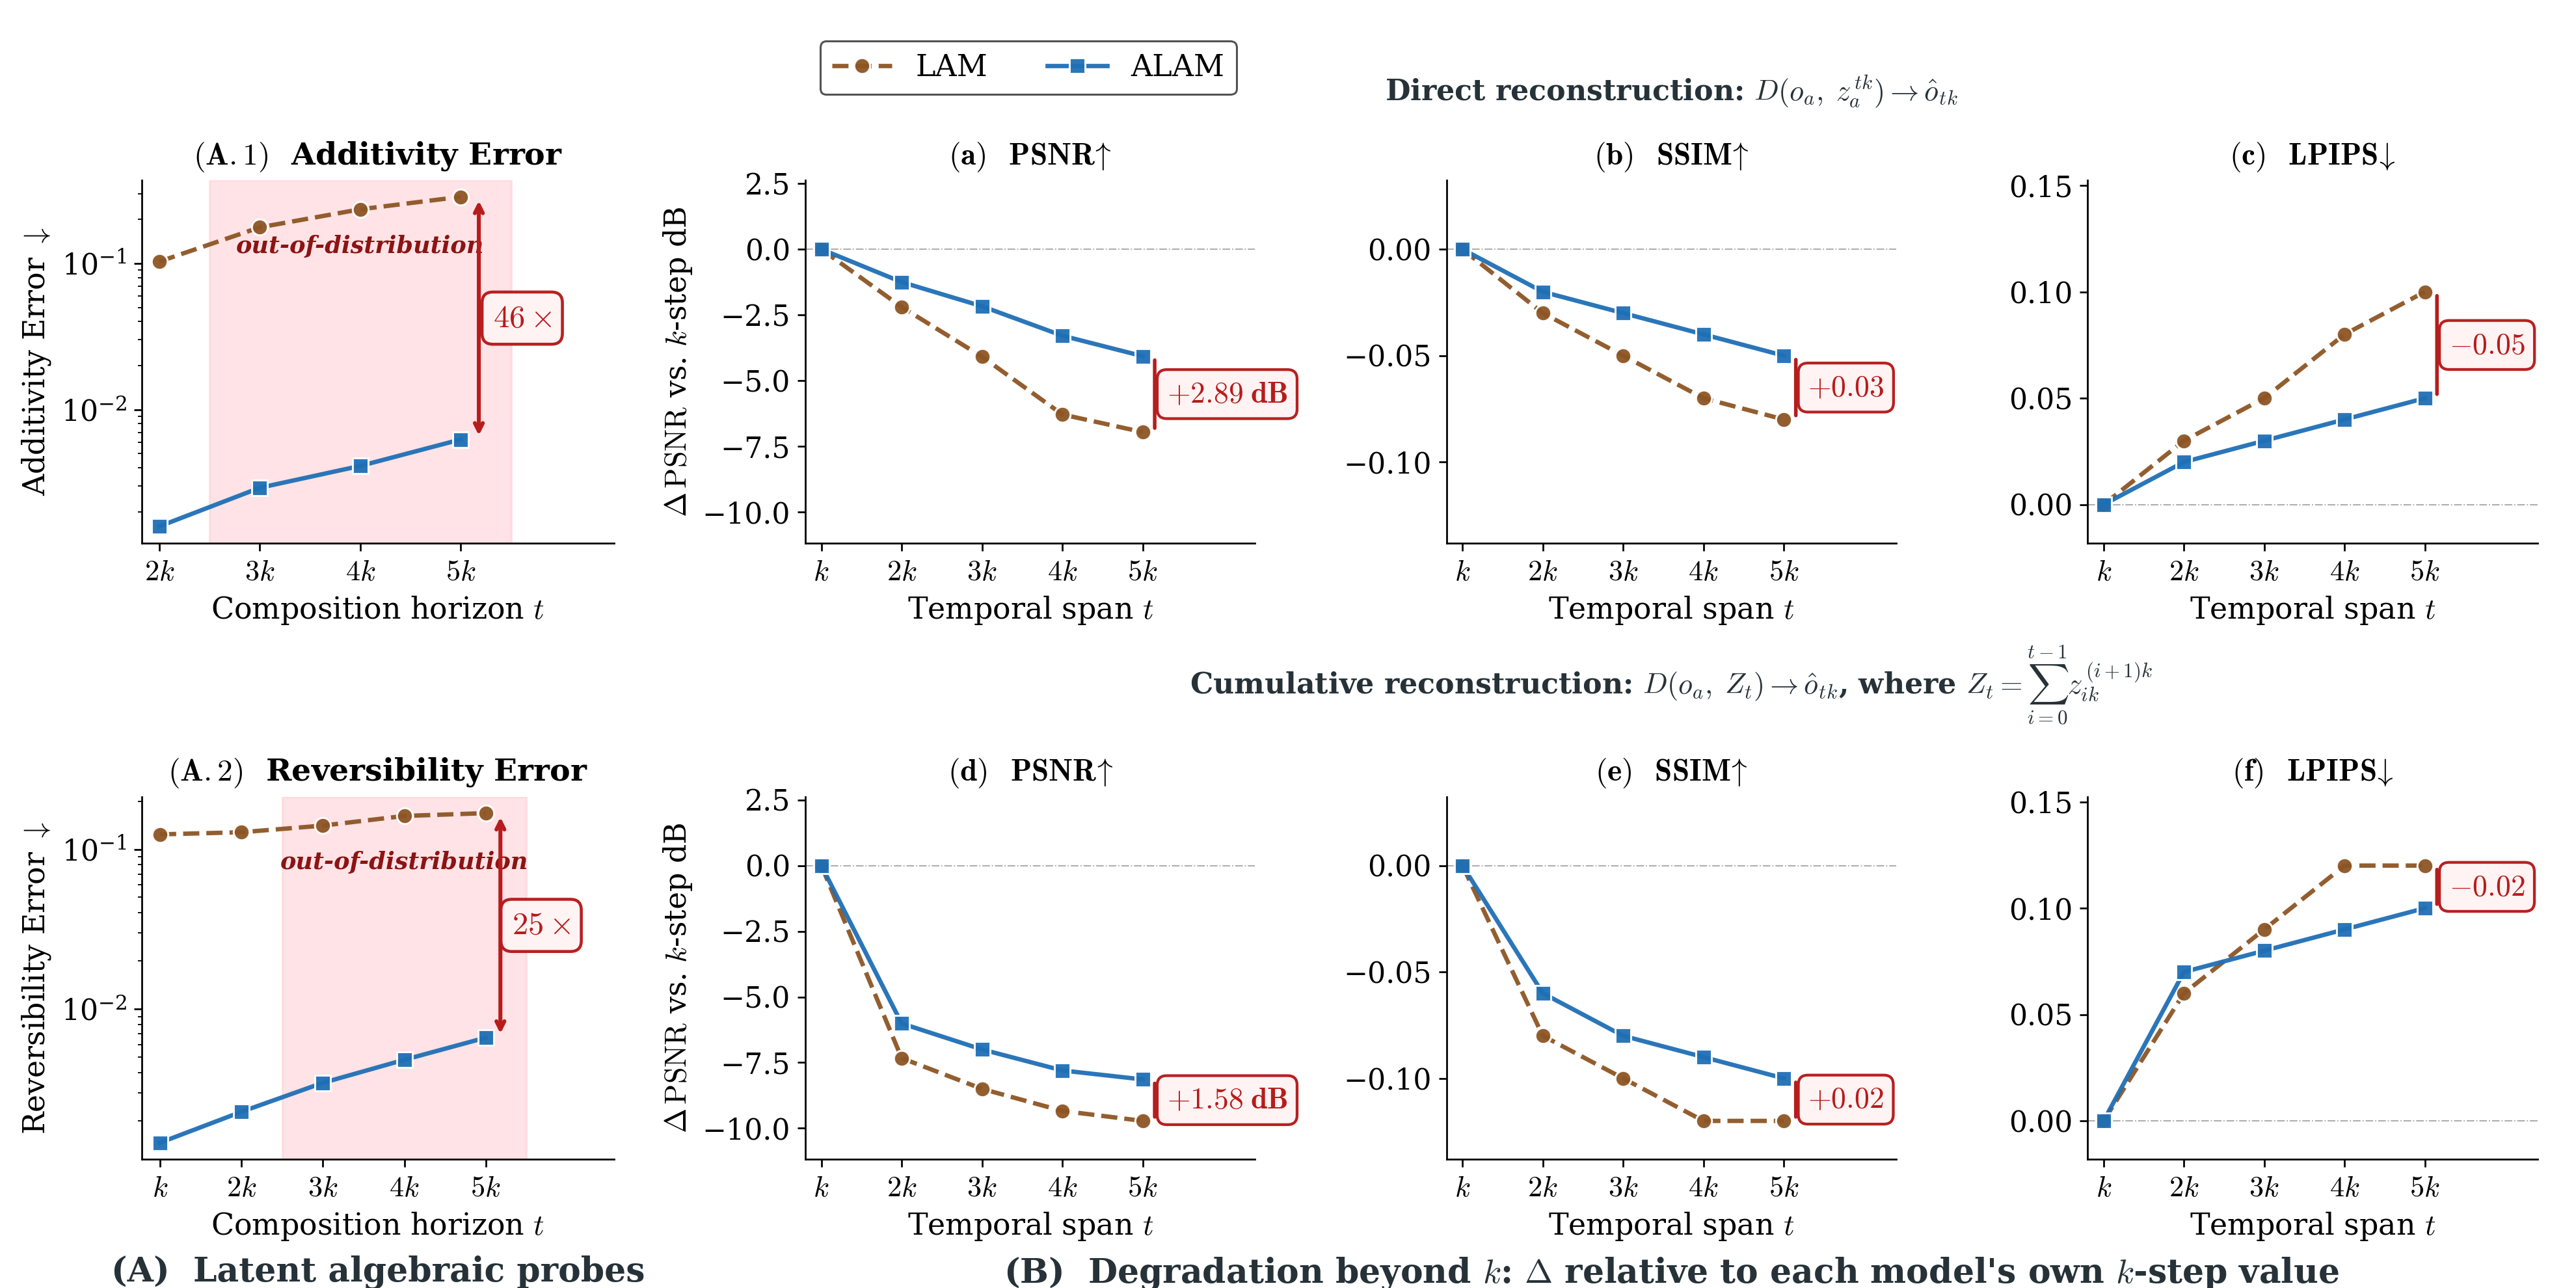
We introduce ALAM , a two-stage framework that learns latent transitions from action-free video and transfers them to vision-language-action (VLA) policy learning. In pretraining (Sec.
3.2 ), a relational encoder is trained with future-frame reconstruction together with two algebraic regularizers, composition consistency and reversal consistency, that encourage the latent transitions to be approximately additive and sign-reversible. At transfer (Sec.
Experimental Setup
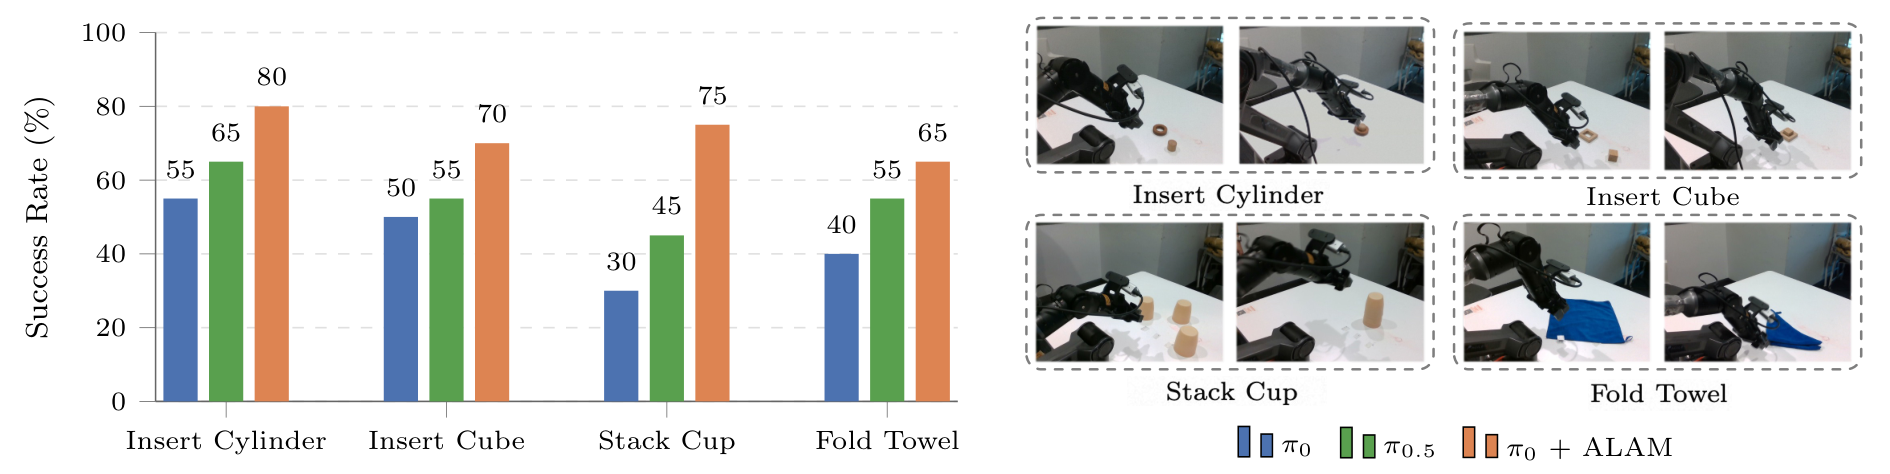
ALAM is pretrained on $11$ action-free video sources, mostly real-robot manipulation data from Open-X-Embodiment O’Neill et al. (2024) and CALVIN Mees et al. (2022) . We use AdamW on $128\!\times\!$H20 GPUs (90G) and run for $39$ epochs (about $4$ days), at which point the pretraining loss has plateaued. The full dataset configuration and hyperparameters are in Appendix A .
The transfer stage is built on $\pi_{0}$ Black et al. (2026) .
Sources and Demonstrations
Figures are reproduced from Tang et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers
PriorVLA: Prior-Preserving Adaptation for Vision-Language-Action Models
Xinyu Guo, Bin Xie, Wei Chai et al.
Vision-Language-Action (VLA) models have shown promise for generalizable robot control but struggle when adapting to new domains while preserving prior capabilities.
Unified Noise Steering for Efficient Human-Guided VLA Adaptation
Junjie Lu, Xinyao Qin, Yuhua Jiang et al.
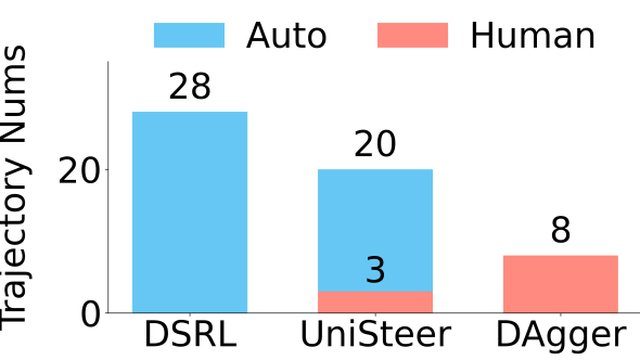
Diffusion-based vision-language-action (VLA) models have emerged as strong priors for robotic manipulation, yet adapting them to real-world distributions remains challenging.
AwareVLN: Reasoning with Self-awareness for Vision-Language Navigation
Wenxuan Guo, Xiuwei Xu, Yichen Liu et al.
AwareVLN introduces selective self-aware reasoning for VLN agents, triggering explicit spatial and progress analysis only at uncertain waypoints to improve robustness and explainability.

DynaFLIP: Rethinking Robotics Perception via Tri-Modal-Dynamics Guided Representation
Jusuk Lee, Seungjae Lee, Jonghun Shin et al.
Robot manipulation critically depends on perception that preserves the action-relevant aspects of a scene. Yet most robot learning pipelines are built upon visual encoders pre-trained for static recog