
RotVLA: Rotational Latent Action for Vision-Language-Action Model
FeaturedQiwei Li, Xicheng Gong, Xinghang Li, Peiyan Li, Quanyun Zhou, Hangjun Ye, Jiahuan Zhou, Yadong Mu · · 2026
Framework
N/A
License
N/A
Stars
7
Summary
Latent Action Models (LAMs) have emerged as an effective paradigm for handling heterogeneous datasets during Vision-Language-Action (VLA) model pretraining, offering a unified action space across embodiments.
Abstract Summary
Key Points
- Introduces a new dataset or benchmark
- Provides open-source code or data
RotVLA
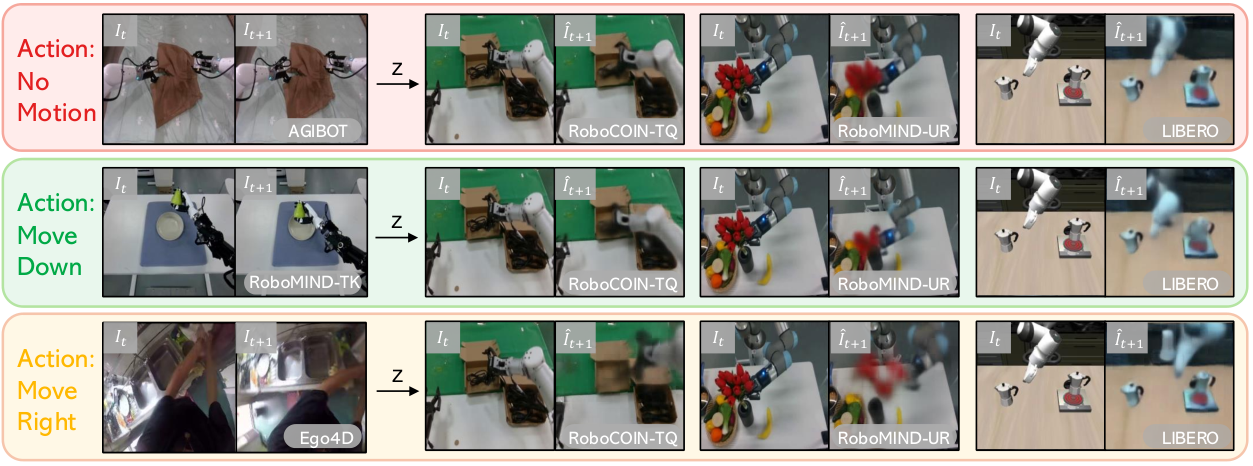
Preliminary. A typical LAM consists of an inverse dynamics encoder $\mathcal{E}$ and a forward dynamics decoder $\mathcal{D}$. Given two consecutive video frames with $k$ interval, denoted as $I_{t}$ and $I_{t+1}$, the encoder extracts a latent action representation composed of $N$ tokens of dimension $d$, i.e. $z_{t\rightarrow t+1}\in\mathbb{R}^{N\times d}$.
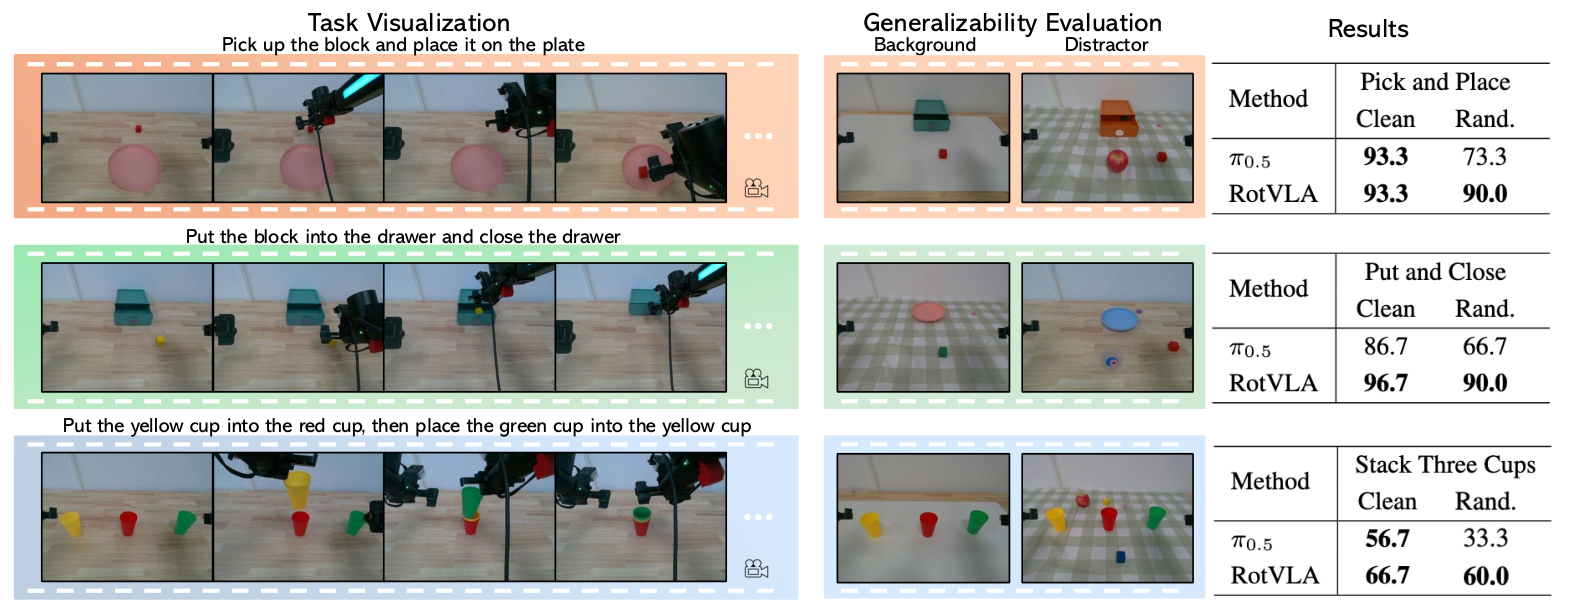
Experiment
Model architecture. Following UniVLA [ 7 ] , we implement the LAM encoder using a frozen DINOv2 [ 46 ] to extract frame-wise visual features. These features are further processed by a spatial–temporal transformer [ 47 ] . The decoder is implemented with standard transformer [ 48 ] . The latent action dimension $n$ is set to 16.
For RotVLA, the VLM backbone is initialized from InternVL3.5-1B [ 38 ] , followed by an action expert implemented as a 24-layer Diffusion Transformer (DiT) [ 49 ] .
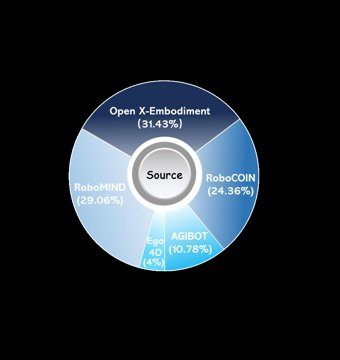
Sources and Demonstrations
Figures are reproduced from Li et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

Scalable Behavior Cloning with Open Data, Training, and Evaluation
Arthur Allshire, Himanshu Gaurav Singh, Ritvik Singh et al.
We introduce ABC, a fully open-source stack for manipulation with behavior cloning. At its core is ABC-130K: the largest open-source teleoperation dataset to date, featuring 3,500 hours of data spanning over 130K episodes across 195 diverse tasks.

E-TTS: A New Embodied Test-Time Scaling Framework for Robotic Manipulation
Wen Ye, Peiyan Li, Tingyu Yuan et al.
Recently, a few works have made early attempts to study test-time scaling for embodied tasks.

LA4VLA: Learning to Act without Seeing via Language-Action Pretraining
Tao Lin, Yuxin Du, Yiran Mao et al.
Vision-Language-Action (VLA) models are commonly pretrained on robot demonstrations by jointly mapping visual observations and language instructions to actions. However, dense visual-action supervision can dominate the comparatively sparse language-action signal.

Learning to Fold: prizewinning solution at LeHome Challenge 2026 (1st place online, 2nd offline)
Ilia Larchenko
I describe my solution to the LeHome Challenge 2026, an ICRA 2026 competition on bimanual garment folding. The system placed 1st of 62 teams in the online (simulation) round and 2nd in the real-world final. It improves a vision-language-action (VLA) policy with a reinforcement-learning loop.