

E-TTS: A New Embodied Test-Time Scaling Framework for Robotic Manipulation
FeaturedWen Ye, Peiyan Li, Tingyu Yuan, Yuan Xu, Xiangnan Wu, Chaoyang Zhao, Jing Liu, Nianfeng Liu, Yan Huang, Liang Wang · · 2026
Framework
N/A
License
N/A
Stars
0
Summary
Recently, a few works have made early attempts to study test-time scaling for embodied tasks.
Abstract Summary
Key Points
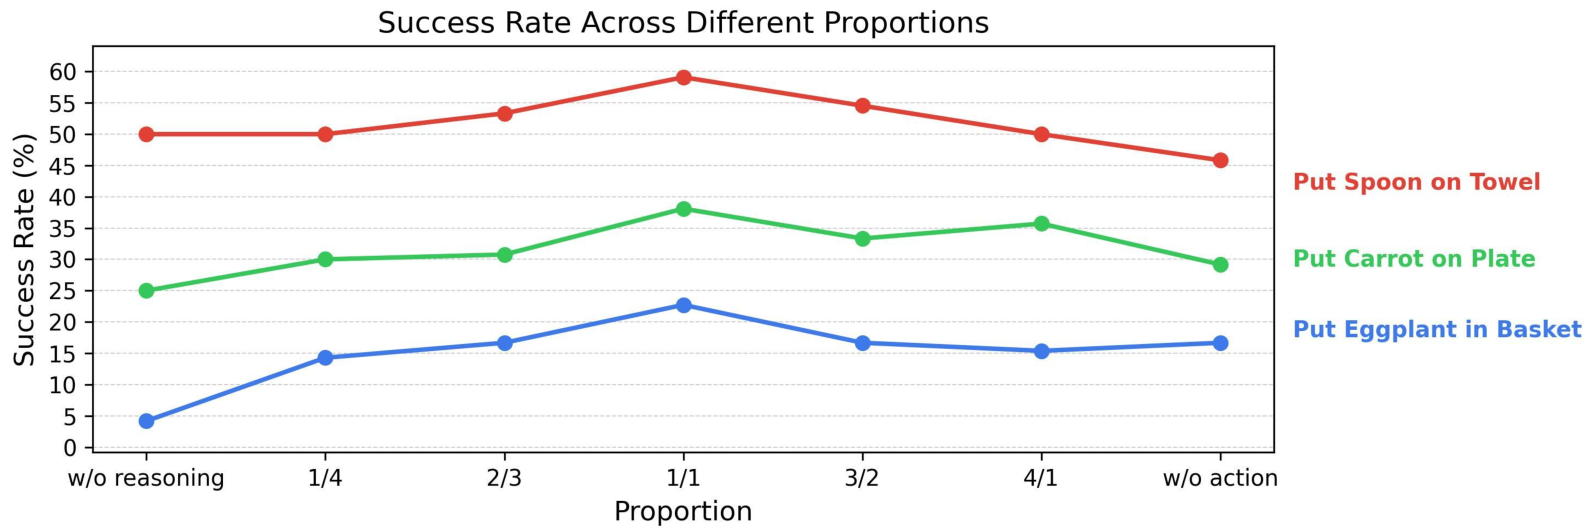
- Recently, a few works have made early attempts to study test-time scaling for embodied tasks. However, two major challenges remain unsolved: (1) reasoning can effectively improve the performance of the policy, but its scaling mechanism has seldom been studied; (2) historical information is essential, as embodied tasks are inherently long-horizon and sequential, making sole reliance on current observations for action scaling inadequate due to the lack of historical context utilization.
Embodied Test-Time Scaling
As shown in Fig. 2 , given a task instruction $I$ and the current observation $O_{t}$, our method first performs Reasoning-Action Joint Sampling (Sec. 3.2 ) . This step involves sampling a diverse set of candidate pairs $J_{t}^{i,j}=(C_{t}^{i},a_{t}^{i,j})$, where $C_{t}^{i}$ represents an intermediate reasoning step and $a_{t}^{i,j}$ is the corresponding action.
These joint samples, along with previous observations, are stored in a history buffer denoted as $H_{t}$.
Experiments
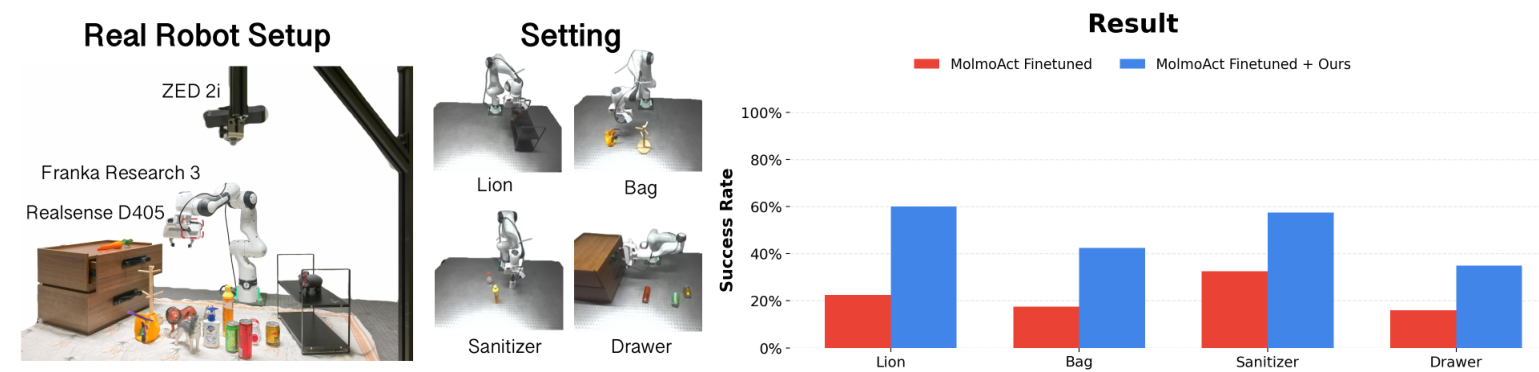
We conduct extensive experiments to evaluate the effectiveness of E-TTS. Our experiments are designed to address the following research questions: Q1: Is E-TTS general enough to enhance the performance of various manipulation methods that rely on different intermediate reasoning results?
Q2: Are specific designs for embodied scenarios, such as jointly scaling reasoning and action and incorporating feedback and history, truly beneficial? Q3: What is the efficiency–performance trade-off of E-TTS, and can it achieve substantial gains without highl...
Sources and Demonstrations
Figures are reproduced from Ye et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

Scalable Behavior Cloning with Open Data, Training, and Evaluation
Arthur Allshire, Himanshu Gaurav Singh, Ritvik Singh et al.
We introduce ABC, a fully open-source stack for manipulation with behavior cloning. At its core is ABC-130K: the largest open-source teleoperation dataset to date, featuring 3,500 hours of data spanning over 130K episodes across 195 diverse tasks.

LA4VLA: Learning to Act without Seeing via Language-Action Pretraining
Tao Lin, Yuxin Du, Yiran Mao et al.
Vision-Language-Action (VLA) models are commonly pretrained on robot demonstrations by jointly mapping visual observations and language instructions to actions. However, dense visual-action supervision can dominate the comparatively sparse language-action signal.

Learning to Fold: prizewinning solution at LeHome Challenge 2026 (1st place online, 2nd offline)
Ilia Larchenko
I describe my solution to the LeHome Challenge 2026, an ICRA 2026 competition on bimanual garment folding. The system placed 1st of 62 teams in the online (simulation) round and 2nd in the real-world final. It improves a vision-language-action (VLA) policy with a reinforcement-learning loop.
RotVLA: Rotational Latent Action for Vision-Language-Action Model
Qiwei Li, Xicheng Gong, Xinghang Li et al.
Latent Action Models (LAMs) have emerged as an effective paradigm for handling heterogeneous datasets during Vision-Language-Action (VLA) model pretraining, offering a unified action space across embodiments.