
IntentVLA: Short-Horizon Intent Modeling for Aliased Robot Manipulation
FeaturedShijie Lian, Bin Yu, Xiaopeng Lin, Zhaolong Shen, Laurence Tianruo Yang, Yurun Jin, Haishan Liu, Changti Wu, Hang Yuan, Cong Huang, Kai Chen · · 2026
Framework
N/A
License
N/A
Stars
8
Summary
Robot imitation data are often multimodal: similar visual-language observations may be followed by different action chunks because human demonstrators act with different short-horizon intents, task phases, or recent context.
Abstract Summary
Key Points
- Introduces a new dataset or benchmark
- Provides open-source code or data
AliasBench: Ambiguity-Aware Benchmark Design
To evaluate whether a policy can resolve aliased observations from recent context, we build AliasBench on top of RoboTwin2 Chen et al. (2025) . AliasBench contains 12 manipulation tasks together with matched simulation training data and held-out evaluation environments.
The benchmark targets an underexplored gap in current VLA evaluation: most standard benchmarks measure whether a policy can complete a manipulation task, but they rarely isolate whether the policy can maintain a consistent decision when the current observation is aliased.
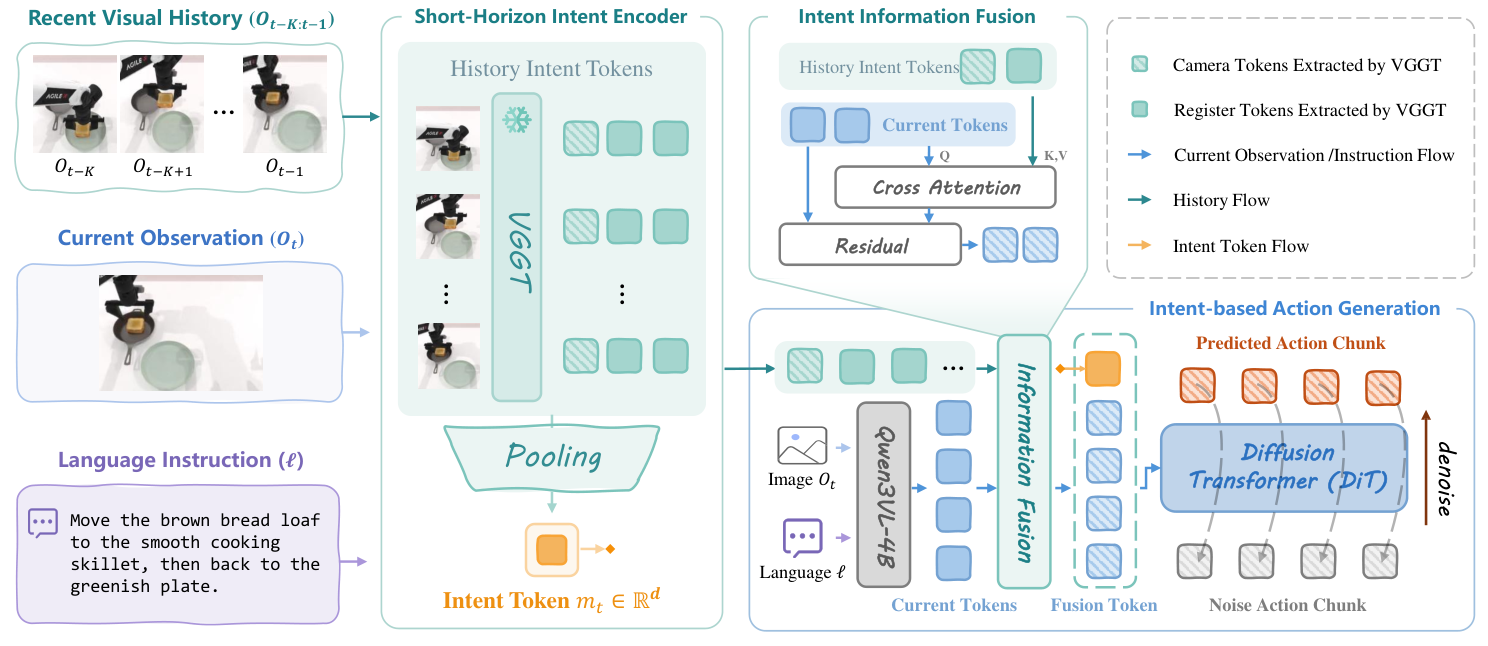
Method
We model manipulation as a partially observable decision process with latent state $s_{t}\in\mathcal{S}$, observation $o_{t}\in\mathcal{O}$, and action $a_{t}\in\mathcal{A}$. This viewpoint is used only to motivate why recent observations can disambiguate the current frame.
At time step $t$, the robot observes $o_{t}$, receives a language instruction $\ell$, and predicts a future action chunk where $H$ is the chunk horizon and $d_{a}$ is the action dimension.
Experiment
We begin with AliasBench, which directly tests the failure mode identified in the introduction. On this benchmark, we compare against Qwen3-VL-GR00T and several history-as-extra-context baselines that feed multiple past frames directly into the Qwen backbone. We then evaluate on SimplerEnv Li et al. (2024c) , LIBERO Liu et al. (2023) , RoboCasa-GR1 Tabletop Tasks Nasiriany et al. (2024) ; Bjorck et al.
(2025) , and a real-world snack-cleanup task to test whether the same design transfers beyond the controlled ambiguity benchmark.
Sources and Demonstrations
Figures are reproduced from Lian et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

Scalable Behavior Cloning with Open Data, Training, and Evaluation
Arthur Allshire, Himanshu Gaurav Singh, Ritvik Singh et al.
We introduce ABC, a fully open-source stack for manipulation with behavior cloning. At its core is ABC-130K: the largest open-source teleoperation dataset to date, featuring 3,500 hours of data spanning over 130K episodes across 195 diverse tasks.
Hand-in-the-Loop: Improving Dexterous VLA via Seamless Interventional Correction
Zhuohang Li, Liqun Huang, Wei Xu et al.
Vision-Language-Action (VLA) models are prone to compounding errors in dexterous manipulation, where high-dimensional action spaces and contact-rich dynamics amplify small policy deviations over long horizons.

LA4VLA: Learning to Act without Seeing via Language-Action Pretraining
Tao Lin, Yuxin Du, Yiran Mao et al.
Vision-Language-Action (VLA) models are commonly pretrained on robot demonstrations by jointly mapping visual observations and language instructions to actions. However, dense visual-action supervision can dominate the comparatively sparse language-action signal.

E-TTS: A New Embodied Test-Time Scaling Framework for Robotic Manipulation
Wen Ye, Peiyan Li, Tingyu Yuan et al.
Recently, a few works have made early attempts to study test-time scaling for embodied tasks.