
FIRE-LIVWO: Robust LiDAR-Inertial-Visual-Wheel Odometry via Failure-Immune mmWave Radar Enhancement
Kun Hu, Menggang Li, Kaidi Wu, Zhiwen Jin, Yingjie Zhao, Chaoquan Tang, Eryi Hu, Gongbo Zhou · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Achieving robust SLAM in large-scale underground coal mines with complex structures and severe degeneracies remains highly challenging.
Abstract Summary
Key Points
- Achieving robust SLAM in large-scale underground coal mines with complex structures and severe degeneracies remains highly challenging.
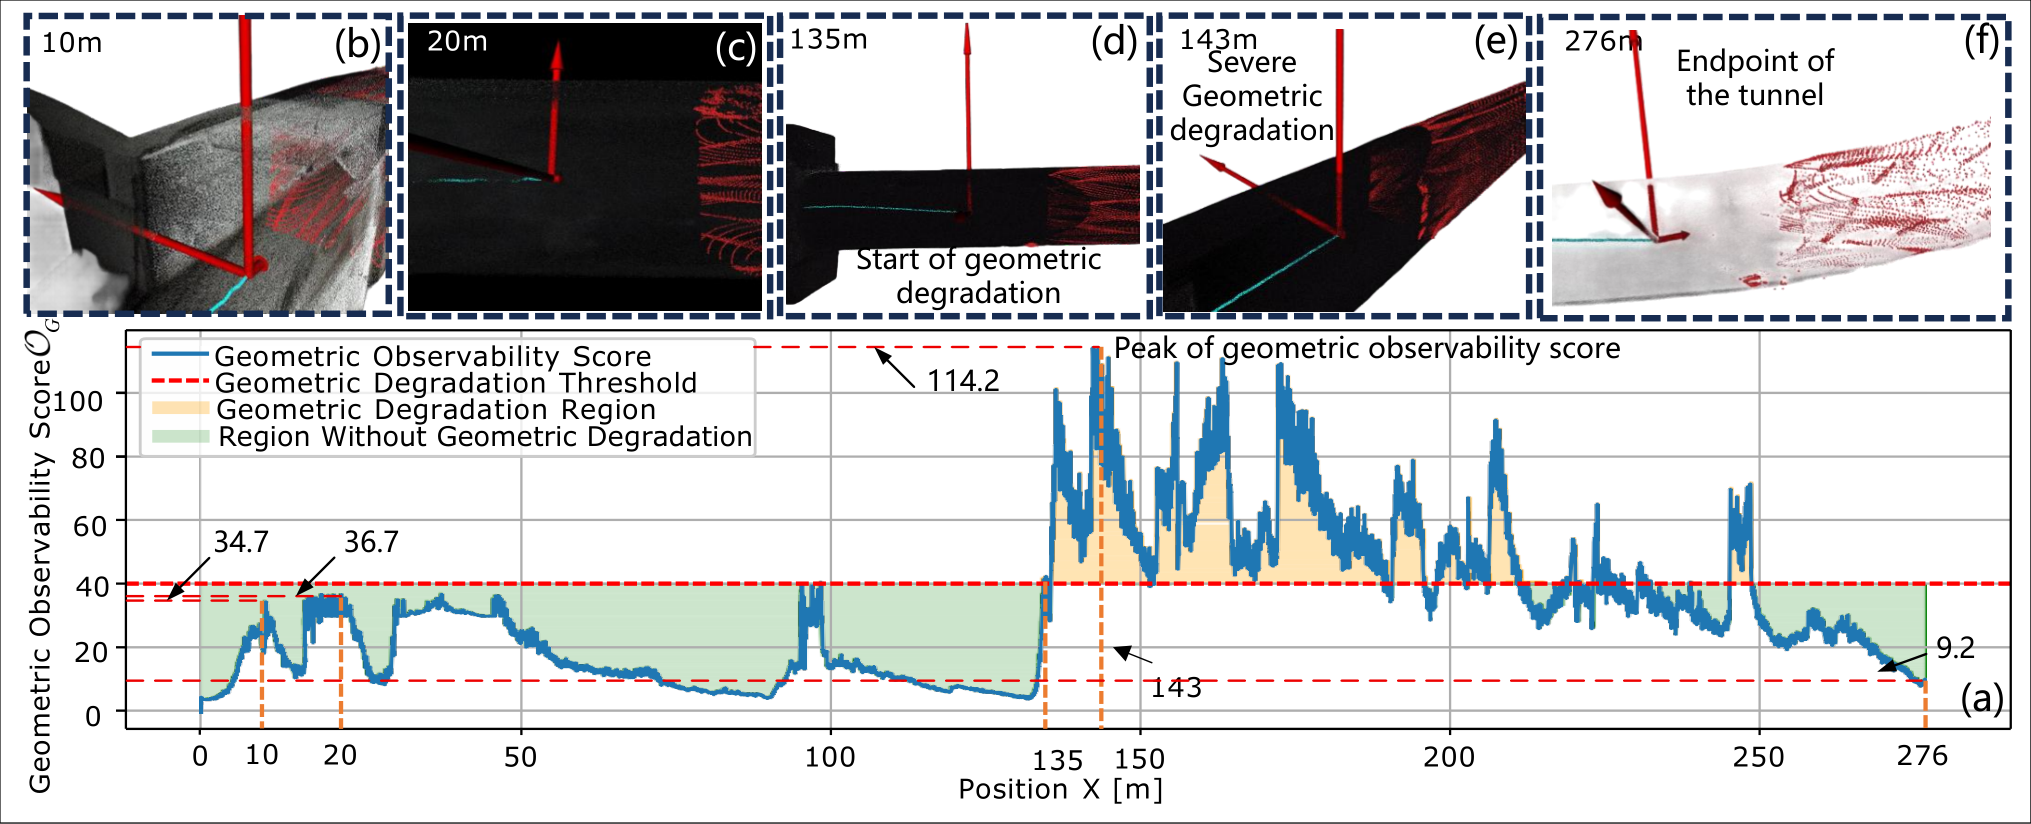
- Dense smoke and dust cause substantial loss of visual information and degrade LiDAR point-cloud features, while long, self-similar corridors induce geometric degeneration, leading to pronounced odometry drift.
- To address these issues, we propose FIRE-LIVWO: Failure-Immune mmWave Radar-Enhanced LiDAR-Inertial-Visual-Wheel Odometry, a tightly coupled multi-modal odometry framework based on an iterated error-state Kalman filter (IESKF).
- The framework fuses 4D mmWave radar, LiDAR, and visual features within a unified VoxelMap and jointly constructs LiDAR-radar point-to-plane residuals and sparse visual photometric residuals.
- In smoke-filled environments, we exploit the strong penetration of 4D mmWave radar and introduce pointwise Doppler velocity constraints to preserve state observability.
Preliminary
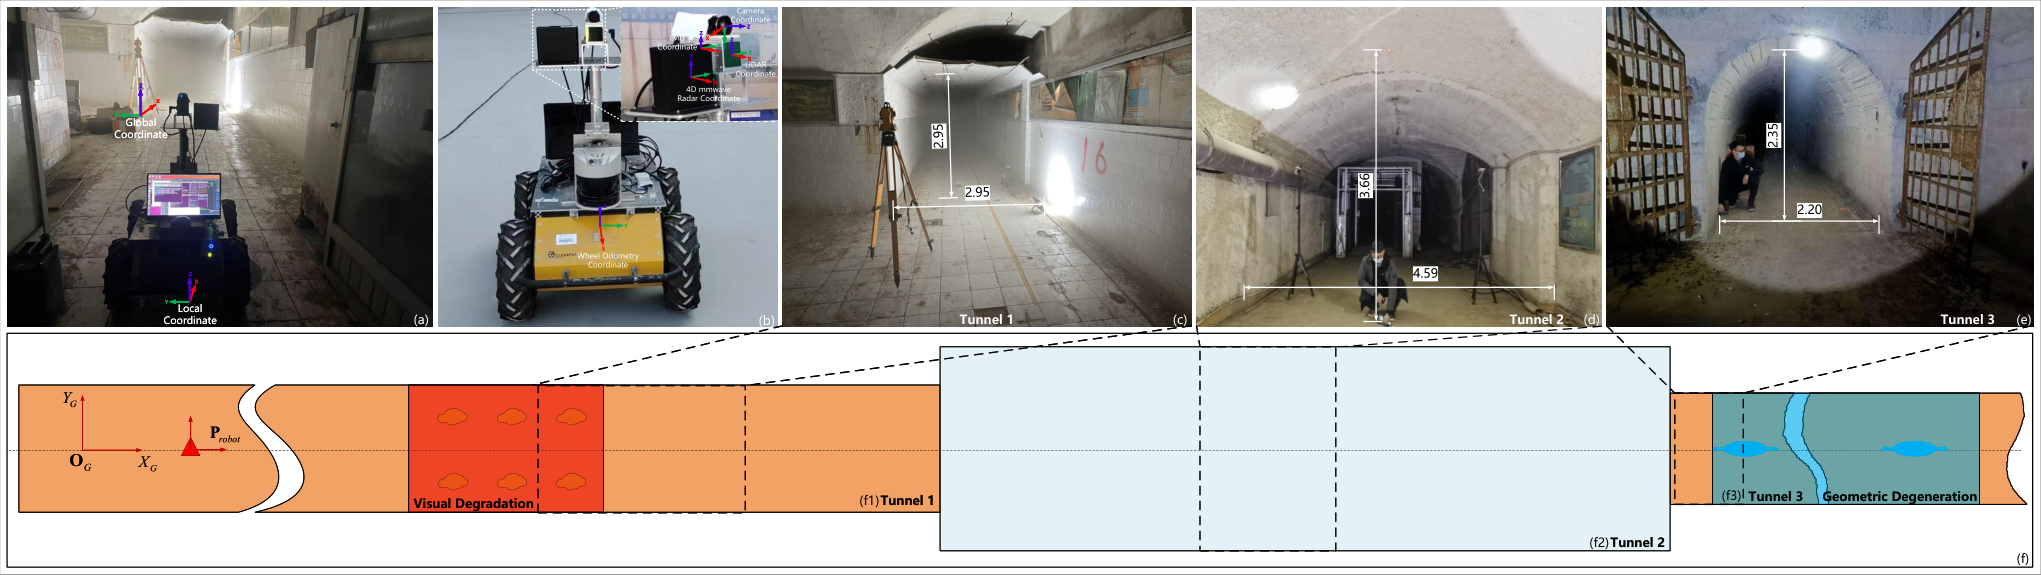
We assume that the temporal offsets among the five sensors—LiDAR, IMU, camera, wheel odometer, and 4D mmWave radar—are known (via pre-calibration or synchronization). The IMU frame, denoted by $I$, is used as the body frame, and the global frame, denoted by $G$, is defined at the origin of the total-station coordinate system (Table I ).
All sensors are rigidly mounted, and the LiDAR, camera, and IMU are hardware-synchronized.
System Overview
Our objective is to estimate the 6-DoF pose of a coal-mine robot while constructing a global map. The overall system architecture is shown in Fig. 1 . The system comprises three modules: (i) Radar-Enhanced LiDAR Visual Inertial Constraint Module: We extract point clouds from mmWave radar echoes. Using ego-velocity estimation, we reject outliers and construct Doppler-velocity constraints (Chapter V-A ).
Methodology
We employ an adaptive, octree-based voxel map (Fig. 1 ) with a root voxel size of 0.5 m. Each leaf voxel stores planar features $\Pi\triangleq(\mathbf{n},\mathbf{q},\boldsymbol{\Sigma}_{\mathbf{n},\mathbf{q}})$ and LiDAR points ${}^{L}\mathbf{p}_{i}$.
A subset of points is augmented with $8\times 8$ image patches to form a set of visual map points, denoted by $\mathcal{P}^{map}$: converged points retain only the reference patch, whereas unconverged points additionally store other visible patches.
Experiment
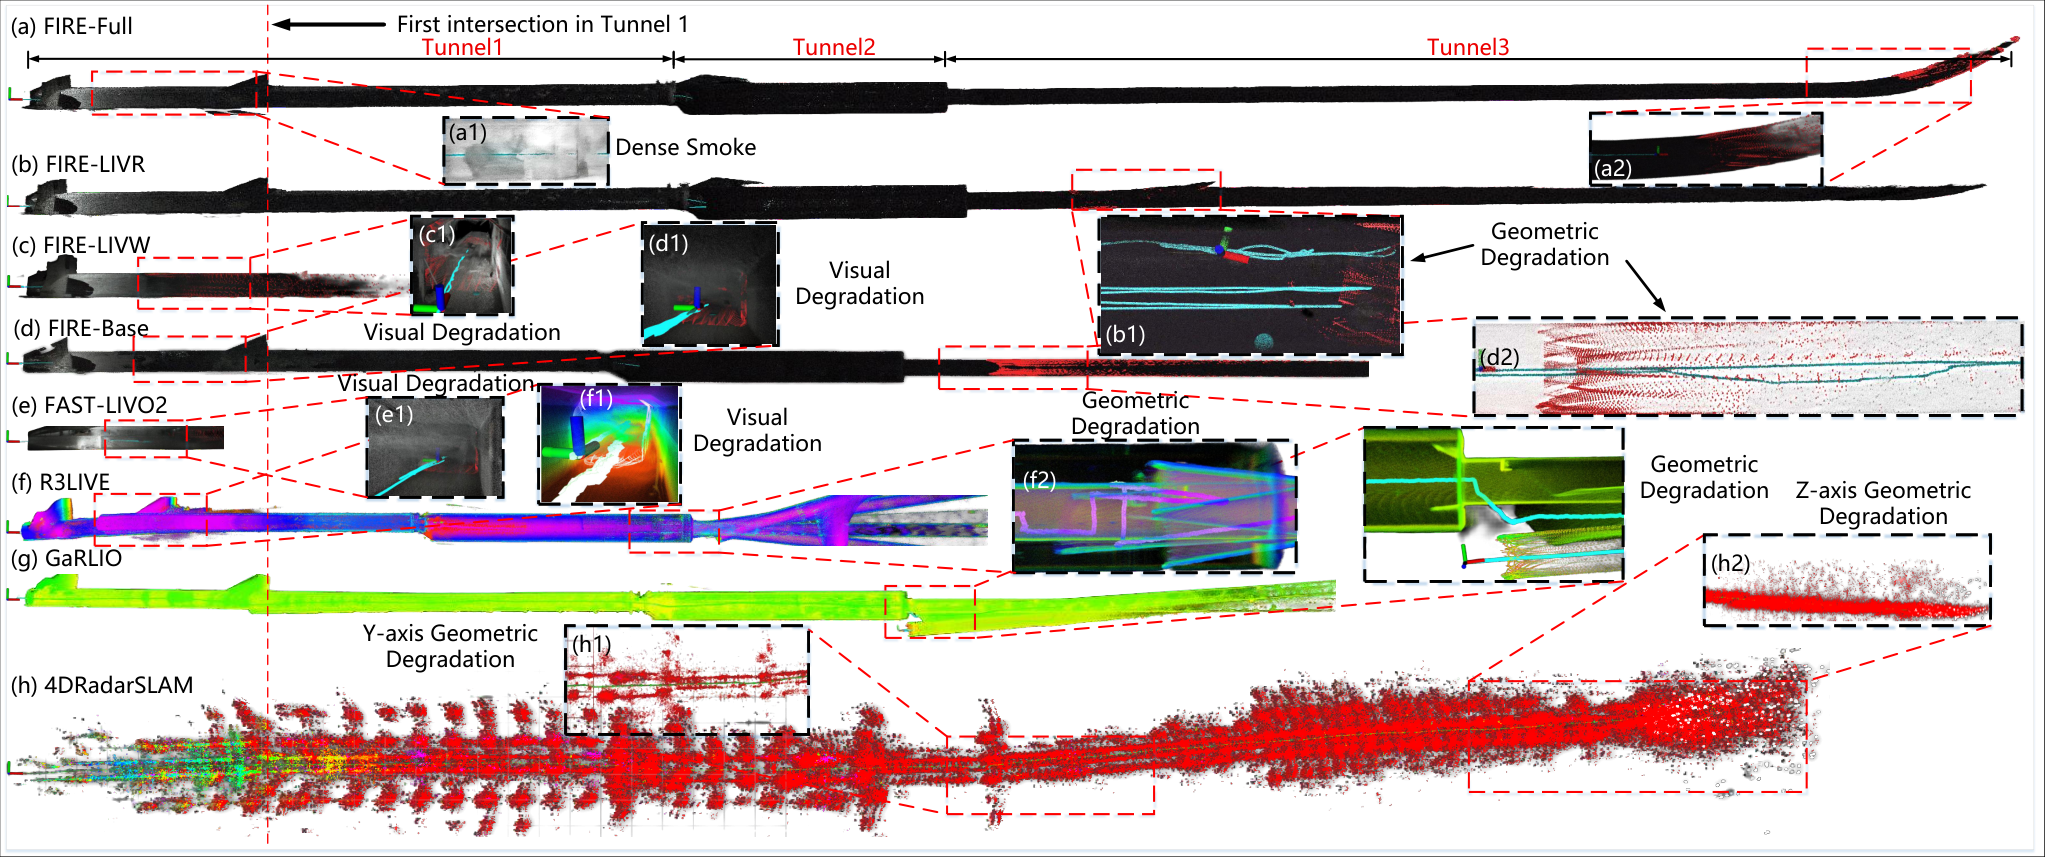
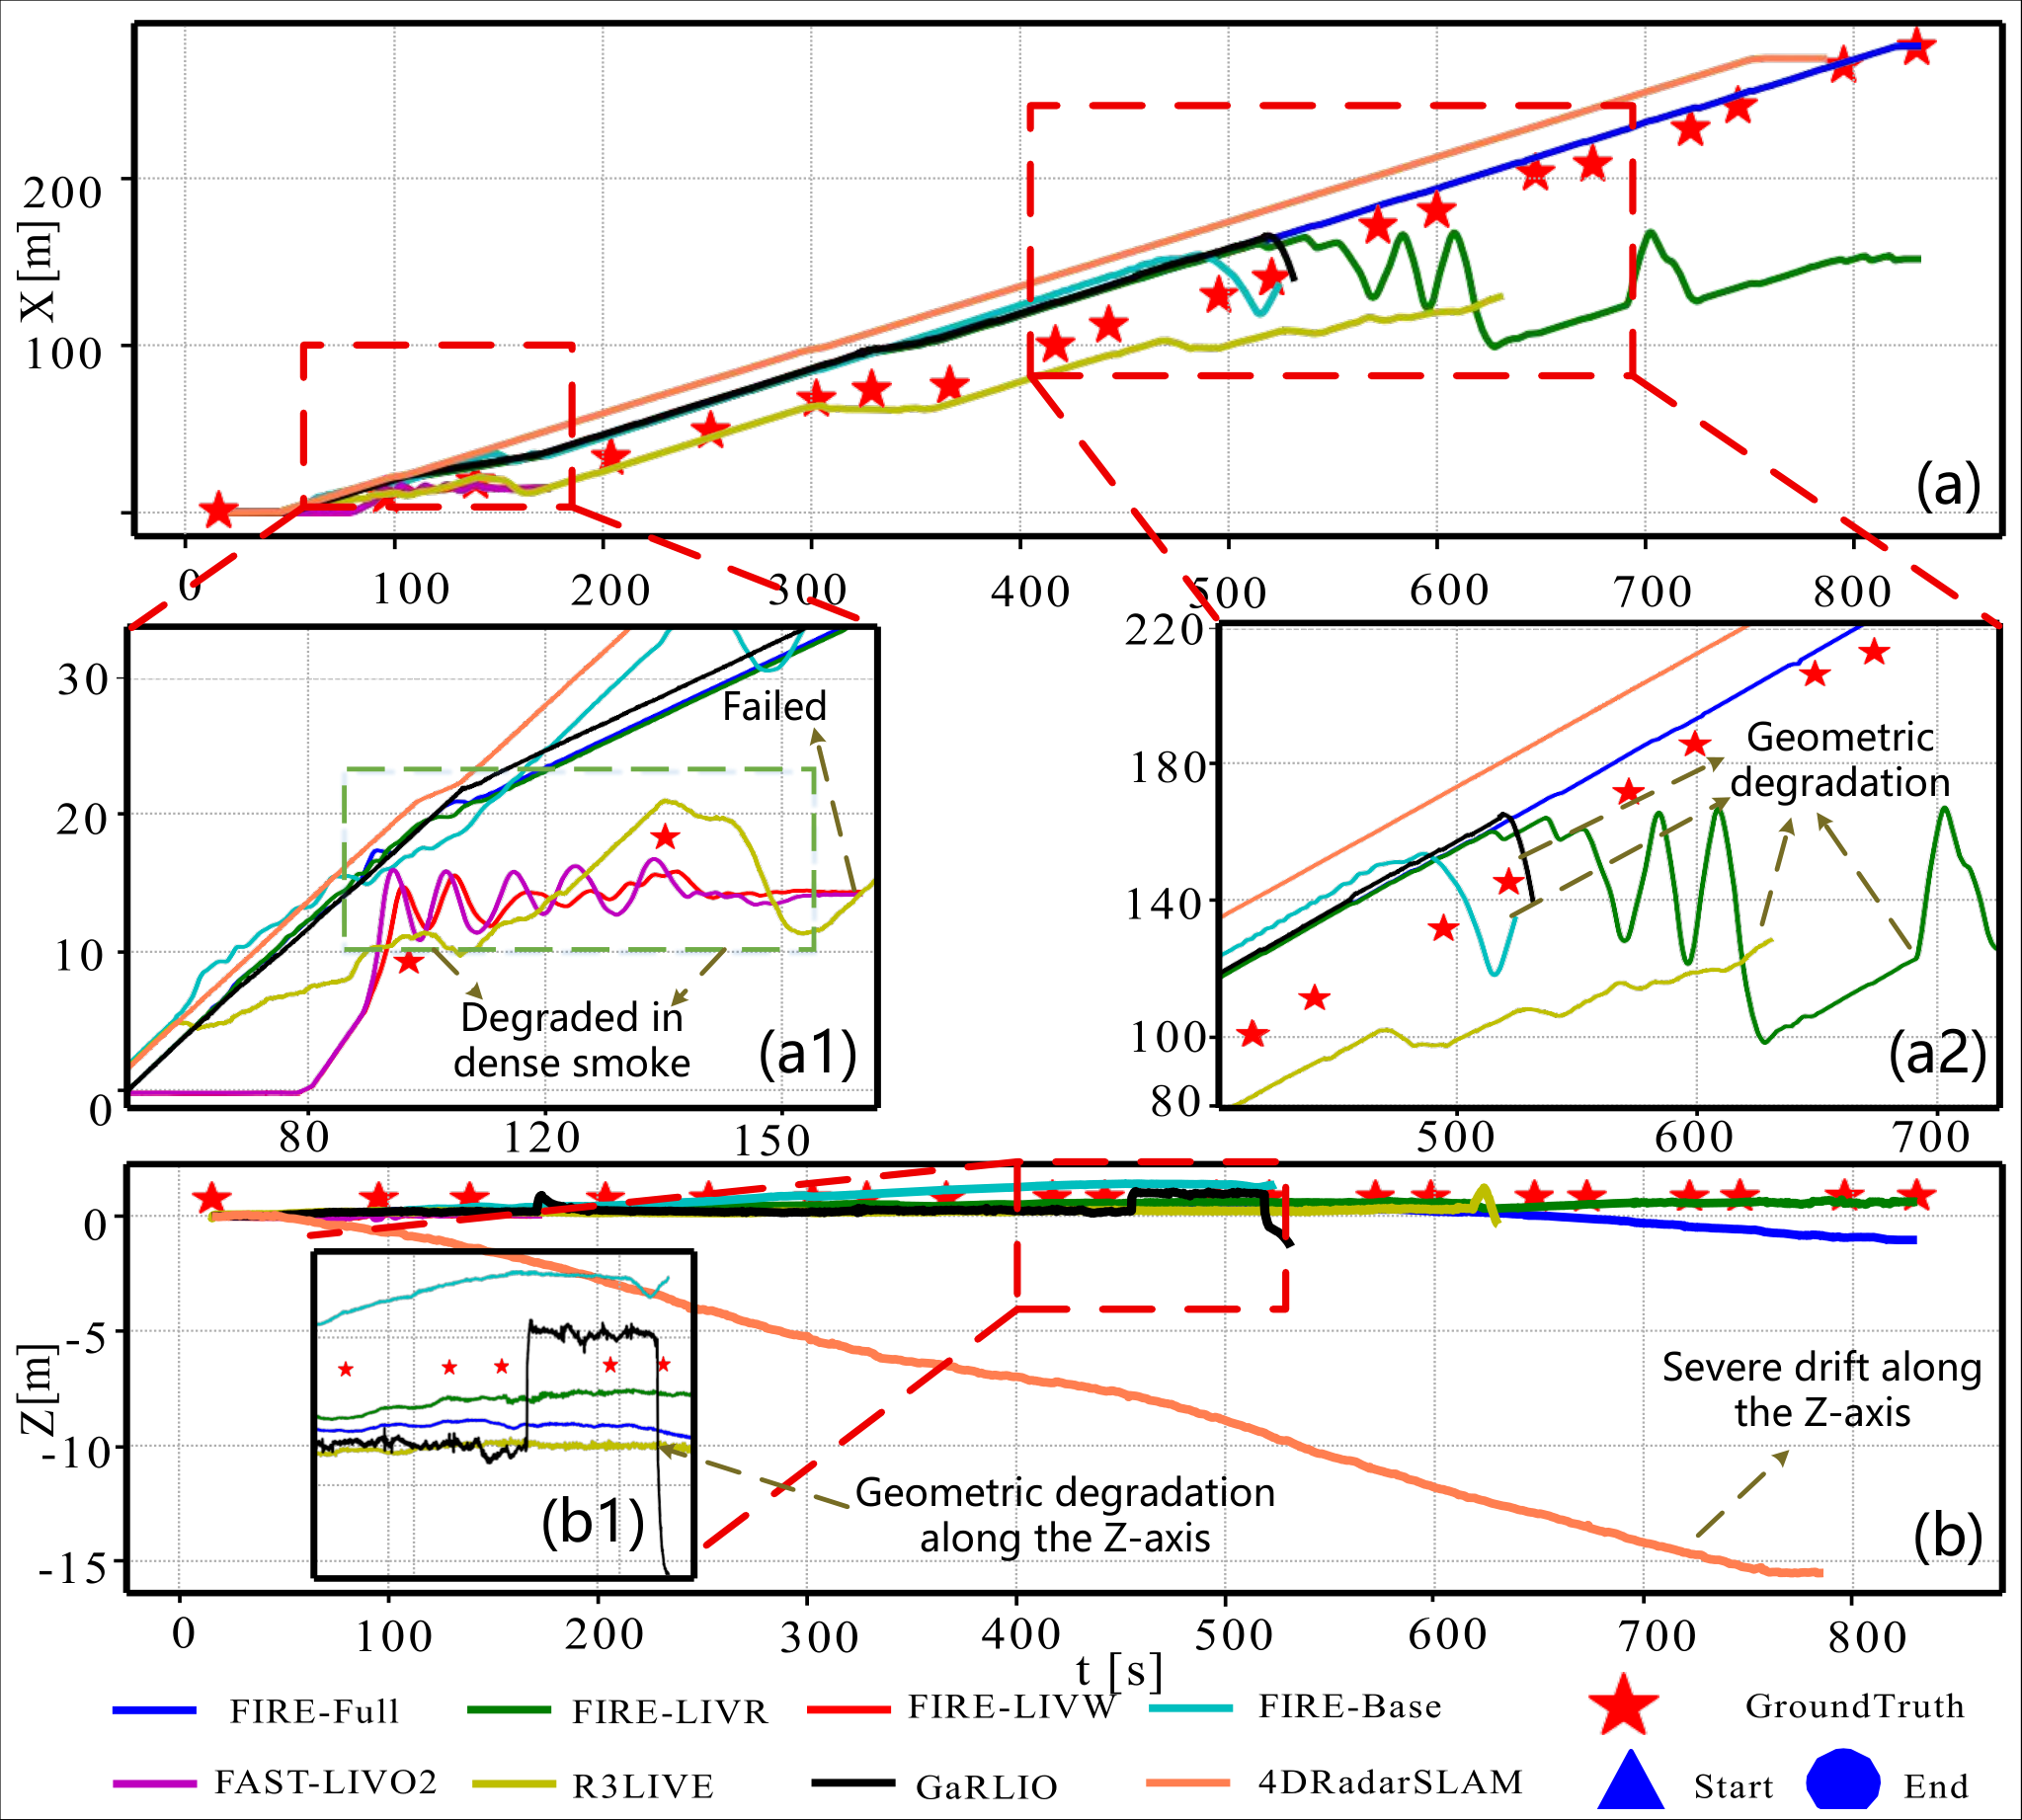
We conducted field experiments in severely degenerate underground coal-mine tunnels. The mobile platform is a Husky A200 equipped with a Livox AVIA LiDAR (with a built-in IMU), a Hikvision camera (MVS-CU013-A0UC), an Oculii Eagle 4D mmWave radar, and the chassis wheel odometer.
The LiDAR–camera and radar–IMU extrinsics were carefully calibrated, and a hardware synchronizer time-synchronized the LiDAR, IMU, camera, and mmWave radar. Ground-truth points were measured using a total station.
Sources and Demonstrations
Figures are reproduced from Hu et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

A Low-Cost, Open Platform for End-to-End Autonomous Driving on a Miniature Ackermann Vehicle
Gustavo Claudio Karl Couto, Eric Aislan Antonelo, Gabriel George Zipperer
This paper presents a low-cost, open experimental platform for research in end-to-end autonomous driving with miniature Ackermann vehicles.

AcousticDiffusion: Semantically Conditioned Audio-Guided Diffusion Policy for Search-and-Rescue Assistance
Iana Zhura, Didar Seyidov, Dmitrii Plotnikov et al.
Navigating toward human callers is an important capability for rescue robots operating where visual contact is degraded or occluded. We present AcousticDiffusion, a semantically conditioned, audio-guided diffusion policy for human-directed navigation.

Aim Short to Reach Far: Your Frozen World Model Can Plan Better Than You Think
Xvyuan Liu, Jianjie Fang, Chen Gao et al.
Planners built on visual world models commonly score each predicted outcome by its distance to the encoded goal image. We show that this target can limit control even with exact dynamics and globally optimal short-horizon search: reaching a goal may require actions that initially move away from it.

Autonomous Droplet Navigation via Model-Based Reinforcement Learning: Zero-Shot Transfer and Emergent Dynamics
Rajneesh Anand, Mayuresh V. Kothare
Self-driving laboratories (SDLs) are transforming chemical and materials discovery through closed-loop automation, yet automated infrastructure for physical manipulation of soft, deformable matter remains beyond current robotic platforms.