

CrossDepth: Geometry-Constrained Attention for Generalizable Multi-View Surround Depth Estimation
Samer Abualhanud, Max Mehltretter · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Reliable 3D understanding of the surrounding environment is a core requirement for autonomous driving. Multi-view surround camera rigs provide broad scene coverage, but the spatially adjacent images typically overlap only minimally.
Abstract Summary
Key Points
- Reliable 3D understanding of the surrounding environment is a core requirement for autonomous driving.
- Multi-view surround camera rigs provide broad scene coverage, but the spatially adjacent images typically overlap only minimally.
- Consequently, the depth of most pixels must be inferred from monocular appearance cues
- These cues can appear differently across images and may therefore be interpreted differently by the depth estimation model.
- We target two main sources of cross-image inconsistency: differences in camera intrinsics and the limited receptive field of each image.
Methodology
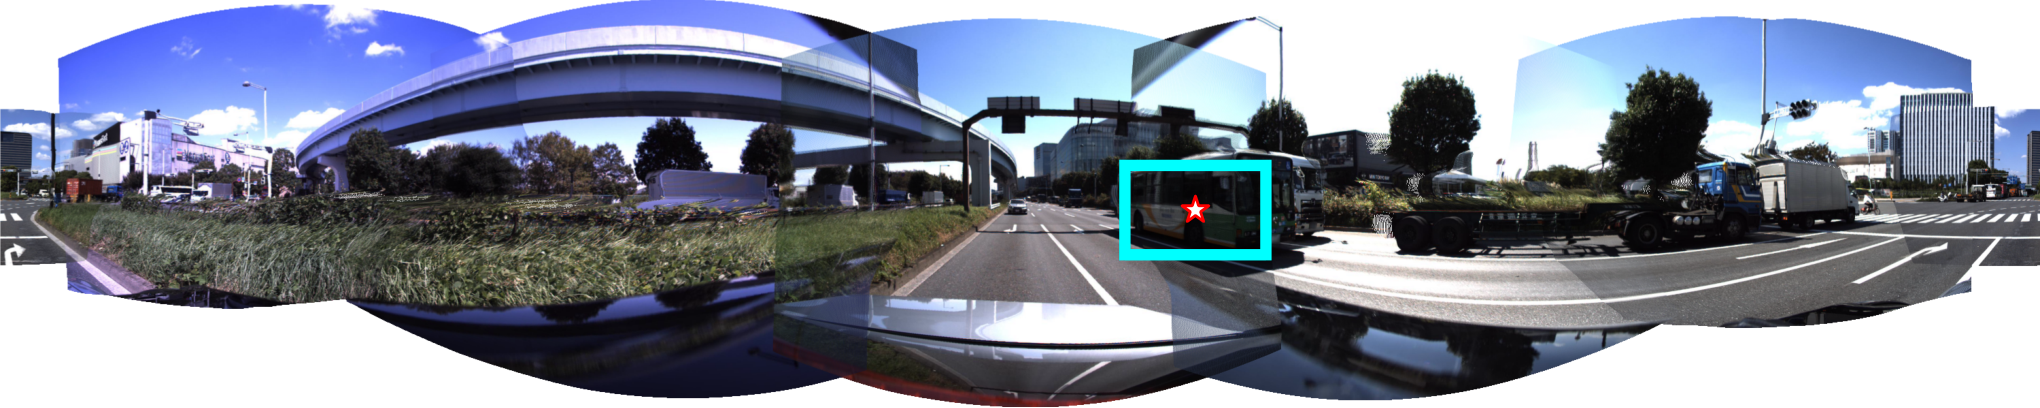
Given a surround-view camera rig consisting of $N$ time-synchronized cameras with overlapping fields of view, known intrinsic calibration parameters, and metrically scaled relative poses, the objective is to estimate a metric depth map for each input image. Our depth estimation network follows an encoder-decoder architecture, inspired by [ 31 , 51 ] .
For frame $t$, the input images are denoted by $\mathbf{I}_{t}\in\mathbb{R}^{N\times H\times W\times 3}$, where $H$ and $W$ denote the image height and width, respectively.
Experiments
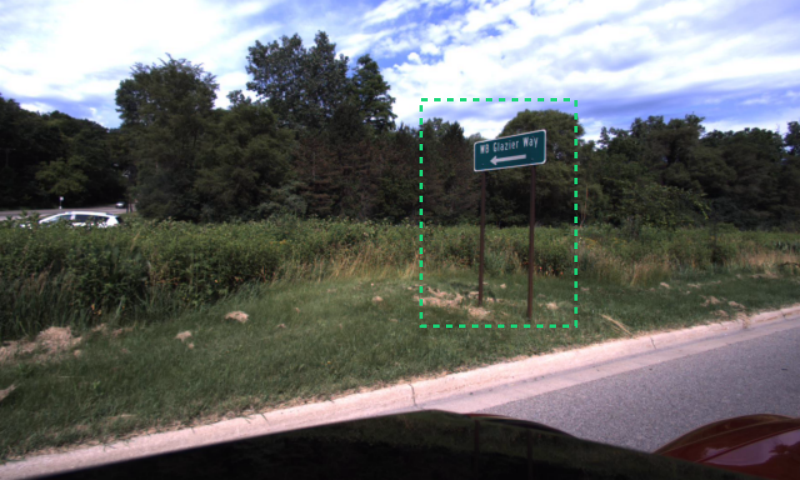
We compare our method with five state-of-the-art self-supervised approaches: FSM [ 16 ] , SurroundDepth [ 47 ] , VFDepth [ 22 ] , CVCDepth [ 6 ] , and CylinderDepth [ 1 ] . We report results for the entire image and the overlapping regions under in-domain and cross-domain evaluation.
We further conduct ablation studies to assess the effects of cross-image attention, geometric attention constraints, and camera-aware ray embeddings. Experiments are conducted on two surround-view datasets, DDAD [ 15 ] and nuScenes [ 4 ] .
Sources and Demonstrations
Figures are reproduced from Abualhanud et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

4D Radar Perception Algorithms for Autonomous Driving: A Review
Xumin Wu, Jun Zhou, Jilin Mei et al.
Research on 4D millimeter-wave radar perception algorithms has flourished in recent years, extending from signal processing and object detection to semantic segmentation, motion estimation, occupancy prediction, and dynamic scene reconstruction.
A Review Of Robotic World Models For Dynamic Environments Based On Factor And Scene Graphs
Marco Giberna, Miguel Fernandez-Cortizas, Jose Luis Sanchez Lopez et al.
Models based on graphs have emerged in robotics as a powerful foundation for internal world representations, where factor and scene graphs are among the most prominent model types found in the related literature and in successful robotic solutions.

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.

Aim Short to Reach Far: Your Frozen World Model Can Plan Better Than You Think
Xvyuan Liu, Jianjie Fang, Chen Gao et al.
Planners built on visual world models commonly score each predicted outcome by its distance to the encoded goal image. We show that this target can limit control even with exact dynamics and globally optimal short-horizon search: reaching a goal may require actions that initially move away from it.