
Towards Surgical World-Action Modeling: A Preliminary Joint Visual-Trajectory Forecasting for Surgical Motion Planning
Weiliang Huang, Huanrong Liu, Bob Zhang, Qi Dou, Zhen Chen, Yun Gu, Guy Rosman, Qingbiao Li · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Reliable surgical planning requires models to anticipate not only how instruments will move, but also how the operative visual state will evolve together with such motion. Existing approaches typically treat future scene generation and instrument trajectory prediction as two separate tasks.
Abstract Summary
Key Points
- Reliable surgical planning requires models to anticipate not only how instruments will move, but also how the operative visual state will evolve together with such motion.
- Existing approaches typically treat future scene generation and instrument trajectory prediction as two separate tasks.
- Scene-only models cannot directly evaluate the accuracy of future instrument motion at the trajectory level, while trajectory-only models fail to capture the visual consequences of instrument movement, leaving the consistency between predicted trajectories and future scene evolution unaddressed.
- Jointly forecasting both provides a more complete account of surgical action-scene dynamics by enabling explicit trajectory-level evaluation while simultaneously modeling the corresponding visual evolution.
- To bridge this gap, we present a preliminary joint visual-trajectory world-action model that simultaneously forecasts future visual states and instrument trajectories from historical surgical observations.
Method
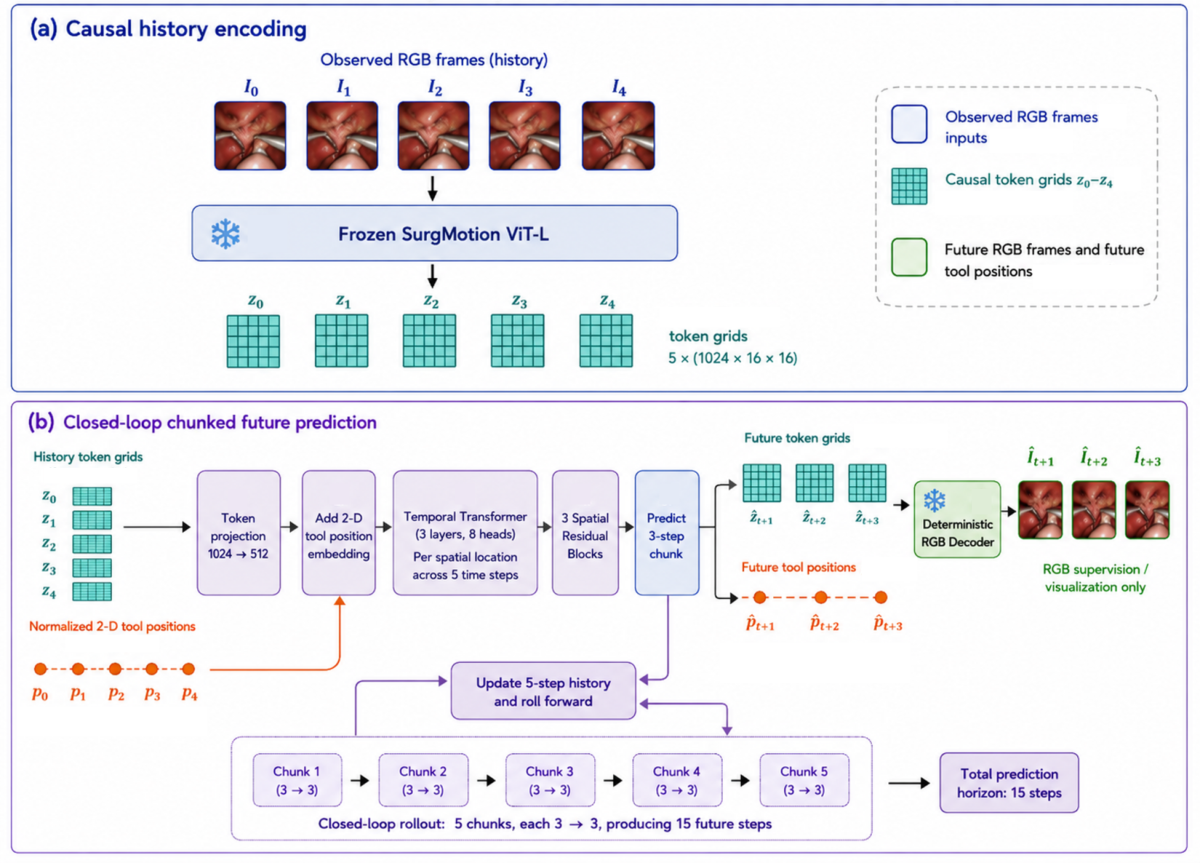
Given a sequence of $K$ observed surgical frames, and the corresponding historical two-dimensional instrument trajectory, our objective is to jointly predict future visual states and instrument trajectories over a horizon of $H$ steps. Instead of directly predicting future frames in the pixel space, we represent each future visual state using a latent feature representation.
Experiments
We conduct experiments on SurgWMBench [ 11 ] , a vision-based surgical motion planning benchmark constructed from SAR-RARP50 [ 13 ] , which contains real clinical videos of Robot-Assisted Radical Prostatectomy (RARP) performed using the da Vinci surgical system. SurgWMBench focuses on suturing motions and extracts effective needle insertion and extraction actions as individual motion segments.
The benchmark contains 1,637 valid segments, corresponding to 32,740 annotated surgical frames.
Sources and Demonstrations
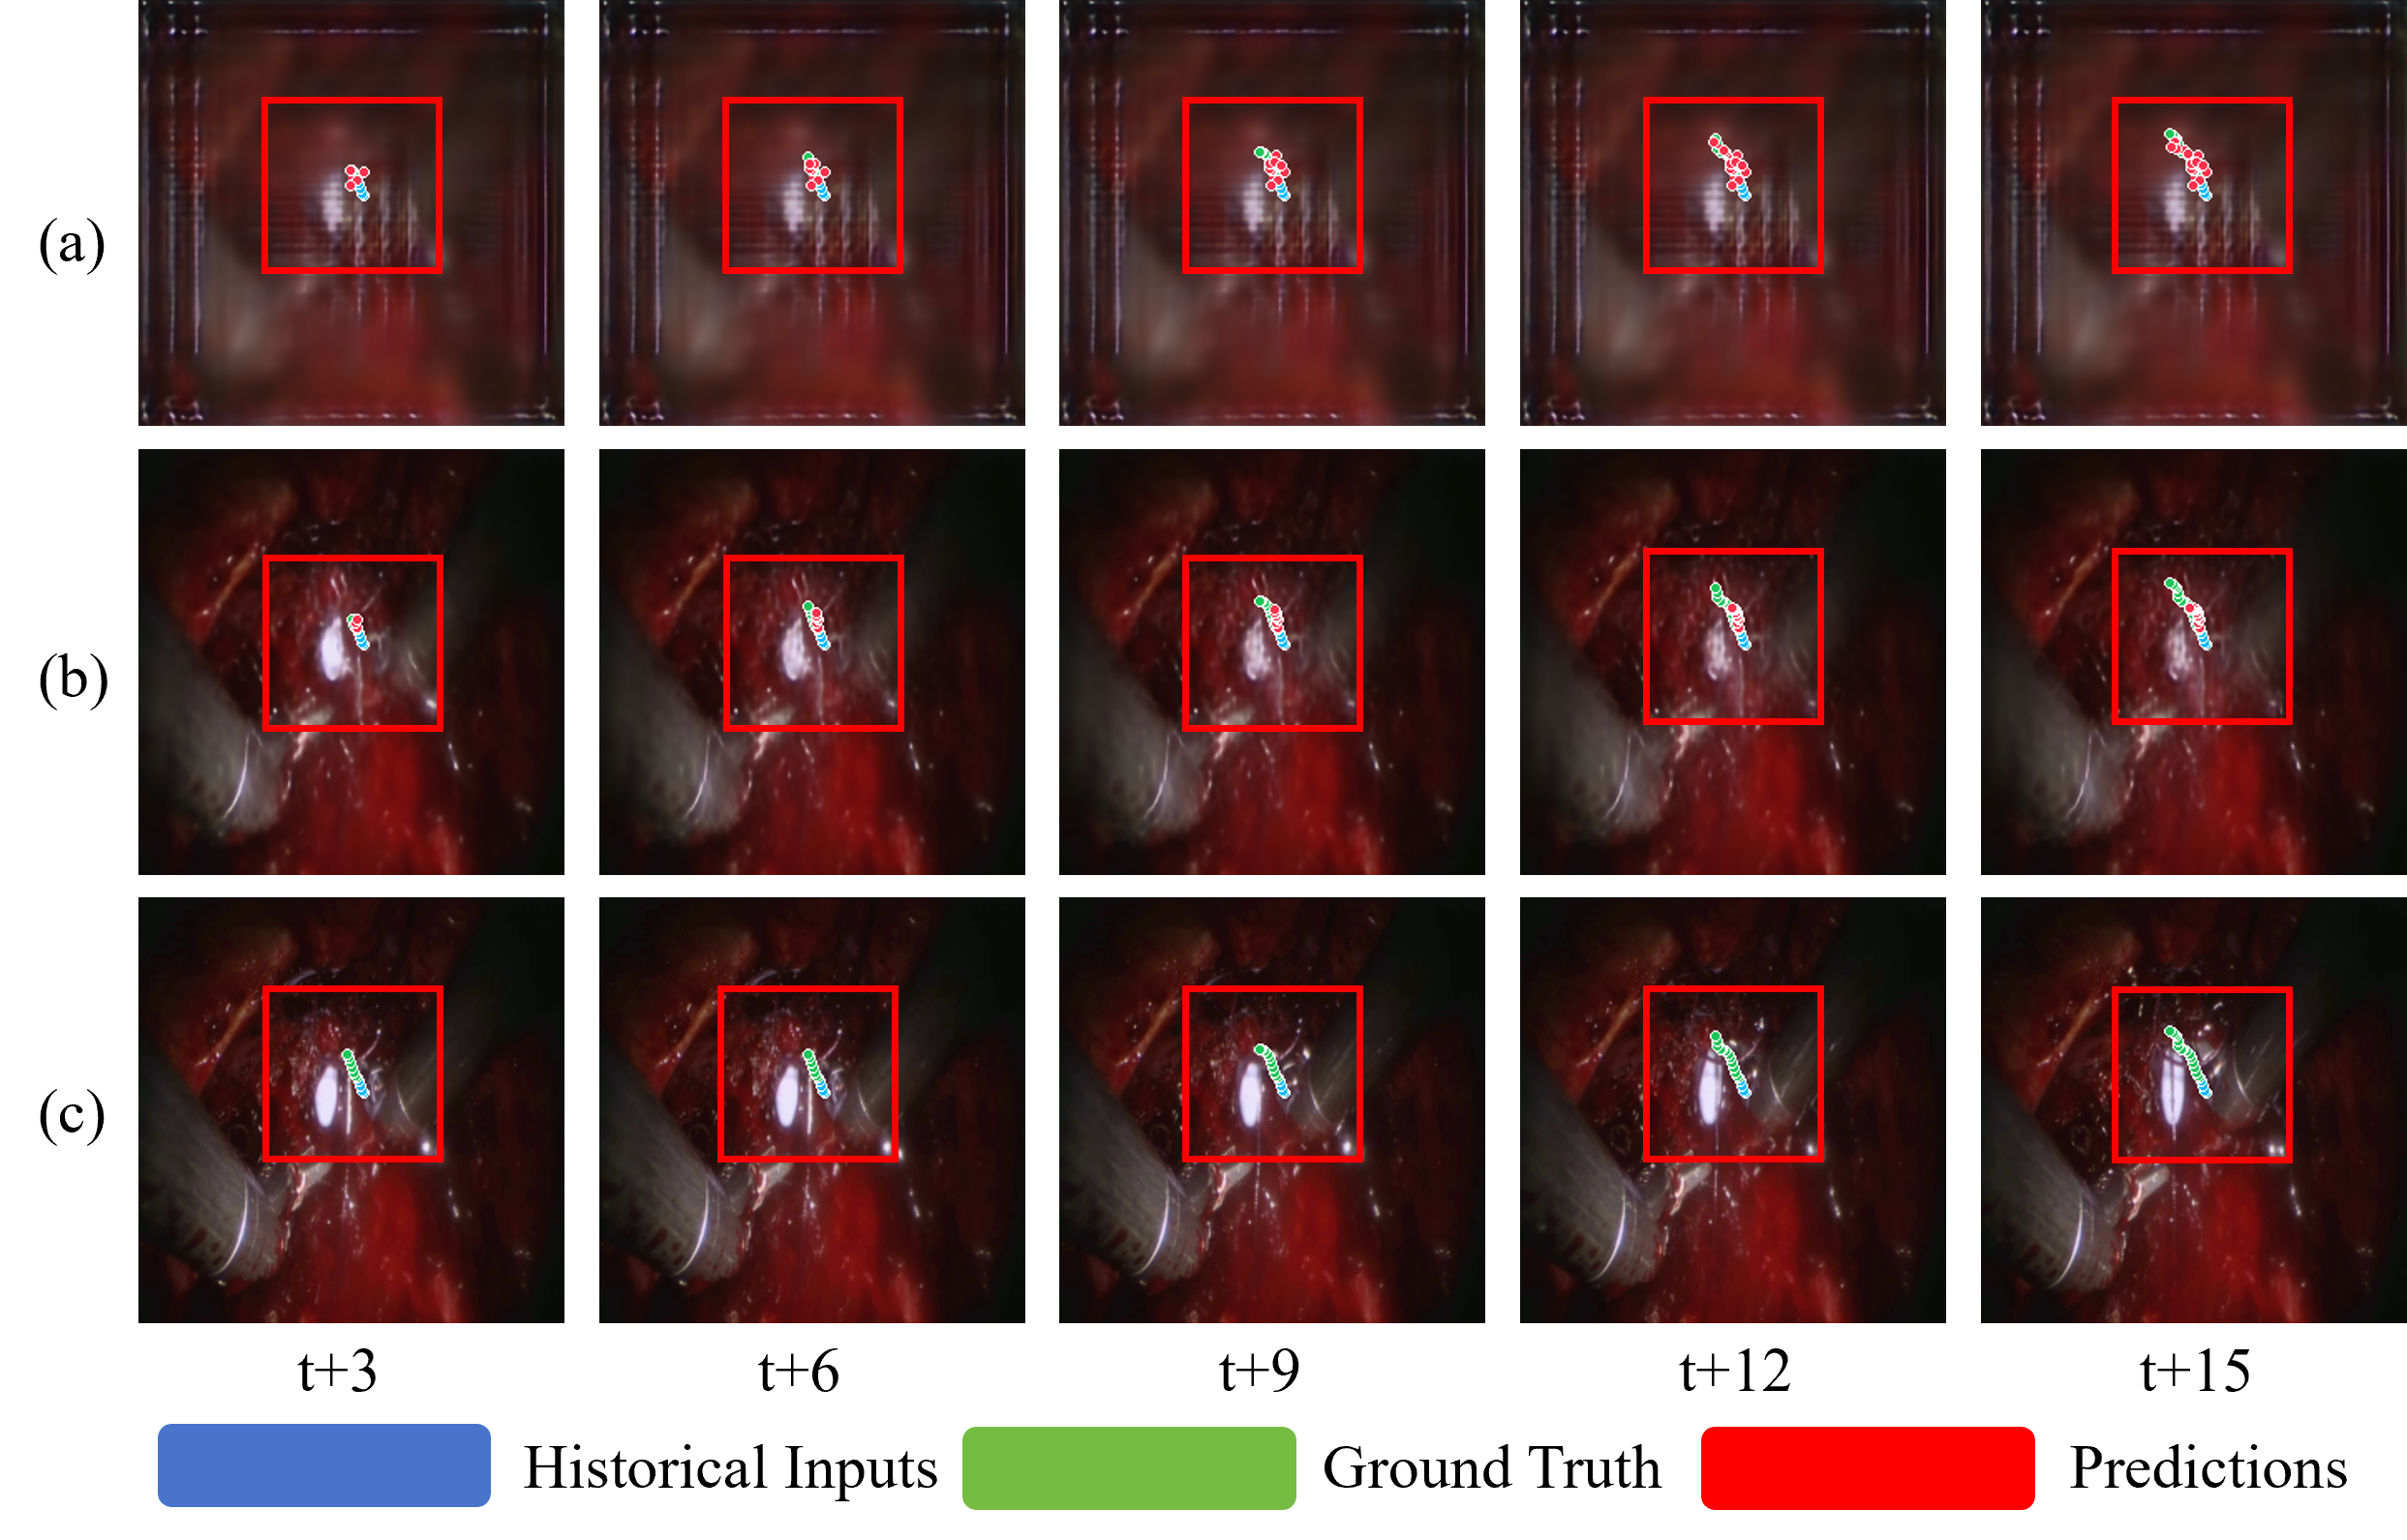
Figures are reproduced from Huang et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

Aim Short to Reach Far: Your Frozen World Model Can Plan Better Than You Think
Xvyuan Liu, Jianjie Fang, Chen Gao et al.
Planners built on visual world models commonly score each predicted outcome by its distance to the encoded goal image. We show that this target can limit control even with exact dynamics and globally optimal short-horizon search: reaching a goal may require actions that initially move away from it.
Beyond Episodic Evaluation: Memory Architectural Bottlenecks in Sequential Embodied Question Answering
Zikui Cai, Kaushal Janga, Tan Dat Dao et al.
Embodied question answering (EQA) is traditionally evaluated under an episodic formulation, where agents solve each task independently and reset internal state between episodes.
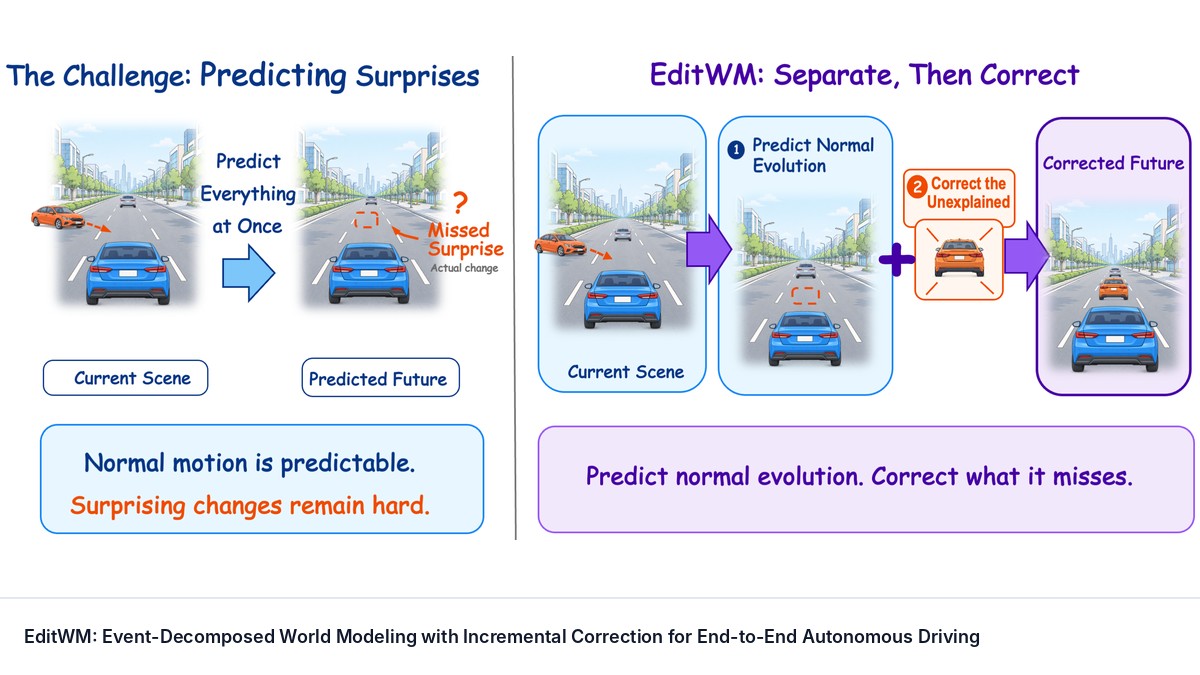
EditWM: Event-Decomposed World Modeling with Incremental Correction for End-to-End Autonomous Driving
Junjie Yang, Qingwei Zeng, Youyou Li et al.
World models support autonomous driving by predicting the scene evolution associated with candidate trajectories. Driving dynamics differ in predictability, motivating a distinction between regular evolution and event-induced deviations that call for selective correction.
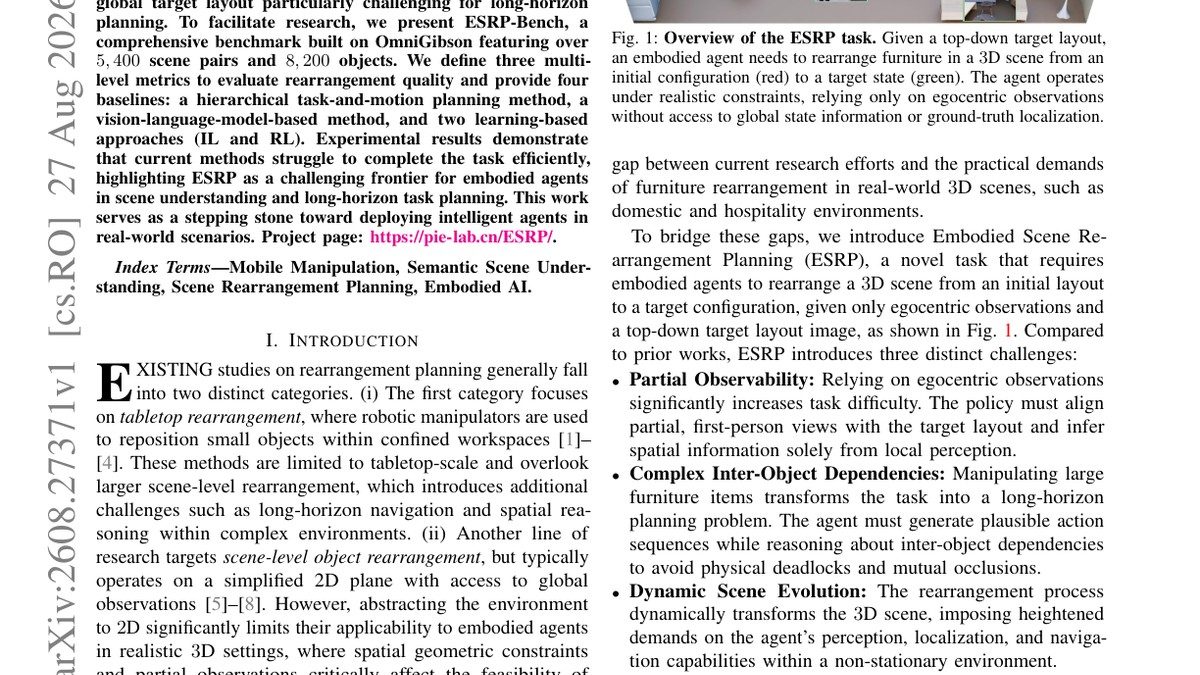
Embodied Scene Rearrangement Planning
Canzhi Chen, Zan Wang, Siqi Zhu et al.
This paper introduces Embodied Scene Rearrangement Planning (ESRP), a novel task requiring embodied agents to rearrange furniture in 3D scenes to match a target configuration using only egocentric observations and a top-down target layout.