
CLAP: Cross-Embodiment Video World Models are Zero-Shot Physical Simulators
Kechen Liu, Ola Shorinwa · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
State-of-the-art action-conditioned video models are typically restricted to a single robot embodiment, preventing them from leveraging the vast corpus of heterogeneous video data that contains rich signals for learning generalizable physics.
Abstract Summary
Key Points
- State-of-the-art action-conditioned video models are typically restricted to a single robot embodiment, preventing them from leveraging the vast corpus of heterogeneous video data that contains rich signals for learning generalizable physics.
- To bridge this gap, we introduce CLAP, a framework for cross-embodiment action-conditioned video generation capable of being trained on diverse, internet-scale videos across human and robotic agents.
- CLAP is grounded in the insight that universal physical laws govern spatiotemporal dynamics regardless of the actor.
- However, cross-embodiment learning is non-trivial because action representations vary sharply across robot platforms and are typically absent in human videos.
- CLAP addresses this fundamental challenge through the following core contributions
CLAP: Training Cross-Embodiment Video World Models
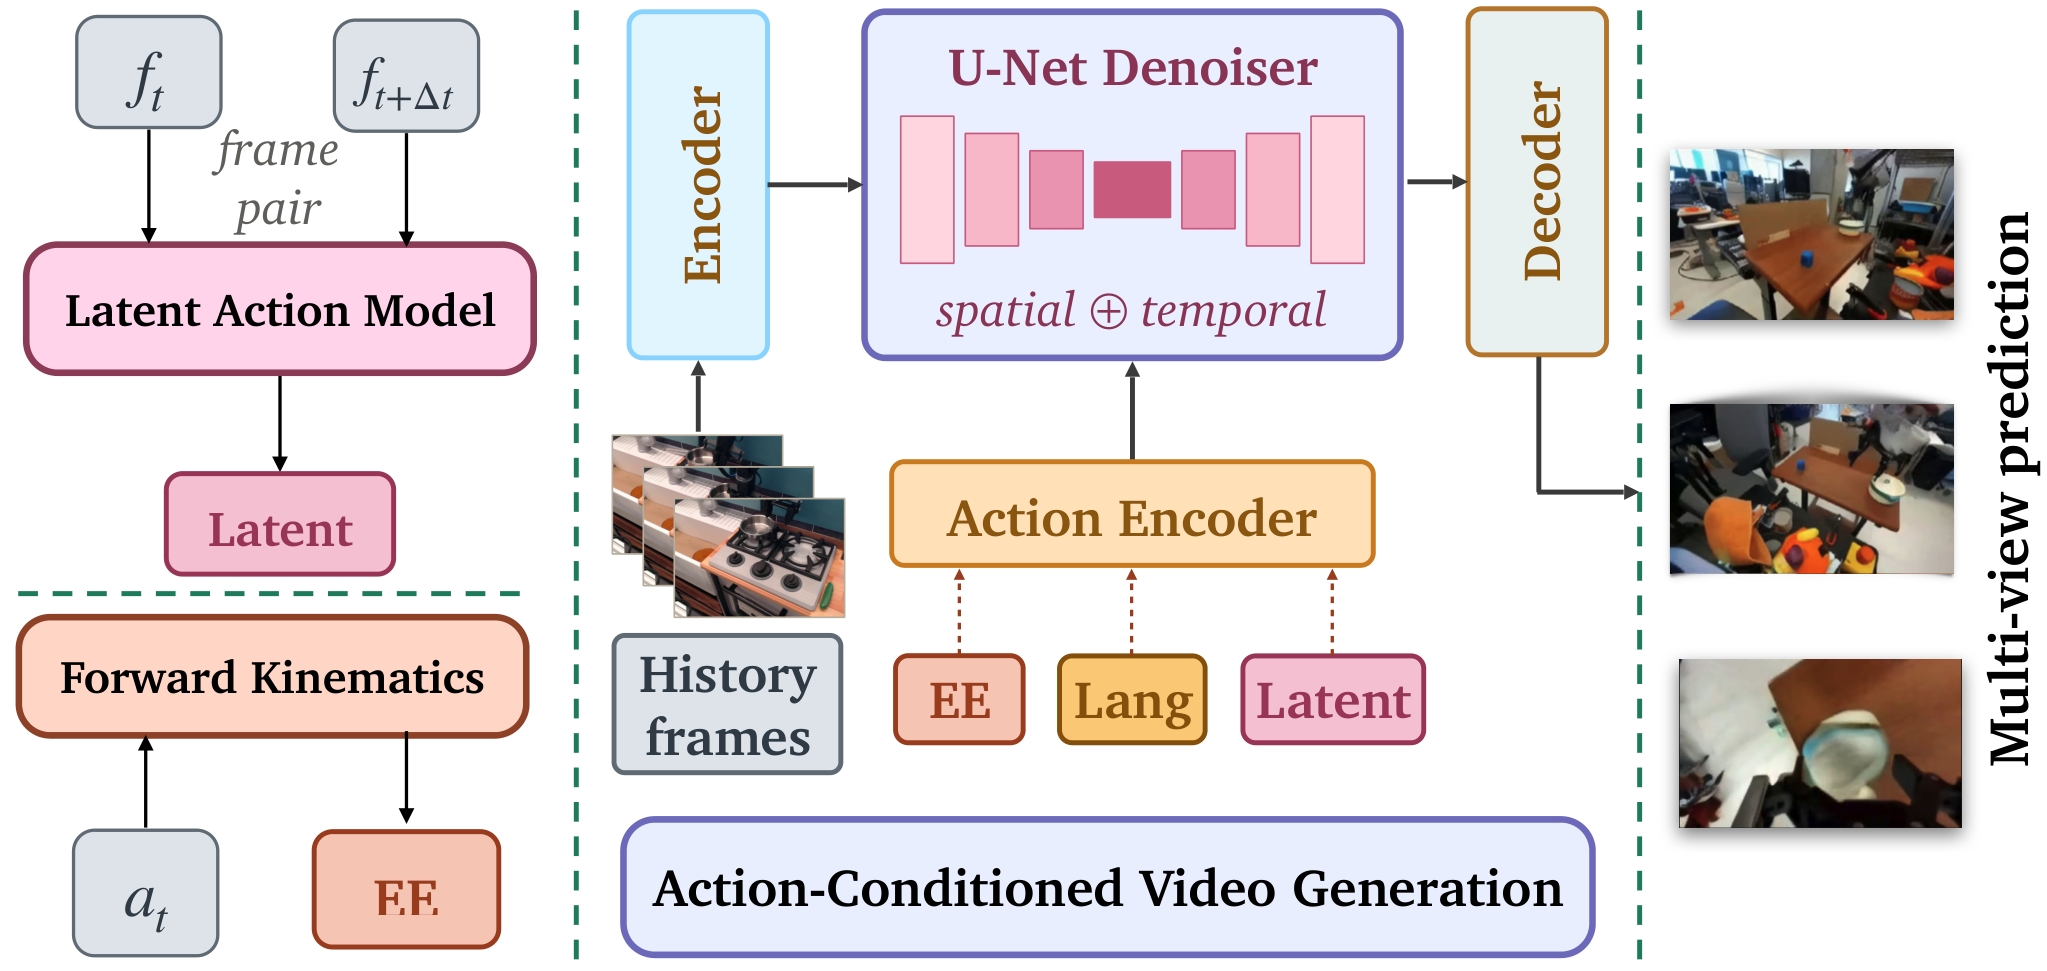
Cross-embodiment learning from video data presents a unique challenge: robot and human data is inherently heterogeneous with different observation and action spaces, and internet-scale video data largely lacks action labels.
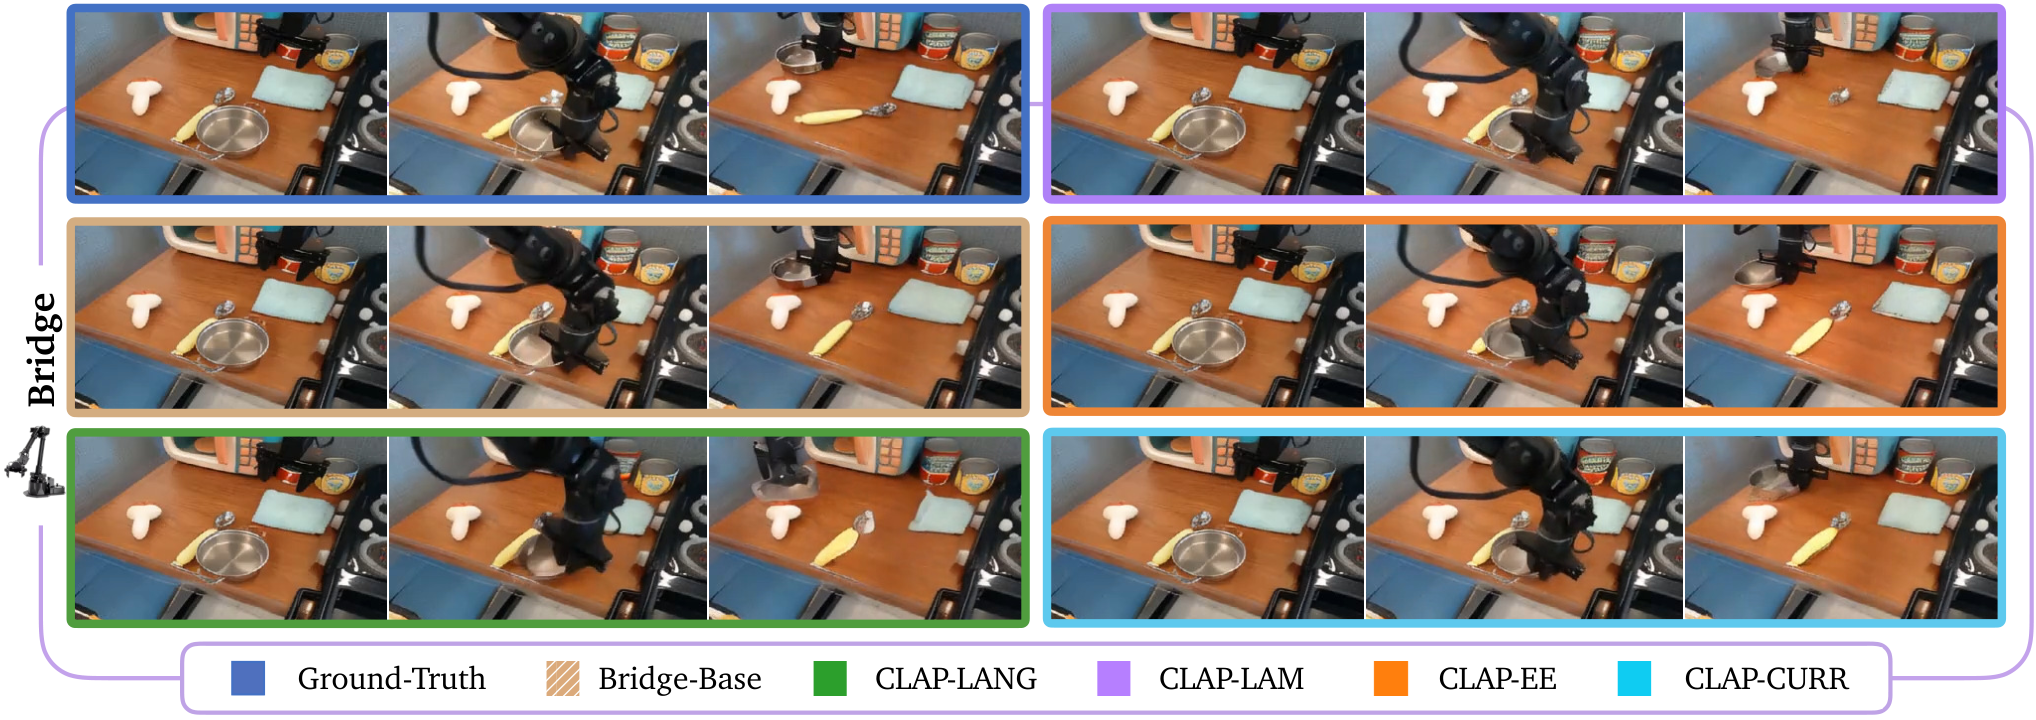
To address these challenges, CLAP introduces a novel recipe for training cross-embodiment video world models, reconciling heterogeneous action spaces using end-effector poses, natural language, and latent action representations (see Secs. 3.1 and 3.2 ).
Experiments
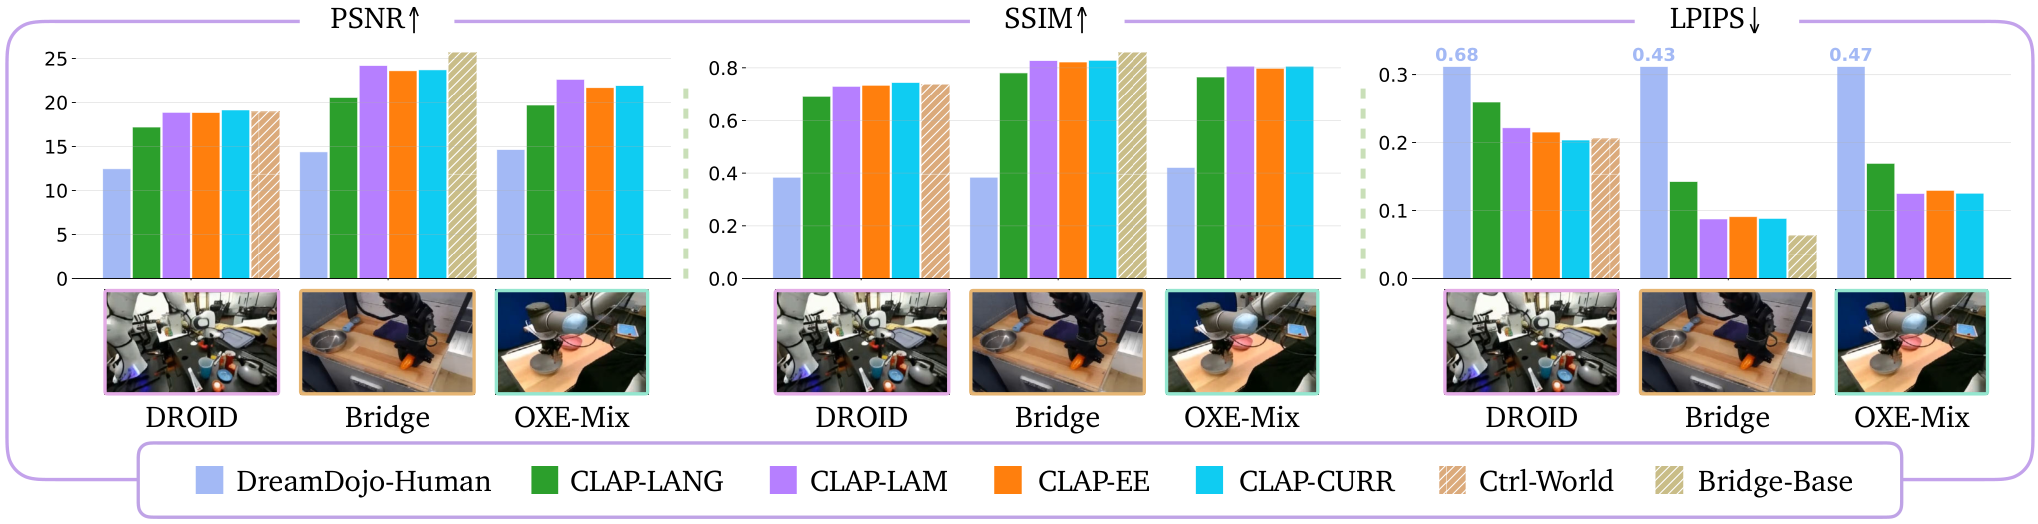
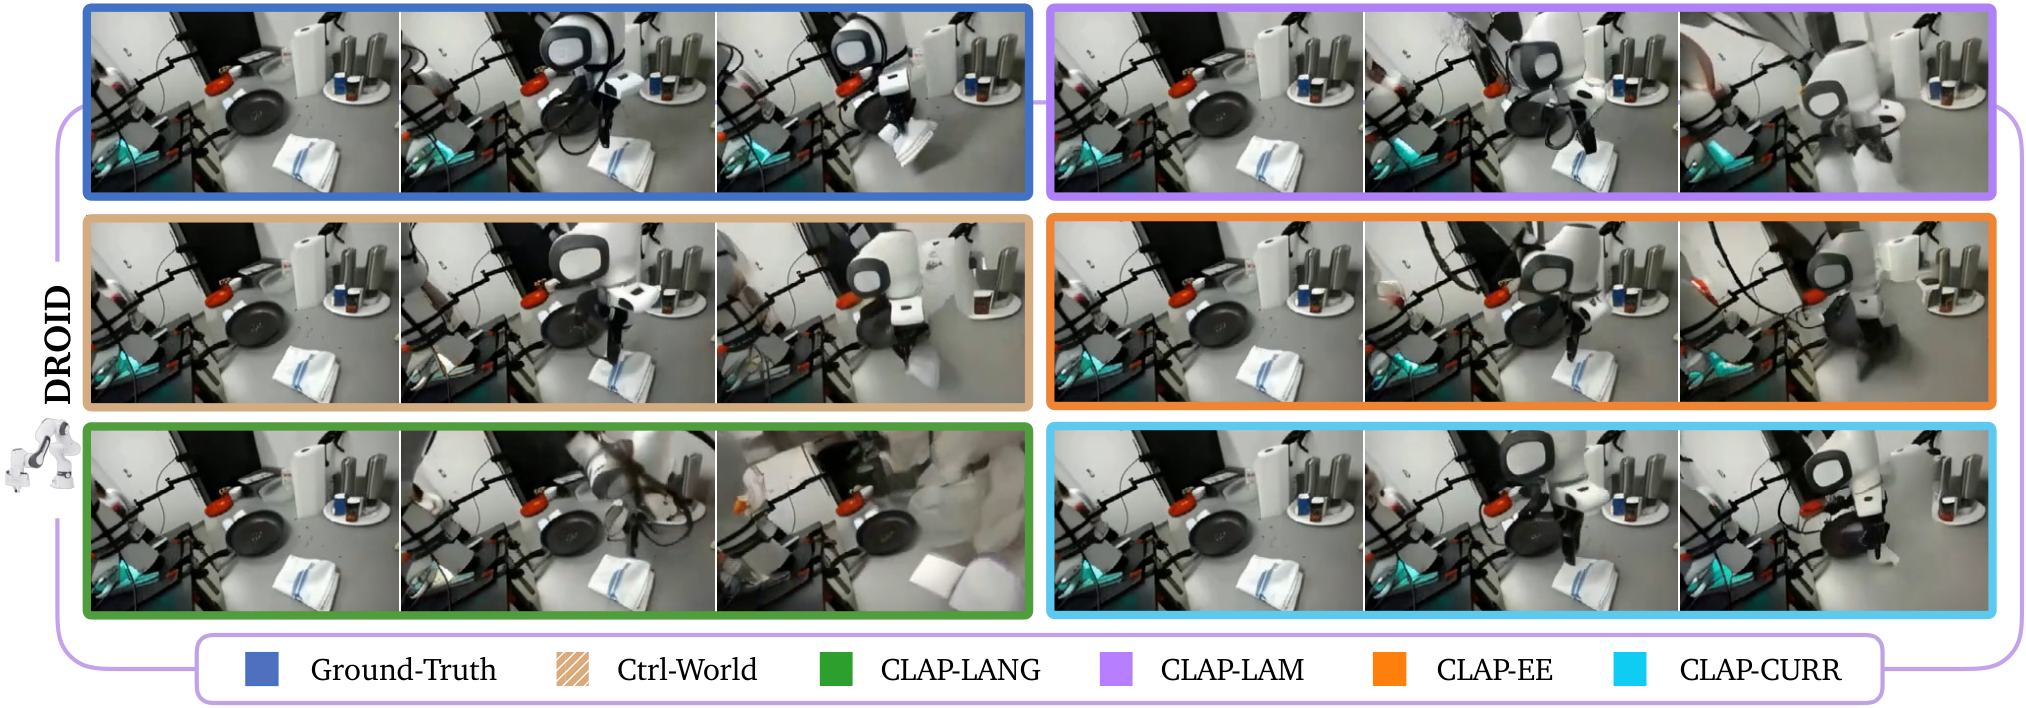
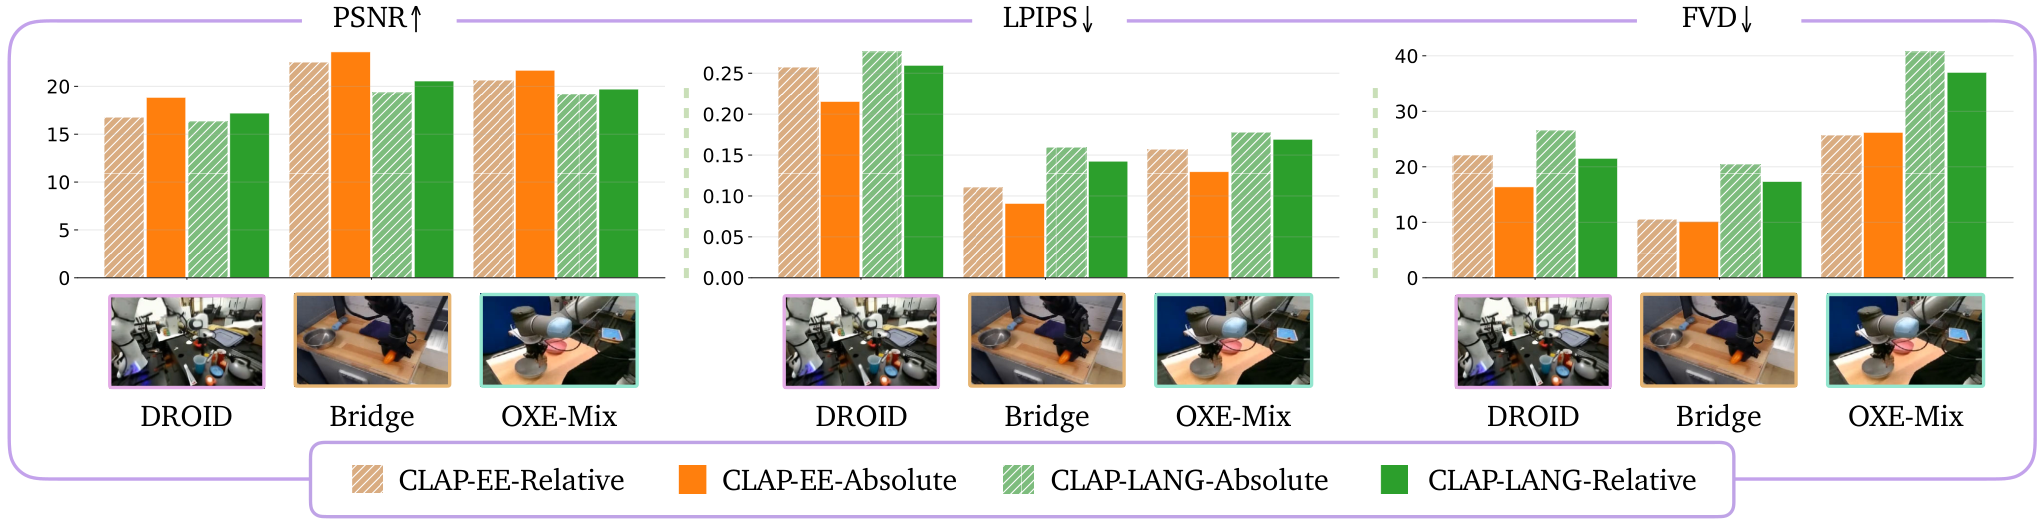
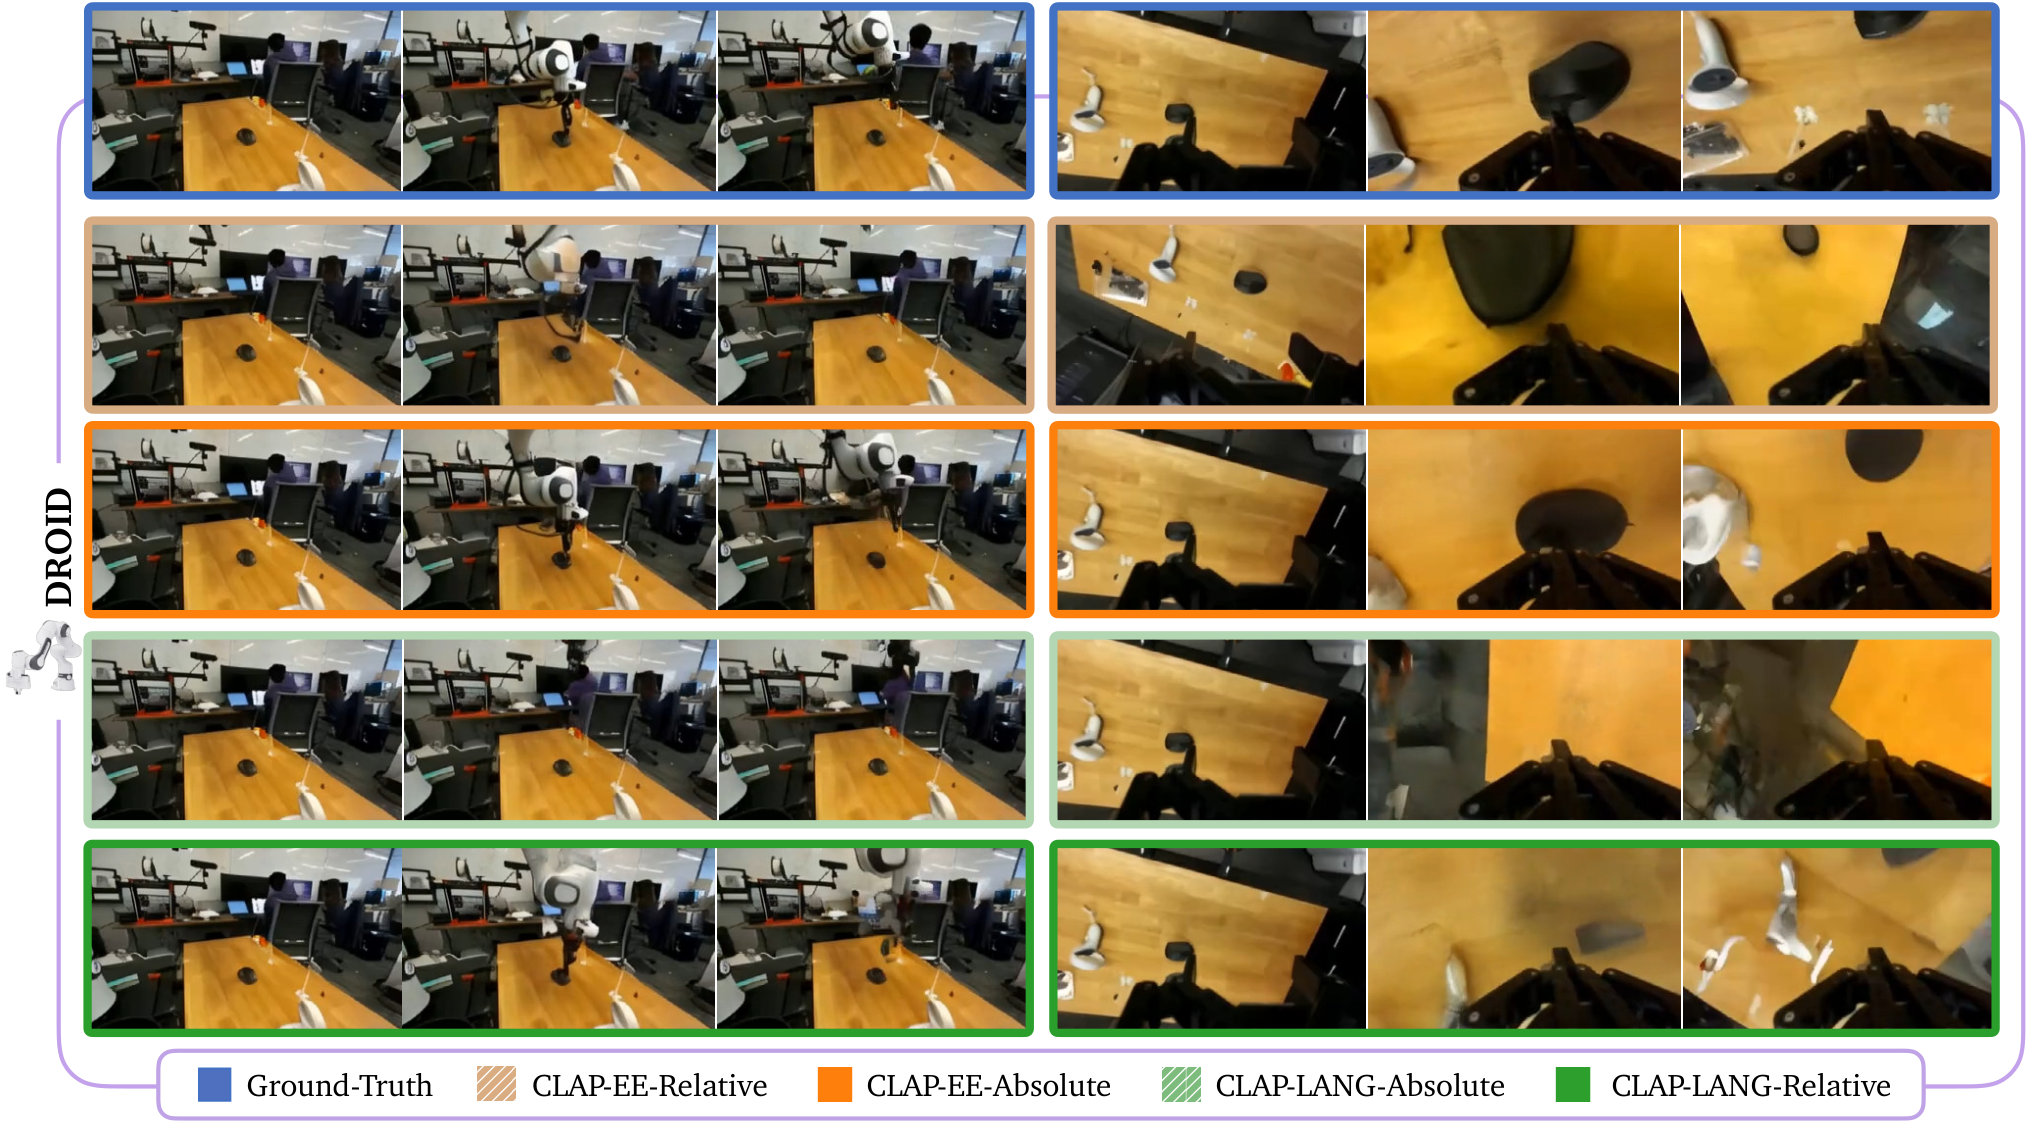
Through the lens of the following research questions, we investigate the impact of cross-embodiment scaling on action-conditioned video models and their efficacy in downstream robotics tasks: [Q1.] Do cross-embodiment video models surpass their single-embodiment counterparts? ( Sec. 4.1 ) [Q2.] Do relative-action spaces outperform absolute-action spaces in cross-embodiment video modeling? ( Sec.
4.2 ) [Q3.] Do cross-embodiment video models achieve zero-shot real-world generalization? ( Sec.
Preliminaries
Video world models predict future outcomes conditioned on per-frame actions, starting from an initial camera observation. Furthermore, to capture temporal context such as robot velocities that dictate future evolution, video world models are often conditioned on a history of past observations.
Method
End-effector Actions. Each demonstration is stored as a trajectory of end-effector states aligned to the video frames.
A single state is a $7$-dimensional vector ${s_{t}=\big[\,x_{t},\;y_{t},\;z_{t},\;\phi_{t},\;\theta_{t},\;\psi_{t},\;g_{t}\,\big],}$ where $(x_{t},y_{t},z_{t})$ is the gripper position in meters in the robot base frame, $(\phi_{t},\theta_{t},\psi_{t})$ are the roll–pitch–yaw orientation Euler angles in radians, and $g_{t}$ is the raw gripper signal.
Experiments
CLAP trains cross-embodiment video models on diverse datasets using the sampling ratios in Tab. 3 , proportional to the complexity and quaity of the individual datasets.c Multi-view camera images are vertically stacked into a single fixed-size frame (${576\times 320}$) after resizing individual frames to ${192\times 320}$.
For uniformity, we repeat single-view camera inputs in datasets without multi-view images, although preliminary experiments revealed that such repetition is unnecessary.
Nuanced Summary
This section discusses the nuances surrounding CLAP’s novelty, broader potential impact, and scope of claims. CLAP uses an old video backbone (SVD, 2023), a pretrained language encoder (CLIP), simple MLP action encoders, and does not introduce a new dataset. Is it novel? Answer: Not quite. By that same token, current state-of-the-art action-conditioned video models are largely derivative.
CLAP’s novelty lies in introducing a new paradigm for action-conditioned video modeling rooted specifically in cross-embodiment learning.
Sources and Demonstrations
Figures are reproduced from Liu et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

3DThinkVLA: Endowing Vision-Language-Action Models with Latent 3D Priors via 3D-Thinking-Guided Co-training
Jiaxin Shi, Xidong Zhang, Fucai Zhu et al.
We propose a 3D-thinking-guided co-training framework that enables vision-language-action (VLA) models to perform 3D spatial reasoning implicitly during action prediction.

4D Radar Perception Algorithms for Autonomous Driving: A Review
Xumin Wu, Jun Zhou, Jilin Mei et al.
Research on 4D millimeter-wave radar perception algorithms has flourished in recent years, extending from signal processing and object detection to semantic segmentation, motion estimation, occupancy prediction, and dynamic scene reconstruction.

A Balanced Data Diet: Addressing the Exploration Bottleneck in Mega-Scale RL for Robot Control
Octi Zhang, Mateo Guaman Castro, Patrick Yin et al.
General-purpose robots must perform a wide range of tasks from agile locomotion to dexterous manipulation.

A Browser-Native Digital Test Range for Benchmarking 4D Ocean-Glider Planning Algorithms
Edward Holmberg, Elias Ioup, Mahdi Abdelguerfi
Repeated in-situ evaluation of ocean-glider planners requires scarce vehicles, operators, deployment and recovery resources, and ocean conditions that cannot be reset for competing algorithms.