
BadWAM: When World-Action Models Dream Right but Act Wrong
Qi Li, Xingyi Yang, Xinchao Wang · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
World-action models (WAMs) are emerging as a promising foundation for embodied control: rather than predicting actions alone, they learn representations that couple action generation with future world prediction.
Abstract Summary
Key Points
- World-action models (WAMs) are emerging as a promising foundation for embodied control: rather than predicting actions alone, they learn representations that couple action generation with future world prediction.
- This coupling is often viewed as a source of robustness, interpretability, and safety, as a robot's action can in principle be checked against its imagined future.
- In this paper, we show that this assumption is fragile
- We introduce BadWAM, a unified framework for modeling and evaluating World-Action Drift Attacks: a new class of WAM-specific adversarial attacks that use small visual perturbations to break the alignment between what a WAM imagines and what it executes.
- BadWAM characterizes this attack surface along two natural criteria: attack strength and stealthiness.
Threat Model
We study inference-time attacks against deployed WAM-based robot policies. Following the notation introduced above, the robot observes $o_{t}$ and receives an instruction or goal $g$ at each replanning step. The WAM then outputs an action chunk $a_{t:t+H-1}$ and, depending on the model interface, may also expose an imagined future in latent form $z_{t+1:t+K}$ or decoded video form $v_{t+1:t+K}$.
The robot executes part of the predicted action chunk, observes the environment again, and repeats this process in closed loop.
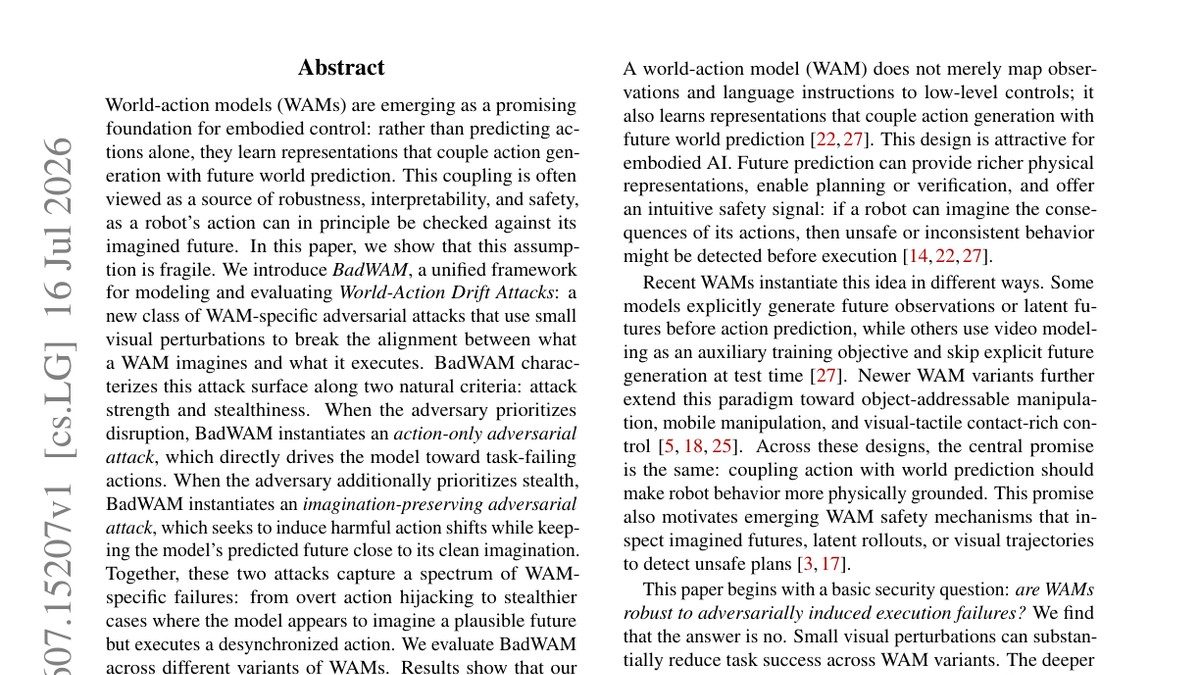
BadWAM
BadWAM is a unified framework for modeling and evaluating world-action drift attacks. As shown in Figure 3 . The framework treats a WAM as a queryable predictive-action system and optimizes bounded visual perturbations at each replanning step.
Its two attack instantiations correspond to two points on the attack-strength/stealthiness spectrum: an action-only adversarial attack that prioritizes execution failure, and an imagination-preserving adversarial attack that additionally constrains predicted-future drift.
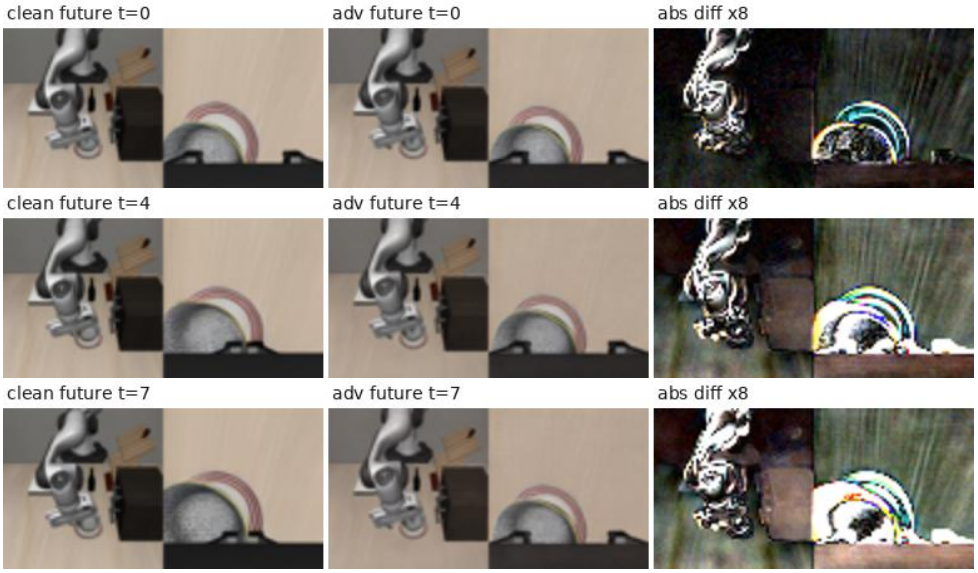
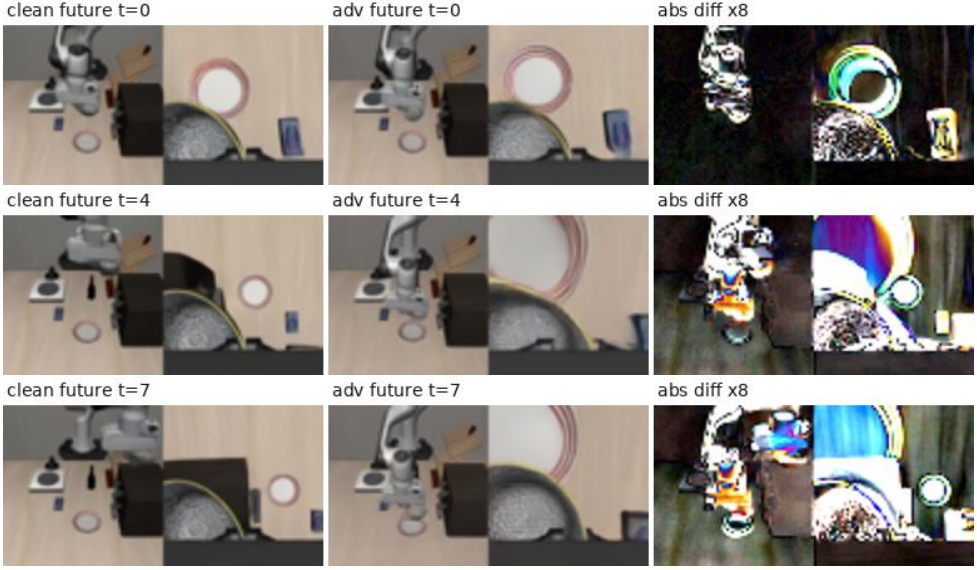
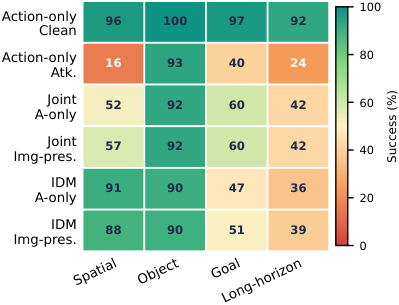
Evaluation
Attack effectiveness. How much can bounded observation perturbations reduce closed-loop WAM reliability? Systematicity. Are the failures concentrated in a few tasks, or do they persist across suites and repeated trials? Failure mechanism. What do BadWAM failures look like during execution, and how does the query-based search produce them? Stealth under matched strength.
Under matched attack strength, what does imagination preservation buy? Sensitivity and efficiency.
Sources and Demonstrations
Figures are reproduced from Li et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

A Low-Cost, Open Platform for End-to-End Autonomous Driving on a Miniature Ackermann Vehicle
Gustavo Claudio Karl Couto, Eric Aislan Antonelo, Gabriel George Zipperer
This paper presents a low-cost, open experimental platform for research in end-to-end autonomous driving with miniature Ackermann vehicles.

A Phenomenology of Neural Geometry in Vision-Language-Action Models
Mozes Jacobs, Aiden Swann, Mathilde Papillon et al.
Robotic manipulation is inherently geometric, but what shape does the world take inside the policy that performs it?

A Sim-to-Real Integration Pipeline for Training and Deployment of Chunk-Based VLA Manipulation Policies
Mathilde Kappel, Clémence Grislain, Mohamed Chetouani et al.
Vision-Language-Action (VLA) models have become a prominent paradigm for mapping multimodal inputs, including semantic instructions, visual observations of the scene, and proprioceptive observations, to robot actions.

Aim Short to Reach Far: Your Frozen World Model Can Plan Better Than You Think
Xvyuan Liu, Jianjie Fang, Chen Gao et al.
Planners built on visual world models commonly score each predicted outcome by its distance to the encoded goal image. We show that this target can limit control even with exact dynamics and globally optimal short-horizon search: reaching a goal may require actions that initially move away from it.