

QQWorld: Quantile-Quantile Matching for World Model Regularization
Zhoushun Yu, Xiaoyu Hu, Xiangyu Xu · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Latent world models enable efficient planning by predicting future states in a compact representation space, but their performance depends critically on the quality of the learned latent distribution.
Abstract Summary
Key Points
- Latent world models enable efficient planning by predicting future states in a compact representation space, but their performance depends critically on the quality of the learned latent distribution.
- LeWorldModel (LeWM) regularizes its latents toward an isotropic Gaussian using the Epps-Pulley (EP) objective.
- We show that the corrective gradients of EP rapidly vanish for isolated tail samples, leaving heavy-tailed deviations insufficiently controlled.
- To address this limitation, we propose QQWorld, which replaces EP with a quantile-quantile matching objective that directly aligns projected latent samples with rank-matched Gaussian quantiles, thereby maintaining effective corrective gradients in the tails.
- We further develop cross-batch QQ, which enlarges the effective ranking pool using detached samples from previous batches, and characterize its bias-variance trade-off.
Method
Let $z_{1},\dots,z_{N}\in\mathbb{R}^{d}$ denote the latent embeddings of a training batch. Similar to Balestriero and LeCun (2025) , normality is enforced along random one-dimensional projections.
For a direction $u\sim\operatorname{Uniform}(\mathbb{S}^{d-1})$ where $\mathbb{S}^{d-1}$ denotes the unit sphere in $\mathbb{R}^{d}$, we form the projected samples $x_{n}=\langle u,z_{n}\rangle$ and penalize their departure from $\mathcal{N}(0,1)$.
Experiments
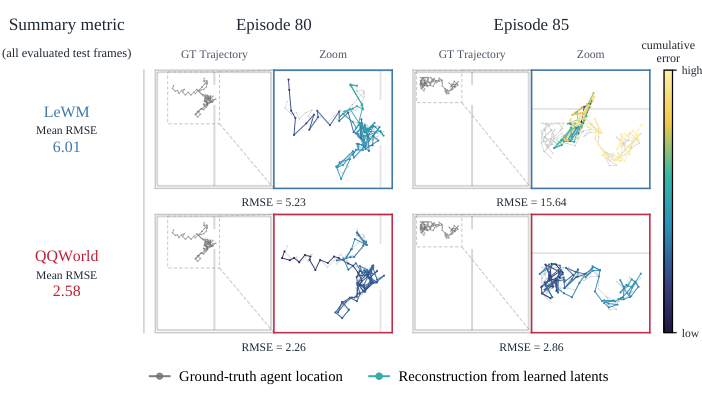
We follow LeWM ( Maes et al., 2026 ) for dataset preprocessing, model training, and CEM-based goal-conditioned evaluation. Experiments are conducted on the same offline datasets, including Two-Room ( Sobal et al., 2025 ) , PushT ( Zhou et al., 2025 ) , Reacher ( Tassa et al., 2018 ) , and OGBench-Cube ( Park et al., 2025 ) . QQWorld differs from LeWM only by replacing the EP regularizer with the proposed QQ objective.
We set the QQ regularization weight to $3.5$ for all environments.
Sources and Demonstrations
Figures are reproduced from Yu et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

A Browser-Native Digital Test Range for Benchmarking 4D Ocean-Glider Planning Algorithms
Edward Holmberg, Elias Ioup, Mahdi Abdelguerfi
Repeated in-situ evaluation of ocean-glider planners requires scarce vehicles, operators, deployment and recovery resources, and ocean conditions that cannot be reset for competing algorithms.

A Low-Cost, Open Platform for End-to-End Autonomous Driving on a Miniature Ackermann Vehicle
Gustavo Claudio Karl Couto, Eric Aislan Antonelo, Gabriel George Zipperer
This paper presents a low-cost, open experimental platform for research in end-to-end autonomous driving with miniature Ackermann vehicles.

AD-WM: Action-Discriminative World Models for Counterfactual Model Predictive Control
Jiabin Qiu, Zixuan Chen, Hongye Cao et al.
Latent world models are typically trained to predict factual transitions, whereas model predictive control (MPC) must compare alternative actions from the same state. A model can therefore achieve low factual prediction error yet poorly distinguish candidate actions.

AHEAD: Anticipatory Hand-Driven Teleoperation via Human Intent Prediction
Seok Joon Kim, Junho Lee, Federica Spinola et al.
Direct hand-driven teleoperation maps an operator's hand motion to robot end-effector commands at every frame, enabling precise control, but it requires constant monitoring and correction during approach, grasp, and placement, which can be slow and fatiguing.