
CORAL: Curriculum-Optimized Reward Adaptation for LiDAR-Based Goal-Directed Urban Driving
Anisa Saleem, Duksu Kim · N/A · 2026
Framework
N/A
License
N/A
Stars
N/A
Summary
Reinforcement learning is promising for autonomous urban driving, but long-horizon goal-directed navigation asks a policy to acquire several competing behaviors at once--reaching a distant goal, tracking a route, avoiding obstacles, obeying signals--and a fixed objective gives no order in which to learn them.
Abstract Summary
Key Points
- Reinforcement learning is promising for autonomous urban driving, but long-horizon goal-directed navigation asks a policy to acquire several competing behaviors at once--reaching a distant goal, tracking a route, avoiding obstacles, obeying signals--and a fixed objective gives no order in which to learn them.
- This paper presents CORAL, which advances two schedules together: a five-stage curriculum that progressively lengthens routes and tightens behavioral constraints, and a stage-aware reward whose component weights shift emphasis from mission progress toward route following, safety, smoothness, and rule compliance as the task hardens.
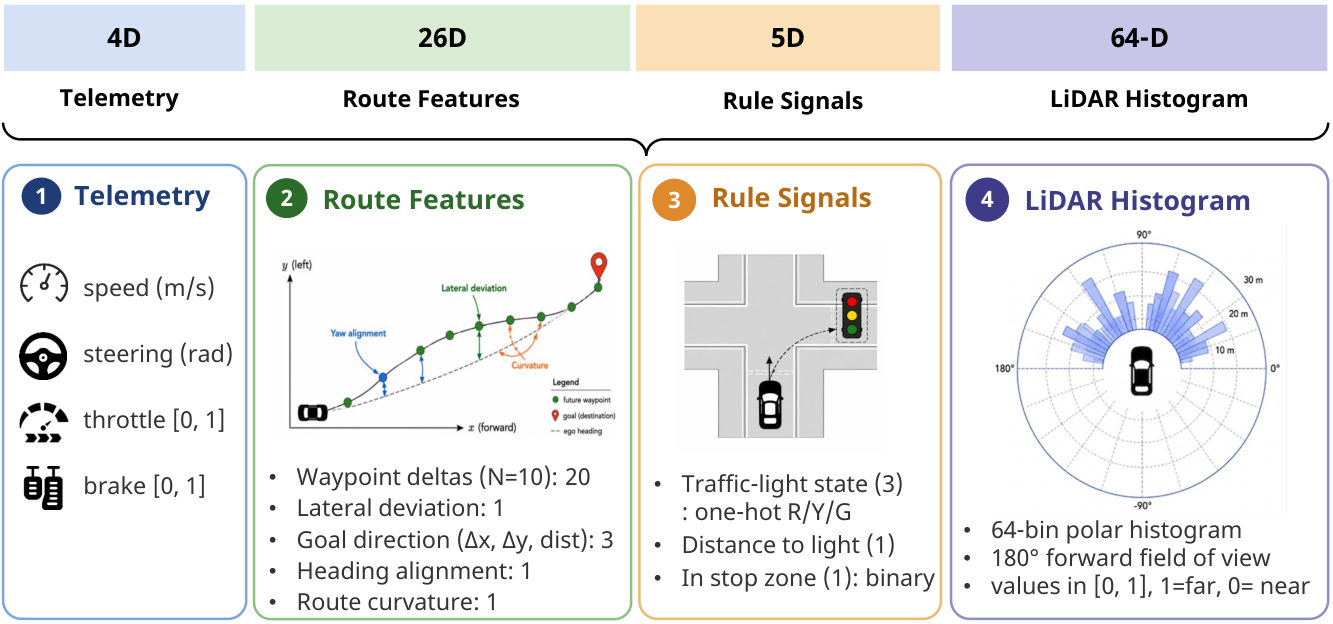
- The policy is a multi-stream actor-critic network trained with Proximal Policy Optimization (PPO) in CARLA on a compact 99-dimensional state pairing a polar LiDAR histogram with vehicle telemetry, ego-frame route geometry, and traffic-rule indicators--no point-cloud encoder, no bird's-eye-view rasterization.
- Against two PPO baselines under an identical protocol, CORAL reaches the goal in all twenty evaluation episodes on the longest routes under the full set of behavioral constraints, where the baselines reach 5% and 10%; a factorial ablation shows that neither schedule alone matches their combination: removing either lowers both success and route completion, and disabling both drops success to 55%.
- Trained in one town, the policy transfers zero-shot to seven unseen towns, succeeding in 68-98% of episodes on routes of the same 100-150 m length, with mean lateral deviation below 0.35 m.
Methodology
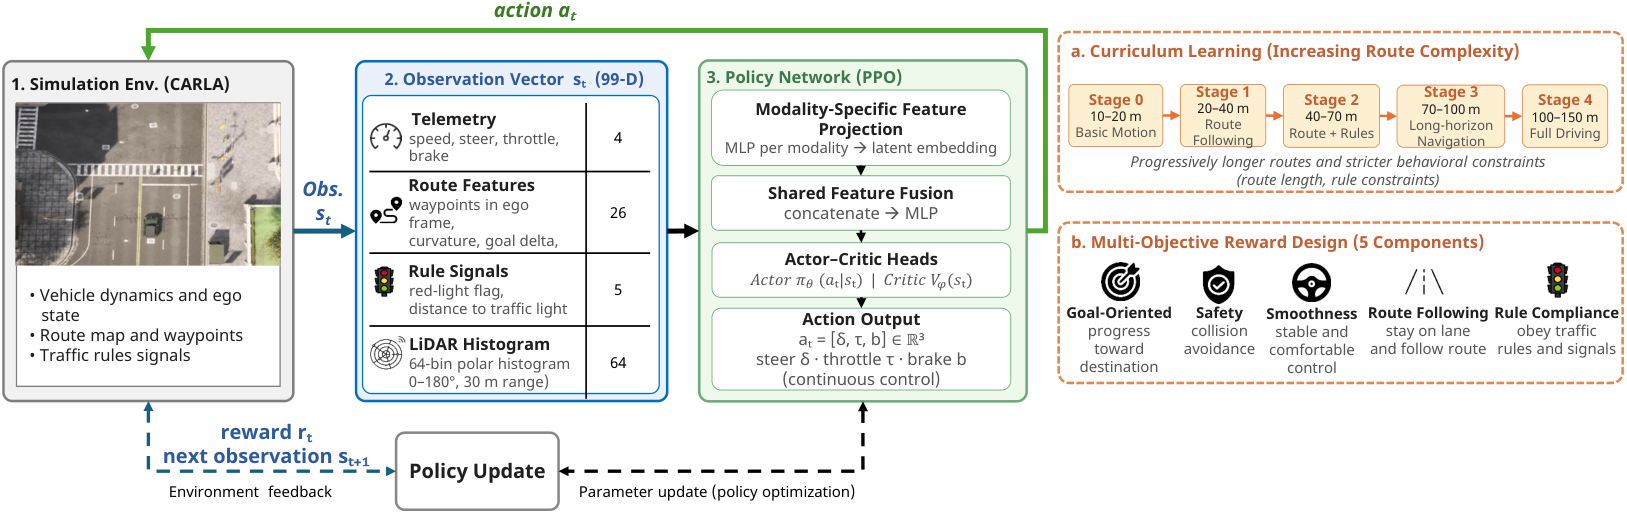
This section presents the proposed curriculum-guided reinforcement learning framework for goal-directed autonomous driving. We formulate goal-directed urban driving as a continuous-control reinforcement learning problem in which, at each timestep, the agent maps an observation of the driving scene to steering, throttle, and brake commands, and is trained in the CARLA simulator using PPO. Fig.
1 gives an overview of CORAL; this subsection walks through the end-to-end pipeline and points to the subsection that develops each component in detail.
Experiments and Results
This section first describes the experimental setup—the simulation environment, training configuration, evaluation protocol and metrics, and baselines—and then reports the comparative and generalization results, followed by two ablation studies.
Simulation environment: All experiments use the CARLA simulator (v0.9.15) on a goal-directed navigation task, in which the agent drives from a randomly sampled start to a target destination while following a planned route and obeying traffic signals.
Sources and Demonstrations
Figures are reproduced from Saleem et al. See the full paper for experimental details and the project page, when the paper links one, for demonstrations and videos.
Related Papers

A Browser-Native Digital Test Range for Benchmarking 4D Ocean-Glider Planning Algorithms
Edward Holmberg, Elias Ioup, Mahdi Abdelguerfi
Repeated in-situ evaluation of ocean-glider planners requires scarce vehicles, operators, deployment and recovery resources, and ocean conditions that cannot be reset for competing algorithms.

Aim Short to Reach Far: Your Frozen World Model Can Plan Better Than You Think
Xvyuan Liu, Jianjie Fang, Chen Gao et al.
Planners built on visual world models commonly score each predicted outcome by its distance to the encoded goal image. We show that this target can limit control even with exact dynamics and globally optimal short-horizon search: reaching a goal may require actions that initially move away from it.
Beyond Episodic Evaluation: Memory Architectural Bottlenecks in Sequential Embodied Question Answering
Zikui Cai, Kaushal Janga, Tan Dat Dao et al.
Embodied question answering (EQA) is traditionally evaluated under an episodic formulation, where agents solve each task independently and reset internal state between episodes.
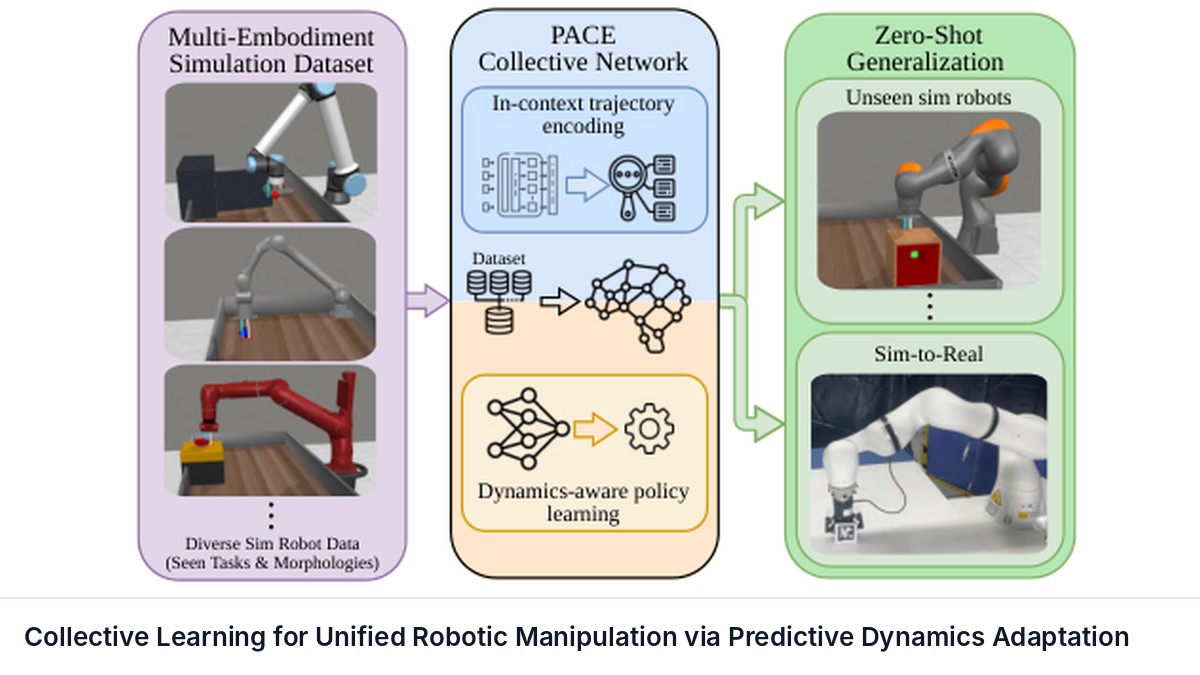
Collective Learning for Unified Robotic Manipulation via Predictive Dynamics Adaptation
Shaocheng Liu, Yuan Meng, Zhenshan Bing et al.
Learning a collective policy for state-based Cartesian manipulation across diverse robotic embodiments presents a fundamental challenge due to embodiment-dependent transition dynamics.